Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinking
The fixed version Anthropic positions for long-running agentic coding and knowledge work (claude-opus-5-5, retirement no earlier than 2027-09-22): 1M-token context, 128K-token single output, adaptive thinking defaulting to medium, at $4/$20 per million tokens, the cheapest of the three top rows we track. On the Artificial Analysis intelligence index this site syncs (2026-09-22) the top three rows are all its thinking tiers (max 57.62, xhigh 55.99, high 53.58), while the default medium tier sits #8 at 51.24, with sibling Fable 5.1 (53.35) and GPT-6 Astra (52.67) in between. Two discounts: those rows carry the with fallback qualifier while Astra reads (max), so the protocols differ, and the 53.94% at #8 on Terminal-Bench belongs to the previous-generation Opus 5. Closed, API only; adaptive thinking is a black box, so budget on p90 rather than the mean; 1M context is not 1M of effective attention, so whole-repo input still needs retrieval. Use it for most workloads and move to Fable 5.1 only when the highest tier is not enough: 2.5x the price for 4.3 index points. Graded A (confirmed); not benchmarked by us.
57.62AA 智能指数Confirmed · 2026-09
Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinkingJev: TypeSafe's first System One Model types decisions and prices them two orders of magnitude lower
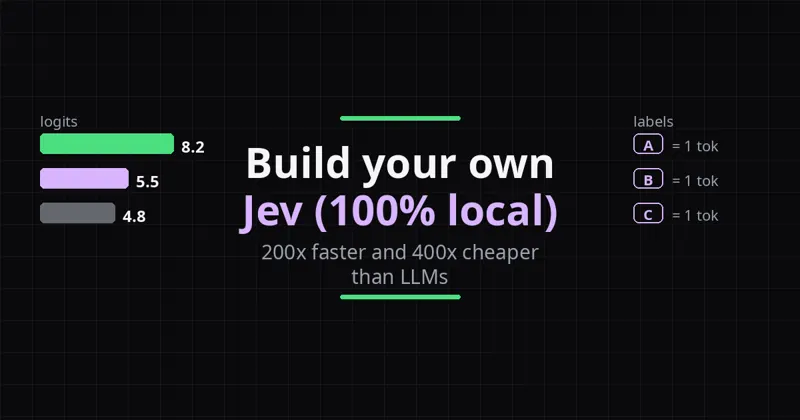
TypeSafe's first System One Model: outputs are type-safe structured values under three question primitives (Noul/Choice/Score) rather than strings, trained with RLCD for calibrated decision probabilities. The official 13-question parallel experiment makes one synthesized call ~12.2x cheaper and ~10.0x faster than 13 separate calls; four-workflow mean accuracy 67.8% at /tmp/run_ingest2.sh.0004 and 0.4s per instance - opus 5 / sol tier accuracy at almost two orders of magnitude less cost; input $0.042/M tokens, output free. Ships an OpenJev local reproduction path and an eight-item caveats list.
67.8%四工作流平均准确率(官方评测)Vendor Claim · 2026-09
Jev: TypeSafe's first System One Model types decisions and prices them two orders of magnitude lowerMiMo-V2.6: Live RL as an auditable ledger of 30 steps, 750k trajectories, and dollars
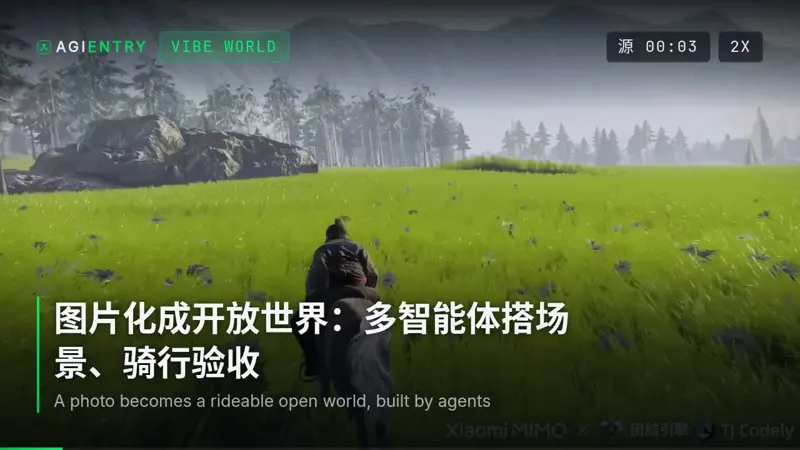
Xiaomi's open-source MiMo-V2.6 Pro/Flash: 30 steps of Live RL, roughly 750k trajectories, public cost of $850k/$2.62M, and 7k+ RL environments released in the same batch; tops the open-weights camp on the Artificial Analysis intelligence index at 46 with +17/+14 points out-of-sample on DeepSWE v1.1; four demo lines (Vibe World, CUA, research, content creation) all open. Self-improvement becomes an auditable ledger - steps, trajectories, and dollars on the table for third-party recomputation.
46AA 智能指数(开源榜首)Confirmed · 2026-09
MiMo-V2.6: Live RL as an auditable ledger of 30 steps, 750k trajectories, and dollarsGLM-5.3: the open-weights coding flagship bought with post-training alone
Z.ai post-trained the very same base as GLM-5.2 and nothing else, producing the 744B-A40B GLM-5.3: 50 percent over 5.2 on the in-house Z.ai Code Bench, open-weights first on Terminal Bench 3.0 at 28.3 and Agents' Last Exam at 28.5, while AutomationBench 48.2 and GDPVal-AA v2 1769 beat every closed-source comparison on the official chart; CyberGym vulnerability discovery is SOTA and the exploitation-chain gains emerged without dedicated training. The companion 320B-A18B Flash starts from a new base and is the first GLM to mix sparse with linear attention, attacking long-context serving cost. Weights ship in FP8 and BF16, deployable on SGLang, vLLM, KTransformers and the Ascend stack.
28.3Terminal Bench 3.0(开源权重第一, 官方图)Vendor Claim · 2026-08
ProductZ.ai (Zhipu AI)SiteRepo GLM-5.3: the open-weights coding flagship bought with post-training aloneClaude Fable 5.1: the long-horizon agentic tier that tops the ladder on a different ruler
The fixed version Anthropic positions for demanding reasoning and long-horizon agentic work (claude-fable-5-1, retirement no earlier than 2027-09-01): default thinking effort high at $10/$50 per million tokens, 2.5x sibling Opus 5.5, and default-high is itself a default cost behaviour. Its standing only holds once you switch rulers: #1 on net_improvement in the Arena Agent board (13.71, confirmed_success 19.83, praise 31.83) ahead of GPT-6 Astra (11.54/17.70/32.79), while Opus 5.5 misses the top eight; #2 on Terminal-Bench 4.0 at 57.88% (n=330), 0.3 points behind Astra at 58.18% but with pass@5 of 0.7879 against 0.7121, lower single-shot and more robust over five attempts; #4 on the intelligence index at 53.35 (max), below Opus 5.5. The picture is consistent: not first on composite intelligence, first on pushing a real task forward. A separate praise column means the board carries a human or judge component and is not an objective benchmark. Choose by whether the workload is hard from reasoning or from long-horizon consistency. Closed, API only. Graded A (confirmed); no long-task comparison on our own harness.
13.71Arena Agent 净改进Confirmed · 2026-09
Claude Fable 5.1: the long-horizon agentic tier that tops the ladder on a different rulerGPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligence
The OpenAI flagship tier, officially positioned for hardest end-to-end work (gpt-6-astra): 1.05M-token context, 128K-token single output, knowledge cutoff 2026-04-30, with Functions, Web search, File search and Computer use built in, so search, retrieval and interface control ship with the model instead of an outer agent framework. Reasoning effort runs low to max in five steps while price stays fixed at $10/$50, so the cost lever is token consumption; siblings Sol ($2/$10) and Luna ($0.1/$0.5) make a 100x spread, so load splitting can stay inside one vendor. Readings (2026-09-22): #1 on Terminal-Bench 4.0 at 58.18% (n_trials=330, pass@5 0.7121), the protocol closest to a coding agent's daily life; #2 on Arena Agent with net_improvement 11.54 and confirmed_success 17.70, both below leader Fable 5.1, but the field's highest praise at 32.79; #6 and #7 on the intelligence index (max 52.67). The cutoff is nearly five months older than this page, so version numbers and API changes must go through Web search; computer-use reliability appears on no board; closed, API only. Graded A (confirmed); not benchmarked by us.
58.18%Terminal-Bench 准确率Confirmed · 2026-09
GPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligenceLaya: a 421M non-autoregressive System 1 decision model at 33 ms per forward pass
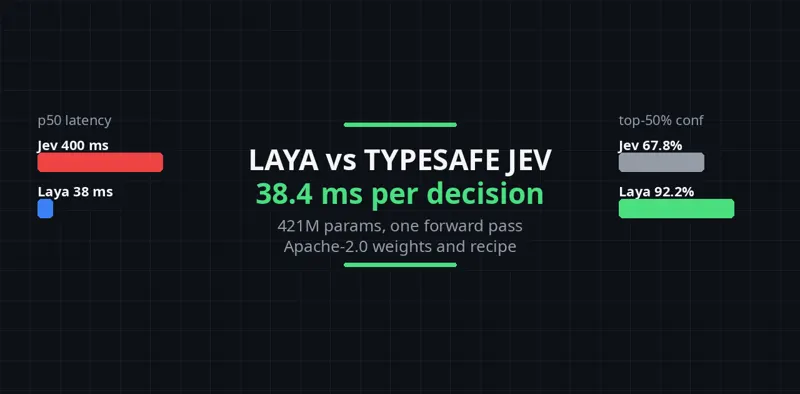
Convai Innovations' open-source non-autoregressive System 1 decision model: 421M parameters, ModernBERT backbone with [MASK] option extraction, one 33 ms forward pass per calibrated decision, Apache-2.0; trained with RLCD strictly proper scoring rules for honest probabilities; the model card ships a real benchmark against Jev plus an honest limitations list. Positioned for edge and high-concurrency small decisions (game NPCs, dialogue policy, request routing), not long reasoning or open generation.
33 ms单次前向延迟(421M,官方)Vendor Claim · 2026-09
ResearchConvai InnovationsSiteRepo Laya: a 421M non-autoregressive System 1 decision model at 33 ms per forward passllama.cpp: seventeen backends and 1.5-to-8-bit quantisation, taking LLM inference anywhere a compiler exists
An MIT-licensed, dependency-free plain C/C++ inference implementation built on ggml. Seventeen backends span CUDA, Metal, HIP, Vulkan, SYCL, WebGPU, CANN, Hexagon, MUSA, zDNN and ZenDNN; integer quantisation runs 1.5 to 8 bits; CPU+GPU hybrid inference makes models larger than VRAM runnable at all; and GGUF, its output format, is a de facto standard that even vLLM consumes. Two lines - llama cli or llama serve - start an OpenAI-compatible server.
130kGitHub stars
llama.cpp: seventeen backends and 1.5-to-8-bit quantisation, taking LLM inference anywhere a compiler existsvLLM: the open serving stack that grew out of PagedAttention, with 200+ architectures and five parallelism axes
An inference and serving library out of UC Berkeley's Sky Computing Lab with 2000+ contributors: paged KV memory, continuous batching and chunked prefill, CUDA/HIP graphs with torch.compile, quantisation across FP8/MXFP4/NVFP4/GGUF, pluggable attention kernels (FlashInfer, TRTLLM-GEN, FlashMLA), four speculative decoding routes (n-gram, suffix, EAGLE, DFlash), tensor/pipeline/data/expert/context parallelism with P/D disaggregation, and both OpenAI and Anthropic protocols.
93kGitHub stars
vLLM: the open serving stack that grew out of PagedAttention, with 200+ architectures and five parallelism axesunsloth: the 2x-faster, 70%-less-VRAM fine-tuning library, now a desktop runtime that wires local weights into Claude Code and Codex
Self-described as the first desktop app to run and train models (Windows/macOS/Linux; multi-GPU across NVIDIA, AMD, Intel, CPU and Vulkan). Fine-tuning is claimed at 2x faster with 70% less VRAM, the post-training menu covers LoRA, QLoRA, full fine-tuning, pretraining, GRPO, DPO and FP8, and export reaches GGUF, NVFP4 and FP8. Unsloth Start connects Claude Code or Codex to local weights in one command; the model list includes Qwen3.8, GLM-5.3-Flash, Kimi K3, DeepSeek-V4, MiniMax-H3 and Gemma 4, with private web search, deep research, auto-compaction and RAG built in.
77kGitHub stars
unsloth: the 2x-faster, 70%-less-VRAM fine-tuning library, now a desktop runtime that wires local weights into Claude Code and CodexSGLang: the serving framework that made prefix reuse a radix tree, and a rollout backend for frontier RL post-training
A high-performance serving framework hosted by LMSYS: RadixAttention prefix caching, a zero-overhead CPU scheduler, prefill-decode disaggregation, DFlash and Spec V2 speculative decoding, compressed finite state machines for structured output, and large-scale expert parallelism (96 H100 GPUs; 3.8x prefill and 4.8x decode on GB200 NVL72 part II). Its day-0 ledger covers Kimi K3, DeepSeek-V4, GLM5.2 NVFP4, Nemotron 3 and MiniMax M2, and AReaL, Miles, slime, Tunix and verl all use it as an RL rollout backend.
37kGitHub stars
SGLang: the serving framework that made prefix reuse a radix tree, and a rollout backend for frontier RL post-trainingTensorRT-LLM: NVIDIA's specialised-kernel and rack-scale engine, with agentic serving as a first-class topic
NVIDIA's inference optimisation library for LLMs and visual generation models, fully open source since 2025-03-22. Its 28 tech blogs form an auditable engineering ledger: Skip Softmax and sparse attention for long context, the three-part expert parallelism series with one-sided AlltoAll over NVLink, DWDP for NVL72, guided decoding cooperating with speculative decoding, inference-time compute, and evaluating agentic serving with trace replay and job-level metrics. Claims include Llama 4 Maverick above 1,000 TPS per user and 40,000+ tok/s on B200; Bing and NAVER Place run it in production.
15kGitHub stars
TensorRT-LLM: NVIDIA's specialised-kernel and rack-scale engine, with agentic serving as a first-class topicDynamo: the datacenter-scale orchestration layer above inference engines, with KV-aware routing, tiered KVBM and an SLA-driven planner
NVIDIA's open-source (Apache-2.0) orchestration layer, Rust for the performance path and Python for extensibility. It explicitly does not replace SGLang, TensorRT-LLM or vLLM - it wires them into a coordinated multi-node system: disaggregated prefill/decode, KV-aware routing (2x faster TTFT on Qwen3-Coder 480B), KVBM offloading KV cache to CPU/SSD/remote, ModelExpress streaming weights over NVLink for 7x faster cold starts, an SLA-driven Planner (80% fewer breaches at 5% lower TCO in Alibaba production), and Grove for topology-aware NVL72 scheduling.
8.2kGitHub stars
Dynamo: the datacenter-scale orchestration layer above inference engines, with KV-aware routing, tiered KVBM and an SLA-driven plannerNInfer: A From-Scratch C++/CUDA Inference Engine for a Single RTX 5090
A from-scratch C++/CUDA inference engine for five explicitly registered Qwen checkpoints on one NVIDIA GeForce RTX 5090. Startup-frozen residency picks MTP or DFlash speculative decoding, Vision, and one of five KV storage formats; a shared Device KV pool plus pinned Host State/KV checkpoints reuse exact prompt prefixes across 240k-token contexts. Measured aggregate decode reaches 1,146.9 tok/s at concurrency 8 and 15,544.3 tok/s on a 7,680-token prefill.
1.4kGitHub stars
NInfer: A From-Scratch C++/CUDA Inference Engine for a Single RTX 5090