Video editing, image generation, audio and scoring
Video and audio production is the field AI has penetrated deepest, and the one most easily misrepresented by demos. It is deep because the work was already cut into small stages - storyboards, footage, transitions, captions, voiceover, grading - each of which can be accelerated separately, so real time is saved without replacing the whole pipeline. It is misleading because vendor samples are almost all cherry-picked: behind one beautiful five-second shot may sit thirty re-rolls, while a real commercial delivery needs consistency on the client's seventh round of notes. The right yardstick in this field is therefore not "how good is the best clip" but "what is the usable rate, how many re-rolls per finished clip, what is the unit cost". The ladder here is ranked on those three, not on picture quality, and anything without a reproducible comparison carries a C (vendor claim).
Tracked assets
14
Installable skills
1
Capability domains
9
SOTA applications
14
Speech & AudioMediaTopC
Eleven Music v2.5: the closed-source row that turns music generation into a callable pipeline
The music generation model from ElevenLabs, currently at v2.5, released 2026-09-11 with the release post last updated 2026-09-20. It sits at the engineering-side top row for music in the audio domain, which contrasts with rather than duplicates the Suno entry already catalogued here: the value of Suno concentrates inside the product, a Studio multi-track timeline, Custom Models, up to twelve stems and MIDI export, while Eleven Music splits comparable capability into endpoints, namely compose, stream, a structured composition plan, scoring an uploaded video, uploading existing audio, stem separation, finetunes and section level inpainting, plus a marketplace where creators license tracks to each other. Choosing between them therefore needs no audio quality comparison, only one question: is this track something a person sits and adjusts, or something a pipeline requests in volume. The API surface is nine endpoints rather than one generate call, and two details matter for procurement: both compose and stem-separation take a sign_with_c2pa flag that applies to mp3 output so outgoing files can carry content credentials, and output format is tied to subscription tier, with mp3_44100_192 requiring Creator or above and pcm_44100 requiring Pro or above on stem-separation and video-to-music while compose goes up to mp3_48000_320, so the threshold for lossless differs per endpoint. The trap worth memorising is that v2.5 is already the interface default yet the model_id enum of music_v1, music_v2 and music_v2_5 still defaults to music_v1, and output_format=auto resolves per model to mp3_44100_128 on v1 and mp3_48000_192 on v2, so a minimal call that omits model_id silently gets the oldest generation at a lower bitrate; pin both in production code and name mp3_48000_320 when 320kbps is required. The two plan schemas are not interchangeable and the wrong pairing is a hard error: music_v1 takes MusicPrompt while music_v2 and music_v2_5 take CompositionPlan, whose chunks carry a text field with square bracket section names, lyric lines and curly brace inline directions. On the control surface prompt and composition_plan are mutually exclusive, and the request takes music_length_ms from 3000 to 600000, that is three seconds to ten minutes, plus force_instrumental, finetune_id and seed. Rights and commercial use are the most structured part of this line: a multi-year agreement with Universal Music Group was announced alongside v2.5 and the vendor states it is separate from Music 2.5; every track is yours on every plan including Free, Free allows commercial use provided ElevenMusic is credited, lossless downloads are capped at five per day on Free and 400 per month on Pro, tracks built on another artist song through Audio Reference cannot be downloaded, the Marketplace sells licences by usage type with creator earnings starting at 25 percent, and no licence permits distribution to streaming platforms such as Spotify. The official evidence for v2.5 over v2 is a self-run blind test in which v2.5 won the majority of 47,885 paired takes with the widest gap in vocal-led and acoustic-heavy genres. Boundaries: the API is paid-subscription only; vocals are documented for English, Spanish, German and Japanese with no Mandarin, so a Chinese language song is more practical on YuE2 or Suno; seed does not guarantee reproducibility; and it is closed source with no weights, so the self-hostable alternatives here are YuE2 for music and VoiceStudio or Kokoro-82M for speech. Graded C (vendor claim): quality was not recomputed and no blind listening test was run, but the API contract is verifiable documentation and every clause of it is listed in the body.
10 minAPI per-track duration cap (music_length_ms 3000-600000)Vendor Claim · 2026-09
Eleven v4: the generation that pushes cloning fidelity far enough to reproduce bad training data
The new generation speech synthesis model from ElevenLabs, shipping in two variants: Eleven v4 for highest quality and Eleven v4 Turbo for real time use at a median inference latency of about 100 ms, with an official footnote stating that application and network latency are excluded. The vendor positions it above v3 on output quality, voice accuracy, consistency, emotion, delivery, audio tags and language coverage, and recommends migrating. It sits at the top closed source voice row in the audio domain because this generation changed the optimisation target from sounding better to sounding more like the source: timbre, cadence, delivery and other mannerisms are reproduced together, and the vendor concedes that accuracy and personal preference are not always the same thing and that you may still prefer how a voice sounded in v3. The engineering consequence is hard, since the burden of data cleaning moves back to the user. The showcase samples are explicitly labelled raw, with no EQ, compression, normalisation, de-essing or plosive removal, and the vendor says that if you hear clipping or plosives they are very likely in the training data and the model simply captured them accurately. What is deliverable comes down to three numbers: about 100 ms on Turbo; 10,000 characters per request, roughly ten minutes of audio, against 5,000 on v3 so long form text carries twice as many segment seams; and a coverage claim of 90 plus languages against a FAQ that enumerates 87, a gap kept visible rather than smoothed away. Four boundaries matter. Cross language accent handling is a default behaviour change and not a toggle, so generating in a language that differs from the reference produces fluent native sounding speech in the target language, and the vendor calls a switchable version a research project with no timeline; any persona that depends on a native accent carried into a second language must be tested first. The control surface narrowed to Stability and Similarity, the Style and Speed sliders are gone, SSML is unsupported, and fine grained delivery moves to audio tags which the vendor admits are not perfect yet. Continuous model evolution is stated in writing, with training continuing after launch and behaviour possibly shifting over time, so teams treating a voice as a brand asset need periodic re-testing. Voice Design voices may also be less performative on v4. It is closed and not self-hostable, data must pass through ElevenLabs, and cloning compliance sits with the user; the self-hostable counterparts are CosyVoice 3, VibeVoice and Kokoro for speech and YuE2 for music under a non-commercial weight licence. This entry and the Eleven v3 already catalogued here are two generations of the same commercial stack rather than a replacement. Graded C (vendor claim): no verifiable third party benchmark, and no independent blind listening test.
~100msv4 Turbo median inference latency (model side, excl. app and network)Vendor Claim · 2026-09
Suno: the platform that pulls the second half of music production inside one product
The most complete commercial platform on the text-to-song route: a style description, your own lyrics, a hummed melody or a recorded riff all work as a starting point, a full song with vocals and instrumentation arrives in seconds, and the same product then extends it, edits sections, restyles it, extracts stems and remasters it. It sits at the top closed entry for music in the audio domain on workflow completeness rather than peak audio quality. Most generative music products cover drafting and picking a take and stop there; Suno connects the rest through stem extraction with up to 12 stems, MIDI export and Suno Studio, and Studio speaks conventional DAW semantics rather than adding another prompt box, with a multitrack timeline, take lanes, comping, manual BPM to settle tempo drift and per clip transpose and speed. Custom Models trains up to three private style variants from six or more tracks you own, and Voices, formerly Personas, generates in your own singing timbre with a verification step. The tier split matters: the free plan covers creation (generation, lyrics, Cover, crop and fade, audio upload) while stems, Add Vocals, Voices and Custom Models require Pro or Premier and Studio is Premier only on desktop web, so real cost modelling should assume Premier. Version numbers do not track quality on third party benchmarks either: on WildSongBench v5 scores 6.8721, above v6 at 6.5562 and v6 Wild at 6.4195, with v4.5 at 6.6995 and v5.5 at 6.7150, and the vendor itself asks for capability based rather than version based description. Limits: closed with no self-hosting, so unreleased melodies and lyrics must be uploaded; no stable version semantics, meaning a regeneration can sound different after a model update; commercial rights follow the tier; control granularity sits at section and style level with no editable chord track, so theory level edits require Studio multitrack re-arrangement or an open model such as YuE2 that exposes an ABC score. Graded C (vendor claim); the benchmark numbers are submitted by m-a-p and have not been recomputed.
6.8721WildSongBench SongBench mean (v5, third-party measurement)Vendor Claim · 2026-09
VoiceStudio: the commercial voice stack moved onto local hardware and opened to agents by default
An open source, fully local voice workstation (debpalash/VoiceStudio, AGPL-3.0, Python plus Electron) positioned as the local alternative to ElevenLabs: voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation, with a claimed 646 languages. Created on 2026-04-09 and at 42,831 stars and 5,005 forks on 2026-09-29. It sits at the top self-hosted row in the audio domain, not because any model behind it is stronger, but because the abstraction layer is useful. Open voice capability is scattered across a dozen repositories with their own weight formats, device requirements, cloning interfaces and licences, so assembling a pipeline of clone a voice, transcribe, align, dub and produce an audiobook spends most of its effort on glue. VoiceStudio collects 17 TTS and 11 ASR engines into one registry and reports per engine which devices it runs on (CUDA, MPS, CPU), whether it can clone, and its max_ref_seconds and ref_strategy, on top of a workflow that actually runs. The agent surface matters most for the catalogue: a local API and an MCP server ship as first class product features, the README includes an installation prompt ready to paste into Claude Code, Codex or Cursor, and npx skills add installs it as a skill, which means coding agents can call dubbing and transcription as tools rather than needing a human at the interface. The reference audio policy is equally rigorous, with a 75 second ceiling while how much of a longer clip reaches the model depends on the engine and is reported per engine, an automatic or saved transcript ignored beyond the limit, and a hard [clone_ref_too_long] error when sending more than 20 seconds plus transcript text to the default OmniVoice. One measurement point needs stating plainly: the official docs/benchmarks.md contains a real harness with per stage profiling, refusal to start when memory is insufficient, and a rule that only RTF warm and peak memory on named hardware and versions are accepted with no estimated numbers allowed, but the results column reads No verified rows yet. therefore attach no performance figure at all and the card carries only the star count verified ourselves through the GitHub API, which is what earns the A grade. That A asserts the number is real and nothing about being better than ElevenLabs. Four boundaries: AGPL-3.0 is strong copyleft with a network clause, so embedding it in a service offered to outsiders obliges you to release your own server side source, and closed commercial use means either process isolation calling only the local API under your own legal review or assembling the pipeline from Apache-2.0 pieces such as CosyVoice 3 or Kokoro; per-model licences are not settled by the wrapper, since the Breeze-TTS-2 weights behind audio.cpp are research and non-commercial, Supertonic-3 and PocketTTS need extra permissions and GPT-SoVITS requires its own server, so check every model before commercial use; the 646 language figure is the repository own claim and real coverage depends on the engine chosen, from 25 European languages on Parakeet through 50 plus on FunASR to the wider Whisper family, unverified language by language; and desktop is Electron only now, with 0.5.3 the last Tauri release, so existing users must migrate. It sits alongside Eleven v4 on the ladder rather than replacing it, one representing the quality ceiling and convenience of a closed commercial stack and the other the data sovereignty and engine substitutability of local self-hosting.
42,831GitHub stars (2026-09-29, verified here via GitHub API)Confirmed · 2026-09
Gemini Omni: moving the unit of video delivery from one attempt to a conversational editing process
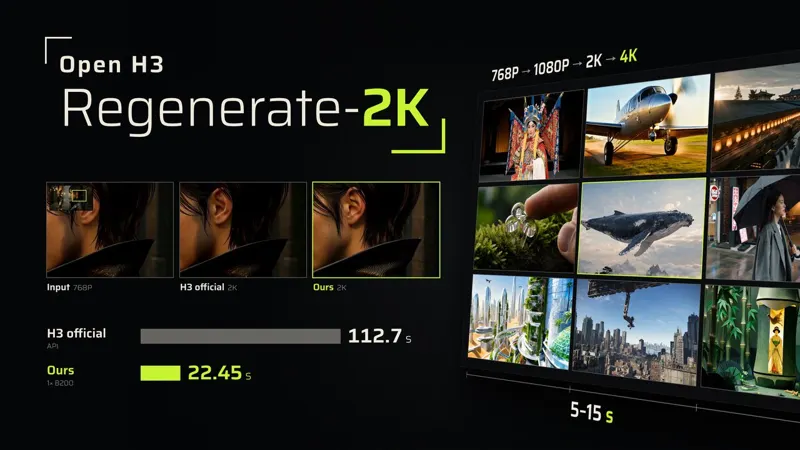
Google DeepMind's video and multimodal generation model, officially create anything from any input, starting with video: it edits video through step-by-step conversation, each edit building on the last and keeping the scene coherent, raising the unit of delivery from one shot to footage you can keep revising; the other two surfaces are real-world knowledge and arbitrary reference composition. Read the level with its votes: on the Artificial Analysis arena (2026-09-22) gemini-omni-1.1-flash is #1 for text-to-video at Elo 1516 with only 1,784 votes and a ±15 CI, while #2 is the sibling at 1513 with 26,576 votes and ±9, a 3-point gap far smaller than either CI, so statistically indistinguishable: the honest statement is that the Omni family ties for the top. For image-to-video minimax-h3 leads (1495, 57,112 votes) with Omni #2 at 1488 on 3,734 votes. Pricing: $1.50 per million input tokens, $9.00 text and $17.50 video output, 720p about $0.10 per second and a 30-second clip roughly $3. GA to paid-tier developers, none on the free tier. Closed, not self-hostable, not fine-tunable. Graded A (confirmed), the first A-grade video asset; A means the reading is credible and checkable, not undisputed first place.
1516Arena T2V Elo (1,784 votes)Confirmed · 2026-09
Eleven v3: the commercial audio stack that covers speaking, listening and singing
ElevenLabs' flagship speech synthesis model, officially its most emotive and expressive: 70+ languages, a 5,000-character request cap, dramatic delivery and natural multi-speaker dialogue, with a separate Text to Dialogue API making multi-character dialogue an endpoint, not a prompt trick. It sits at a top row in audio for the stack behind it: the only commercial one covering speaking, listening and singing, with four TTS tiers, three ASR tiers including a Medical build and two music models. The TTS tiers are mutually exclusive: v3 is most expressive but non-realtime at 5,000 characters, Flash v2.5 is lowest latency (about 75ms, 50% cheaper per character) and Multilingual v2 is most stable for long text at 29 languages. On ASR, Scribe v2 covers 90+ languages with diarisation for 32 speakers. Latency figures are model-side only, excluding network and upstream LLM time, not SLAs. Limits: you split long text and own continuity across the seams; closed and not self-hostable, a hard barrier where data sovereignty matters. No speech board among the boards synced here, so listed alongside Gemini 3.8 Flash TTS without ranking. Graded C (vendor-stated): no WER recomputation or independent blind listening test.
Gemini 3.8 Flash TTS: turning director-level voice direction into API parameters
Google's speech generation model (gemini-3.8-flash-tts), positioned for studio-grade voice fidelity, expressive acting and long-form stability, the most overlooked being the last: audiobook failure is not an ugly sentence but timbre drift by hour three. The design separates scopes: text is strictly a script while performance direction travels on another channel and is never read aloud, fixing "(sighs)" that used to be spoken; round style goes into speech_metadata.style, word-level emotion into pipe tags. Four voice sources: prebuilt, an extended library, voice design IDs (describe it, then reuse) and replication IDs; design and replication arrived only in 3.8. Specs: 130 languages with automatic language detection, WAV by default at 24 kHz, at most 2 speakers per request and only with prebuilt voices. Billing is per audio token at 25 tokens per second, $0.50 input and $9.00 output per million through 2026-12-31 then $1.00/$18.00. Limits: 24 kHz is not mastering grade; replication compliance rests with the user. No speech board among the 12 synced here, so listed alongside ElevenLabs v3 without ranking. Graded C (vendor-stated): no intelligibility or independent blind listening test.
All supportedVoice design + cloning + multi-speakerVendor Claim · 2026-09
Kling 3.0 series: native audio, 4K frames, and parameterised camera language as the moat
Kuaishou Kling was among the first Chinese video lines to reach a level where it can take commercial work, and its lasting strength is not raw text-to-video but image-to-video plus camera control: lock composition and character in the image stage, then let the video model interpolate from that fixed keyframe, with first/last-frame constraints and push/pull/pan/truck/orbit/follow parameters producing predictable clips. The 3.0 series (official release-note banner: API fully available) brings three substantive jumps - audio generated natively (5s/10s/12s audio tiers), native 2K/4K for both image and video, and storyboarding plus element reference turning multi-shot coherence from an editing problem into something the model controls; the line-up is 3.0 / 3.0 Omni / 3.0 Turbo, Kling Image 3.0 and -omni, Native 4K Video and Motion Control. The arena reading, stated plainly: image-to-video kling-v3-pro is #19 (Elo 1354), behind MiniMax h3, gemini-omni, wan3.0 and seedance-2.5. No authoritative release date for the 3.0 series could be obtained, so the metric date is recorded only at the verifiable month, 2026-09. Closed, vendor API only; not independently benchmarked, graded C.
3.0 / Omni / TurboCurrent flagship seriesVendor Claim · 2026-09
Let Claude Code produce 3Blue1Brown-style explainers with Manim
Editor's takeStep three is the point: the agent owns the render-until-success loop instead of handing errors back to you. That is exactly where Manim costs humans the most, since one wrong coordinate means another ten-second re-render. The repo also writes 'avoid generic AI slop aesthetics' into its goals, treating taste as a requirement rather than luck, and keeps plan.md as a separate file so iteration does not require re-explaining context.
156 stars, MIT, site manimate.ai. Four steps: Plan (storyboard, optionally in plan mode), Code (write Manim scenes in Python), Render (keep going until every scene renders successfully) and Iterate (open the video viewer in a browser and paste your notes back). The project layout is fixed as plan.md, script.py, concat.txt and final.mp4.