Video generation and speech/audio in one channel: physical and temporal coherence for text/image-to-video, TTS naturalness and voice cloning, music generation, and ASR
Audio and video share one channel because the generation side stopped being two separate pipelines long ago, and because what a reader actually wants was never a silent clip plus a separate voice track. The frontier is joint generation: picture, ambience and speech coming out of one forward pass, with lip movement matching phonemes or the whole thing does not count. That capability belongs to video and audio at the same time, and splitting it across two entrances forces the reader to assemble one conclusion out of two pages. One nav entry per reader task ("I need a usable piece of footage") is why the channel exists.
The two rulers are still not merged, which is why this page draws member segments instead of one blended ladder. Video is measured on temporal coherence (an object staying identical across frames), physical plausibility (gravity, collision, occlusion) and controllability (camera move, duration, first and last frame constraints), read through VBench, EvalCrafter and arena Elo. Audio is measured on TTS naturalness, voice cloning similarity, ASR WER and music generation preference. Blending them into one ruler collapses "how far is video" and "how far is speech" into a single answer that addresses neither.
Read the current numbers in three parts. On video, the top of the ladder is Gemini Omni (create anything from any input, editing footage through successive turns of conversation, which moves the unit of delivery from one gamble to one editable asset). On the text-to-video arena board we sync (2026-09-22) the leader gemini-omni-1.1-flash sits at Elo 1516 on only 1,784 votes with CI plus or minus 15, while number two from the same family is 1513 on 26,576 votes with plus or minus 9; a 3 point gap far inside both intervals is not distinguishable, so the honest reading is that the Omni family is tied for first. On image-to-video the leader is minimax-h3 (1495, 57,112 votes). Seedance 2.5 (30s of single-pass narrative), the Kling 3.0 family and open-weight Wan sit in the same domain. On audio, split speech from music: speech is Eleven v4 Turbo (median model-side inference latency around 100ms), Gemini 3.8 Flash TTS (130 languages, voice design and cloning, at most 2 speakers per request), Eleven v3 (70+ languages, 5,000 characters per request) and the open source local VoiceStudio (42,831 stars, running a full TTS/ASR/music pipeline offline); music is Suno v5 and open weight YuE2, both carrying third-party SongBench means from WildSongBench.
Kling (video+image+audio) and Seedance (video+audio) qualify for both member domains through joint generation. Their appearing in both segments is deliberate rather than duplicate collection: a reader arriving by the video ruler must see them, and so must a reader arriving by the audio ruler.
RULERVideo: VBench, EvalCrafter, physical & temporal coherence. Audio: TTS naturalness, voice cloning similarity, music generation, ASR WER
Gemini Omni: moving the unit of video delivery from one attempt to a conversational editing process
Google DeepMind's video and multimodal generation model, officially create anything from any input, starting with video: it edits video through step-by-step conversation, each edit building on the last and keeping the scene coherent, raising the unit of delivery from one shot to footage you can keep revising; the other two surfaces are real-world knowledge and arbitrary reference composition. Read the level with its votes: on the Artificial Analysis arena this site syncs (2026-09-22) gemini-omni-1.1-flash is #1 for text-to-video at Elo 1516 with only 1,784 votes and a ±15 CI, while #2 is the sibling at 1513 with 26,576 votes and ±9, a 3-point gap far smaller than either CI, so statistically indistinguishable: the honest statement is that the Omni family ties for the top. For image-to-video minimax-h3 leads (1495, 57,112 votes) with Omni #2 at 1488 on 3,734 votes. Pricing: $1.50 per million input tokens, $9.00 text and $17.50 video output, 720p about $0.10 per second and a 30-second clip roughly $3. GA to paid-tier developers, none on the free tier. Closed, not self-hostable, not fine-tunable. Graded A (confirmed), our first A-grade video asset; A means the reading is credible and checkable, not undisputed first place.
Kling 3.0 series: native audio, 4K frames, and parameterised camera language as the moat
Kuaishou Kling was among the first Chinese video lines to reach a level where it can take commercial work, and its lasting strength is not raw text-to-video but image-to-video plus camera control: lock composition and character in the image stage, then let the video model interpolate from that fixed keyframe, with first/last-frame constraints and push/pull/pan/truck/orbit/follow parameters producing predictable clips. The 3.0 series (official release-note banner: API fully available) brings three substantive jumps - audio generated natively (5s/10s/12s audio tiers), native 2K/4K for both image and video, and storyboarding plus element reference turning multi-shot coherence from an editing problem into something the model controls; the line-up is 3.0 / 3.0 Omni / 3.0 Turbo, Kling Image 3.0 and -omni, Native 4K Video and Motion Control. The arena reading, stated plainly: image-to-video kling-v3-pro is #19 (Elo 1354), behind MiniMax h3, gemini-omni, wan3.0 and seedance-2.5. We could not obtain an authoritative release date for the 3.0 series, so the metric date is recorded only at the verifiable month, 2026-09. Closed, vendor API only; not benchmarked by us, graded C.
Seedance 2.5: raising the unit of video delivery from one shot to a 30-second story beat
ByteDance Seed line for video generation. The 1.x tiers were silent short clips from text or image; from 2.0 the architecture is a unified multimodal audio-video joint generator taking text, image, audio and video as inputs; 2.5 raises the unit of delivery to a 30-second story beat with two further extensions, white-model control, green-screen editing, professional camera work and performance direction. Its third-party reading is the strongest part: on the Artificial Analysis arena this site syncs (2026-09-22), dreamina-seedance-2.5-720p is #4 for image-to-video (Elo 1477), with 2.0 #5 (1479) and 2.5 #7 (1474) for text-to-video. Closed, reachable only through Dreamina / Volcano Engine / BytePlus, no self-hosting or fine-tuning; SeedVideoBench-2.0 is internal and cannot be reproduced. Not benchmarked by us; graded C (vendor-stated).
Wan: the open-weights baseline on the video side, letting the whole ecosystem iterate on its own hardware
Alibaba Tongyi's Wan releases video generation weights under Apache-2.0, making it the most important public baseline in the video domain. Its value differs from a closed service: not "best-looking output today" but that it is fine-tunable, reproducible and runnable on your own inference stack - the whole ecosystem of LoRAs, ControlNet-style conditioning, quantisation and few-step distillation builds on it. For an intelligence site, an open-weights baseline means the question "what can video generation do today" finally has a reference we can verify ourselves instead of trusting vendor-selected samples. The licence and the public repository we have verified; picture quality and physical plausibility remain C-grade vendor claims.
FLUX: the line that moved image generation from "produce a picture" to controllable editing with open weights
Black Forest Labs' FLUX family generates images with a rectified-flow transformer and ships Apache-2.0 dev weights, making it the most important open baseline on the image side; the Kontext tier turned "edit this part of the image on instruction without disturbing the rest" into a usable capability. Our own collected record also covers the FLUX 3 launch, which the vendor positions as a world model unifying image, video and audio - a claim we log as unverified.
TTS naturalness, voice cloning, music generation, ASR
RULERTTS naturalness, voice cloning, music generation, ASR WER
Speech & AudioMediaTopC
Eleven Music v2.5: the closed-source row that turns music generation into a callable pipeline
The music generation model from ElevenLabs, currently at v2.5, released 2026-09-11 with the release post last updated 2026-09-20. We list it as the engineering-side top row for music in the audio domain, which contrasts with rather than duplicates the Suno entry already catalogued here: the value of Suno concentrates inside the product, a Studio multi-track timeline, Custom Models, up to twelve stems and MIDI export, while Eleven Music splits comparable capability into endpoints, namely compose, stream, a structured composition plan, scoring an uploaded video, uploading existing audio, stem separation, finetunes and section level inpainting, plus a marketplace where creators license tracks to each other. Choosing between them therefore needs no audio quality comparison, only one question: is this track something a person sits and adjusts, or something a pipeline requests in volume. The API surface is nine endpoints rather than one generate call, and two details matter for procurement: both compose and stem-separation take a sign_with_c2pa flag that applies to mp3 output so outgoing files can carry content credentials, and output format is tied to subscription tier, with mp3_44100_192 requiring Creator or above and pcm_44100 requiring Pro or above on stem-separation and video-to-music while compose goes up to mp3_48000_320, so the threshold for lossless differs per endpoint. The trap worth memorising is that v2.5 is already the interface default yet the model_id enum of music_v1, music_v2 and music_v2_5 still defaults to music_v1, and output_format=auto resolves per model to mp3_44100_128 on v1 and mp3_48000_192 on v2, so a minimal call that omits model_id silently gets the oldest generation at a lower bitrate; pin both in production code and name mp3_48000_320 when 320kbps is required. The two plan schemas are not interchangeable and the wrong pairing is a hard error: music_v1 takes MusicPrompt while music_v2 and music_v2_5 take CompositionPlan, whose chunks carry a text field with square bracket section names, lyric lines and curly brace inline directions. On the control surface prompt and composition_plan are mutually exclusive, and the request takes music_length_ms from 3000 to 600000, that is three seconds to ten minutes, plus force_instrumental, finetune_id and seed. Rights and commercial use are the most structured part of this line: a multi-year agreement with Universal Music Group was announced alongside v2.5 and the vendor states it is separate from Music 2.5; every track is yours on every plan including Free, Free allows commercial use provided ElevenMusic is credited, lossless downloads are capped at five per day on Free and 400 per month on Pro, tracks built on another artist song through Audio Reference cannot be downloaded, the Marketplace sells licences by usage type with creator earnings starting at 25 percent, and no licence permits distribution to streaming platforms such as Spotify. The official evidence for v2.5 over v2 is a self-run blind test in which v2.5 won the majority of 47,885 paired takes with the widest gap in vocal-led and acoustic-heavy genres. Boundaries: the API is paid-subscription only; vocals are documented for English, Spanish, German and Japanese with no Mandarin, so a Chinese language song is more practical on YuE2 or Suno; seed does not guarantee reproducibility; and it is closed source with no weights, so the self-hostable alternatives here are YuE2 for music and VoiceStudio or Kokoro-82M for speech. Graded C (vendor claim): quality was not recomputed and we ran no blind listening test, but the API contract is verifiable documentation and every clause of it is listed in the body.
Eleven v4: the generation that pushes cloning fidelity far enough to reproduce bad training data
The new generation speech synthesis model from ElevenLabs, shipping in two variants: Eleven v4 for highest quality and Eleven v4 Turbo for real time use at a median inference latency of about 100 ms, with an official footnote stating that application and network latency are excluded. The vendor positions it above v3 on output quality, voice accuracy, consistency, emotion, delivery, audio tags and language coverage, and recommends migrating. We list it as the top closed source voice row in the audio domain because this generation changed the optimisation target from sounding better to sounding more like the source: timbre, cadence, delivery and other mannerisms are reproduced together, and the vendor concedes that accuracy and personal preference are not always the same thing and that you may still prefer how a voice sounded in v3. The engineering consequence is hard, since the burden of data cleaning moves back to the user. The showcase samples are explicitly labelled raw, with no EQ, compression, normalisation, de-essing or plosive removal, and the vendor says that if you hear clipping or plosives they are very likely in the training data and the model simply captured them accurately. What is deliverable comes down to three numbers: about 100 ms on Turbo; 10,000 characters per request, roughly ten minutes of audio, against 5,000 on v3 so long form text carries twice as many segment seams; and a coverage claim of 90 plus languages against a FAQ that enumerates 87, a gap we keep visible rather than smoothing away. Four boundaries matter. Cross language accent handling is a default behaviour change and not a toggle, so generating in a language that differs from the reference produces fluent native sounding speech in the target language, and the vendor calls a switchable version a research project with no timeline; any persona that depends on a native accent carried into a second language must be tested first. The control surface narrowed to Stability and Similarity, the Style and Speed sliders are gone, SSML is unsupported, and fine grained delivery moves to audio tags which the vendor admits are not perfect yet. Continuous model evolution is stated in writing, with training continuing after launch and behaviour possibly shifting over time, so teams treating a voice as a brand asset need periodic re-testing. Voice Design voices may also be less performative on v4. It is closed and not self-hostable, data must pass through ElevenLabs, and cloning compliance sits with the user; the self-hostable counterparts are CosyVoice 3, VibeVoice and Kokoro for speech and YuE2 for music under a non-commercial weight licence. This entry and the Eleven v3 already catalogued here are two generations of the same commercial stack rather than a replacement. Graded C (vendor claim): no verifiable third party benchmark, and no blind listening test by us.
Suno: the platform that pulls the second half of music production inside one product
The most complete commercial platform on the text-to-song route: a style description, your own lyrics, a hummed melody or a recorded riff all work as a starting point, a full song with vocals and instrumentation arrives in seconds, and the same product then extends it, edits sections, restyles it, extracts stems and remasters it. We list it as the top closed entry for music in the audio domain on workflow completeness rather than peak audio quality. Most generative music products cover drafting and picking a take and stop there; Suno connects the rest through stem extraction with up to 12 stems, MIDI export and Suno Studio, and Studio speaks conventional DAW semantics rather than adding another prompt box, with a multitrack timeline, take lanes, comping, manual BPM to settle tempo drift and per clip transpose and speed. Custom Models trains up to three private style variants from six or more tracks you own, and Voices, formerly Personas, generates in your own singing timbre with a verification step. The tier split matters: the free plan covers creation (generation, lyrics, Cover, crop and fade, audio upload) while stems, Add Vocals, Voices and Custom Models require Pro or Premier and Studio is Premier only on desktop web, so real cost modelling should assume Premier. Version numbers do not track quality on third party benchmarks either: on WildSongBench v5 scores 6.8721, above v6 at 6.5562 and v6 Wild at 6.4195, with v4.5 at 6.6995 and v5.5 at 6.7150, and the vendor itself asks for capability based rather than version based description. Limits: closed with no self-hosting, so unreleased melodies and lyrics must be uploaded; no stable version semantics, meaning a regeneration can sound different after a model update; commercial rights follow the tier; control granularity sits at section and style level with no editable chord track, so theory level edits require Studio multitrack re-arrangement or an open model such as YuE2 that exposes an ABC score. Graded C (vendor claim); the benchmark numbers are submitted by m-a-p and have not been recomputed by us.
VoiceStudio: the commercial voice stack moved onto local hardware and opened to agents by default
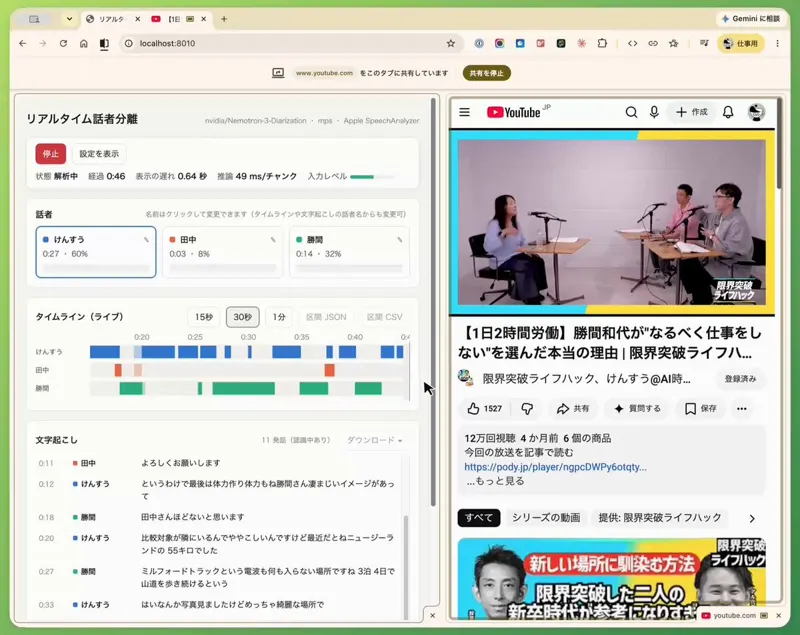
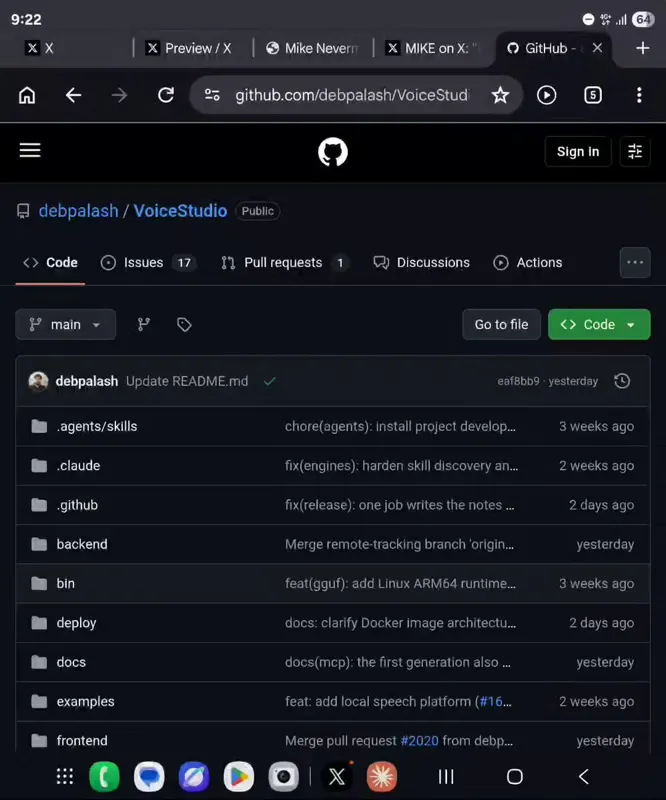
An open source, fully local voice workstation (debpalash/VoiceStudio, AGPL-3.0, Python plus Electron) positioned as the local alternative to ElevenLabs: voice cloning, voice design, video dubbing, dictation, transcription and audiobook creation, with a claimed 646 languages. Created on 2026-04-09 and at 42,831 stars and 5,005 forks on 2026-09-29. We list it as the top self-hosted row in the audio domain, not because any model behind it is stronger, but because the abstraction layer is useful. Open voice capability is scattered across a dozen repositories with their own weight formats, device requirements, cloning interfaces and licences, so assembling a pipeline of clone a voice, transcribe, align, dub and produce an audiobook spends most of its effort on glue. VoiceStudio collects 17 TTS and 11 ASR engines into one registry and reports per engine which devices it runs on (CUDA, MPS, CPU), whether it can clone, and its max_ref_seconds and ref_strategy, on top of a workflow that actually runs. The agent surface matters most for this site: a local API and an MCP server ship as first class product features, the README includes an installation prompt ready to paste into Claude Code, Codex or Cursor, and npx skills add installs it as a skill, which means coding agents can call dubbing and transcription as tools rather than needing a human at the interface. The reference audio policy is equally rigorous, with a 75 second ceiling while how much of a longer clip reaches the model depends on the engine and is reported per engine, an automatic or saved transcript ignored beyond the limit, and a hard [clone_ref_too_long] error when sending more than 20 seconds plus transcript text to the default OmniVoice. One measurement point needs stating plainly: the official docs/benchmarks.md contains a real harness with per stage profiling, refusal to start when memory is insufficient, and a rule that only RTF warm and peak memory on named hardware and versions are accepted with no estimated numbers allowed, but the results column reads No verified rows yet. We therefore attach no performance figure at all and the card carries only the star count we verified ourselves through the GitHub API, which is what earns the A grade. That A asserts the number is real and nothing about being better than ElevenLabs. Four boundaries: AGPL-3.0 is strong copyleft with a network clause, so embedding it in a service offered to outsiders obliges you to release your own server side source, and closed commercial use means either process isolation calling only the local API under your own legal review or assembling the pipeline from Apache-2.0 pieces such as CosyVoice 3 or Kokoro; per-model licences are not settled by the wrapper, since the Breeze-TTS-2 weights behind audio.cpp are research and non-commercial, Supertonic-3 and PocketTTS need extra permissions and GPT-SoVITS requires its own server, so check every model before commercial use; the 646 language figure is the repository own claim and real coverage depends on the engine chosen, from 25 European languages on Parakeet through 50 plus on FunASR to the wider Whisper family, unverified by us language by language; and desktop is Electron only now, with 0.5.3 the last Tauri release, so existing users must migrate. It sits alongside Eleven v4 on the ladder rather than replacing it, one representing the quality ceiling and convenience of a closed commercial stack and the other the data sovereignty and engine substitutability of local self-hosting.
42,831GitHub Stars(2026-09-29,本站经 GitHub API 核)Confirmed · 2026-09
Eleven v3: the commercial audio stack that covers speaking, listening and singing
ElevenLabs' flagship speech synthesis model, officially its most emotive and expressive: 70+ languages, a 5,000-character request cap, dramatic delivery and natural multi-speaker dialogue, with a separate Text to Dialogue API making multi-character dialogue an endpoint, not a prompt trick. We list it as a top row in audio for the stack behind it: the only commercial one covering speaking, listening and singing, with four TTS tiers, three ASR tiers including a Medical build and two music models. The TTS tiers are mutually exclusive: v3 is most expressive but non-realtime at 5,000 characters, Flash v2.5 is lowest latency (about 75ms, 50% cheaper per character) and Multilingual v2 is most stable for long text at 29 languages. On ASR, Scribe v2 covers 90+ languages with diarisation for 32 speakers. Latency figures are model-side only, excluding network and upstream LLM time, not SLAs. Limits: you split long text and own continuity across the seams; closed and not self-hostable, a hard barrier where data sovereignty matters. No speech board among the ones we sync, so listed alongside Gemini 3.8 Flash TTS without ranking. Graded C (vendor-stated): no WER recomputation or blind listening test by us.
Gemini 3.8 Flash TTS: turning director-level voice direction into API parameters
Google's speech generation model (gemini-3.8-flash-tts), positioned for studio-grade voice fidelity, expressive acting and long-form stability, the most overlooked being the last: audiobook failure is not an ugly sentence but timbre drift by hour three. The design separates scopes: text is strictly a script while performance direction travels on another channel and is never read aloud, fixing "(sighs)" that used to be spoken; round style goes into speech_metadata.style, word-level emotion into pipe tags. Four voice sources: prebuilt, an extended library, voice design IDs (describe it, then reuse) and replication IDs; design and replication arrived only in 3.8. Specs: 130 languages with automatic language detection, WAV by default at 24 kHz, at most 2 speakers per request and only with prebuilt voices. Billing is per audio token at 25 tokens per second, $0.50 input and $9.00 output per million through 2026-12-31 then $1.00/$18.00. Limits: 24 kHz is not mastering grade; replication compliance rests with the user. No speech board among the 12 we sync, so listed alongside ElevenLabs v3 without ranking. Graded C (vendor-stated): no intelligibility or blind listening test by us.
Fun-CosyVoice3-0.5B: open TTS that turns controllability into an interface
The third generation LLM based speech synthesis system from the FunAudioLLM group at Alibaba, 0.5B parameters, released as Fun-CosyVoice3-0.5B-2512 with base and RL weight sets plus training and inference scripts; the code repository has moved to QwenAudio/CosyVoice (Apache-2.0, 23,794 stars, verified through the GitHub API on 2026-09-29). We list it as the open source top row for speech in the audio domain, and the reason is not that it sounds most human but that it gives each of the four failure modes of production TTS an explicit interface: misread polyphonic characters go through pronunciation correction with Chinese pinyin or English CMU phonemes written straight into the input, wrong readings of numbers and symbols go through the built in text normalisation, collapsed long sentences go through RAS repetition aware sampling, and low latency goes through bidirectional streaming with an official first packet at 150ms, which is the right order of magnitude to sit inside a realtime conversational agent. Three readings matter on the metric sheet. The test-zh speaker similarity of 78.0 is the highest among 0.5B open models and above the human baseline of 75.5, yet still below the closed source Seed-TTS at 79.6, so open source first holds while world first does not. The test-hard column is the real strength, base 6.71 and RL 5.44 being the lowest in the table and better than the closed source 7.59, and hard is exactly long sentences and tongue twisters, so that lead maps to usable real scripts. English needs a discount: base test-en similarity 71.8 sits below the human baseline 73.4 and only the RL tier WER of 1.68 recovers it. Base and RL are two post training weights of one architecture, with all three error rates falling (zh CER down 33 percent, hard CER down 19 percent) and all three similarities slipping slightly, which is a good trade for broadcast and support workloads where one misread character is an incident, while voice fidelity work for a specific IP should audition the RL tier first. The repository also ships GRPO training scripts and a triton plus TensorRT-LLM runtime claimed at four times the speed of HF transformers, so post training is a path others can continue rather than a one off delivery, and the language surface covers nine languages with more than eighteen Chinese dialect accents, a tier the closed APIs still barely offer. Boundaries: the licence is two layered, Apache-2.0 for code while the weight terms live on the model pages and must be checked separately before commercial use; every reading comes from the evaluation of the authors themselves with no third party blind listening table to cross check and we did not recompute; zero shot cloning similarity comes from standard sets while real deployments depend on the noise and style of the reference recording. Graded C (vendor claim).
Kokoro-82M: an Apache-2.0 TTS trained for a thousand dollars
An open weight TTS model from hexgrad at 82M parameters under Apache-2.0, repository hexgrad/kokoro (9,061 stars, verified through the GitHub API on 2026-09-29). We list it as the cost floor and the licence floor of the audio domain: what deserves to be remembered is not a leaderboard position but the fact that it published the full arithmetic of what one TTS deployment costs. Total training cost was 1000 dollars, being 500 A100 80GB GPU hours for each of v0.19 and v1.0; v0.19 (2024-12-25) trained on under 100 hours of audio with one language and ten voices, while v1.0 (2025-01-27) used a few hundred hours across eight languages and 54 voices. On price, two independent third party sources point at the same order of magnitude: ArtificialAnalysis records 65 cents per million characters on Replicate and DeepInfra lists 80 cents per million characters, which works out to roughly three to five cents per finished hour of audio. That price line is the reference floor for every comparison we make in the audio domain: whatever costs more than it is buying voice cloning, dialect coverage, emotion control, streaming latency or compliance backing, not the ability to be listened to at all. The technical form is a decoder-only StyleTTS 2 plus ISTFTNet stack with no diffusion and an unpublished encoder, G2P through the author maintained misaki library, espeak-ng on the system side and 24kHz output; input text accepts inline phoneme overrides such as [Kokoro](/kˈOkəɹO/), the same idea as the pinyin and CMU phoneme level pronunciation correction in CosyVoice 3, turning misreading from a probability problem into declarative configuration, except the scope here is a word rather than a whole prosody. The decoder-only shape also decides what it cannot do: there is no zero shot voice cloning, the 54 voices are trained in and a reference clip will not grow a new one, which is a division of labour rather than a defect. The compliance disclosure is close to unique in TTS: the model card states that only permissively licensed or copyright free audio was used, lists public domain audio, Apache and MIT licensed audio and synthetic audio generated by closed source TTS models as separate classes, explicitly excludes synthetic audio from open TTS models and custom voice cloning, publishes a CC BY attribution table, and publishes the model SHA256 so you can verify the weights you downloaded are the same ones. Boundaries: no voice cloning, so reference driven use cases are out; 24kHz is enough for broadcast and reading but not for music grade masters; the eight languages and 54 voices have not grown since v1.0 and Mandarin usability needs your own audition; the project is close to dormant with the last push on 2025-08-06, so bugs are yours to fix; and its fame has grown a phishing surface, with the model card naming lookalike domains containing kokoro as unrelated to the project, the only real entries being hexgrad/Kokoro-82M on Hugging Face and hexgrad/kokoro on GitHub, so never pay a search result that calls itself the Kokoro official site. Graded B (confirmed): what is confirmed is the cost and market price chain with independent third party sources, not audio quality.
Kling 3.0 series: native audio, 4K frames, and parameterised camera language as the moat
Kuaishou Kling was among the first Chinese video lines to reach a level where it can take commercial work, and its lasting strength is not raw text-to-video but image-to-video plus camera control: lock composition and character in the image stage, then let the video model interpolate from that fixed keyframe, with first/last-frame constraints and push/pull/pan/truck/orbit/follow parameters producing predictable clips. The 3.0 series (official release-note banner: API fully available) brings three substantive jumps - audio generated natively (5s/10s/12s audio tiers), native 2K/4K for both image and video, and storyboarding plus element reference turning multi-shot coherence from an editing problem into something the model controls; the line-up is 3.0 / 3.0 Omni / 3.0 Turbo, Kling Image 3.0 and -omni, Native 4K Video and Motion Control. The arena reading, stated plainly: image-to-video kling-v3-pro is #19 (Elo 1354), behind MiniMax h3, gemini-omni, wan3.0 and seedance-2.5. We could not obtain an authoritative release date for the 3.0 series, so the metric date is recorded only at the verifiable month, 2026-09. Closed, vendor API only; not benchmarked by us, graded C.
Seedance 2.5: raising the unit of video delivery from one shot to a 30-second story beat
ByteDance Seed line for video generation. The 1.x tiers were silent short clips from text or image; from 2.0 the architecture is a unified multimodal audio-video joint generator taking text, image, audio and video as inputs; 2.5 raises the unit of delivery to a 30-second story beat with two further extensions, white-model control, green-screen editing, professional camera work and performance direction. Its third-party reading is the strongest part: on the Artificial Analysis arena this site syncs (2026-09-22), dreamina-seedance-2.5-720p is #4 for image-to-video (Elo 1477), with 2.0 #5 (1479) and 2.5 #7 (1474) for text-to-video. Closed, reachable only through Dreamina / Volcano Engine / BytePlus, no self-hosting or fine-tuning; SeedVideoBench-2.0 is internal and cannot be reproduced. Not benchmarked by us; graded C (vendor-stated).
VibeVoice: a 7.5Hz token rate buys 90 minutes of speech in one pass
The open frontier speech model family from Microsoft, repository microsoft/VibeVoice (MIT, 54,531 stars, verified through the GitHub API). We catalogue it as one asset rather than three because TTS, Realtime and ASR share a single technical core: both the acoustic and the semantic tokenizer are continuous rather than quantised into discrete codebooks, and the frame rate is pushed down to 7.5Hz. That 7.5Hz is where every capability comes from. Ninety minutes of audio at 25Hz is 135,000 tokens and does not fit a 64K context, while at 7.5Hz it is 40,500, so single pass synthesis of 90 minutes and single pass transcription of 60 minutes are two directions of the same fact rather than two separate engineering feats. Five product lines each carry their own ceiling: TTS-1.5B at 90 minutes per run with up to four speakers, Realtime-0.5B at roughly 300ms to first packet, ASR-7B transcribing 60 minutes in one pass while emitting who said what and when with custom hotwords across more than 50 languages, ASR-Streaming emitting text as speech arrives, and ASR-BitNet using heterogeneous quantisation to compress 4.62GB into 1.58GB with RTF under 1 on three or more CPU threads and no GPU. The ASR line is the one worth remembering: conventional long form transcription chains slicing, recognition, diarisation and timestamp alignment, and the global context is lost at the slice boundary, while VibeVoice-ASR fuses recognition, diarisation and timestamps into a single generation, which is the difference between usable and unusable for meeting minutes and support QA. The architecture is next token diffusion, with the LLM owning conversational direction and the diffusion head owning acoustic detail, because turn consistency over a long dialogue is a language problem and only the LLM can hold four speakers distinct across 90 minutes. One fact must be recorded plainly: on 2025-09-05 the team removed the VibeVoice-TTS code from the repository, stating that usage inconsistent with its declared intent had been observed; the weights remain on Hugging Face but the Quick Try section reads Disabled, the official inference scripts are gone and today the TTS path runs through community reproductions, with the model page advising against commercial or real world use without further testing. Every public move since has been on the ASR side, so the commercially usable half is ASR rather than TTS. Its position in tables published by others must also be reported as written: the CosyVoice 3 README lists it at test-zh CER 1.16 with similarity 74.4 and test-en WER 3.04 with similarity 68.9, against CosyVoice3 base at 1.21 and 78.0. Short clip zero shot cloning is not its lane; the three comparisons that matter are how long a single run can be, whether four speakers stay distinct, and whether one hour of meeting audio can be processed in one pass, and on those three the open source field has almost no rival. Boundaries: no official TTS inference path; MIT covers code but not the usage limits on the model page; long form failure is global, since a 90 minute single pass has no retry one segment at a time fallback; the official Risks and Limitations section names deepfakes and requires disclosure of AI involvement. Graded B (confirmed): what is confirmed is the frame rate arithmetic, the published ceilings of each line, the code removal and the licence boundary, not audio quality, which we only relay without recomputing or blind listening.
YuE2-3B: open song generation that exposes the score as an interface
The open song generation model from m-a-p, 3B parameters, weights under CC-BY-NC-4.0, turning lyrics and a style prompt into a complete song with vocals and accompaniment at 48 kHz stereo. We list it as the open-weight top row for music in the audio domain on the strength of a combination that is close to unique among its peers: open weights plus an editable intermediate representation. One AR-NAR Mixture-of-Transformers backbone writes an ABC score (melody and chords) and semantic tokens, flow matching then produces acoustic latents and a VAE decodes them, so the score is an artefact that a person or an agent can read and edit instead of a black box whose only control is another sample. Three cot modes (full, melody, off) map onto composing, covering and direct generation, and the official agentic editing demo runs nine turns across fourteen versions from Mandarin pop to English jazz. Read the benchmark protocol carefully: on 192 WildSongBench prompts the best-of-8 SongBench average of 6.9632 sits above Suno v5 at 6.8721 and Suno v6 at 6.5562, but that is eight candidates with selection against a delivered single candidate; MuLan and AllMusicCaps, the two style-text alignment measures, still favour Suno v5, and PER at 8.44 percent trails Suno v6 Wild at 7.45 and MiniMax Music 3 at 6.27. Cost is the most concrete advantage: a 3.6 minute song in 71 seconds on an RTX 4090 24GB with a peak of 11.18 GiB, and 373 songs per hour on an H800 with vLLM at AR concurrency 32. Limits: non-commercial licence; identity preservation in covers comes almost entirely from a supplied score (CLEWS mAP collapses to 0.006 without one); the benchmark runs on the legacy VAE while the default release is the newer one; no technical report yet and no arena result. Graded C (vendor claim), not recomputed by us.
Boundaries and failure modes, ordered from the ones specific to this channel down to the ones each member domain carries on its own.
One, the easiest thing to misread at channel level: the union ladder is not a ranking. It pulls assets from both member domains into one list under a single ordering rule (featured, then maturity, then newest metric date) purely so a reader can see at a glance what we have reviewed on this line. An Elo of 1516 on video and a 100ms latency on speech are not commensurable, and appearing higher does not mean stronger. For a ranking, enter a member segment, or open /sota/video and /sota/audio and read each ruler separately.
Two, missing evaluation keeps the whole channel conservative. Of the 12 boards we sync, there are text-to-video and image-to-video boards and no speech board, no TTS naturalness board and no ASR WER board; on music there is only third-party academic work such as WildSongBench, narrow in coverage and inconsistent in sampling budget across vendors (the 6.9632 for YuE2 is best-of-8 while the 6.8721 for Suno v5 is not the same budget, so the two numbers cannot be compared directly). Every water-level judgement on the audio side therefore carries vendor-claim; confirmed is reserved for verifiable public facts (GitHub star counts, licence, price, self-reported latency), and we run no blind listening test and recompute no WER.
Three, alignment error in joint audio-video generation accumulates. A lip-sync miss is tolerable at 5 seconds and unmistakable across a 30 second narrative, and no third party publishes a protocol for measuring it, so vendor demos are always hand-picked samples. Read every "video with sound in one pass" claim as vendor-claim.
Four, duration and physics remain the hard wall on the video side. Single-pass generation generally stops at 5 to 10 seconds; anything longer is built by relaying first and last frames or by stitching segments, and style drift and character inconsistency at the seams have to be picked out by hand. Fluids, cloth, multi-person interaction and hand-to-object contact are the frequent failure points, because what the model learns is the texture statistics of looking physical, not conservation laws.
Five, most boundaries on the audio side are not technical. A few seconds of sample is enough to clone a voice, while consent chains, watermarking and abuse detection are all immature; open-weight TTS can be withdrawn over abuse (there is a 2025-09 precedent), so "open and usable today" is not "available long term". We fold compliance status into the confidence judgement. On music, training-data copyright litigation is unresolved, so check the licence before any commercial delivery.
Six, latency and real-time behaviour are barely measured in evaluations. First-packet latency for high-quality TTS typically runs from a few hundred milliseconds to seconds, and genuinely usable real-time conversation needs streaming synthesis plus barge-in, so the most natural model on a board may be unusable in a call. Long-text consistency (paragraph prosody, how numbers and proper nouns are read, ambiguous readings, mixed Chinese and English text) is the most common production failure, while evaluation sets usually read only short sentences.
Seven, cost stacks along two lines, so do not budget one side only. 720p video runs about $0.10 per second, roughly $3 for a 30 second clip, and three to ten re-rolls is normal in commercial delivery; speech is billed per second or per character, where bulk TTS unit prices sit far below video but the cost of a real-time channel lives in concurrency rather than duration; music generation is close to the video magnitude, with a single track taking tens of seconds to a few minutes. A finished narrated piece with a score must be budgeted as video re-rolls plus multiple voice takes plus multiple music takes, not as three unit prices added together.