How the Claude Code Team Does Code Review
With Claude writing about 90 percent of Claude Code, Anthropic runs seven layers of automated review plus risk-tiered approval, doubling merged PRs while reverts fell 40 percent. The most instructive finding is convergence: an agent author and agent reviewer once burned fifty-plus rounds on one PR, and git blame showed 59 percent of the repeatedly flagged code had been there since the first pass.
Claude writes roughly 90 percent of Claude Code's own code. When a team's output is amplified an order of magnitude by agents, "does anyone still read the code?" stops being a rhetorical question and becomes an engineering problem you answer every day. In a post published on October 15, Anthropic gave their current answer: review wasn't removed, but most of the reading moved to machines, human time and attention are treated as the scarcest resource in the system, and a great deal was invested in making mistakes easy to undo.
Results first. From June to September, merged pull requests to the Claude Code codebase more than doubled, while the share that had to be reverted fell by more than 40 percent. Across Anthropic's monorepo, changes landing per day went from about 2,500 in May to more than 30,000 in September. The two numbers only matter together: throughput rose by an order of magnitude without the quality metrics deteriorating.
We didn't remove review. But we did move most of the reading to machines, optimized for human time and attention, and invested heavily in making it fast and easy to undo mistakes.
The post is worth a close read not because it is another round of "AI review is great" marketing, but because it lays out a working process, the metrics behind it, and the gaps that remain — including a genuinely instructive failure case. Here is my full reading of it.
1. Redefining what review is for
The opening move is more important than any tool introduction: redefining the purpose. The authors argue that "did a human read the code?" is an imprecise proxy. The real question is "what could go wrong with this change, and which check — automated or human — is the right one to catch it?"
The consequence is not merely rhetorical. It also changed when review happens. Before, review was a gate at the end of the road: write the code, open a PR, wait for a colleague. Now review runs continuously, more like spellcheck while you write. Most changes have been reviewed and fixed by Claude at least once before a human is asked to look. Routine mistakes are cleared at that layer, saving team attention for higher-level questions.
The post concedes that code review has always done two jobs: finding and fixing issues before they ship, and building shared codebase understanding across the team. The article focuses on the first, with a promise to return to the second later — and the way that promise is kept, via agent-generated explainers, is more radical than expected.
2. The scarce resource: human time and attention
The whole design starts from an economic judgment that is routinely missed: human time covers both sides of review's cost — the time people spend reviewing, and the time they spend fixing what bad code breaks. Cutting the first doesn't help if the time just shows up in the second.
So the goal is that most PRs in the Claude Code repos — the CLI, the desktop and web apps, and the mobile apps — merge with at most one human in the loop, who can be the author, with no increase in reverts or incidents.
On measurement, they track human approvals per PR (median and 95th percentile), human comments, and how long a PR waits on a person. Revert and incident rates are the guardrail: if those rise, human time wasn't saved, it was only moved. That guardrail design matters more than any single efficiency number, because it stops the optimization from degenerating into a numbers game.
3. The life of a change: seven layers, not one gate
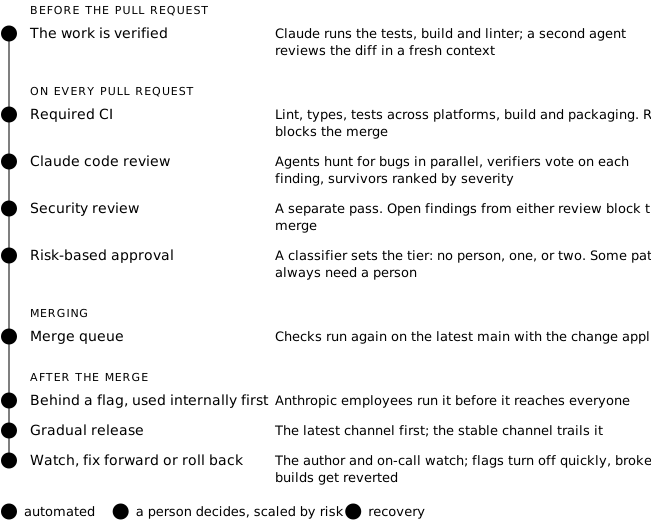
The original walks the full path in a vertical flow diagram. Flattened into a table, the division of labor and the failure mode of each layer get clearer:
| Layer | Where | Who runs it | What it catches |
|---|---|---|---|
| 1. Work verified first | Before the PR exists | Claude plus a fresh-context subagent | "Claimed done but never ran it," the most common failure |
| 2. Required CI | Every PR | Lint, types, tests on every platform, build and packaging | Broken builds, red tests, cross-platform regressions |
| 3. Claude code review | Every PR | Several agents hunt bugs in parallel, verifiers vote on findings | Logic errors, poor fit with the system, unmet intent |
| 4. Security review | Every PR | A separate automated pass | Vulnerabilities, unsafe data handling |
| 5. Human approval | Scaled by risk | Zero, one, or two people | The questions machines are bad at |
| 6. Merge queue and flags | At merge | The queue re-runs every check on latest main with the change applied | Two PRs that pass separately combining into a broken main |
| 7. Fast detection, fast rollback | After the merge | Flags, on-call, dashboards | Whatever slipped through the first six layers |
Layer 6 exists for a specific reason: the merge queue re-runs every check under the condition "latest main plus this change." Two PRs that each pass alone can still break main together — the classic hole in pipeline-style review. New behavior also usually ships behind a flag to Anthropic employees first, and their own heavy use tends to surface regressions before users do.
4. Three layers worth copying
Layer 1: most review happens before the PR exists
This is the most counterintuitive layer: most review now happens while no PR exists. The practice is to give Claude something it can run — tests, a build, or a screenshot to compare against the design — and ask it to show the output instead of saying it's done. Then a subagent reviews the diff with fresh context.
Boris Cherny, who created Claude Code, has called giving Claude a way to verify its work probably the most important thing for getting good results; he estimates it makes the final result two to three times better. He also wrote a line worth taping to the wall: verification looks different for each domain — it might be as simple as running a bash command, or running a test suite, or testing the app in a browser or phone simulator.
This layer has an easily missed mechanism: when the automated reviewer keeps flagging the same thing, they fix it at the source — in the skill, with a lint rule, or with updates to instructional files. Two files matter:
- CLAUDE.md tells Claude what the project is: the stack, the conventions, the goals and the non-goals. Every review loads it, so in a large codebase they keep it short and point to other docs from there. The reviewer also flags code that breaks a convention in it, and changes that make a line in it out of date.
- REVIEW.md, written by code owners, tells the reviewer what matters in their part of the code. The good ones are short: they say what failure looks like in that repo (for docs it's "it lies," for config it's "it misroutes"), cap the nits, list paths to skip, ask for a file and line as evidence instead of a guess from a name, and ask for a summary that starts with a count and says plainly when there's nothing to fix.
In other words, they treat the reviewer's behavior itself as an engineered asset to be maintained, not something to be re-prompted from scratch each time.
Layer 2: parallel bug hunting plus verifier voting
Every PR gets a Claude review before a person looks at it. It reads the diff against the whole repo and the PR's stated intent, and asks: does the change solve its problem, fit the system, or break something else? On a bug fix it looks for the root cause.
The genuinely designed part is the verification mechanism: several agents look for bugs at the same time, then a separate group votes on each finding, and it only gets posted if enough of them agree it's real. Findings that are only about style, diagnostics, or cleanup get dropped. Those filters were A/B tested on their own PRs before being kept. Survivors appear as inline comments sorted by severity, each tagged Important, Nit, or Pre-existing — that last tag matters, because it keeps a bug the PR didn't introduce from looking like the author's fault.
Two numbers indicate how tuned this is: when the research preview launched, the share of internal PRs getting substantive review comments went from 16% to 54%; most PRs over 1,000 lines get findings, and most small ones come back clean. Admins set each repo to Quick, Standard, or Deep, with Deep worth it where one missed bug costs more than the extra review time.
Layer 5: risk tiers, not author tiers
Human approval is the one place a person still decides, and they turned even that into a computed gate: a classifier reads the change and picks its risk tier, and a second classifier asks whether this particular change needs another person even when its tier says it doesn't. The change sets the tier, not the author.
| Risk | Examples | Human approvals |
|---|---|---|
| Low | Docs, copy, internal-only features, additive changes behind a flag | None required once automated review and security checks are green |
| Medium | Ordinary product changes, and changes to sensitive areas such as caching, the auto-updater, or system prompts | One person |
| High | The highest-risk code, plus a small set of paths that always need two people | Two people |
Four supplementary rules are worth recording one by one: only trusted authors get the lighter paths, mostly the team that owns the repo, while everyone else needs a second person; an agent's approval never counts as a person's — automated review can clear a low-risk change but cannot fill a slot that calls for a human; on an agent-written PR, the person directing the agent counts as one of the required reviewers, the same as if they'd typed the code themselves; and an approval covers one specific commit — if new commits land that the system can't vouch for, such as an agent's push or a merge someone resolved by hand, the approval must be given again.
5. Making the reviewer better: incidents are the eval
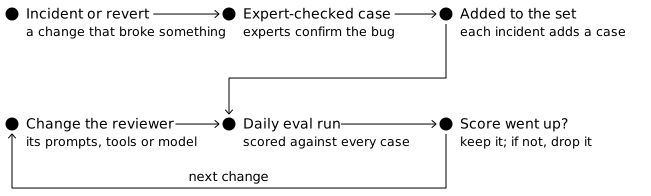
If the previous sections are the process, this one is about how the process itself gets iterated — and it is the most transferable part of the post.
The team collected past PRs that caused incidents, with their fix-forwards and reverts, and had engineers who know that code confirm each bug and where it lived. The reviewer runs against that set daily. So every incident grows the eval by one case, and any change to the reviewer — its prompts, tools, or model — is scored against the entire history: keep it if the score went up, drop it if not.
This turns "is the reviewer any good?" from a feeling into a regressible engineering metric. It is the same idea as an eval set in machine learning, applied to the review policy itself.
How noise is measured: watch what people do with the comments
Recall alone is not enough — catching more bugs is easy if you don't mind flagging a lot of non-bugs. So the countermeasure is sorting every comment by how the person on the PR responded: they fixed it, said it was wrong, said the behavior was intentional, or decided it didn't matter. They also run the reviewer on PRs they know are clean and count how often it reports something that would have led someone to make a harmful change.
The written-down priority is: catching real bugs first and cutting review rounds second. That ordering is worth noting — it means they accept trading some efficiency for recall, but not the reverse.
And noise costs more when the author is an agent: a person can wave off a nit in seconds, while an agent fixes it, which means another commit and another round of review. That sentence is the key to the convergence problem below.
6. Convergence: the most important finding in the post
This is the section I would single out after reading the whole thing, because it records a real failure — and one that only appears when agents are both author and reviewer.
An agent author and an agent reviewer can keep each other busy indefinitely. One CLI PR went through more than fifty rounds of review and fixes overnight before its author stopped it. When they ran git blame on what the reviewer kept flagging, about 59% of it was code that had been there since the reviewer's first pass. The reviewer was rarely finding new bugs; it was finding a few more old ones each round.
The next sentence is the honest one: they made it worse themselves. The team had gotten used to running several rounds by default, since each pass catches something new. That can be worthwhile on a risky change, but not on every PR.
Their fix is four rules, each aimed at one of the diagnosed causes:
- A round cap. After three rounds, the reviewer asks the author to step back and reconsider the approach rather than keep circling details.
- Diff-only re-review after the first few passes — the new code, not the whole file.
- Flag the class of bug, so the author fixes every instance instead of burning one round per line.
- No repeats of findings already posted.
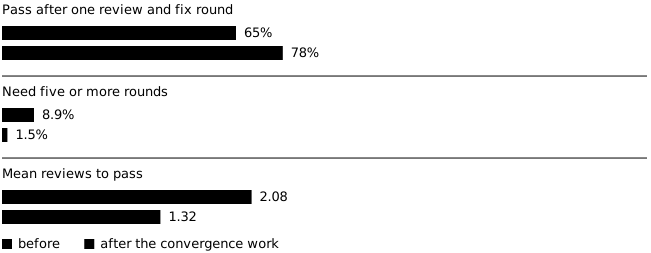
| Metric | Before | After |
|---|---|---|
| Pass after one review and fix round | 65% | 78% |
| Need five or more rounds | 8.9% | 1.5% |
| Mean reviews to pass | 2.08 | 1.32 |
Dropping "five or more rounds" to one and a half percent shows how badly wrong the intuition "a few more rounds can't hurt" was. They also run review agents nightly over existing code, catching old bugs before they show up somewhere else.
7. Where humans stay: five kinds of decisions
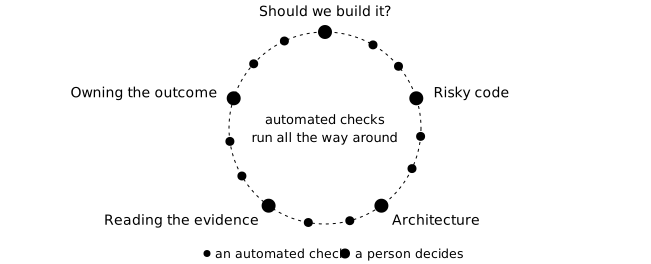
Pulling a senior engineer out of deep work to catch a routine mistake costs far more than an automated review. Anthropic's jobs have moved from reading every diff to the decisions machines are bad at:
- Should we build this at all? Direction, taste and scope. One team that declared its review bottleneck solved still kept human review for changes from outside the team, so someone asks "should we even do this?"
- Risky code such as billing, the auto-updater and CI workflows.
- Architecture that sets a pattern others will copy.
- Reading the evidence. Test output, the command that ran and what it returned, a screenshot, the reviewer's findings. The post offers a good self-check: if you can't say what the checks would miss, ask for a real review rather than a quick approval.
- Owning the outcome. A person is accountable for every change that ships, whoever typed it.
8. The job they gave up: passing on code context
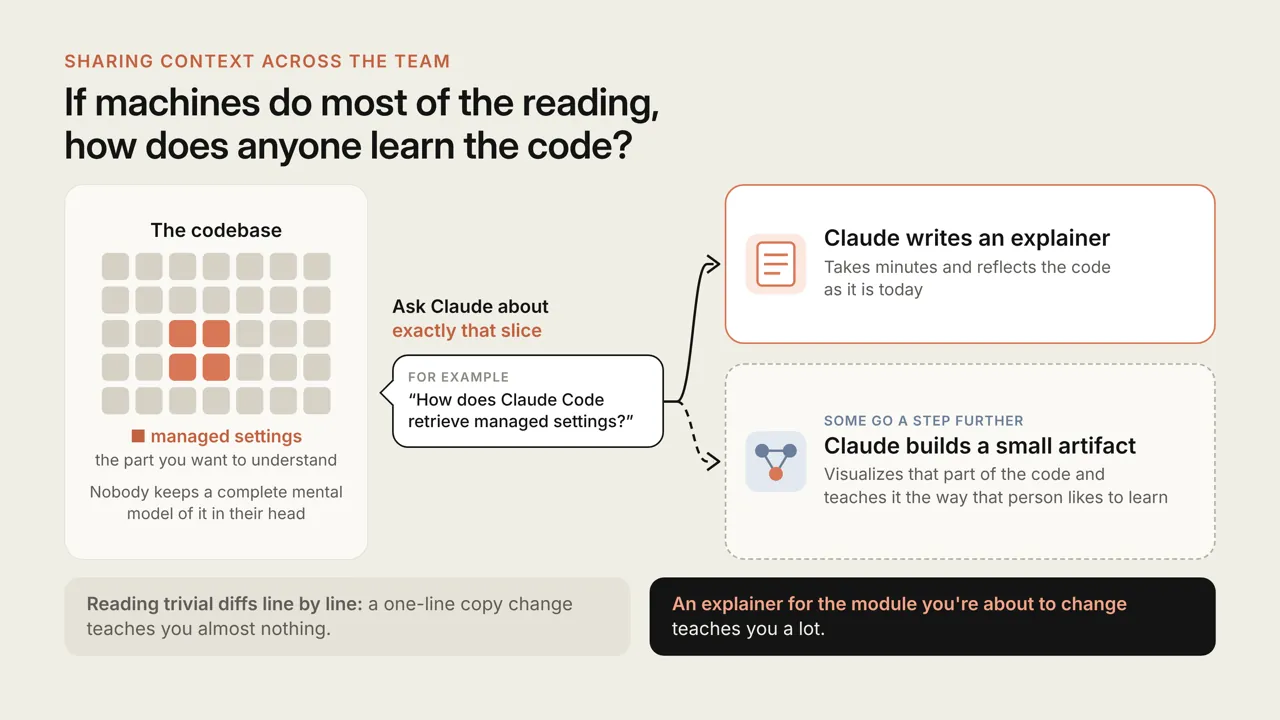
The article promised to return to review's second duty — spreading codebase understanding across the team. Their answer is the most radical passage in the post: there is no formal process. Nobody on the team keeps a complete mental model of Claude Code in their head, and they don't think anyone needs to.
When someone wants to understand a part of the codebase, they ask Claude to write an explainer for exactly that slice. It takes minutes and reflects the code as it is today. Some go a step further and have Claude build a small artifact that visualizes that part of the code and teaches it the way that person likes to learn. Their argument is blunt: if the goal is to spend human attention well, this beats reading trivial diffs line by line. A one-line copy change teaches you almost nothing; an explainer for the module you're about to change teaches you a lot.
A culture of defaulting to open Slack channels helps too, since you see what others are building while they build it.
9. "You land it, you own it," and changing direction
If you land a small or medium change and something still goes wrong, the team norm is that you usually fix it. Four things keep that from going badly: changes are small, so they're easy to review, debug and revert; everything is reversible, with flags, reverts and staged releases undoing most mistakes in minutes; blast radius sets the bar, so expensive code gets more people and more checks; and regressions surface fast through telemetry and internal use. The post stresses that it isn't blame — owning a fix means you have the most context, while incident reviews look at the system.
Agents make it cheap to start things, so some work shouldn't land. Usually someone in the channel asks why, points at an earlier decision, or suggests a simpler route, and the author closes or reshapes the PR. Since the code was fast to write, closing the PR doesn't feel like a loss. The trick is to raise a different direction in the thread early, not as a blocking comment on a finished PR.
10. How to adopt it: a checklist
The original gives a fairly specific adoption path, most of which is actionable today:
- Before the pull request: give your agent checks it can run, listed in a short CLAUDE.md, plus hooks that run formatters and linters; run /code-review and /security-review locally, or a fresh-context subagent review; add a REVIEW.md and move repeated review comments into it.
- On every pull request: require CI, and add "Testing", "Risk" and "How to revert" to your PR template; add an AI reviewer on one repo, tune REVIEW.md for a few weeks, then widen; add automated security review and require every review thread resolved before merge; match review effort to risk; cap review rounds and re-review only the new diff after the first few.
- Approval: write down risk tiers, set from the change rather than the author, and start strict and loosen with evidence; keep the lighter approval paths for authors you trust; use CODEOWNERS and branch protection so auth, billing, CI and release workflows, and installers always need a person; never let a bot's approval replace a required human's, and dismiss approvals on new commits.
- Merge and after: use a merge queue, feature flags, internal use first, staged releases and one-step rollback; turn incidents and reverts into an eval set and rescore the reviewer whenever its prompts, tools or model change; measure human time, with revert and incident rates as the guardrail.
11. Where this is going — and a few criticisms
The product leaves one door ajar: Code Review's announcement says approving a pull request is still a human call, and the product posts findings, not approvals. But their own repos go further, letting owners decide which low-risk changes merge on automated checks alone — and that line keeps moving. When a review misses something, they ask what the model didn't have in front of it and put the fix into a CLAUDE.md, a skill or a new check.
Now the criticisms, because this is a first-party blog from the vendor of the tool being reviewed:
- Every number is self-reported. PRs doubling, reverts down 40%, 16% to 54%, 65% to 78%, 2.08 to 1.32 rounds — all from Anthropic's own repos and dashboards, with no third-party reproduction and no external audit. That is normal for a vendor blog, but the provenance should travel with any citation.
- The strongest numbers have non-reproducible ingredients. They own the model, the product, the reviewer and the monorepo at once; "trusted authors get the lighter paths" and "the person directing the agent counts as a reviewer" both lean on a small, deeply trusting team. Moved to an ordinary company, some of the most effective rules here may be the first to fail.
- The gap is admitted but not yet closed. They don't yet have circuit breakers that tighten approval when revert and incident numbers move; engineers want them before more code moves to zero-human merges. In other words, the system still leans on a human on-call watching dashboards rather than degrading automatically.
- The convergence fix is a process patch, not a cure. A round cap, diff-only re-review and no-repeat findings all constrain a loop that can still spin. The 59% figure shows the reviewer keeps circling existing code, so there is obvious engineering room for the reviewer to deduplicate and prioritize against its own finding history.
Those reservations aside, this is the most substantive material I have read this year on software engineering in the age of agents. It doesn't sell AI review as a silver bullet. It offers a measurable middle path instead: give machines what they can read, keep for humans what they read poorly, and always use revert and incident rates to prove you actually saved time. That last sentence may be the single most worth copying from the whole piece.
Source:Anthropic (claude.dev Blog)https://claude.dev/blog/solving-code-review-at-anthropic/