Skip to content
← Tags

#Sim-to-Real (117)

Real2Sem2Real: 3D Semantic Augmentations for Robot Learning from a Single Human RGB Demonstration

Real2Sem2Real: 3D Semantic Augmentations for Robot Learning from a Single Human RGB Demonstration

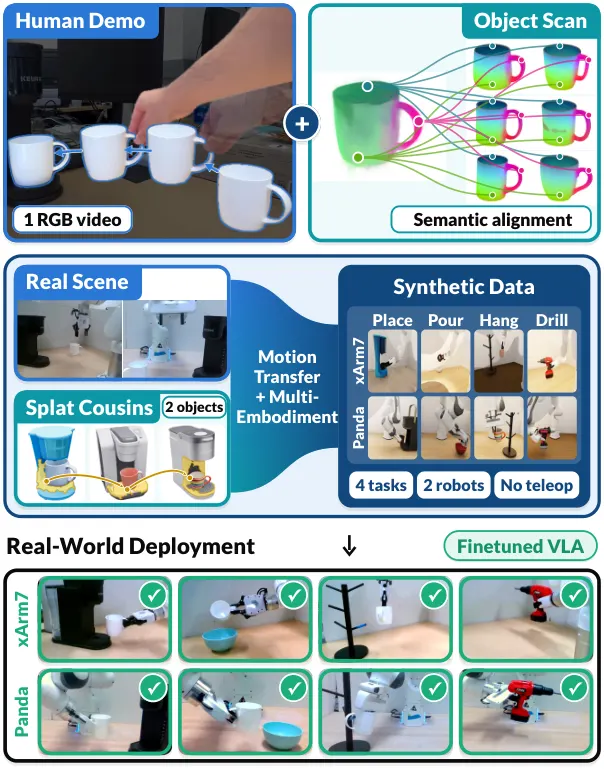
Human video scales easily and does not need robot hardware, but existing methods require depth sensing, overlay the robot onto 2D video, or generate data only for the demonstrated objects. We present Real2Sem2Real (R2Sem2R), a real-to-semantic-to-real pipeline that turns one monocular RGB video of a human demonstration into thousands of robot demonstrations across the semantic object instances of a category. R2Sem2R tracks the SE(3) pose of each object with DINOv3-distilled Gaussian splats, outperforming existing methods and FoundationPose with estimated metric depth. R2Sem2R then aligns digital cousins, each generated from one or a few photographs, to the demonstrated objects with a semantic alignment. This alignment matches whole objects and the functional regions of target objects, such as a coffee machine's tray. R2Sem2R maps the human hand to a feasible robot grasp that extends to the cousins. Robot demonstrations are generated either in IsaacSim, for photorealistic rendering, or MuJoCo, for contact physics, and R2Sem2R can generate over 2,000 episodes in about two hours. On two real robots and four tasks, we train a vision-language-action policy on data from one human video per task, and policies trained on our data match or exceed policies trained on teleoperation across diverse object instances. The project page is available at https://real2sem2real.github.io/.
Matthew Strong, Ankush K. Dhawan, Julien Poffet · 46 views · Oct 20, 2026
Robot LearningHuman demonstrations
Oct 20, 2026
Learning Multi-Phase Robot Loco-Manipulation via Phase-Conditioned Policy Optimization

Learning Multi-Phase Robot Loco-Manipulation via Phase-Conditioned Policy Optimization

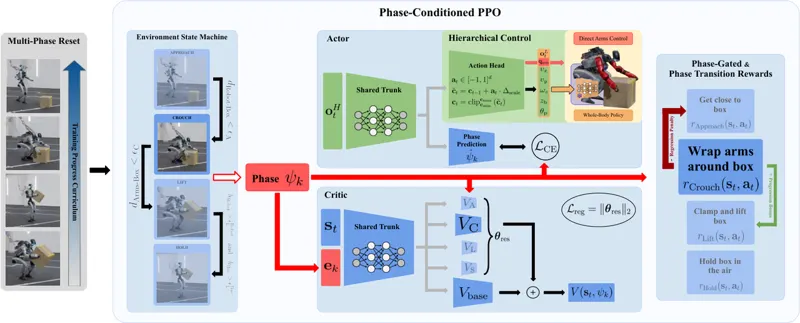
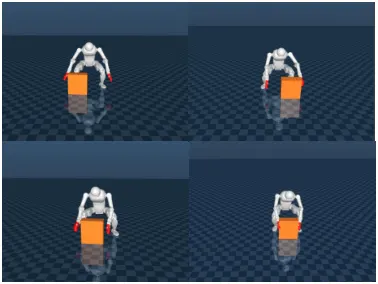
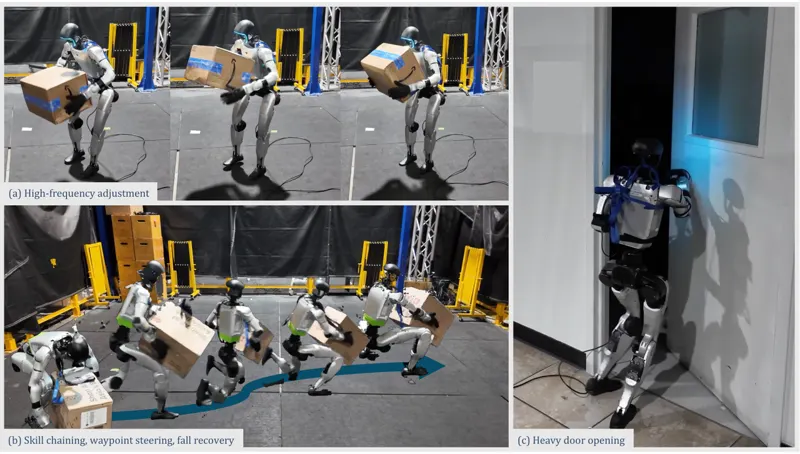
Complex whole-body loco-manipulation requires executing diverse maneuvers, such as crouching, grasping, and locomotion, within a single long-horizon task. While performing simple pick-and-place behaviors is well-established, scaling to complex, long-horizon tasks remains difficult. Currently, this challenge is addressed by relying on human motion data and correspondingly humanoid platforms, which limits platform independence and introduces substantial data processing overhead. Instead, we extend proximal policy optimization (PPO) to train a single policy for multi-phase tasks across diverse robotic hardware, leveraging prior task structure to shape behavior. Our method adapts PPO using a phase-conditioned critic, phase-gated reward functions, and a multi-phase reset curriculum to guide exploration. To support varied hardware, we employ a decoupled hierarchical control architecture that separates lower-level balancing dynamics from high-level phase execution. We demonstrate multi-stage loco-manipulation skills on hardware on both the Unitree G1 and a Boston Dynamics Spot equipped with a manipulator arm, and validate our design choices through ablations. Our approach enables the acquisition of complex loco-manipulation behaviors purely through environment interaction while directly incorporating high-level task structure into policy learning.

Simone Manni, Annika Wollschläger, Dario Bellicoso · 250 views · Oct 26, 2026
Whole-Body Loco-ManipulationPhase-Conditioned PPO
Oct 26, 2026
Compliant GMT: Making General Motion Tracking Compliant via Residual Reference Adaptation

Compliant GMT: Making General Motion Tracking Compliant via Residual Reference Adaptation

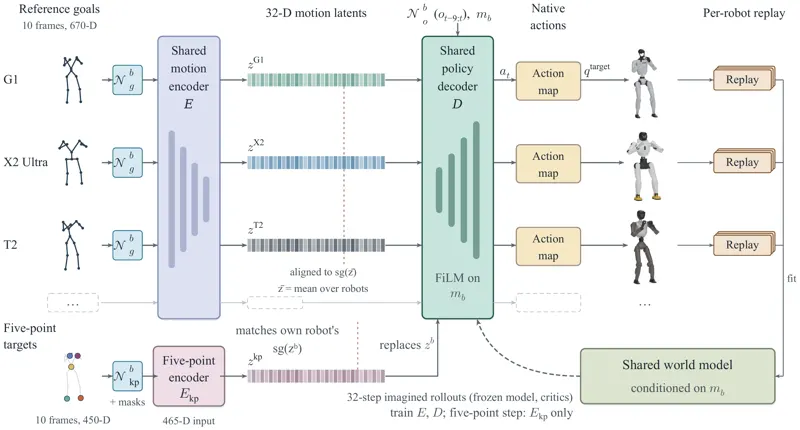
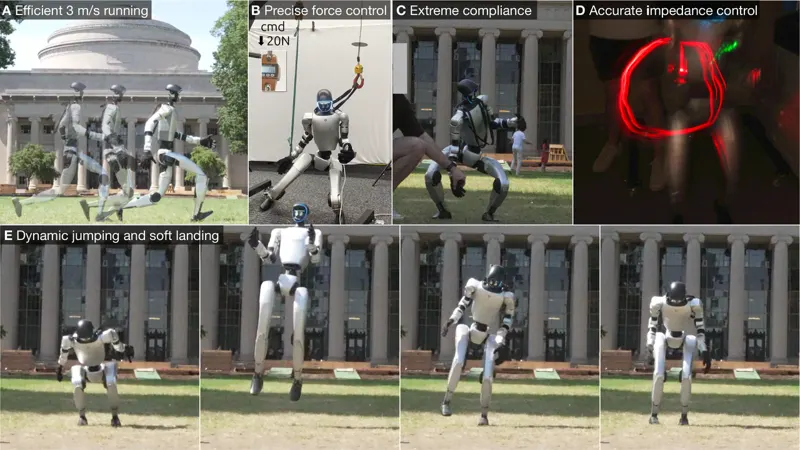
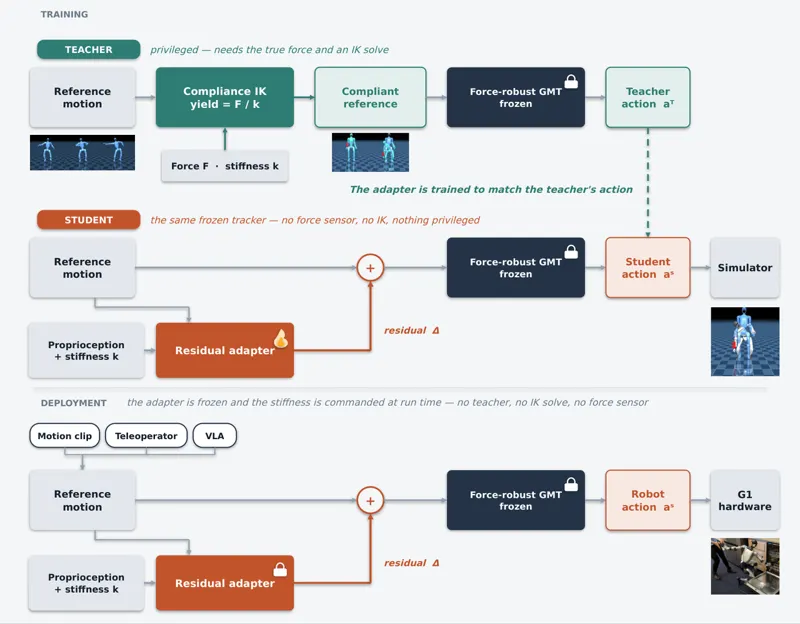
We propose Compliant GMT (C-GMT), a modular framework for full-body compliant responses in general motion tracking. As humanoid robots move into real world deployment, they not only need to perform any motion but also respond safely and robustly to interaction forces. Existing general motion tracking policies can imitate diverse motions but are trained to be stiff, leading to unexpected and unsafe behaviors under disturbance. Prior work in compliant humanoid control trades off compliance and generality. There exist examples of full-body compliant responses, but these are heavily curated to single-reference policies. On the other hand, general motion trackers (GMT) are trained to rigidly imitate massive motion capture datasets. Our key insight is to leverage the generality of pretrained GMTs for motion tracking while introducing compliance from a residual adapter that conditions on a history of proprioception. This enables our approach, C-GMT, to achieve both general motion tracking and whole-body compliant responses. Compared to state-of-the-art general motion trackers and single-motion compliant policies, C-GMT demonstrates competitive performance in both motion tracking accuracy and compliance adherence. We further demonstrate improved safety, robustness, and error tolerance in simulation and real-world G1 experiments.

Venki Parsuram, Michelle Wang, Jin-Hyuk Hong · 259 views · Oct 15, 2026
HumanoidMotion Tracking
Oct 15, 2026
Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

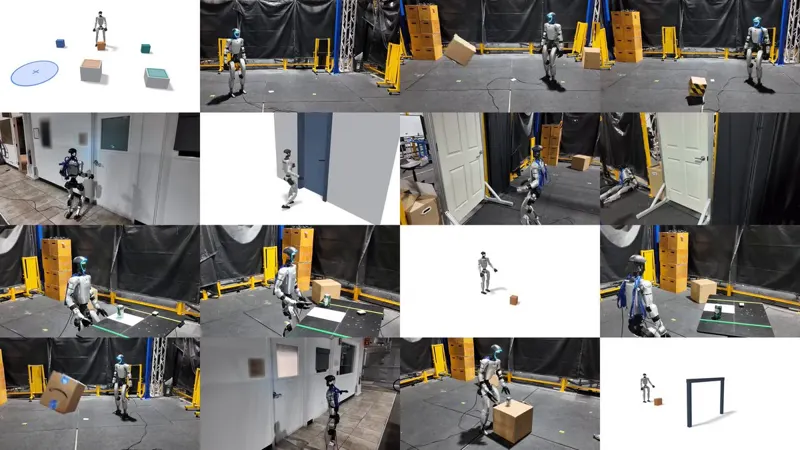
FIBER addresses a representation problem at the heart of versatile humanoid loco-manipulation: high-level planners need a compact abstraction, but kinematic or contact targets do not encode the state-dependent control responses that make contact-rich interaction succeed, while predicting low-level actions forces an offline planner to model high-frequency closed-loop feedback. FIBER resolves this by using the executable latent space of a frozen behavioral foundation model (BFM) as the shared planning representation. Its latent policy projection (LPP) maps each independently acquired task expert into that space by identifying latent commands whose BFM-induced actions match the expert's local control responses in physical joint-target space, regularized by a semantic term that anchors each command to the BFM backward representation of the same state. Because projection only requires the expert's actions, experts may differ in observations, objectives, and training pipelines, and are discarded once projected. Closed-loop latent rollouts from all projected skills are then aggregated to train a single perceptive flow-matching planner entirely offline, conditioned on egocentric depth, proprioception, and steering tokens derived from language or waypoints; at deployment it replans in a receding-horizon loop while the frozen BFM supplies 50 Hz state feedback. The paper further contributes AH-BFM, an adaptive-horizon BFM trained with multi-gamma forward-backward learning that keeps both short-horizon tracking fidelity and long-horizon behavioral coherence in one latent space, and successor-feature-guided behavior reuse, which composes an acquired interaction such as box carrying with native whole-body behaviors like crouching or running. In IsaacSim, across 128 variations per task, FIBER reaches 42.0% mean success versus 11.6% for projected latent replay and 3.5% for kinematic planning; on a real Unitree G1 it transfers zero-shot with 6/10 box pickup, 4/10 door opening, and 2/10 object grasping, running a 5 Hz TensorRT planner and the 50 Hz BFM on a single laptop GPU.

Yutang Lin, Guanya Shi, C. Karen Liu · 269 views · Oct 17, 2026
HumanoidMobile Manipulation
Oct 17, 2026
Perceptive Humanoid Parkour: Chaining Dynamic Human Skills via Motion Matching

Perceptive Humanoid Parkour: Chaining Dynamic Human Skills via Motion Matching

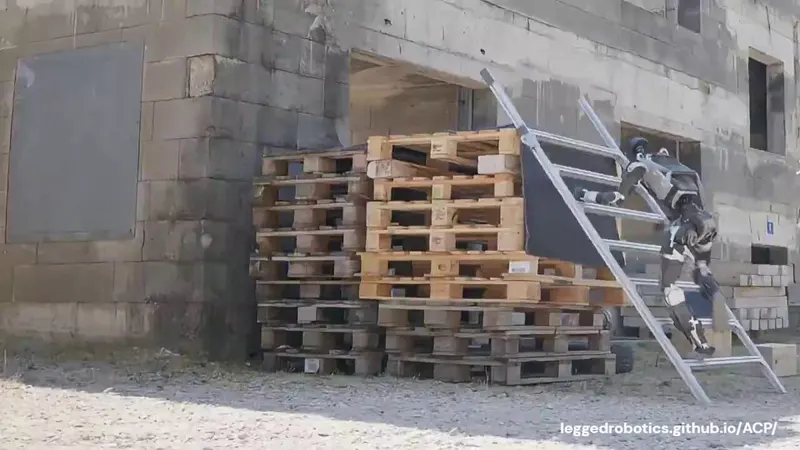
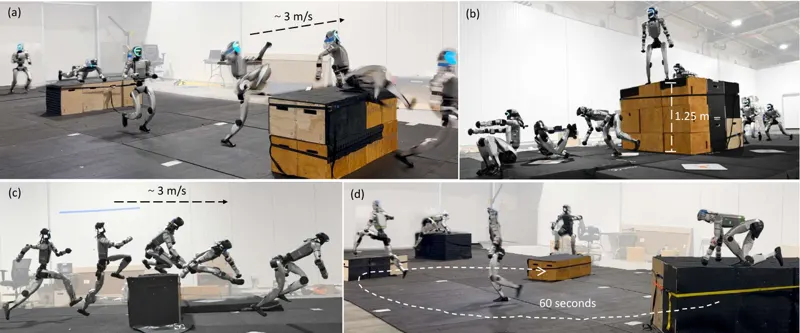
While recent advances in humanoid locomotion have achieved stable walking on varied terrains, capturing the agility and adaptivity of highly dynamic human motions remains an open challenge. In particular, agile parkour in complex environments demands not only low-level robustness, but also human-like motion expressiveness, long-horizon skill composition, and perception-driven decision-making. In this paper, we present Perceptive Humanoid Parkour (PHP), a modular framework that enables humanoid robots to autonomously perform long-horizon, vision-based parkour across challenging obstacle courses. Our approach first leverages motion matching, formulated as nearest-neighbor search in a feature space, to compose retargeted atomic human skills into long-horizon kinematic trajectories. This framework enables the flexible composition and smooth transition of complex skill chains while preserving the elegance and fluidity of dynamic human motions. Next, we train motion-tracking reinforcement learning (RL) expert policies for these composed motions, and distill them into a single depth-based, multi-skill student policy, using a combination of DAgger and RL. Crucially, the combination of perception and skill composition enables autonomous, context-aware decision-making: using only onboard depth sensing and a discrete 2D velocity command, the robot selects and executes whether to step over, climb onto, vault or roll off obstacles of varying geometries and heights. We validate our framework with extensive real-world experiments on a Unitree G1 humanoid robot, demonstrating highly dynamic parkour skills such as climbing tall obstacles up to 1.25m (96% robot height), as well as long-horizon multi-obstacle traversal with closed-loop adaptation to real-time obstacle perturbations.

Zhen Wu, Xiaoyu Huang, Lujie Yang · 227 views · Feb 17, 2026
HumanoidParkour
Feb 17, 2026
Blind Precise Assembly: Proprioceptive Sim-to-Real Peg-in-Hole for Diverse Parts

Blind Precise Assembly: Proprioceptive Sim-to-Real Peg-in-Hole for Diverse Parts

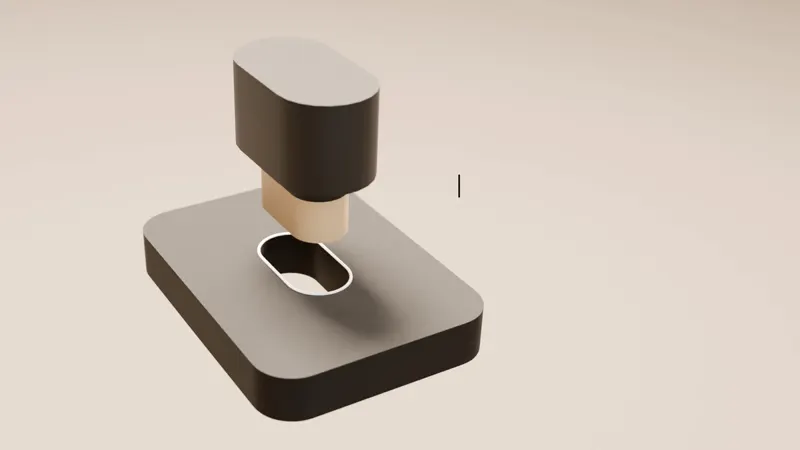
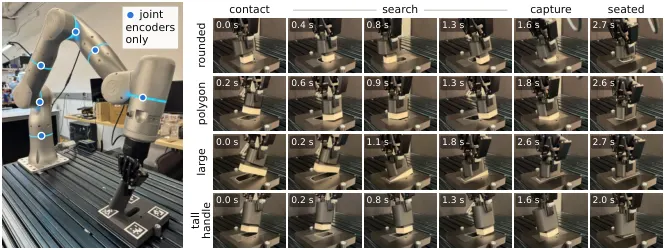
Every robot already carries high-resolution contact sensors: its own joints. Legged robots and humanoids exploit them to walk, run, and track whole-body motions without vision, but there the contacts are large and forceful. Is joint sensing also enough for precise, contact-rich assembly, where the robot must find a millimeter-scale opening, mesh gear teeth, or catch a thread through light contact? We study this question by training blind assembly policies that observe only a short history of joint positions, velocities, and their own actions, without visual, force, torque, or tactile sensing. The poses of both the fixture and the part are unknown to the policy, and the grasp is randomized substantially. The policy must therefore assemble the parts through contact, sensed exclusively through its own proprioception. Trained with reinforcement learning entirely in simulation over randomized parts, grasps, and contacts, such policies learn peg insertion, gear meshing, and nut threading. The peg insertion policy transfers zero-shot to the real world and inserts pegs of different shapes and sizes in 73% of trials. Controlled comparisons with matched visual policies in simulation show that blind policies generalize far better to unseen part shapes and sizes, though they can be slower. Training such policies needs thousands of different assemblies, each simulated with its clearance intact, so we also release an open-source generator that builds them procedurally from exact convex pieces for MuJoCo; it is more accurate and faster than convex decomposition or MuJoCo's signed-distance collision. Videos and interactive simulations are at https://younghyopark.me/blind-proprioceptive-assembly/.

Antonia Bronars, Younghyo Park, Kushal Kedia · 346 views · Oct 16, 2026
Peg-in-HoleSim-to-Real
Oct 16, 2026

As an Amazon Associate, we earn from qualifying purchases.