HarnessVLN: Unifying Training-Free Embodied Navigation through an Agent Harness
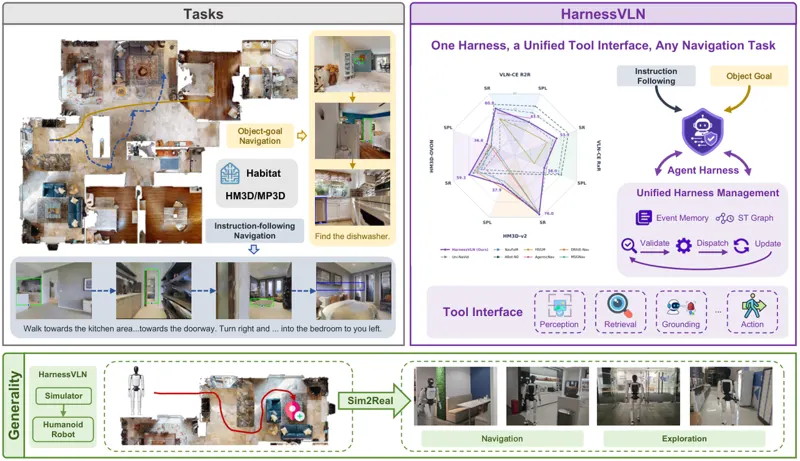
Embodied navigation requires an agent to ground instructions or object goals in spatial observations and turn plans into execution. HarnessVLN is a zero-shot, training-free agent harness that coordinates perception, hierarchical event memory, a persistent spatiotemporal graph, and navigation tools through a shared interface. Before dispatch, the harness checks evidential support, geometric feasibility, and subgoal consistency; structured execution feedback then updates task progress, spatial evidence, and failure records for subsequent planning, recovery, and stopping. HarnessVLN reaches success rates of 60.8% on R2R, 53.9% on RxR, 76.0% on HM3D-v2, and 59.3% on HM3D-OVON, outperforming the training-free methods compared in the paper. Three real-world scenarios on an AgiBot A3U humanoid demonstrate deployment feasibility across both navigation families. Project page: https://agibot-harnessvln.netlify.app/.