Skip to content
← Tags

#Mobile Manipulation (74)

Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

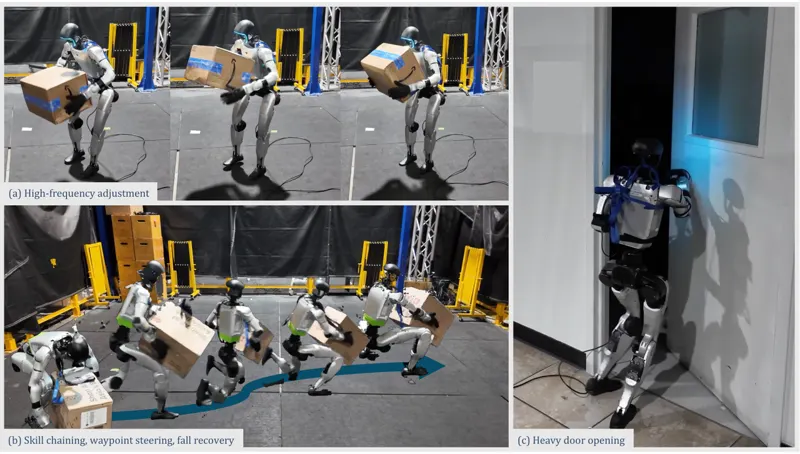
FIBER addresses a representation problem at the heart of versatile humanoid loco-manipulation: high-level planners need a compact abstraction, but kinematic or contact targets do not encode the state-dependent control responses that make contact-rich interaction succeed, while predicting low-level actions forces an offline planner to model high-frequency closed-loop feedback. FIBER resolves this by using the executable latent space of a frozen behavioral foundation model (BFM) as the shared planning representation. Its latent policy projection (LPP) maps each independently acquired task expert into that space by identifying latent commands whose BFM-induced actions match the expert's local control responses in physical joint-target space, regularized by a semantic term that anchors each command to the BFM backward representation of the same state. Because projection only requires the expert's actions, experts may differ in observations, objectives, and training pipelines, and are discarded once projected. Closed-loop latent rollouts from all projected skills are then aggregated to train a single perceptive flow-matching planner entirely offline, conditioned on egocentric depth, proprioception, and steering tokens derived from language or waypoints; at deployment it replans in a receding-horizon loop while the frozen BFM supplies 50 Hz state feedback. The paper further contributes AH-BFM, an adaptive-horizon BFM trained with multi-gamma forward-backward learning that keeps both short-horizon tracking fidelity and long-horizon behavioral coherence in one latent space, and successor-feature-guided behavior reuse, which composes an acquired interaction such as box carrying with native whole-body behaviors like crouching or running. In IsaacSim, across 128 variations per task, FIBER reaches 42.0% mean success versus 11.6% for projected latent replay and 3.5% for kinematic planning; on a real Unitree G1 it transfers zero-shot with 6/10 box pickup, 4/10 door opening, and 2/10 object grasping, running a 5 Hz TensorRT planner and the 50 Hz BFM on a single laptop GPU.

Yutang Lin, Guanya Shi, C. Karen Liu · 269 views · Oct 17, 2026
HumanoidMobile Manipulation
Oct 17, 2026
ASENA: Self-evolving Agents for Embodied Navigation

ASENA: Self-evolving Agents for Embodied Navigation

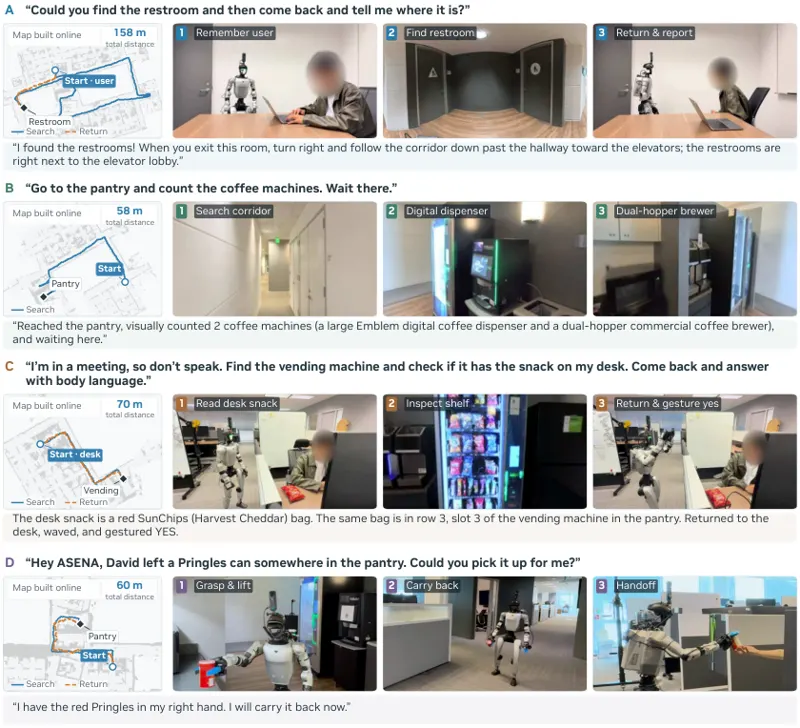
We present ASENA, an embodied agent system that enables general-purpose coding agents to program humanoid navigation, manipulation, and interaction. Through a unified robot harness, agents read sensor data, write and execute programs, inspect recorded outcomes, repair failures, and reuse notes and executable skills while keeping their model weights fixed. We also introduce ASENA-VLN, a 4B monocular navigation policy that serves as an optional tool within this programmable system. ASENA-VLN predicts body-frame trajectories for both extended routes and short-horizon behaviors. Its shared vision-language decoder is trained on route instructions, visual question answering, and a newly curated dataset of geometry-derived atomic navigation tasks. As a standalone policy, ASENA-VLN achieves state-of-the-art success rates of 68.7% on R2R and 70.2% on RxR. When integrated with a coding agent, learned navigation improves ASENA's success rate by 11 percentage points on both agentic benchmarks and reduces execution time. Persistent workspace evolution uses simulator feedback to improve success over ten passes through recurring 100-task subsets. Success increases from 72% to 98% on R2R and from 65% to 89% on RxR. On embodied question answering, ASENA achieves state-of-the-art accuracy with fewer interaction steps. On a Unitree G1, we demonstrate search, visual inspection, spatial reasoning, synthesized gestures, and mobile manipulation combining object pickup, carrying, and handoff without a pre-built map. These demonstrations illustrate how online programming extends robot behavior beyond route following and predefined skills.

An-Chieh Cheng, Isabella Liu, Edmund Bu · 388 views · Sep 30, 2026
Vision-language navigationEmbodied AI
Sep 30, 2026

PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface

PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface

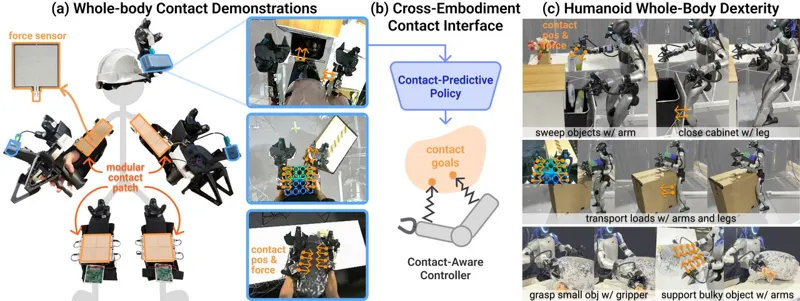
PanTact treats contact, not joint trajectories, as the transfer currency from people to humanoids. Wearable patches are assembled magnetically from 44x44 mm FSR modules; a custom 50x50 mm PCB streams 16 channels at 1 kHz over a CRC-checked RS-485 daisy chain, one Vive tracker per patch maps sensor centers into the world frame, and contact states are binarized against a per-channel adaptive baseline with threshold max(0.35 beta, r_min). The policy observes body-masked 3D egocentric point clouds, both wrist images and proprioception, and at 10 Hz predicts an action chunk of H=16 steps containing a look-at point, EEF poses with gripper widths, and per-sensor contact goals (binary state plus 3D position). A soft-minimum proximity d(p,q) with T = 0.02 m hands each active contact to whichever robot surface is currently nearest, and active goals are offset by delta along the pressing direction to form virtual goals that generate pressing force, so the G1 holds objects without any tactile sensor on its body. Three control formulations trade off differently: training-free upper-body IK, WBIK whose dense reference is executed by SONIC, and a sparse contact tracker trained with PPO over 4096 simulation environments for 30k iterations (50 Hz, 29 joints, S=8 upper-body / S=16 whole-body contact slots). On a 29-DoF Unitree G1: Grasp-and-Embrace reaches 85% with upper-body IK and 80% with the sparse tracker against 0% for Humanoid UMI; Sweep-and-Stow reaches 90.63% end to end while Humanoid UMI++ scores 18.75% on each stage and 0% end to end; Carry-and-Push is 90% versus 40%. In simulation replay, adding contact goals lowers contact distance for all three controllers at almost no cost in EEF accuracy.

Xu, Xiaomeng, Zhang, Han, Ruan, Zhian · 562 views · Oct 8, 2026
Whole-Body ManipulationTactile Sensing
Oct 8, 2026
MobileVISTA: Generative Data Augmentation for Pose Generalization in Mobile Manipulation

MobileVISTA: Generative Data Augmentation for Pose Generalization in Mobile Manipulation

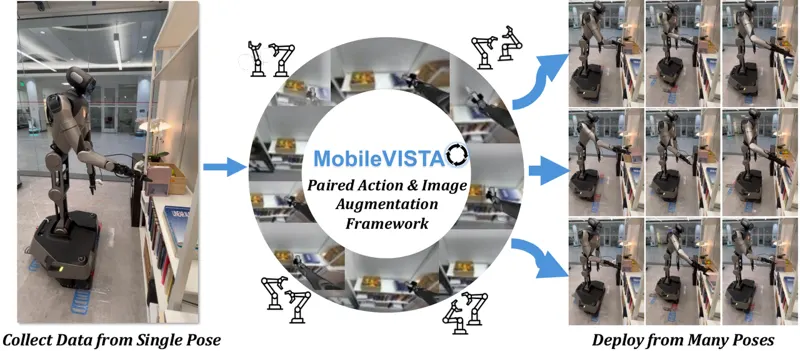
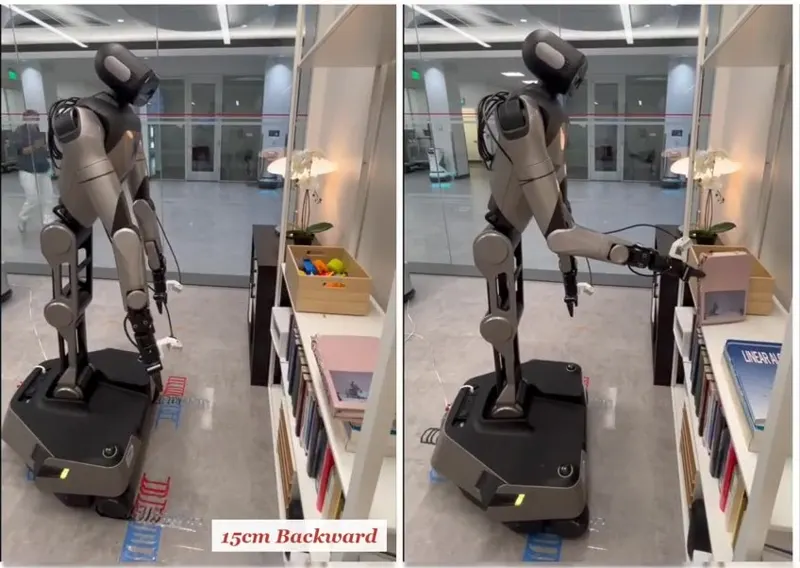
Mobile manipulators such as humanoid robots are increasingly deployed in dynamic, unstructured environments to perform dexterous manipulation tasks. However, end-to-end manipulation policies trained to imitate demonstration data collected from a single robot pose are brittle: even centimeter-scale deviations in robot pose at deployment can drive ego-centric observations and end-effector trajectories out of the training distribution, leading to sharp drops in performance. We introduce MobileVISTA, a data generation framework that transforms demonstrations captured at canonical poses into diverse, pose-perturbed training data by jointly (1) augmenting egocentric visual observations and (2) retargeting actions to compensate for base pose changes. Unlike prior methods, which assume a camera rigidly mounted off the actuated chain or non-trivial articulated robot geometry largely out of frame, MobileVISTA targets compatibility with egocentric platforms (e.g., humanoids) where the camera is both influenced by and must observe the robot's kinematic chain as it moves. We study MobileVISTA in simulated tasks spanning humanoid and bimanual embodiments, and on a real Galaxea R1 Pro. We find policies trained on MobileVISTA-augmented data demonstrate improved robustness to previously out-of-distribution poses encountered at test time, without additional demonstration collection or a trained generative model. Additionally, we find MobileVISTA's benefit is largest on tested humanoids, where the camera rides the actuated chain and the robot fills much of the frame. Additional videos and appendix can be found on our website: https://mobilevista.github.io

Wistreich, Suzannah, Tian, Stephen, Huang, Isabella · 319 views · Oct 5, 2026
Mobile ManipulationData Augmentation
Oct 5, 2026
UniLM-Nav: A Unified Framework for Zero-Shot Last-Mile Navigation

UniLM-Nav: A Unified Framework for Zero-Shot Last-Mile Navigation

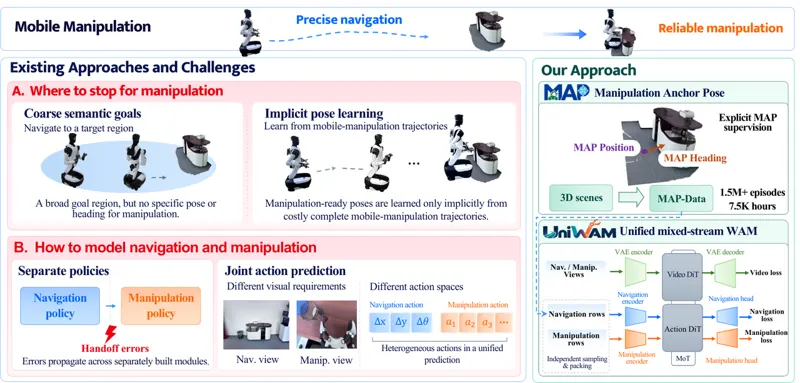
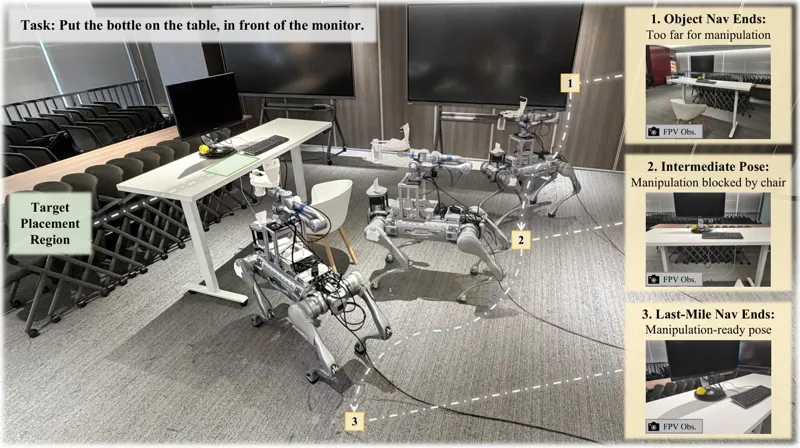
Mobile manipulation requires a robot to navigate to a target object or receptacle and then perform intended manipulation. However, reaching the vicinity of the target does not guarantee a manipulation-ready base pose, a problem known as last-mile navigation. Prior methods for last-mile navigation either rely on manual pose annotation or task-specific training, limiting their scalability to open-vocabulary settings with fine-grained spatial constraints. We propose UniLM-Nav, a unified framework for zero-shot open-vocabulary last-mile navigation. UniLM-Nav decomposes last-mile navigation into view selection, task-conditioned affordance grounding, and geometry-aware base-pose reasoning, all resolved with a shared multimodal large language model (MLLM) backend. Specifically, UniLM-Nav first selects a reference view that best captures the target object or receptacle from recently collected observations. It then grounds task-relevant affordance point in the selected view and lifts the result into the robot-centric coordinate frame. Finally, conditioned on the grounded affordance, task context, and robot geometry, it infers a manipulation-ready base pose for the robot. We evaluate UniLM-Nav on the OVMM benchmark, where it outperforms the previous state-of-the-art method, MoTo, by 3.13 percentage points. Analyses show that the components of our method are crucial to final performance, and that the choice of MLLM also has a substantial effect. We further deploy UniLM-Nav on a Unitree B2 quadruped robot with a 6-DoF Unitree Z1 manipulator, validating its applicability to real-world mobile manipulation tasks.

Zhuofan Zhang, Tianxu Wang, Guoxi Zhang · 383 views · Jul 7, 2026
Mobile ManipulationLast-Mile Navigation
Jul 7, 2026
Robot Planning and Situation Handling with Active Perception (VAP-TAMP)

Robot Planning and Situation Handling with Active Perception (VAP-TAMP)

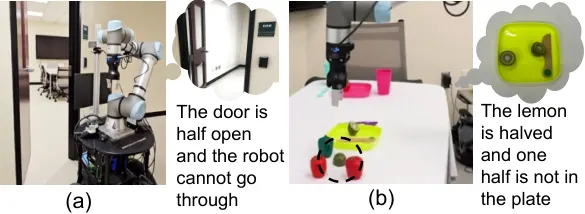
SUNY Binghamton + CMU + Ford Research + Agility Robotics. A TAMP (task and motion planning) framework with VLM-based active perception. Core problem: TAMP assumes a fully observable world, but execution constantly surfaces unforeseen situations — a door only half open, one lemon half fallen out of the plate. Prior open-world planning implicitly assumed situations are fully observable, while real robots rely on unreliable onboard sensors. VAP-TAMP’s key novelty is the bidirectional interaction between VLMs and action knowledge: predicates from the current action’s PDDL preconditions/effects construct VQA prompts for the VLM, and VLM outputs update the action knowledge. Three modules: (1) scene graph generator (RGB-D point cloud + instance segmentation + CLIP embeddings; geometric rules for on/inside/near; updated via both action-driven and observation-driven channels); (2) active perception (N semantically equivalent paraphrases per predicate with majority voting; inconsistent responses → the VLM suggests a viewing direction (left/right/closer/above) → navigate and re-observe, looping within budget K until the view is sufficient); (3) situation handling (verify-execute-verify loop: preconditions checked before, effects after; any failure → correct the scene graph → PDDL replanning; diagnoses whether discrepancies stem from perception error, world state change, or execution failure). Real-world: Segway RMP + UR5e + Robotiq gripper, 4 household tasks × 25 trials (100 total), 88% success (OK-Robot 76%, COWP 69%, Closed-World 33%); 72/100 trials contained at least one unforeseen situation; VLM-guided viewpoint selection averages 1.61 views vs 4.35 for greedy exploration (63% fewer); failure-mode analysis shows VAP-TAMP failures concentrate in manipulation hardware (42%) — the perceptual bottleneck has been shifted away. Simulation (OmniGibson, 5 tasks with injected failure probabilities) shows predicate-based verification beats SuccessVQA/AffordanceVQA and their combination, with effect verification contributing more than precondition verification (grasp/cut carry 50% combined failure rates detectable only post-execution).

Austine Oloo, Zainab Altaweel, Yohei Hayamizu · 627 views · Apr 28, 2026
TAMPActive Perception
Apr 28, 2026

As an Amazon Associate, we earn from qualifying purchases.