Skip to content
← Tags

#Tactile Sensing (61)

PACE: Temporal-Role Tactile Conditioning for Chunk-Based Insertion Policies

PACE: Temporal-Role Tactile Conditioning for Chunk-Based Insertion Policies

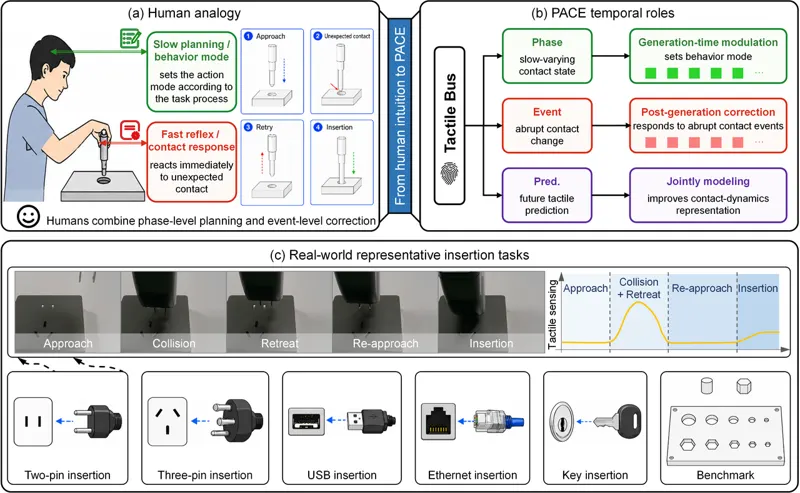
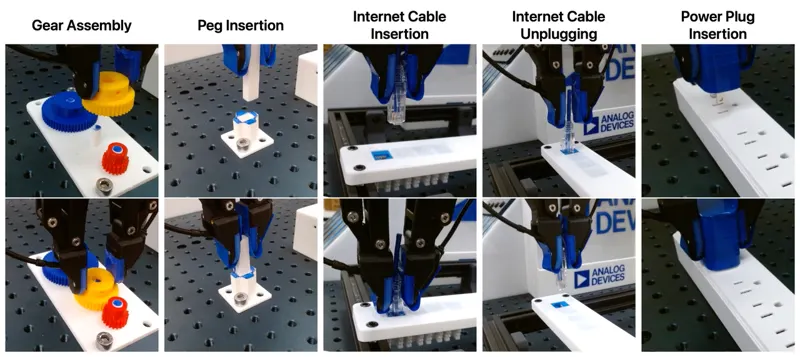
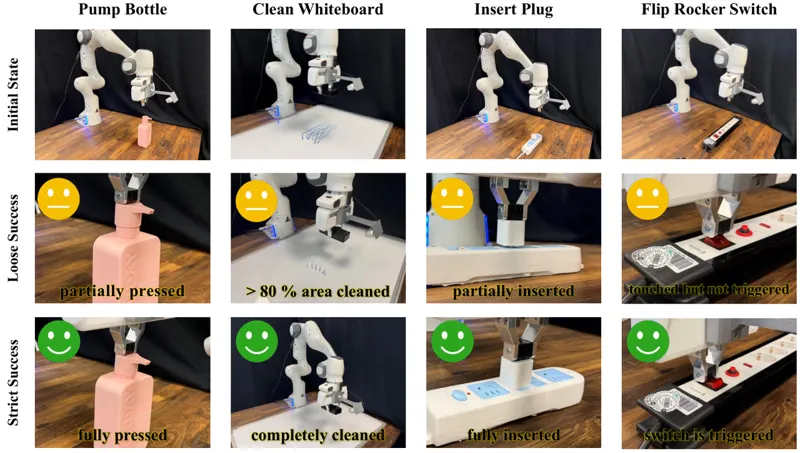
Contact-rich insertion requires a robot to combine visual alignment with tactile adjustment. Existing visuotactile chunk-based policies often collapse tactile feedback into one generation-time pathway, so persistent contact state, abrupt contact events, and the future contact consequences of an action are modeled implicitly in a single representation. PACE assigns one tactile stream three temporal roles. An exponential-smoothed contact state modulates action-chunk generation through layer-wise feature conditioning. A short-window tactile difference forms an event cue and drives a gated residual correction over only the first steps of the chunk. A training-only head predicts future tactile increments from decoder states as an auxiliary representation-learning objective. This preserves chunk-level action continuity while giving slowly varying contact phases and fast collision or jamming events separate pathways. Across five real insertion tasks, PACE reaches 90.7 percent average success, more than 44 percentage points above vision-only and single-path tactile-fusion baselines. It also averages 88.7 percent on six ManipulationNet geometry and clearance settings, including 0.1 mm clearance. Ablations show complementary contributions from Phase, Event, and Pred., while cross-signal and cross-architecture tests extend the principle to force/torque, joint current, and diffusion-policy backbones.

Zhiyuan Chen, Shixiong Xu, Shuai Chen · 243 views · Oct 12, 2026
Tactile SensingRobot Manipulation
Oct 12, 2026
Agile-WAM: An Agile Tactile World Action Model for Contact-Rich Robot Control

Agile-WAM: An Agile Tactile World Action Model for Contact-Rich Robot Control

World Action Models (WAMs) advance beyond conventional visuomotor policies by jointly predicting future world states and robot actions, enabling the policy to learn phys- ical dynamics that support effective control. However, recent tactile WAMs often rely on large-scale pretrained generative backbones to capture contact-rich physical dynamics, which limit their inference efficiency and flexible deployment. In this paper, we present Agile-WAM, an agile tactile World Action Model for contact-rich robot control. Agile-WAM encodes visual and tactile observations into a shared latent that serves as the source of a direct vision-tactile-to-action flow-matching process, which can jointly generate latent representations of action chunks and future visual/tactile latents. A key observation is that vision and tactile signals evolve at inherently different timescales: adjacent visual frames are often highly similar, whereas tactile signals can change abruptly upon contact. We therefore introduce multi-horizon multimodal prediction in Agile-WAM, which provides supervision for visual latent at a larger temporal offset while predicting the tactile latent in the next frame to capture fine-grained contact dynamics. Across nine simulated and five real-world contact-rich ma- nipulation tasks, Agile-WAM demonstrates strong and robust performance, outperforming the strongest baseline in success rate while maintaining low inference latency. In particular, in five real-world experiments, Agile-WAM yields a relative gain of 29.4% in overall success rates while achieving inference latency of 11.9 ms. These results demonstrate that multimodal WAM can be achieved with an agile architecture suitable for precise and high-frequency robot control. More details are available on our project page.

Hanchu Zhou, Brendan Lynch, Raman Goyal · 235 views · Sep 17, 2026
World-action modelsFlow Matching
Sep 17, 2026
VT-Bridge: Bridging Pretrained Foundation VLAs to VTLAs via Lightweight Residual Adaptation

VT-Bridge: Bridging Pretrained Foundation VLAs to VTLAs via Lightweight Residual Adaptation

Vision-Tactile-Language-Action (VTLA) models have demonstrated clear advantages over Vision-Language-Action (VLA) models in contact-rich manipulation. However, developing VTLA models is severely constrained by the massive amounts of vision-tactile data and computational resources required. To address this bottleneck, we propose VT-Bridge, a lightweight residual adaptation strategy that bridges pretrained foundation VLAs to VTLAs. Rather than training a VTLA model from scratch or modifying the original architecture of a pretrained VLA, VT-Bridge employs an identical lightweight residual-adapter architecture across VLA backbones and uses backbone-specific weights to refine actions at the robot execution frequency. This design substantially lowers the data and training barriers. Specifically, it requires up to 50 vision-tactile demonstrations per task to fine-tune a VLA backbone and train a 0.98M-parameter residual adapter. Experiments with three representative VLA backbones (π₀, π_0.5, and SmolVLA) across four contact-rich manipulation tasks further demonstrate its consistent effectiveness across VLA architectures. On average, VT-Bridge raises the task completion rate from 11.7% with task-level VLA fine-tuning alone to 62.9%. Together, these findings demonstrate the broad applicability, effectiveness, and accessibility of VT-Bridge for contact-rich manipulation. The project page is available at https://hoxnocha.github.io/vt-bridge-web/.

Yansong Wu, Tuo Yang, Rongping Zhao · 292 views · Sep 18, 2026
Tactile SensingVLA
Sep 18, 2026
PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface

PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface

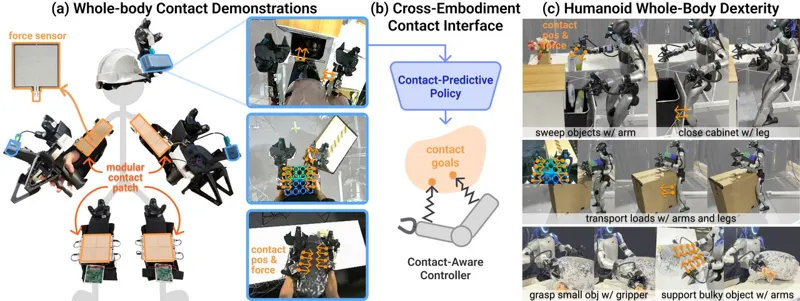
PanTact treats contact, not joint trajectories, as the transfer currency from people to humanoids. Wearable patches are assembled magnetically from 44x44 mm FSR modules; a custom 50x50 mm PCB streams 16 channels at 1 kHz over a CRC-checked RS-485 daisy chain, one Vive tracker per patch maps sensor centers into the world frame, and contact states are binarized against a per-channel adaptive baseline with threshold max(0.35 beta, r_min). The policy observes body-masked 3D egocentric point clouds, both wrist images and proprioception, and at 10 Hz predicts an action chunk of H=16 steps containing a look-at point, EEF poses with gripper widths, and per-sensor contact goals (binary state plus 3D position). A soft-minimum proximity d(p,q) with T = 0.02 m hands each active contact to whichever robot surface is currently nearest, and active goals are offset by delta along the pressing direction to form virtual goals that generate pressing force, so the G1 holds objects without any tactile sensor on its body. Three control formulations trade off differently: training-free upper-body IK, WBIK whose dense reference is executed by SONIC, and a sparse contact tracker trained with PPO over 4096 simulation environments for 30k iterations (50 Hz, 29 joints, S=8 upper-body / S=16 whole-body contact slots). On a 29-DoF Unitree G1: Grasp-and-Embrace reaches 85% with upper-body IK and 80% with the sparse tracker against 0% for Humanoid UMI; Sweep-and-Stow reaches 90.63% end to end while Humanoid UMI++ scores 18.75% on each stage and 0% end to end; Carry-and-Push is 90% versus 40%. In simulation replay, adding contact goals lowers contact distance for all three controllers at almost no cost in EEF accuracy.

Xu, Xiaomeng, Zhang, Han, Ruan, Zhian · 563 views · Oct 8, 2026
Whole-Body ManipulationTactile Sensing
Oct 8, 2026

Temporal Visuo-Tactile Learning for Dexterous Grasp Stability

Temporal Visuo-Tactile Learning for Dexterous Grasp Stability

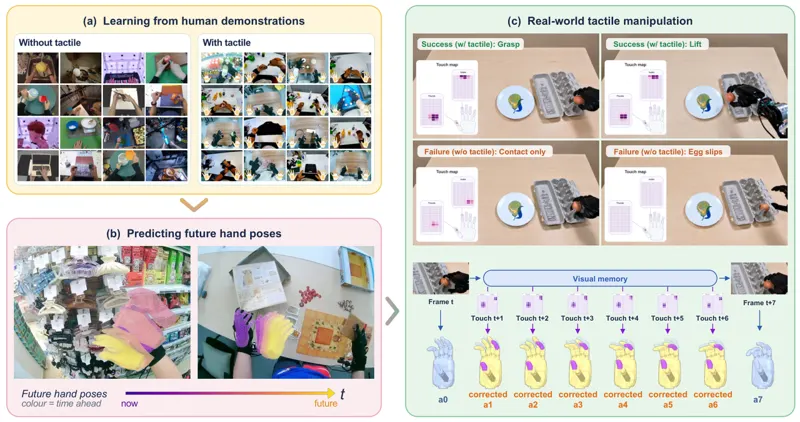
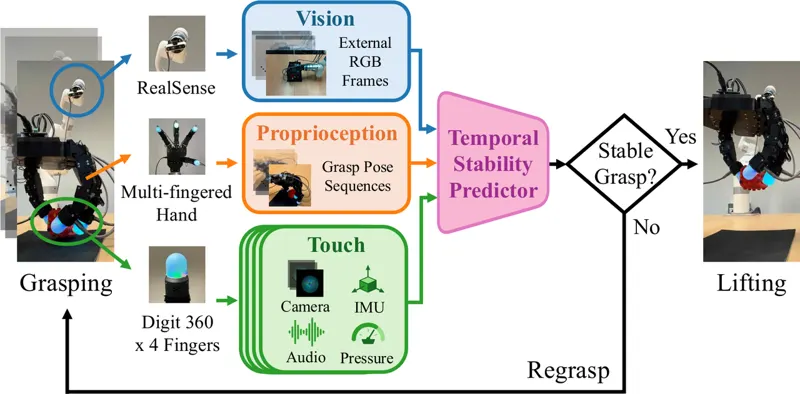
Most robotic grasping research picks a pose from vision and closes a parallel gripper, while humans rely on fingertip touch and almost never drop things. The LASR Lab at TU Dresden reframes the question as "is this multi-fingered grasp stable before we lift?" and answers it with data. They mount four Digit 360 sensors on the fingertips of a 16-DoF Tilburg Hand on a 7-DoF xArm7 and automatically collect 10,000 grasp trials over 200 objects (105 rigid, 95 deformable, 1.9-244 g), recording external RGB-D, proprioception and four tactile streams (camera, audio, IMU, pressure) throughout each grasp. Stability labels come from SAM 3 measuring post-lift object height and agree with manual verification on 92.34% of trials. The predictor consumes a 3-second window anchored at grasp initiation: 16-frame RGB and tactile clips go through pretrained VideoMAEv2-Base, 100-step proprioception and 224-step audio/IMU/pressure go through Transformers, fingertip features are fused across modalities, time and fingers by weight-shared factorized attention, and everything is aggregated by attention fusion into a post-lift stability probability. Under 5-fold object-disjoint cross-validation, vision+proprioception+touch reaches 83.55% and removing touch costs 3.99 points (79.56%). Tactile spatial resolution matters monotonically (79.40% at 1x1 up to 83.55% at 112x112), and freezing touch to its final frame costs 2.07 points, so the useful signal is high-resolution and dynamic. Deployed as an online lift-or-regrasp gate (threshold 0.95, up to five regrasps) on 20 objects excluded from training, the visuo-tactile gate reaches 82.0% success among executed lifts, 10.5 points above a non-tactile gate. The ~1.2 TB dataset is public on OPARA.

Ken Nakahara, Aleksei Buvailik, Prokhor Kotov · 625 views · Oct 7, 2026
Dexterous ManipulationTactile Sensing
Oct 7, 2026
DexTacWAM: A Visuo-Tactile World-Action Model for Dexterous Manipulation

DexTacWAM: A Visuo-Tactile World-Action Model for Dexterous Manipulation

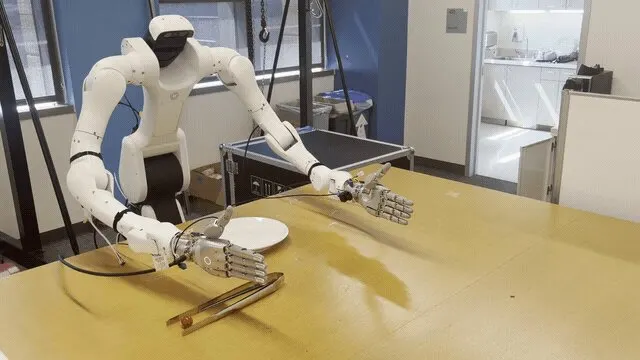
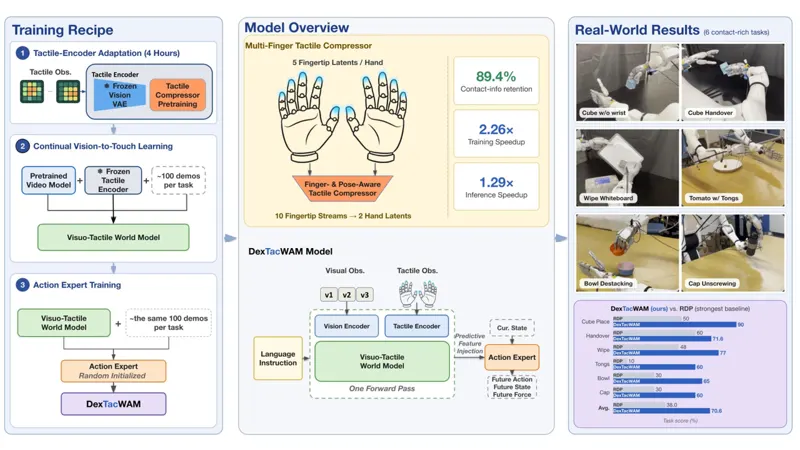
Dexterous manipulation depends on contact dynamics that are often only partially observable from vision. Recent World-Action Models (WAMs) couple predictive video world modeling with action generation, but remain largely vision-centric and therefore cannot directly model these contact dynamics. We present DexTacWAM, a visuo-tactile WAM that encodes each fingertip independently, aggregates the resulting features through a finger- and pose-aware tactile compressor, and injects the tactile latent into a video diffusion world model for joint visuo-tactile world modeling. Across six contact-rich dexterous manipulation tasks on a 22-DoF bimanual platform, DexTacWAM achieves the highest score on every task, averaging 70.6 versus 38.0 for the strongest baseline. Ablations attribute the gain to modeling contact evolution as part of the predicted world state rather than tactile conditioning alone: removing tactile world modeling reduces the four-task mean from 74.7 to 26.6 while keeping the same tactile features and action expert. After four hours of tactile-encoder adaptation with a frozen pretrained vision VAE, our continual vision-to-touch learning extends the pretrained video model to touch using roughly 100 demonstrations per task without tactile midtraining, while retaining visual prediction quality within 0.5 dB of vision-only counterparts. The compressor retains 89.4% of pre-fusion contact recall while enabling 2.26x faster training and 1.29x faster inference. Together, these results show that pretrained video priors can be extended to distributed multi-finger contact dynamics in a data- and compute-efficient manner.

Haoran Yuan, Zekai Wang, Boning Shao · 862 views · Sep 21, 2026
Dexterous ManipulationWorld-action models
Sep 21, 2026

As an Amazon Associate, we earn from qualifying purchases.