PAPERNov 2, 2026
RoboColosseum: Evaluating Physical Intelligence at Scale In-The-Wild
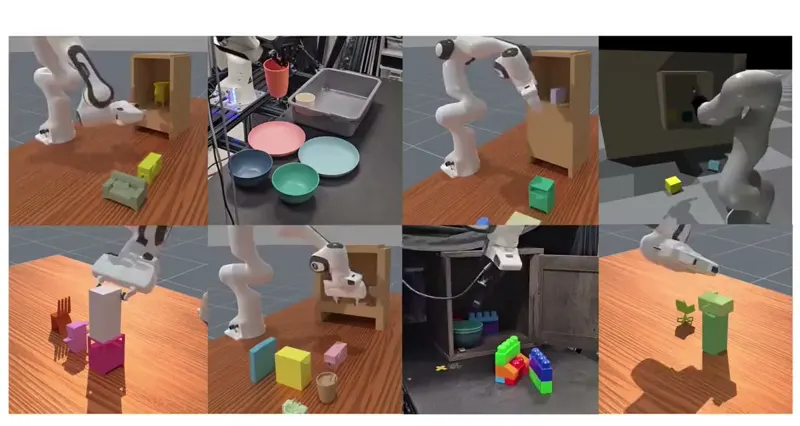
General-purpose robot policies must work across robots, tasks, and environments, yet the variation that makes physical trials informative also makes them difficult to reproduce. We introduce RoboColosseum, a distributed evaluation framework that combines unified policy serving and standardized protocols across a network of locally operated robots in diverse environments. Our initial study evaluates five vision-language-action (VLA) policies and three frontier AI agents across four embodiments (SO-101, Franka, Bimanual-YAM, and G1 Humanoid). The Open Track compares models without task-specific adaptation in blinded, pairwise trials under matched local conditions. The Fine-tune Track measures how well VLA policies adapt to 20 tasks across all four embodiments when each policy receives the same 100 demonstrations per task. Across 5,699 pairwise Open Track comparisons at 124 sites, frontier agents rival specialized VLA policies, while all systems struggle to complete open-world tasks reliably. After fine-tuning, GR00T N1.7 leads on SO-101 and pi0.5 leads on Franka and Bimanual-YAM. Policy rankings show weak agreement across embodiment-specific task suites (Kendall W = 0.24). Open Track rankings poorly predict relative performance after fine-tuning, with substantial rank reversals on all three embodiments shared between tracks. Measuring partial progress reveals differences that task success alone misses. On the G1 Humanoid, no policy completes any of the five tasks, yet average progress ranges from 13.3% to 23.2% across policies. Open Track rankings stabilize as trials accumulate, and active matchmaking achieves comparable ranking agreement with substantially fewer physical trials than uniform sampling. These results show how distributed physical evaluation can reveal where robot policies generalize, how well they adapt to new tasks, and how far they progress on tasks they fail to complete.
Tan Sang Nguyen, Yi Ru Wang, Shailesh Shailesh
Physical AIVLA