From RT-1 to MolmoAct 2: A Brief History of Vision-Language-Action Models
A complete history of VLAs from SayCan and RT-1 through RT-2, RT-X, Octo, OpenVLA, pi0, SmolVLA and MolmoAct 2, including the author's action-discretization experiment.
Introduction
Vision-Language-Action models are one of the phrases I encountered most often after joining the robot-learning community on X. In 2026, with every new claim of a "GPT moment for robotics," what interested me was that robotics still has not converged on one thing to scale. Researchers continue to place strong bets on different methods, and VLAs are one of them.
I wanted to understand how the field arrived here, what actually changed between RT-1 and newer systems such as MolmoAct 2, and which architectural decisions made those systems work. This article traces that evolution, examines the trade-offs, and includes a small experiment along the way. Mostly, it is an excuse to update my own mental model of robot learning.
Why Do We Need VLAs?
Imagine that a robot arm is halfway through a pick-and-place task when someone moves the bin two inches to the left. The robot misses. It tries again and misses again. Eventually it stops.
This is not necessarily a sensor failure or a calibration problem. It exposes a deeper weakness in how many robots have been built: they are trained for precise conditions, and small changes can break them. The robot can see, and it can move, but it cannot reliably reason about what it sees and decide what to do next.
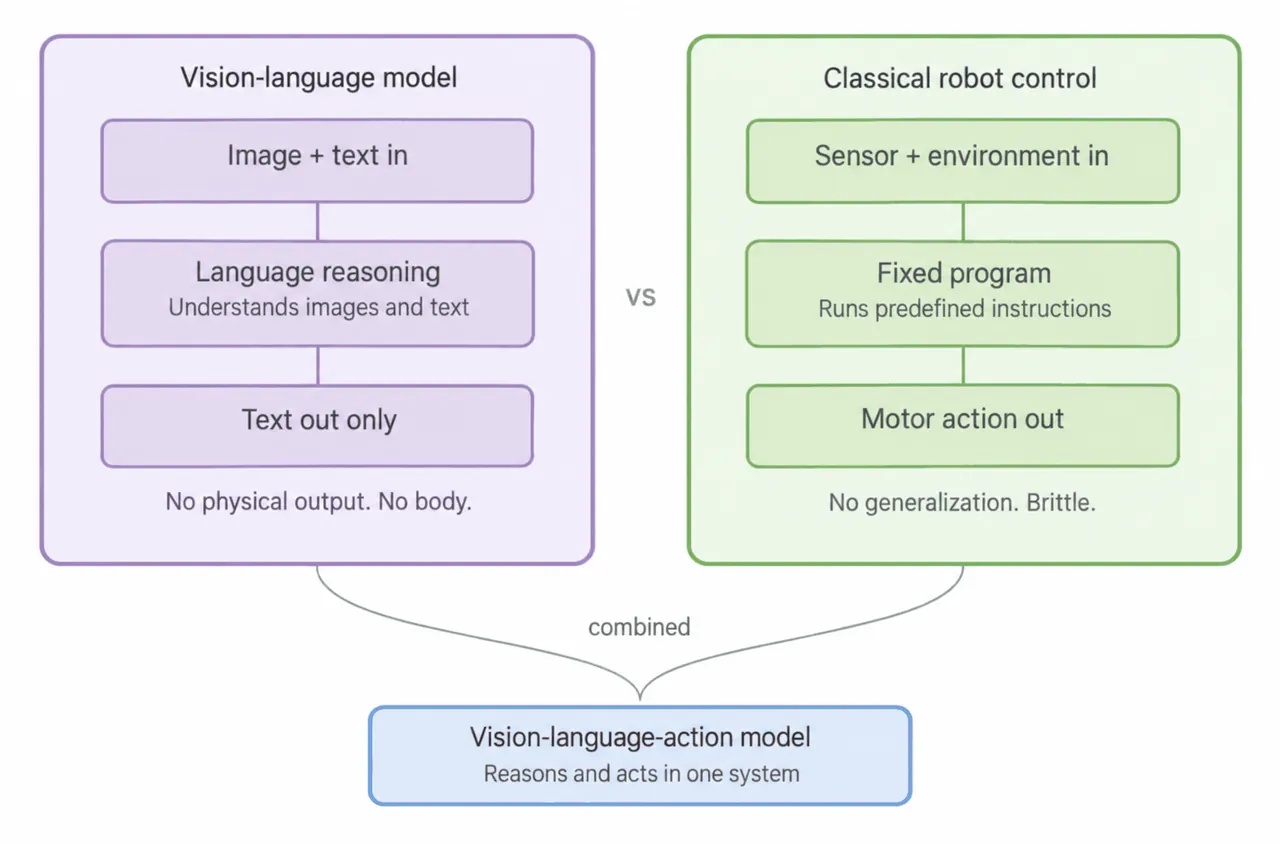
For a long time, the two halves of the problem were individually useful but not fully connected. Vision-language models became remarkably capable. GPT-4V, Gemini, and LLaVA could inspect a cluttered desk, answer where a cup was, or identify what was missing. They could not reach out and move anything:
- The reasoning happened almost entirely inside the model.
- There was no output connected to motors and no direct link to the physical world.
- The model was strong at understanding, but unable to act.
Classical robot control has powered industrial automation for decades. Factory arms and pick-and-place systems can be fast, precise, and reliable, but their competence is narrow. A system is usually programmed or trained for one task, one environment, and a limited set of conditions. It can fail when objects move a few centimeters, lighting changes, or anything appears outside the original setup.
In that sense, conventional manipulation did not generalize because its behavior was largely pattern matching without a broader model of the scene. Intelligent robots need generalization, and VLAs offered a promising route toward it.
The core insight looks simple in hindsight: take the reasoning capacity of a vision-language model and add a new output modality for actions. Train the combined system end to end on robot demonstrations. Early results showed that scene understanding and instruction following could transfer into physical control better than isolated imitation policies.
What Is a Vision-Language-Action Model?
In short, a VLA takes camera observations and a natural-language instruction and predicts robot commands. It replaces the usual sequence of separate perception, planning, and low-level control modules with one learned policy. This architecture can generalize beyond conditions seen during training, although how far it generalizes still depends heavily on the model, the data, and the post-training process.
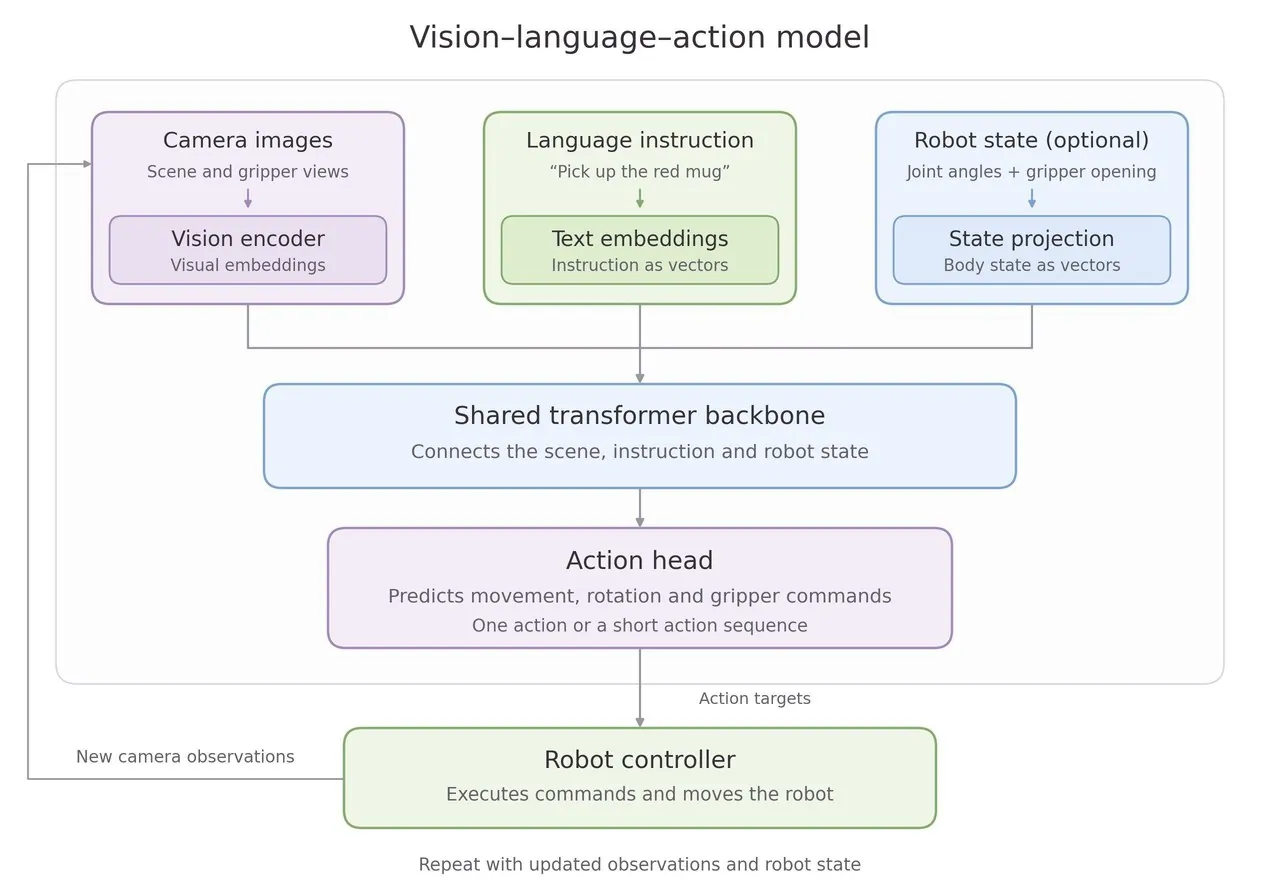
Consider a robot facing a red cup. You tell it, "Pick up the red cup." The camera images pass through a visual encoder, which turns image patches into visual feature embeddings. The instruction is tokenized and converted into text embeddings. Many models also receive robot state, such as joint angles and gripper opening, and project that state into the same learned representation space.
A transformer then processes these inputs together. For "pick up the red cup," it connects the phrase with the cup in the image and with the cup's position relative to the gripper. This relationship is represented internally rather than passed between separate hand-engineered modules.
The action head uses that representation to predict movement: changes in gripper position, rotation, and opening, for example. Some models produce discretized action tokens. Others directly predict continuous values, or use diffusion or flow matching. Many predict several future actions at once as an action chunk.
The robot controller executes those commands, receives a new image and state, and repeats the loop. During training, a VLA commonly starts from a pretrained VLM and learns from demonstrations that contain images, instructions, and matching actions. The demonstrations teach the model how to connect what it sees and what the user asks with the movements it should produce.
A Brief History of VLAs
The Coke Can Demonstration
This may be the most important moment in modern robot learning. In 2023, a Google researcher arranged a table with a Coke can and pictures of Tom Cruise, Snoop Dogg, and Taylor Swift. The newest robot brain, RT-2, was asked to move the can onto Taylor Swift's picture.
RT-2 was too large to run on the robot. The robot sent one onboard-camera image at a time to a TPU cluster, which returned control signals. The robot slowly picked up the Coke can and awkwardly placed it on the edge of Taylor Swift's picture. In 2025, Karol Hausman, one of the researchers on the team, described this as the moment when it became clear to him that the approach was going to work.
Within a year of that demonstration, Hausman and many key members of the RT-2 team had left Google and formed Physical Intelligence. Their robots have improved substantially since then. The company's later robot brains can open padlocks, fold laundry, peel an orange, make a grilled cheese sandwich and coffee, and clean bedrooms and kitchens they have never seen.
SayCan: Using a Language Model to Plan
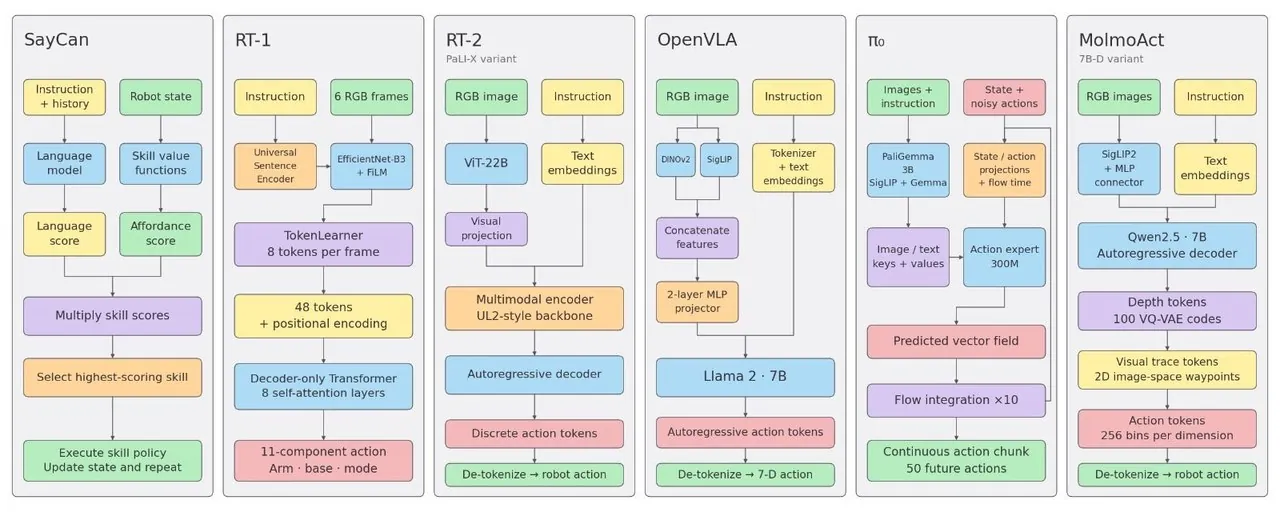
In 2022, the year ChatGPT was released, Google researchers began exploring what large language models could contribute to robotics. One of their first notable systems was SayCan. It used an LLM as a high-level planner that decomposed a complex task into subtasks. To clean up a spill, for example, SayCan could propose finding a sponge, picking it up, moving to the spill, and so on.
Once the language model selected "pick up a sponge," a separate neural network, trained to imitate people teleoperating a robot on small skills, computed the control signals. SayCan was therefore constrained by a finite menu of skills. The LLM could arrange those skills, but it did not learn a unified policy that could turn any instruction directly into motion.
RT-1: Learning a Unified Robot Policy
RT-1, or Robotics Transformer 1, changed that. Google Robotics trained it for more than 17 months on 130,000 successful robot episodes collected from 13 robots across more than 700 tasks. Its central idea was to map a natural-language instruction and camera images directly to discrete action tokens for the arm, base, and mode selection.
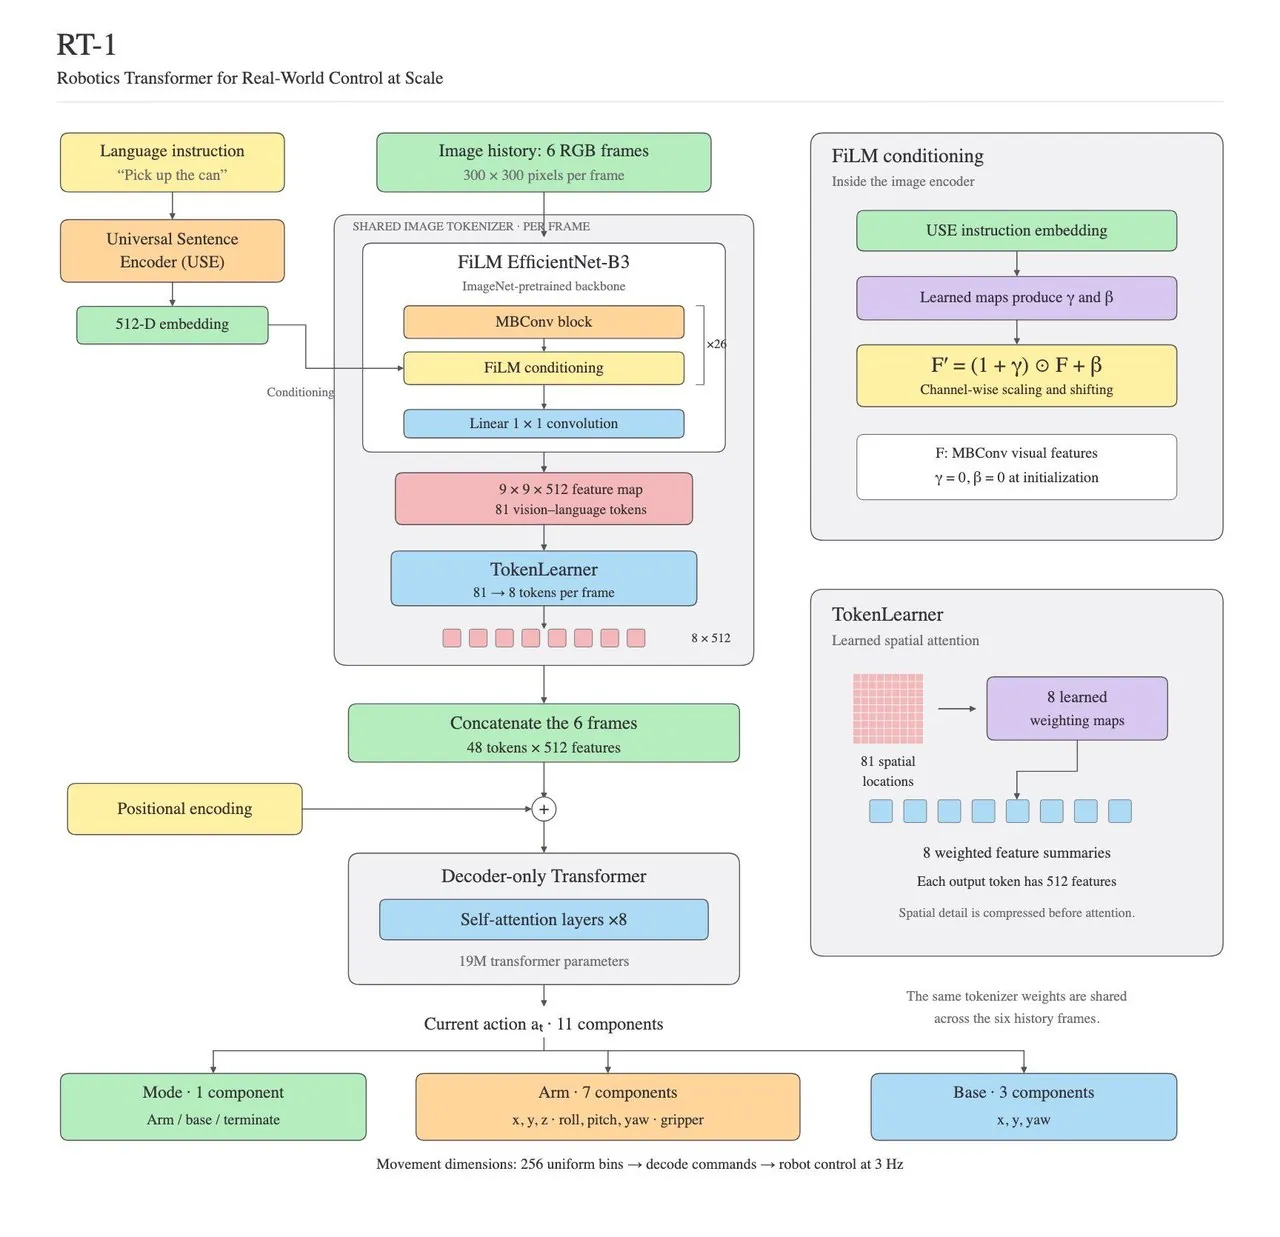
The model receives one instruction and six images at a time. Its action has 11 components: three dimensions of arm translation, three of arm rotation, one gripper command, two for base translation, one for base rotation, and one for selecting the active mode, such as controlling the arm, controlling the base, or terminating.
RT-1 combines a FiLM-conditioned EfficientNet, TokenLearner, and a transformer. Language is encoded with the Universal Sentence Encoder, which turns the full instruction into a fixed-size vector. It does not perform explicit LLM-style reasoning; it supplies a semantic representation of the task.
Each of the six 300 by 300 images is processed by an ImageNet-pretrained EfficientNet-B3. The encoder turns an image into a 9 by 9 grid, with a 512-dimensional vector at each location. That gives 81 spatial tokens per image, or 486 tokens across the six frames.
FiLM conditioning lets the instruction alter visual processing. The language embedding generates two sets of parameters, gamma and beta, which scale and transform the visual features. For "open the drawer," the model can emphasize the drawer and handle. For "pick up the can," it can emphasize the can and the gripper.
Self-attention over 486 tokens would be expensive, so TokenLearner compresses each image from 81 spatial tokens to eight learned summaries. Each summary is a weighted combination of information from across the image:
$$z_k=\sum_i \alpha_{k,i}F_i$$
The six frames therefore become 48 tokens. A decoder-only transformer with eight self-attention layers processes them. The full model has about 35 million parameters, including 19 million in the transformer.
The transformer can connect where the can is now, where the gripper was in previous frames, whether the gripper is approaching the object, and what the instruction requires. The action head then outputs discrete tokens. Each continuous component is assigned to one of 256 bins, turning control into a classification problem. RT-1 runs at about 3 Hz: observe, predict one action, execute, and observe again.
Training uses behavioral cloning. The model learns to copy expert human teleoperation actions conditioned on images and instructions, using 130,000 successful episodes and more than 700 task variations such as picking objects, placing them near one another, and opening or closing drawers.
The reported success rates were approximately 97% on tasks seen during training, 76% on unseen instructions, 83% under visual distractors, and 59% with new backgrounds. The drop from 97% to 59% shows that scaling the dataset improved robustness, but environmental generalization remained unsolved.
RT-1's main contribution was not a new reasoning mechanism. It showed that a single transformer policy trained with behavioral cloning could cover a large and diverse collection of real-robot tasks while remaining fast enough for closed-loop control. SayCan decomposed tasks; RT-1 learned to execute many low-level skills with one policy.
One especially interesting result was that reducing task diversity hurt generalization more than reducing the number of repeated demonstrations for the same task. Seeing many different behaviors can be more valuable than collecting a huge number of repetitions from a narrow task distribution. TokenLearner was also revealing because it creates an explicit information bottleneck. The policy becomes faster, but it assumes that eight learned summaries per image preserve everything needed for manipulation. Small objects and precise geometry may be lost.
Experiment 1: How Much Does Action Discretization Cost?
RT-1 outputs discrete action tokens, so every continuous command must be mapped to one value from a finite set. To study the information lost in this rounding step, I took 843 recorded actions from three LIBERO demonstrations, rounded every action component to a uniform grid, and compared 16, 32, 64, 128, and 256 values per dimension.
As expected, adding bins reduced reconstruction error. A second question was more consequential: what range should those bins cover? Imagine equally spaced marks on a ruler. If the ruler is shortened while the number of marks stays fixed, the marks are packed more closely together. Precision improves inside that range, but values outside it are rejected or clipped.
I compared a full-range version with a clipped version that covered only the first to ninety-ninth percentiles of observed commands. Figure 5 reports the resulting translation RMSE.
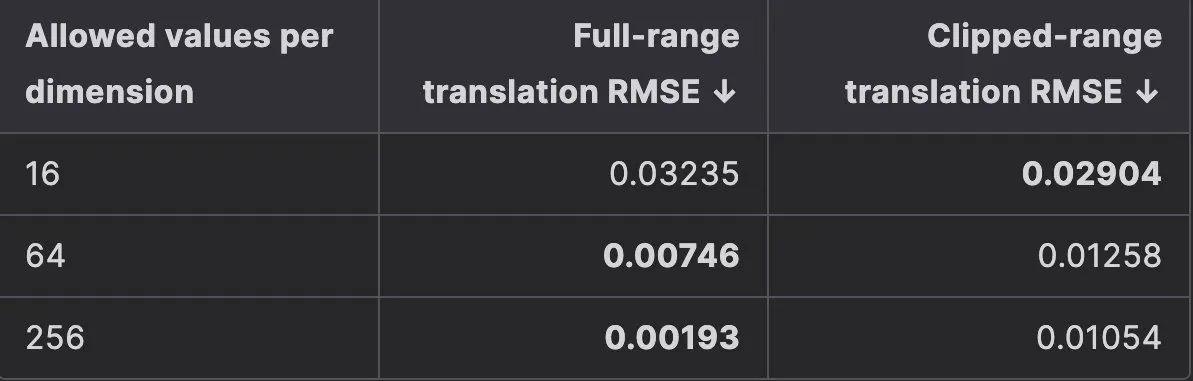
With 16 bins, clipping helped slightly: the finer spacing compensated for the information lost at the distribution's extremes. With 256 bins, the full-range version had roughly 5.5 times lower error. Rounding was already very precise in that setting, so rejecting clipped values hurt more than the extra resolution helped.
I also examined what happened as errors accumulated over consecutive commands. A smaller error on each individual step does not guarantee a smaller final discrepancy, because errors can reinforce one another or cancel. For this experiment, the key lesson was that action resolution depends on both the number of available values and the range they cover. The best one-step reconstruction also does not automatically imply proportionally better long-horizon behavior.
RT-2: Teaching a Vision-Language Model to Act
RT-1 learned from robot demonstrations, but its semantic knowledge was mostly limited to concepts present in those demonstrations. Web-trained VLMs already knew much more because they had consumed image-captioning, visual-question-answering, and language data. The next question was whether a VLM that already understood images and language could be turned into a policy.
The answer was yes. The trick was to treat actions as another language. A VLM can take an image and the question "Which object is the dinosaur?" and answer "the green toy." RT-2 instead trains it to take an image and "pick up the dinosaur" and answer with a sequence such as "128, 91, 241, 5, 101, 127, 217," representing a discretized robot command.
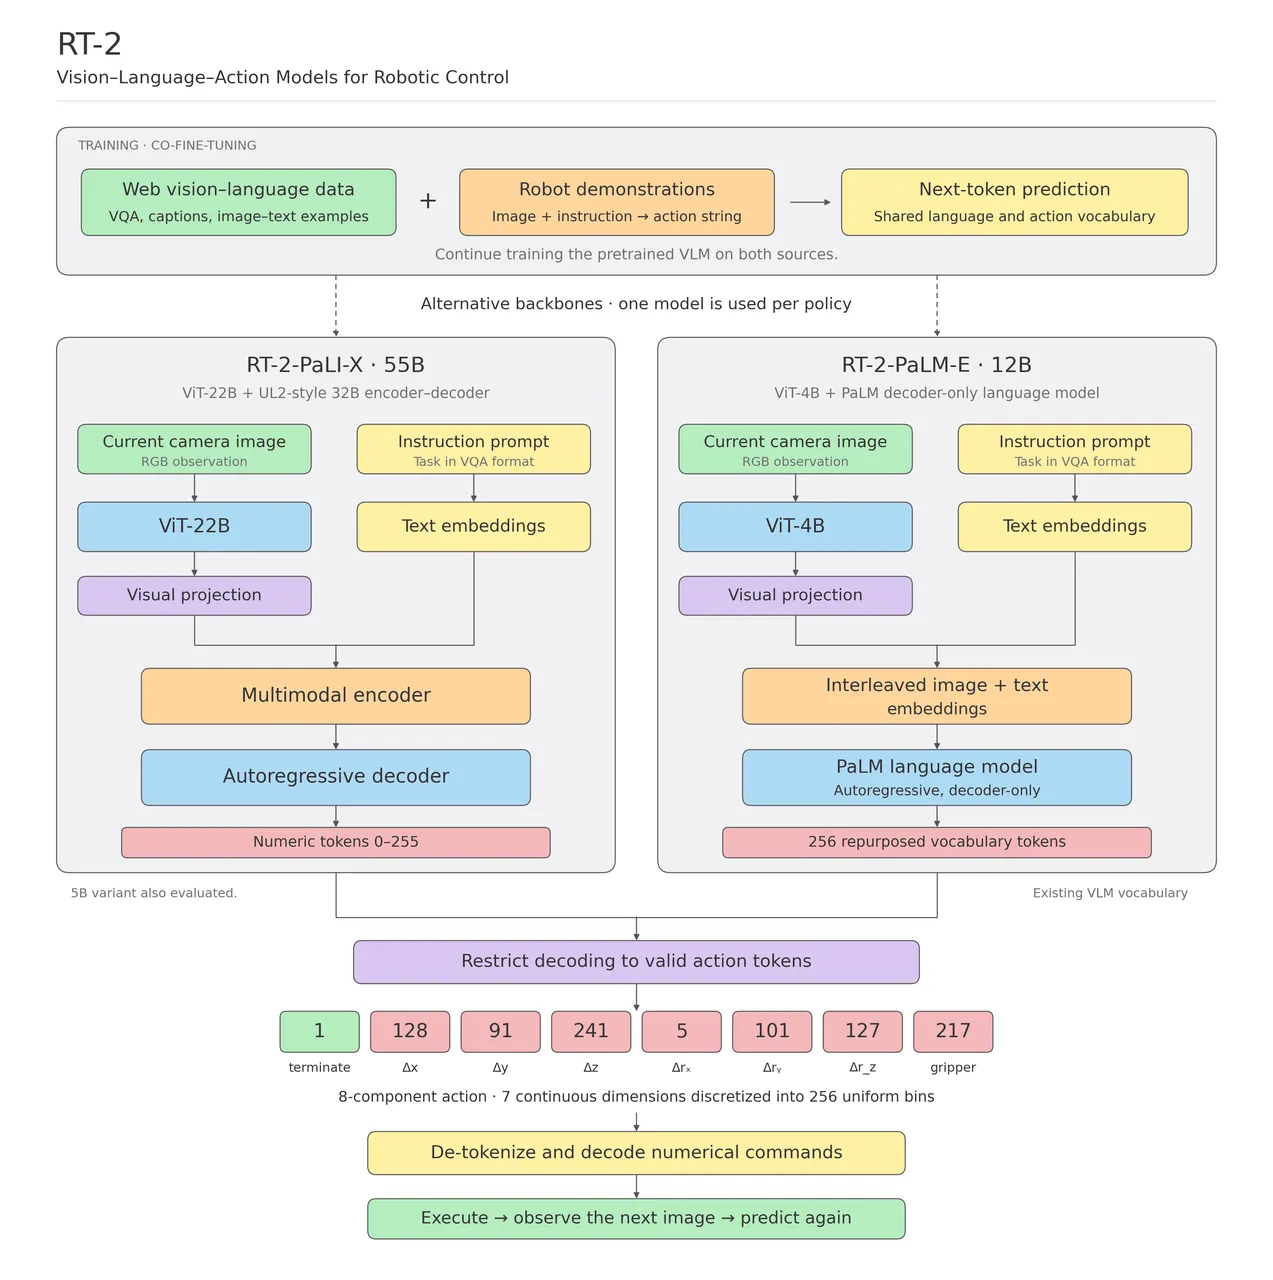
Unlike RT-1's six-frame history, the main RT-2 formulation uses only the current image. Temporal behavior comes primarily from closed-loop execution: act, observe a new image, and act again.
RT-2 predicts an eight-component action discretized into 256 bins. The paper uses two VLM families. PaLI-X was tested at 5B and 55B parameters; because its vocabulary already contains tokens numbered below 1,000, an action value such as 154 can use an existing token. PaLM-E was tested at 12B parameters; the authors assigned 256 rarely used words to act as action tokens. Those words are arbitrary, so their original meanings have no useful relationship to the action values.
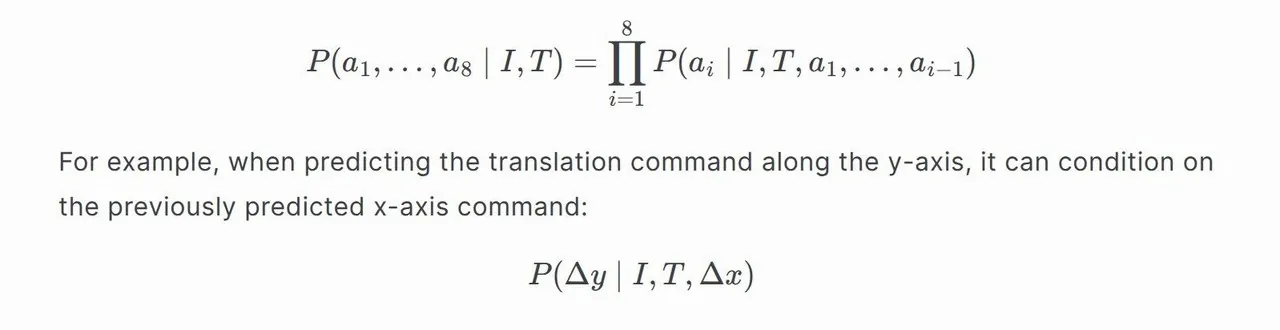
Another important idea is autoregressive action generation. RT-2 generates the eight action tokens sequentially. Each token is conditioned on the image, the instruction, and all previously generated action tokens:
$$P(a_1,\ldots,a_8\mid I,T)=\prod_{i=1}^{8}P(a_i\mid I,T,a_{1:i-1})$$
When predicting the translation command along the y-axis, for example, the model can condition on the x-axis command it has already generated.
The paper's ablation compares training from scratch, ordinary fine-tuning, and co-fine-tuning. Pretrained weights and retaining web data both improve generalization. This is why the Taylor Swift demonstration matters: Taylor Swift was certainly absent from the robot-control demonstrations. RT-2 had to connect an abstract concept learned from internet-scale pretraining with physical actions. That suggested robot policies could draw on far more of the world's image, video, and text knowledge than the robot dataset alone contained.
The demonstration answered a large question with a shaky but definitive yes: language and vision models can be trained to act as robot brains. The RT-2 team gave this class of model a name, vision-language-action, linking vision, language, and action in one network.
Open X-Embodiment and RT-X: Learning Across Robots
RT-2 showed that knowledge from a web-pretrained VLM could transfer into robot actions. The next question was whether experience could transfer between robots. If one robot learned to pick up an object, could its demonstrations help a different robot perform the same task?
Open X-Embodiment brought together 21 institutions and pooled more than one million robot trajectories across 22 embodiments and 527 skills. The robots differed in cameras, action spaces, and control systems. To make the data compatible, the project standardized camera observations and converted actions into a common seven-dimensional representation: three translations, three rotations, and gripper opening. Differences in coordinate frames and control conventions still remained.
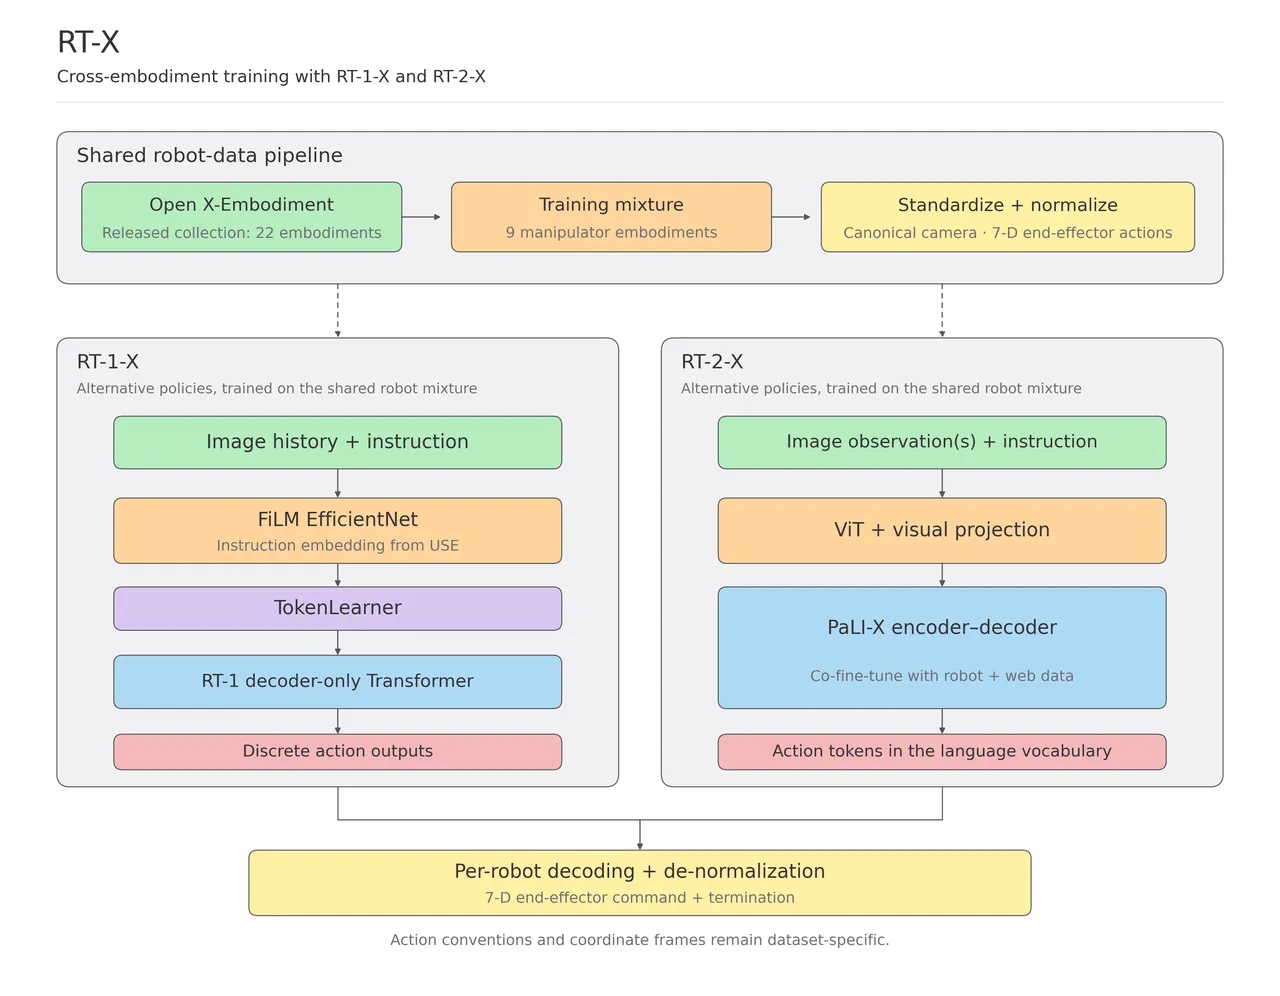
The team trained the existing RT-1 and RT-2 architectures on a mixture from nine robot embodiments, producing RT-1-X and RT-2-X. On skills absent from Google's own robot demonstrations but present in other robots' datasets, RT-2-X reached 75.8% success, compared with 27.3% for RT-2. Experience clearly could cross embodiment boundaries.
More data did not always help, however. The smaller RT-1-X struggled with the diverse mixture and sometimes performed worse than policies trained on individual robots. Pooling demonstrations alone was not enough; the model also needed enough capacity to learn from the combined distribution.
This raised the next question: could researchers build a pretrained robot policy that adapted easily to new robots, camera setups, and action spaces?
Octo: A Modular Open Generalist Policy
RT-X showed that experience from different robots could improve a shared policy. A practical generalist also needed to run on a new robot without retraining every component from scratch. Octo was designed for that form of adaptation.
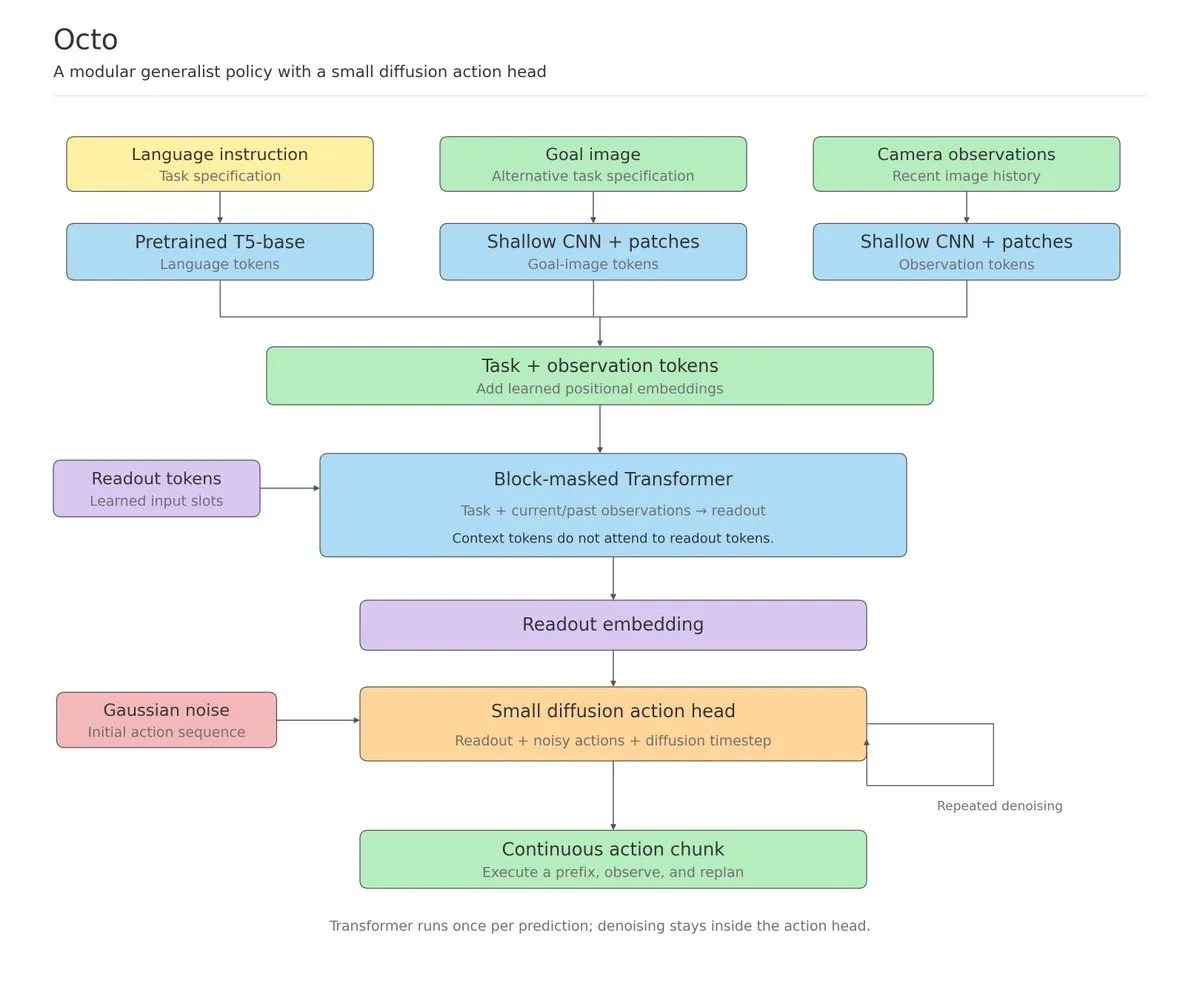
Octo is an open-source generalist robot policy pretrained on 800,000 demonstrations from 25 Open X-Embodiment datasets. It was released in Octo-Small with 27 million parameters and Octo-Base with 93 million. It accepts camera observations and either a language instruction or a goal image showing the desired result.
Its architecture combines input encoders, a transformer, and a diffusion action head. A pretrained T5 encoder converts language into semantic vectors. Convolutional networks turn camera images and goal images into patch tokens. The language and image tokens pass through the transformer together.
Learned readout tokens gather information from those inputs inside the transformer, and the action head uses their outputs to predict commands. This design also lets users add sensors or change the action head during fine-tuning while retaining the pretrained transformer.
Unlike RT-1 and RT-2's discrete action tokens, Octo generates continuous action chunks with a diffusion head. This choice addresses ambiguity. For the same scene and instruction, multiple movements may be valid. To reach a cup behind an obstacle, for example, the robot could go around either side. Training one action sequence with mean-squared error can average these alternatives and produce a trajectory straight into the obstacle. Diffusion can represent several possible modes and sample one instead of averaging them. It starts from noise and denoises it into a command sequence conditioned on the transformer's output. The transformer runs once per prediction; the repeated denoising happens inside the smaller head.
Octo was evaluated across nine real-robot setups. After fine-tuning with 100 demonstrations per task, it reached 72% average success across six setups, compared with 20% for a policy trained from scratch. With sufficient demonstrations and fine-tuning, the same pretrained policy could be adapted to different wrist cameras or end-effector commands.
OpenVLA: An Open-Source VLA
OpenVLA is a 7-billion-parameter open-source VLA trained on 970,000 demonstrations from Open X-Embodiment. It combines a visual encoder, a projector, and a Llama 2 language model. The starting point is the pretrained Prismatic-7B VLM, which uses two vision encoders: SigLIP and DINOv2.
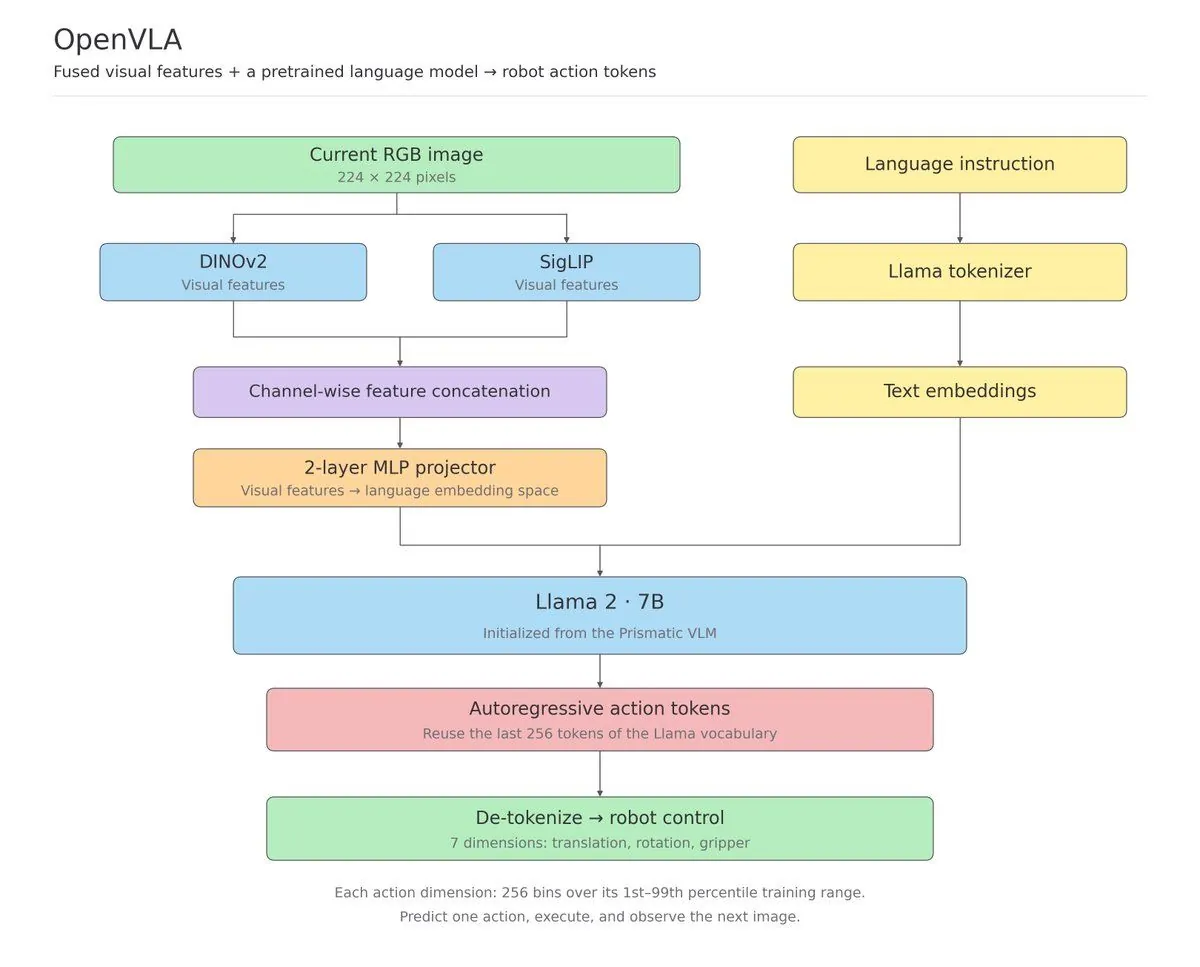
The image passes through both encoders and their features are concatenated. SigLIP contributes features learned from image-language matching, while DINOv2 adds spatial information useful for perception and control. A two-layer MLP projector converts the combined representation into embeddings that the language model can process.
OpenVLA predicts a seven-component action: three translation dimensions, three rotations, and one gripper command. Unlike Octo's diffusion chunks, the original OpenVLA predicts one action at a time autoregressively, similar to RT-2. Each action dimension is discretized into 256 bins using first-to-ninety-ninth-percentile clipping, and the model reuses the last 256 tokens of Llama's vocabulary as action tokens.
Across 29 tasks on WidowX and Google robots, OpenVLA outperformed the much larger 55B RT-2-X by 16.5 percentage points in average success. Training data differed, so the comparison should not be treated as a universal scaling law. OpenVLA also did not beat RT-2-X everywhere. RT-2-X was better at semantic tasks requiring internet concepts absent from robot demonstrations, such as the Taylor Swift example. OpenVLA's robot training did not retain web vision-language data, while RT-2-X used co-fine-tuning. Better robot-task performance therefore does not automatically mean better retention of a VLM's web knowledge.
How Should a Robot Predict Its Next Move?
At this point, two broad approaches have appeared. RT-2 and OpenVLA generate discrete action tokens. Octo and later models generate continuous action chunks with diffusion or flow matching. For dexterous tasks that require precise, high-frequency movement, the natural question is whether the semantic strength of a pretrained VLM can be combined with continuous generation.
π0: Continuous Actions with a Separate Action Expert
π0 is a VLA from Physical Intelligence that combines a pretrained VLM with a dedicated action expert to produce continuous robot commands. I had seen it discussed frequently, and the demonstrations explain why. In one table-cleaning example, π0 sometimes stacked dishes before moving them instead of picking up every object one at a time. Laundry folding also requires continuous adaptation because every fold changes the observation. These policies received task-specific post-training; their dexterity did not come from the pretrained VLM alone.
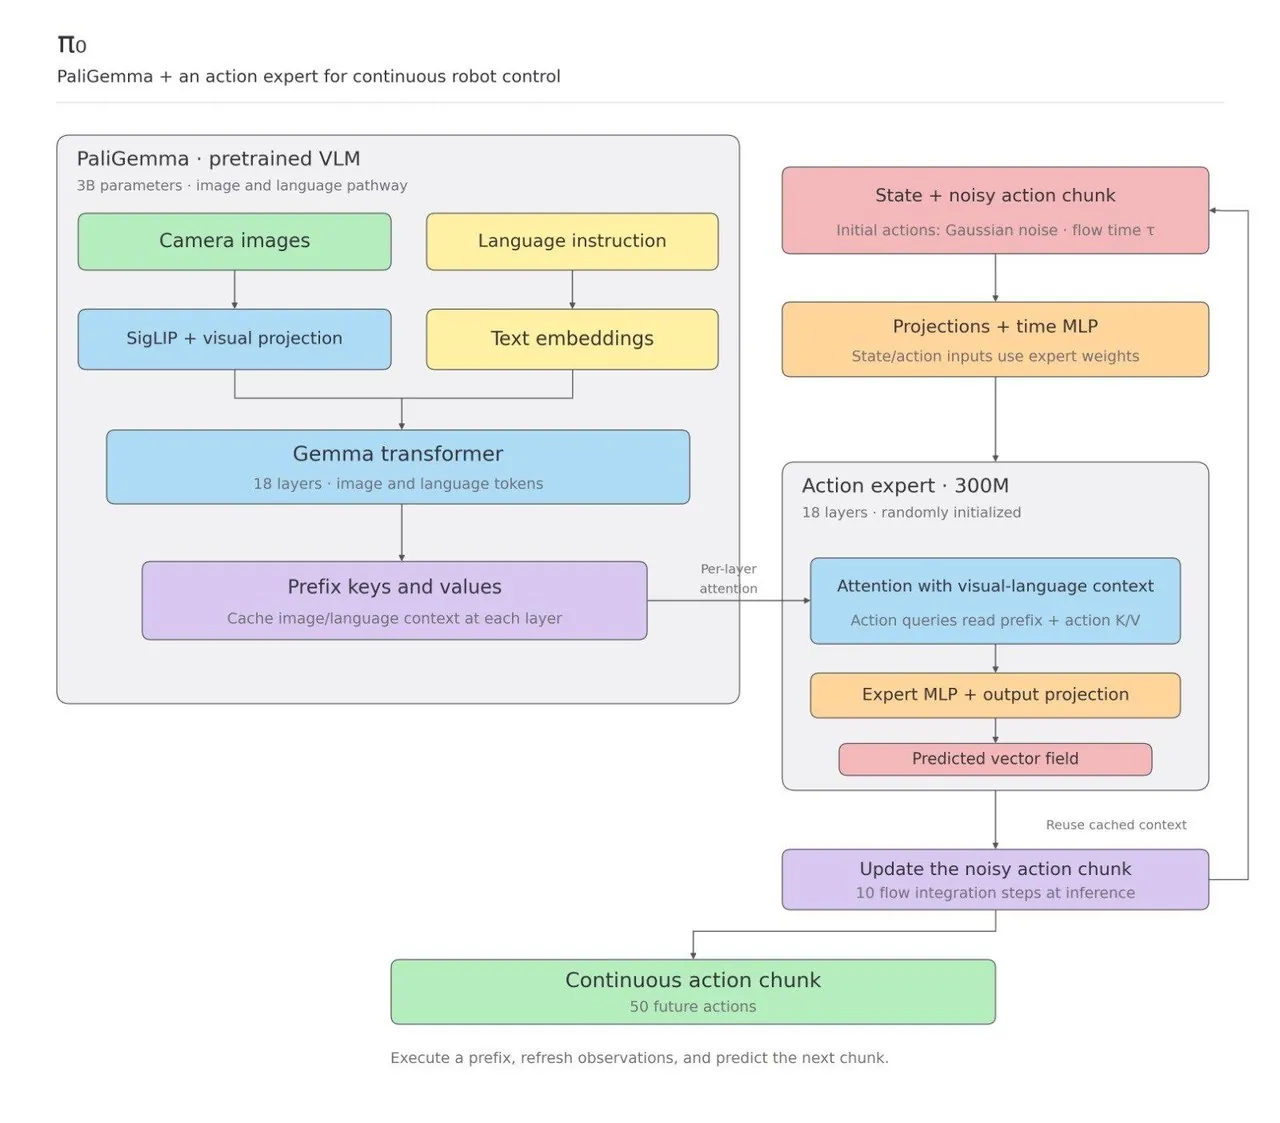
The model contains PaliGemma, a pretrained 3-billion-parameter VLM, and an action expert with roughly 300 million parameters. It receives camera images, a language instruction, and robot state such as joint angles, then predicts a chunk of 50 future actions.
Instead of emitting discrete tokens, π0 adds a smaller transformer that follows Gemma's architecture but is narrower and randomly initialized. It attends to robot state and information from the VLM, then generates continuous commands. The expert uses flow matching: it starts from random noise and repeatedly updates the candidate action chunk using the images, instruction, and robot state. These refinement steps happen inside the model before the robot executes the chunk.
π0 combines VLM pretraining with continuous generation, but producing each chunk still requires repeated refinement. Predicting 50 actions together also does not mean that every action uses a fresh observation. Deciding how much of a chunk to execute before replanning is another architectural and deployment choice. I am exploring that trade-off separately.
SmolVLA: A Policy Small Enough to Fine-Tune
After reading about the models with billions of parameters, SmolVLA stood out because its size makes local fine-tuning plausible. It has about 450 million parameters, roughly one-sixteenth of OpenVLA. Its real-world base model was pretrained on fewer than 30,000 episodes from publicly shared community datasets.
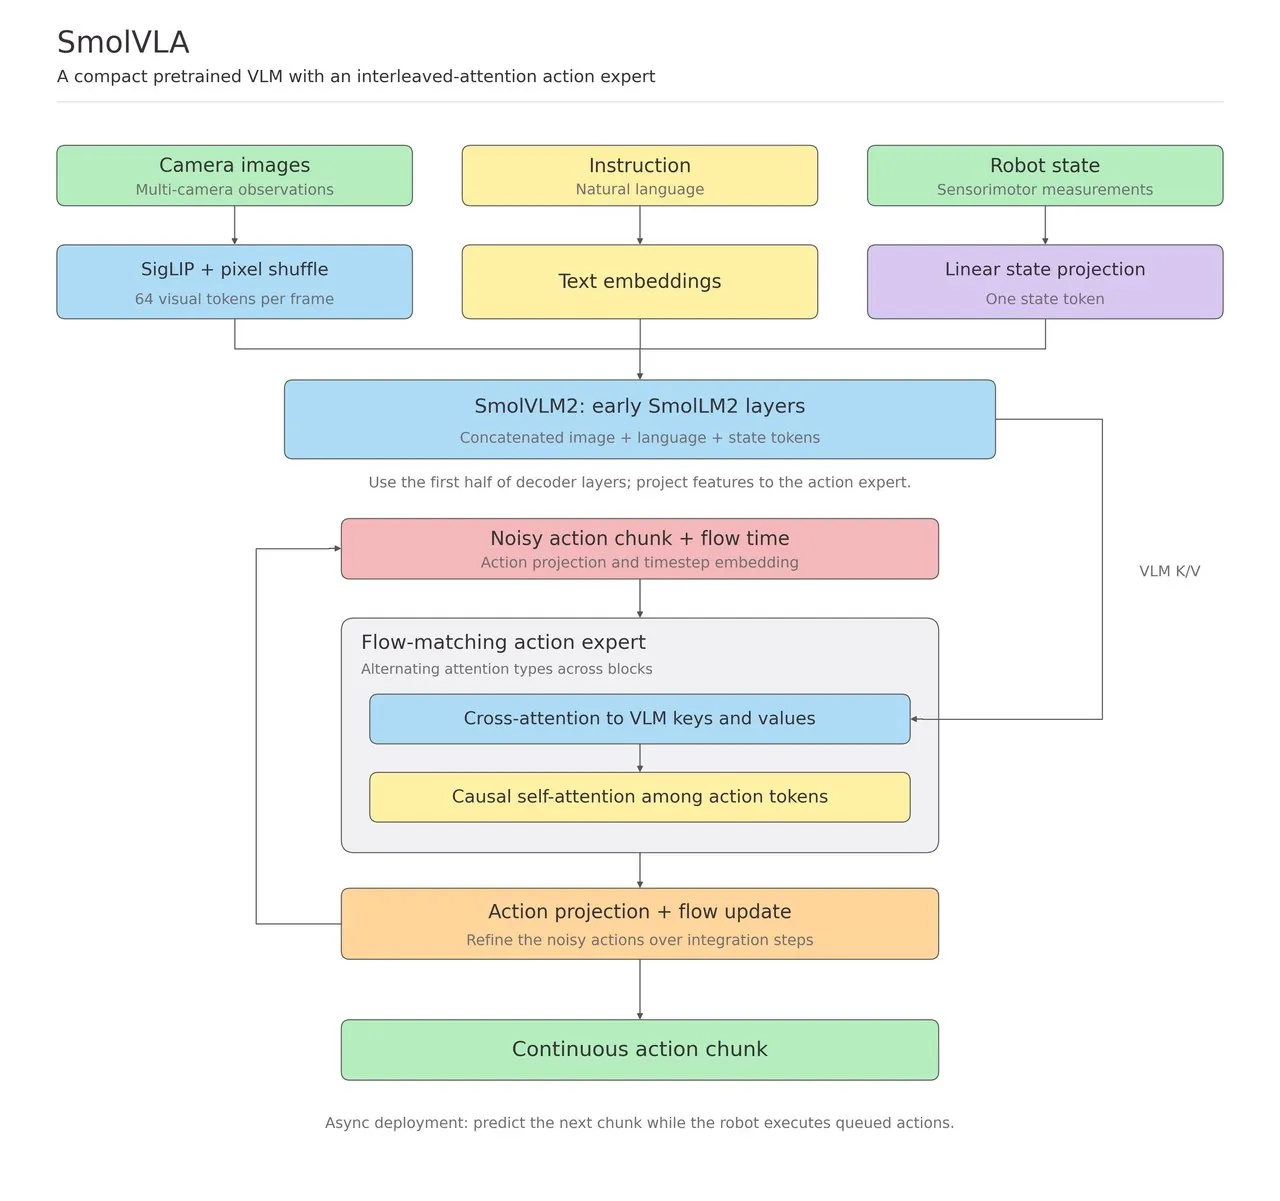
SmolVLA uses SmolVLM2, which combines a SigLIP image encoder with the SmolLM2 language model. Like π0, it uses flow matching and outputs a continuous action chunk. It also uses only the first half of the VLM's language-decoder layers and reduces each image to 64 visual tokens. The action expert does not need the full language model to finish processing before using visual and instruction features.
The model supports asynchronous inference. A synchronous robot might finish a queued chunk and then wait for the next prediction. SmolVLA requests the next chunk while it is still executing the current one, roughly doubling task throughput and reducing idle time. The trade-off is that later actions in the queued chunk are based on older observations, not a fresh image at every step.
I have also run experiments with a LIBERO-trained SmolVLA checkpoint to see how changing the instruction affects behavior. Those results belong in a separate article.
MolmoAct: Making Spatial Reasoning Explicit
Reading MolmoAct reminded me of object-navigation work I did during an internship. The methods differ, but both make spatial information explicit instead of expecting the network to learn every geometric relationship implicitly.
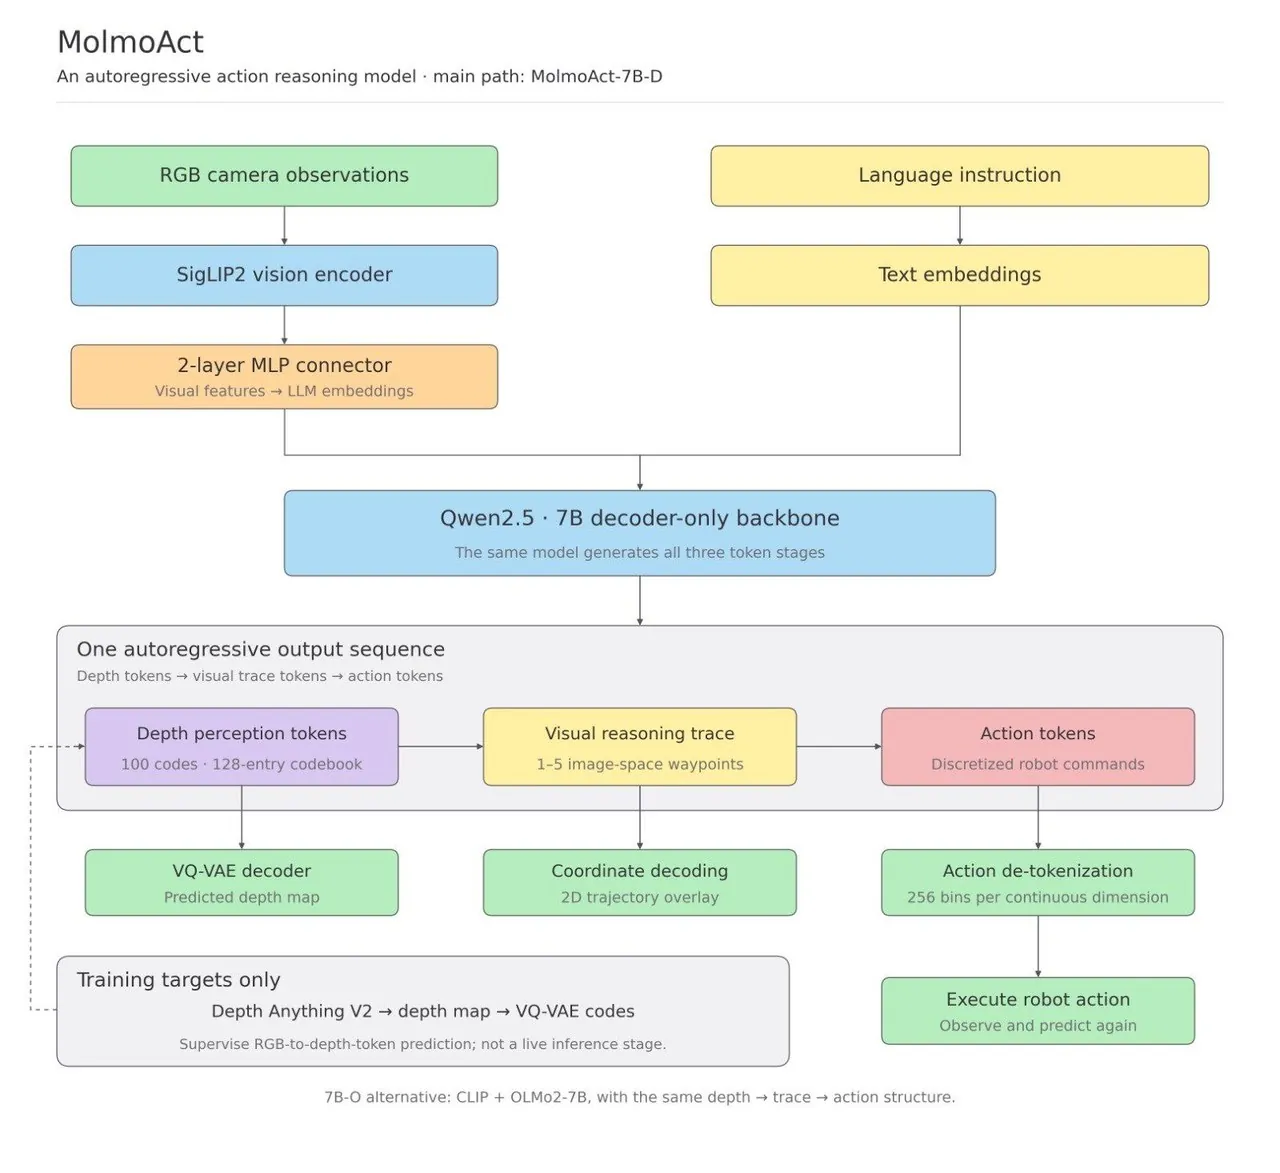
Most VLAs map observations and instructions directly to actions. MolmoAct introduces three stages: predict depth, generate a visual trajectory, and finally produce robot actions.
For depth, it uses Depth Anything v2 and a VQ-VAE to compress a depth map into a 10 by 10 grid of discrete tokens. These tokens are training targets, so MolmoAct can learn to predict depth directly from camera images without running the external depth estimator at inference time.
The model then predicts up to five image-space points that describe the intended path of the end effector, followed by a chunk of eight discretized robot actions. The useful consequence is inspectability: a person can examine the predicted depth and intended movement instead of seeing only the final command. The cost is extra inference latency, and a trajectory that looks plausible in image space does not guarantee correct execution.
MolmoAct 2: Faster Spatial Policies
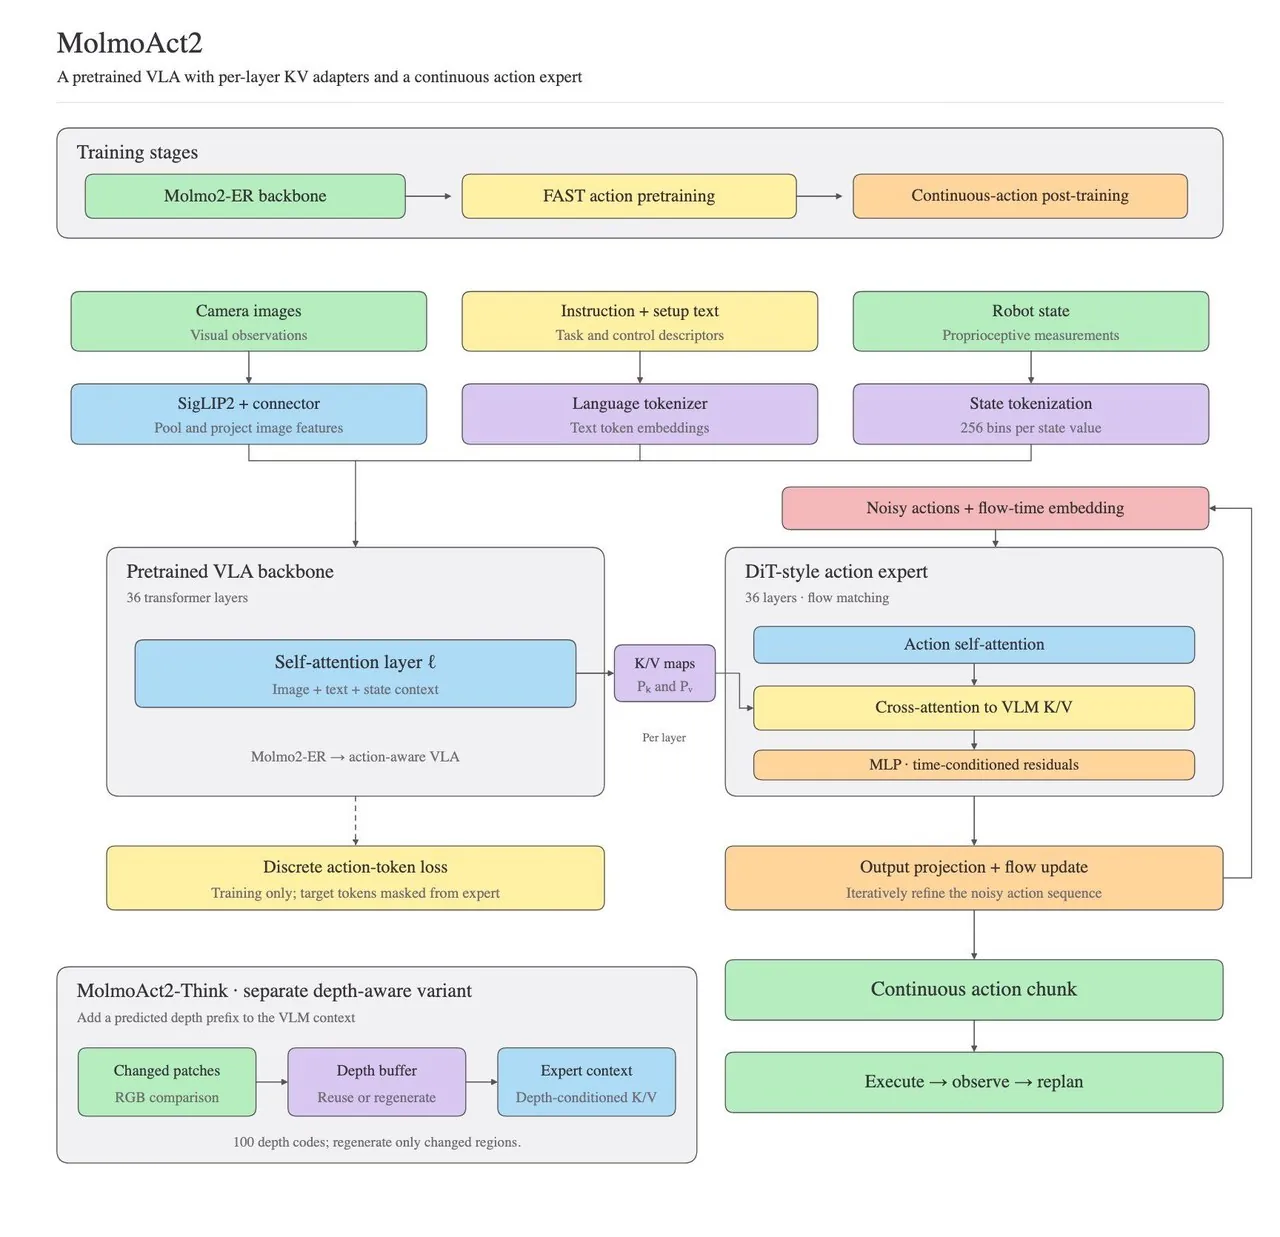
MolmoAct 2 builds on the first system with improved spatial reasoning, adaptive depth prediction, and a continuous flow-matching action expert. The result is considerably faster and more practical. The architecture still preserves intermediate spatial reasoning, but the action-generation path moves closer to the continuous experts used by π0 and SmolVLA.
Open Problems
After reading these papers, I keep returning to one idea: demonstrations can teach a robot where to start, but a robot should also learn from its own mistakes. Most VLAs discussed here are trained primarily through imitation learning. Reinforcement learning could take these pretrained policies further by using feedback from actual interaction to improve behavior. Collecting experience on real robots is expensive, and designing reliable reward signals is difficult. VLAs and RL therefore do not need to be separate directions. One provides a policy; the other provides a way to improve it through experience.
I am also interested in combining VLAs with world models. Instead of only predicting the next movement, what if the system could predict what would happen after that movement? A robot could compare possible actions, plan farther ahead, or learn from imagined rollouts. Inaccurate world-model predictions could also cause bad decisions, and the extra computation could slow reaction time. The benefit depends on getting both accuracy and latency right.
I do not know what the final architecture will look like. My intuition is that learning from demonstrations, predicting consequences, and improving through experience will all have a role. Their intersection is one of the most interesting directions in robot learning.
Conclusion
I started this article to understand how VLAs evolved and to update my own model of robot learning. The progression from SayCan's language-based planning to RT-1's unified policy, RT-2's transfer of web knowledge, and later systems such as π0 and MolmoAct shows substantial progress in a relatively short period.
I am not convinced that there is a single winning approach yet. Different architectures make different trade-offs among generalization, action precision, inference latency, and the amount of robot data required. The demonstrations have become much more impressive, but a large gap remains between completing a task once and performing it reliably in an uncontrolled environment.
The part I enjoyed most was testing some of these trade-offs myself. Even the small discretization experiment showed that bin count and action range can significantly change the commands a policy produces.
I have also been exploring how action-chunk size and replanning affect execution, along with how models such as SmolVLA respond to changes in language instructions. I plan to share those setups, results, and failures separately.
If you have worked on similar problems or have suggestions for useful experiments, I would be glad to hear them.
Source: From RT1 to MolMoAct2: A brief history of VLAs, by Khushi (@starlitmatcha) on X. This RobotWorld edition is a complete bilingual adaptation of the original article.
Source:X Article / Khushi (@starlitmatcha)https://x.com/starlitmatcha/status/2116918927913804223