Accuracy potential of visual localization exploiting high-end street-level imagery
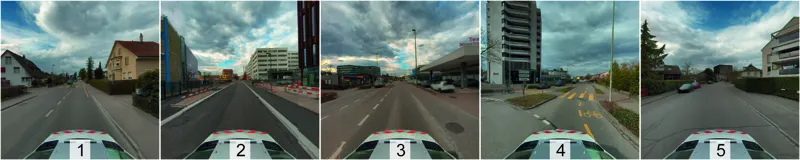
Accurate and reliable pose information with respect to a reference frame is increasingly demanded across applications such as autonomous navigation, surveying, robotics, and augmented and mixed reality. Visual localization can serve as a complementary positioning modality to GNSS, whose applicability and accuracy are often limited. Yet, the accuracy potential of visual localization has not been systematically investigated against survey-grade demands. This is mainly due to the lack of publicly available, large-scale outdoor datasets with ground-truth poses in the sub-centimeter range. In this work, we address both gaps. We introduce a scalable visual localization pipeline that employs precisely georeferenced, high-resolution street-level imagery directly as the scene representation. It combines prior-guided reference candidate selection with on-the-fly local Structure-from-Motion reconstruction and PnP-based pose estimation. We further present the FHNW Muttenz dataset, a real-world dataset covering a contiguous 10 km street network mapped in two mobile mapping campaigns approximately 1.5 years apart. It consists of high-resolution reference imagery and query sequences acquired by four different cameras across five representative scenes. All images are precisely co-registered, yielding 6-DoF ground-truth poses in the sub-centimeter range. Using this dataset, we evaluate the accuracy potential of visual localization. Our experiments demonstrate median pose accuracies in the range of 1-5 cm for translation and 0.05-0.1° for rotation, reaching as low as 1 cm and 0.03° under favorable conditions. These results show that visual localization can complement survey-grade GNSS positioning, paving the way for 3D geospatial data acquisition using consumer devices and fully automated georeferencing approaches. The dataset is publicly available at: https://fhnw-muttenz-vl-dataset.github.io/.
Jonas Meyer, Stephan Nebiker, Pascal Theiler·Jul 27, 2026
RoboticsRobotsJul 27, 2026
 0:56