Scaling Native Multimodal Pre-Training From Scratch
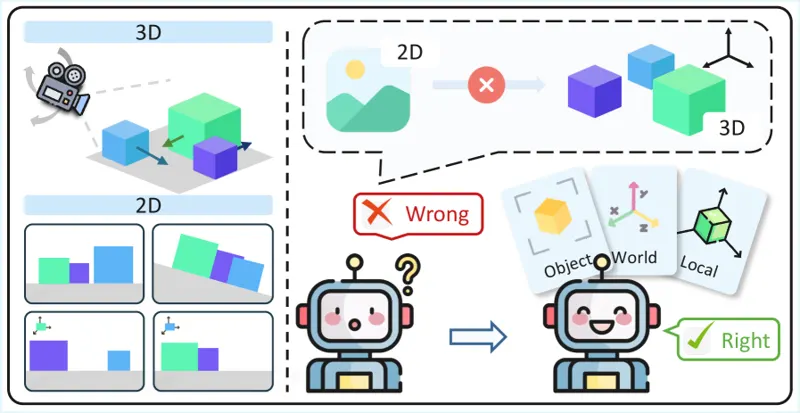
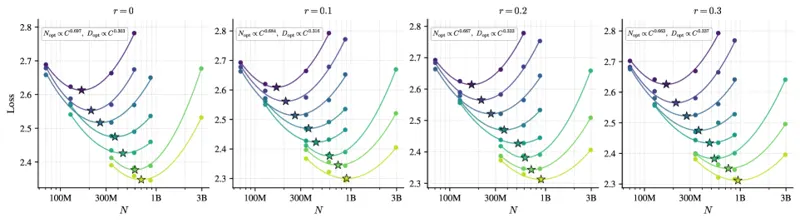
Although large language models (LLMs) exhibit remarkable reasoning capabilities, their reliance on text-only pre-training restricts the perception of the multimodal physical world. Native multimodal pre-training avoids this limitation by training models from scratch on multimodal inputs, thereby achieving deep cross-modal integration and mitigating optimization asymmetries inherent to traditional late-fusion architectures. Despite these advantages, the scaling properties of this paradigm remain systematically uncharacterized. To address this gap, we investigate the optimal model size and token count for training a transformer-based vision-language model under a fixed computational budget. We demonstrate that minimal objective loss adheres to a predictable compute law, whereas compute-optimal model sizes and token counts scale as power laws. Notably, language and multimodal objectives manifest distinct scaling behaviors. The language allocation law is largely invariant to the composition of the data, indicating stable language learning regardless of the multimodal data ratio. Conversely, the multimodal allocation law is highly sensitive to this composition. Specifically, text-heavy mixtures become compute-efficient only at larger model scales, shifting the optimal resource allocation toward greater model capacity. Additionally, by modeling the influence of data composition on compute laws and allocation exponents, we derive an efficiency frontier specifying precise configurations of model size, token count, and data mixture. Downstream evaluations further reveal that native multimodal pre-training induces positive cross-modal transfer, thereby enhancing pure-text spatial reasoning and enabling robust multimodal in-context learning. In summary, this empirical research establishes the essential groundwork for predictably scaling multimodal foundation models.
Haoyuan Wu, Aoqi Wu, Hai Wang·Jul 24, 2026
MultimodalPre-TrainingNativeJul 24, 2026
 0:43