PixelUMM: Pixel-Space Image and Video Model
Loading video
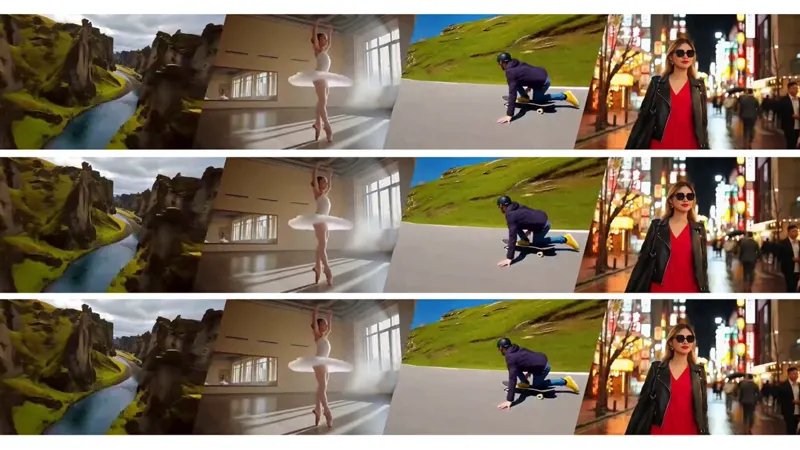
Loading videoPixelUMM removes vision encoders and VAEs, using 16×16 image patches and four-frame video tubelets in a Qwen3-8B backbone for unified understanding and generation.
Category: research
Author: @CongWei1230
Date: 2026-10-01T00:00:00
Duration: 28.966s
Reference: https://arxiv.org/abs/2609.38597