Skip to content
← Tags

#Gaussian Splatting (22)

Real2Sem2Real: 3D Semantic Augmentations for Robot Learning from a Single Human RGB Demonstration

Real2Sem2Real: 3D Semantic Augmentations for Robot Learning from a Single Human RGB Demonstration

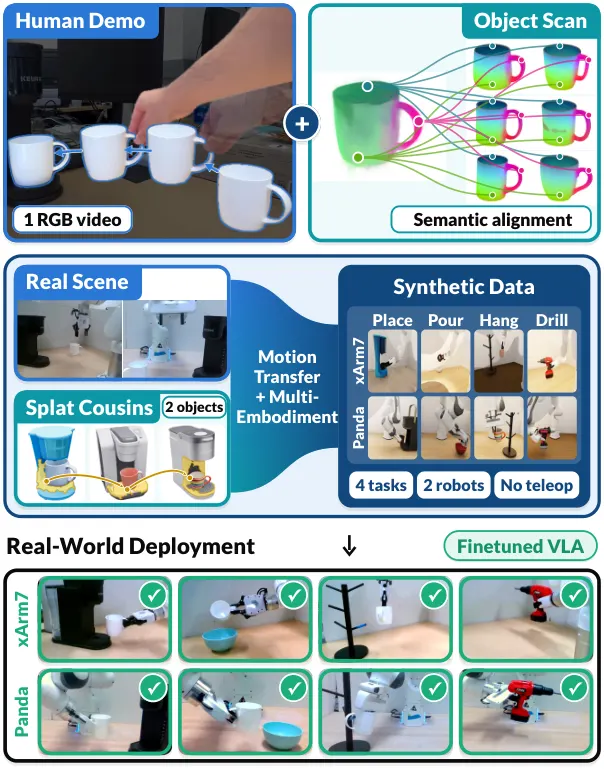
Human video scales easily and does not need robot hardware, but existing methods require depth sensing, overlay the robot onto 2D video, or generate data only for the demonstrated objects. We present Real2Sem2Real (R2Sem2R), a real-to-semantic-to-real pipeline that turns one monocular RGB video of a human demonstration into thousands of robot demonstrations across the semantic object instances of a category. R2Sem2R tracks the SE(3) pose of each object with DINOv3-distilled Gaussian splats, outperforming existing methods and FoundationPose with estimated metric depth. R2Sem2R then aligns digital cousins, each generated from one or a few photographs, to the demonstrated objects with a semantic alignment. This alignment matches whole objects and the functional regions of target objects, such as a coffee machine's tray. R2Sem2R maps the human hand to a feasible robot grasp that extends to the cousins. Robot demonstrations are generated either in IsaacSim, for photorealistic rendering, or MuJoCo, for contact physics, and R2Sem2R can generate over 2,000 episodes in about two hours. On two real robots and four tasks, we train a vision-language-action policy on data from one human video per task, and policies trained on our data match or exceed policies trained on teleoperation across diverse object instances. The project page is available at https://real2sem2real.github.io/.
Matthew Strong, Ankush K. Dhawan, Julien Poffet · 52 views · Oct 20, 2026
Robot LearningHuman demonstrations
Oct 20, 2026
WilLaGS: Latent-Conditional 3D Appearance Fields for Robust Gaussian Splatting In-the-Wild

WilLaGS: Latent-Conditional 3D Appearance Fields for Robust Gaussian Splatting In-the-Wild

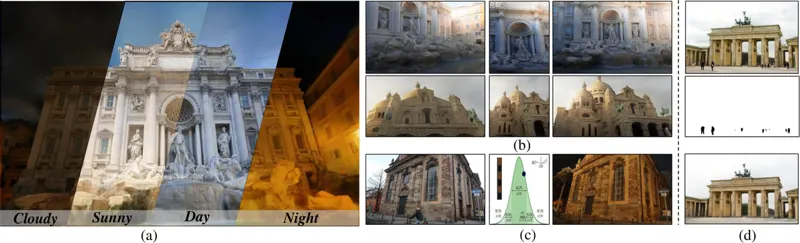
3D Gaussian Splatting (3DGS) delivers real-time and high-fidelity rendering but remains challenged by unconstrained in-the-wild scenes, where drastic appearance variations and transient objects violate multi-view consistency. Existing methods are fundamentally limited by independent and discrete embeddings that struggle to capture continuous environmental changes or model spatially-varying local illumination. To address these limitations, we propose WilLaGS, a unified framework for robust 3D scene reconstruction and generative appearance synthesis under unconstrained settings. Specifically, we introduce a generative appearance model where a β-VAE learns a structured and continuous manifold of global appearance. Conditioned on the latent code, we construct a 3D neural appearance field that generates dynamic Tri-Plane features to encode spatially-varying local illumination effects. Furthermore, to suppress transient artifacts, we present a self-supervised perceptual masking mechanism that leverages a Teacher-Student (EMA) architecture to derive a stable scene consensus, robustly identifying inconsistent regions via perceptual discrepancies. Extensive experiments on multiple datasets demonstrate that WilLaGS achieves state-of-the-art performance in reconstruction quality and novel view appearance synthesis, while maintaining real-time rendering efficiency.

Yuhao Bai, Qianqiu Tan, Lilong Chen · 839 views · Aug 28, 2026
3D Gaussian SplattingGaussian Splatting
Aug 28, 2026
DL-SLAM: Enabling High-Fidelity Gaussian Splatting SLAM in Dynamic Environments based on Dual-Level Probability

DL-SLAM: Enabling High-Fidelity Gaussian Splatting SLAM in Dynamic Environments based on Dual-Level Probability

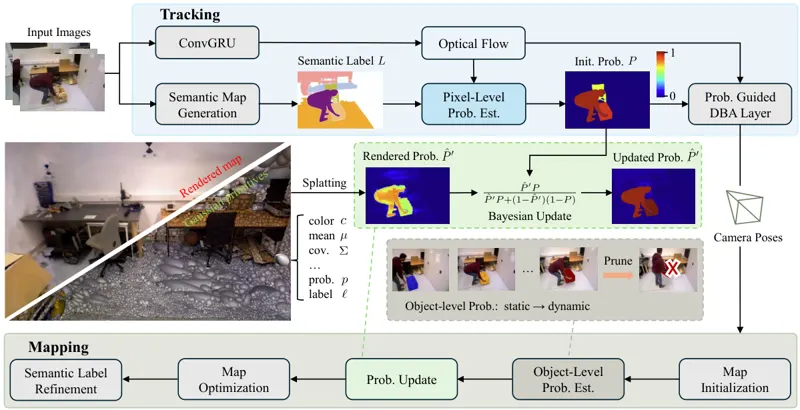
Recent advances in 3D Gaussian Splatting (3DGS) have enabled significant progress in dense dynamic Simultaneous Localization And Mapping (SLAM). Prevailing methods typically discard predefined dynamic objects, ignoring that transiently static objects offer valuable geometric constraints for pose estimation. A recent work attempts to leverage this potential by employing per-pixel uncertainty maps to quantify the magnitude of motion. While this approach enables transiently static objects to enhance pose estimation, it erroneously integrates these objects into the static map, resulting in persistent artifacts. Moreover, its reliance on purely geometric information leads to ambiguous object boundaries in the uncertainty maps. To overcome these limitations, we present DL-SLAM, a monocular Gaussian Splatting SLAM system built upon a novel dual-level probabilistic framework. Our method computes dynamic probability maps by combining semantic and geometric information. These pixel-level probabilities are lifted to 3D and aggregated to derive an object-level dynamic probability for each instance. Object-level probability enables the categorical pruning of dynamic Gaussians, resulting in an artifact-free static map. The static map, in turn, provides a geometrically consistent guidance to refine the pixel-wise probabilities, enhancing their reliability. Experimental results demonstrate that DL-SLAM outperforms existing approaches, improving tracking accuracy by up to 13% while generating high-fidelity semantic maps.

Ziheng Xu, Qingfeng Li, Xuefeng Liu · 780 views · Jul 2, 2026
Dynamic EnvironmentSLAM
Jul 2, 2026

As an Amazon Associate, we earn from qualifying purchases.