VINO Learns 3D Scene Features without Labels
Loading video
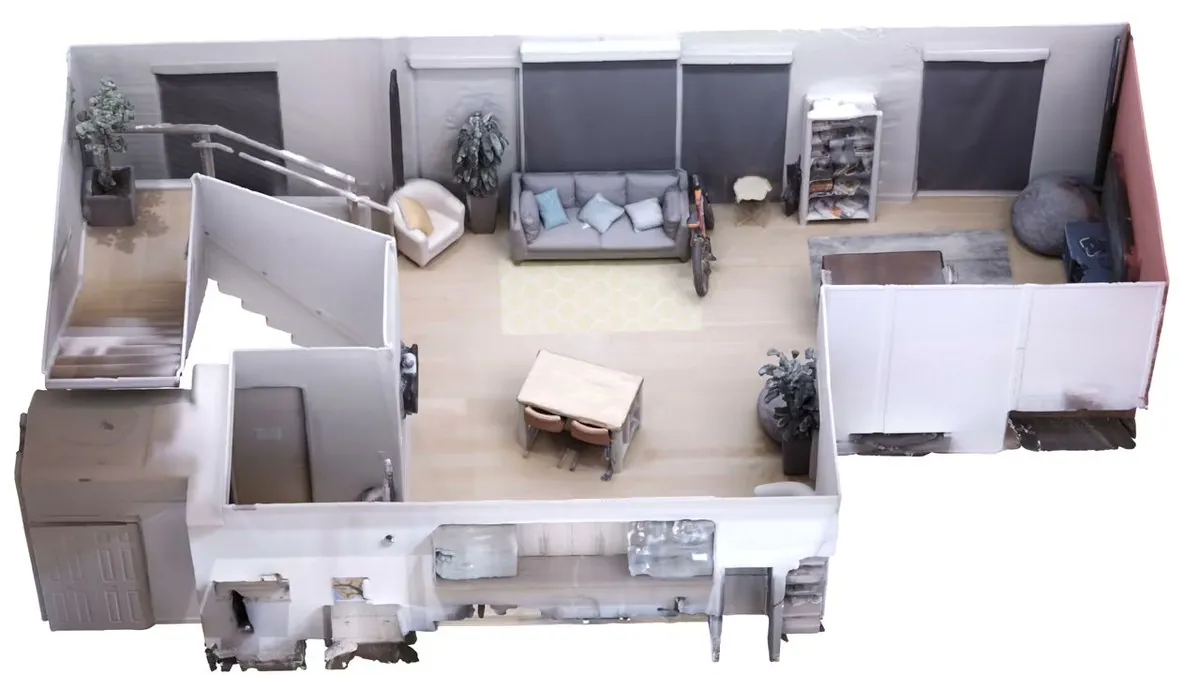
Loading videoVINO replaces a hierarchical point backbone with a Volume Transformer and redesigns its training objectives to learn semantic 3D features from unlabeled point clouds.
Category: perception
Author: @robotsdigest
Date: 2026-11-07T00:00:00
Duration: 13.8s