
Future Representation Distillation for Imagination-Free World Action Models
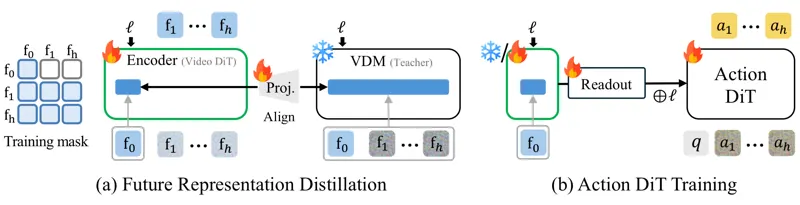
DreamFree turns a pretrained video diffusion model into a predictive visual encoder. A frozen teacher observes current and future frames, while a student predicts the teacher future representation from the current observation alone, so deployment avoids future-video denoising. Two-stage training combines future representation distillation with native flow matching, then learns an action readout and an action DiT. The 14B model reaches strong results on LIBERO, RoboCasa-Kitchen, and real DROID manipulation while running closed-loop control at 11 Hz, 17.8 times faster than DreamZero.
Jaehyeong Jo, Sangwon Jang, Sihyun Yu · 18 views · Nov 3, 2026
World-action modelsVideo Diffusion
Nov 3, 2026