RSI-Anything: Unlocking Recursive Self-Improvement with World Models
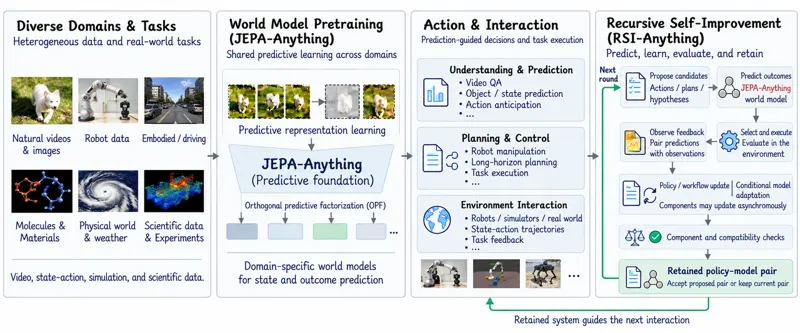
RSI-Anything turns predictive world models into the steering signal of a recursive self-improvement loop built on JEPA-Anything. Predictions decide which candidate actions earn scarce external feedback; that feedback then drives policy learning or workflow revision and, when reliability checks show the predictor has drifted under the changed policy, conditional world-model adaptation, while component and compatibility gates decide which policy-model pair is retained to shape the next round. With the coder held fixed, hidden-test success on 200 CodeContests tasks rises from 26.3% under a capacity-matched static verifier to 29.2% with a fixed world model and 31.2% after adaptation, at comparable online test usage. GUI evaluation reaches 99% on MiniWoB++ click-checkboxes while cutting mean actions per episode by 39.4%; five successive laboratory-planning policy versions more than double the LabHorizon F200 Level-2 score from 21.80% to 46.01%; and in a 40-experiment Suzuki-Miyaura flow screen RSI-Anything reaches 96.15% mean best observed yield against 82.16% for Bayesian optimization. An end-to-end immune-science application carries the same retained-workflow-plus-predictor contract into prospective therapeutic hypothesis generation.