
LG-VLN: A Zero-Shot Vision-and-Language Navigation Framework with LangGraph State Orchestration
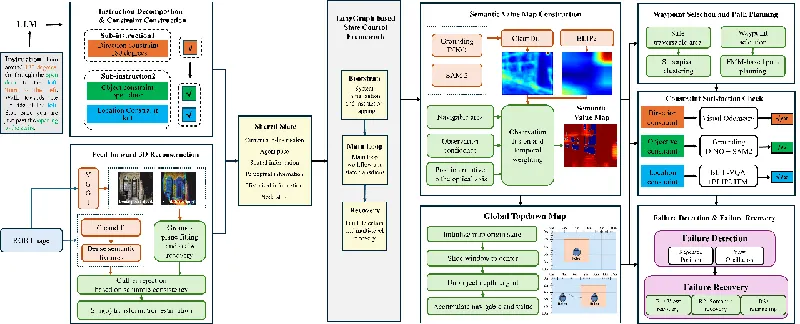
LG-VLN is a zero-shot VLN-CE framework that uses only monocular RGB. VGGT estimates depth, camera poses, and point clouds online, while CleanDIFT supplies shared dense features for correspondence filtering and semantic value construction. BLIP-2 image-text relevance is fused with target-reference similarity, and Grounding DINO with SAM 2 localizes objects. LangGraph orchestrates instruction tracking, mapping, planning, action execution, and staged recovery over persistent state. On a fixed 550-episode R2R-CE val-unseen subset, it reaches 21.3% SR, 12.1% SPL, and 7.85 m NE. The public repository is only a scaffold at the inspected commit and does not yet reproduce the paper.
Jianhe Zhao, Yanhua Qiu, Zhiyu Zhang · 47 views · Sep 14, 2026
Vision-and-Language NavigationVLN-CE
Sep 14, 2026