Skip to content
Tags

#Autonomous Driving (20)

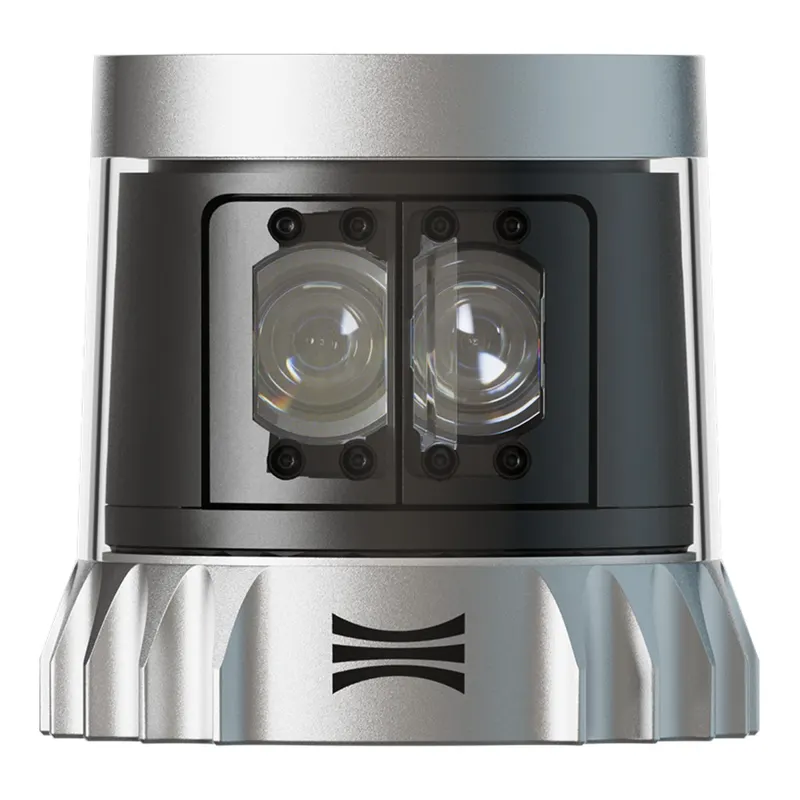
Ouster OS1 Max Rev8 256-Channel Long-Range High-Resolution Imaging Lidar

Ouster OS1 Max Rev8 256-Channel Long-Range High-Resolution Imaging Lidar

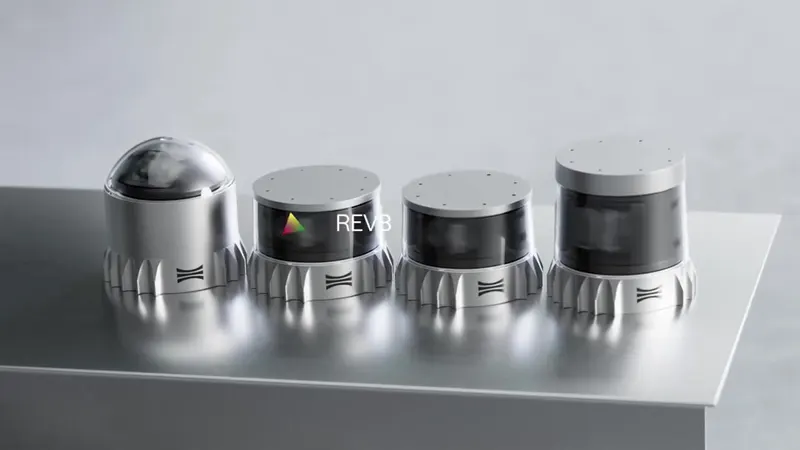
The Ouster OS1 Max is the flagship long-range imaging lidar of the Rev8 OS series and the first to reach 256 vertical channels (also 64/128): 865 nm Class 1 eye-safe laser, 360 deg x 43.9 deg FOV, 512-4096 horizontal columns, 5-40 Hz configurable rotation. In 1024 @ 10 Hz mode it reaches 350 m on 80% Lambertian targets and 200 m on 10% targets (both >90% detection probability at 100 klx sunlight), with 500 m max representable and 0 m minimum range; range accuracy is +/-1.25 cm (Lambertian) / +/-2.5 cm (retroreflective) at 0.1 cm resolution, up to 2 returns and 10,485,760 points per second. Native RGB-D color point cloud (116 dB dynamic range) carries RGB, range, signal, reflectivity, NIR, channel, azimuth and timestamp per point; a synchronous IMU runs at 640/1280/2560 Hz. Data leaves over gigabit Ethernet UDP with PTP/gPTP/NMEA/PPS time sync (<1 ms error) and <10 ms latency. It runs from 12/24 VDC (9-58 V) at 15-25 W (19 W nominal, 28 W peak starting at -40 C), measures 87 mm diameter x 82 mm and weighs 670 g (720 g with halo cap); IP68/IP69K, -40 to +85 C, 100 g shock and 10 Grms vibration. Engineered for functional safety (ASIL-B, SIL-2, PLd) with an on-sensor 3D Zone Monitor and designed for cybersecurity to ISO 21434 / UNECE WP.29 / IEC 62443 / ISO 27001. Built for long-range industrial sensing, off-highway vehicles, autonomous cars, trucks and buses, traffic and security monitoring, and 3D mapping vehicles.

COMPONENT

LiDAROusterLong DistanceRGB-DDigital LiDAR
Think at 5 Hz, Act at 20 Hz: Asynchronous Fast-Slow Vision-Language-Action Inference for Closed-Loop Driving

Think at 5 Hz, Act at 20 Hz: Asynchronous Fast-Slow Vision-Language-Action Inference for Closed-Loop Driving

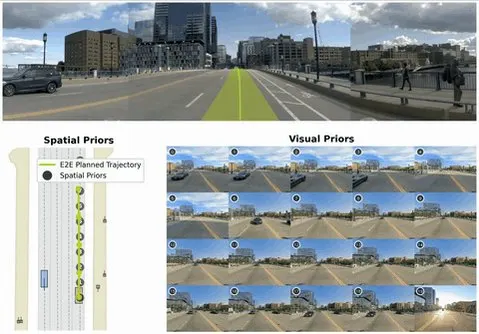
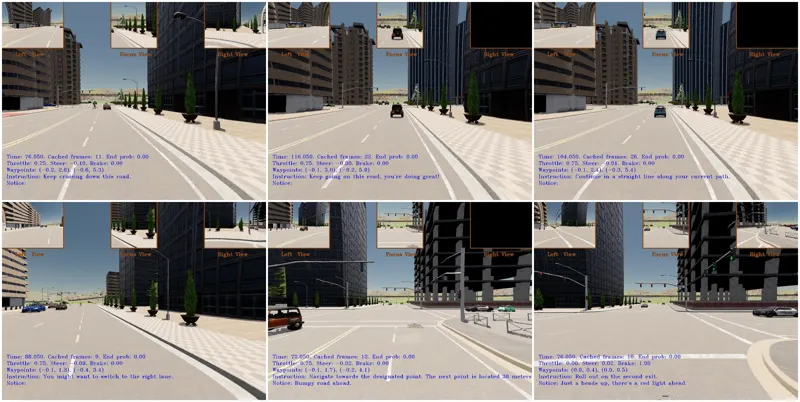
Large language models bring instruction following and scene reasoning to end-to-end driving, but their inference latency collides with the control rate a vehicle requires. Existing closed-loop agents hide this gap by invoking the model on alternate simulation ticks and replaying the previous command in between, so half of all control outputs ignore the newest observations. We present a fast-slow architecture that removes this compromise. A frozen 7B vision-language backbone acts as the slow system, digesting navigation instructions and visual history at low frequency while exposing its per-layer key-value cache as a standing representation of the scene. A lightweight action expert acts as the fast system, attending to this cache and to the current camera frame at every simulation tick to regress waypoints in a single forward pass. Since the cache lags behind the world at deployment, we train the expert under randomized staleness, aligning training with asynchronous execution. On LangAuto-Short routes in CARLA, our system produces fresh control at every 50 ms simulation tick and lifts route completion from 37.0 to 94.0 over the frame-skipping baseline. A frame-skip ablation with the same expert separates the two factors at work: the expert raises the driving score on its own, while per-tick freshness raises completion from 82.1 to 94.0 and cuts red-light violations by a third. Trained on a single town, the expert transfers zero-shot to two unseen towns, holding 84-94% route completion where the baseline reaches 31-41%. It reduces open-loop waypoint error by nearly a factor of four compared to the backbone's own action head, at a per-tick model cost of 32 ms that is independent of history length on a single consumer GPU.

Yun Li, Jiachen Gong, Simon ThompsonJul 17, 2026
Autonomous DrivingSimulationtestingJul 17, 2026
AEGIS: Assay-Aware Protocol Validation and Runtime Monitoring for Open-Source Liquid Handling Robots

AEGIS: Assay-Aware Protocol Validation and Runtime Monitoring for Open-Source Liquid Handling Robots

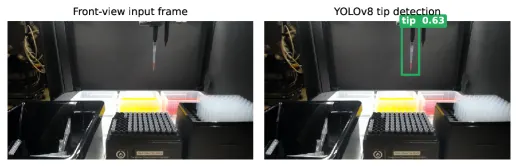
Self-driving laboratories increasingly rely on low-cost liquid handlers such as the Opentrons OT-2, which ship without the pressure-based aspiration monitoring of Hamilton or Tecan systems and are typically run open-loop. Two failure modes go undetected: protocols that are syntactically valid but violate assay-specific invariants (e.g., tip reuse between a PCR template and a no-template control), and physical execution failures (partial dispense, air bubbles, missing tips) at runtime. We present AEGIS, a two-layer guardian for both. Layer 1 pairs a curated machine-readable assay rule database with an LLM that reasons over OT-2 Python code, reaching an adjusted F1 of 0.97 on a 24-protocol benchmark across five assay families and beating rules-only and LLM-only ablations across five backends; a free open-weight model ties the best proprietary one, so no paid API is required. Layer 2 fits a PCA world model to YOLO-cropped four-frame pipette trajectories; under a leakage-free leave-one-plate-out evaluation it reaches average precision 0.89 and operating-point F1 0.71 (AUROC 0.80), a deployment-faithful number that matches the live demonstration, and we characterize the small-pipette (p20) resolution limit (F1 0.47). A live demonstration on a physical OT-2 (five replicates per condition) catches planted no-tip failures deterministically and partial dispense on coloured dyes, with an always-VLM self-vote gate lifting partial-dispense recall to 5/5; transparent water is a principled limit of any front-view-only monitor, which AEGIS surfaces as low-confidence VLM reasoning rather than a wrong verdict. Cascade triage holds VLM cost near $1.63 per plate versus $10.33 for an always-VLM baseline. AEGIS is open source and, to our knowledge, the first system to unify pre-flight assay-aware validation with runtime visual monitoring for an open-source liquid handler.

Priyanka V. Setty, Arvind Ramanathan, Ian FosterJul 17, 2026
Autonomous Drivingscenario generationResearchJul 17, 2026
ToolVerse: Unlocking Massive Environments and Long-Horizon Tasks for Agentic Reinforcement Learning

ToolVerse: Unlocking Massive Environments and Long-Horizon Tasks for Agentic Reinforcement Learning

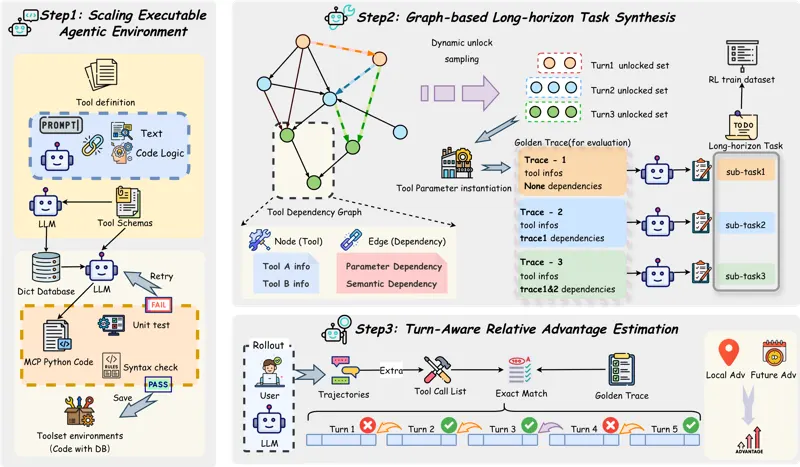
While LLM agents demonstrate strong reasoning abilities in compact and well-defined scenarios, they struggle to maintain robustness and effectiveness when faced with large-scale, diverse, and dynamic real-world environments that demand seamless tool integration. To address this gap, we introduce ToolVerse, a comprehensive framework that scales up agentic RL environments and enables agents to perform complex long-horizon reasoning in Tool-Integrated Reasoning (TIR) tasks. First, ToolVerse automatically builds the massive executable agent training environments from nearly 400 real-world Model Context Protocols (MCPs) that contain about 4500 tools. Second, we propose a task design strategy based on a tool dependency graph, utilizing Dynamic Unlocking Sampling Algorithm to generate long-horizon tasks, and produce GUST (Graph Unlocking Sampling Tasks) dataset. Third, to alleviate the credit assigment problem in long-horizon agentic RL, we propose a fine-grained Turn-Aware Relative Advantage algorithm. We conduct extensive Agentic RL training using ToolVerse and evaluate our framework on serveral agentic benchmarks. Experimental results demonstrate that our framework significantly strengthens LLMs' capabilities in long-horizon tool use, achieving a marked performance boost and showcasing robust reasoning within dynamic environments.

Shuaiyu Zhou, Fengpeng Yue, Zengjie HuJul 17, 2026
Autonomous DrivingDatasetsBenchmarksJul 17, 2026