Skip to content
SKooP: Symmetric Koopman Predictions for Faster and More Generalizable Legged Robot Locomotion with Reinforcement Learning

SKooP: Symmetric Koopman Predictions for Faster and More Generalizable Legged Robot Locomotion with Reinforcement Learning

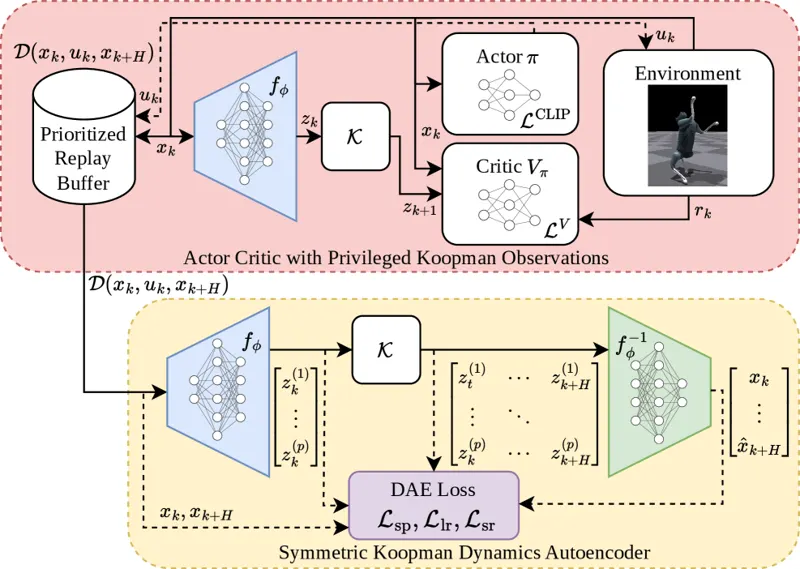
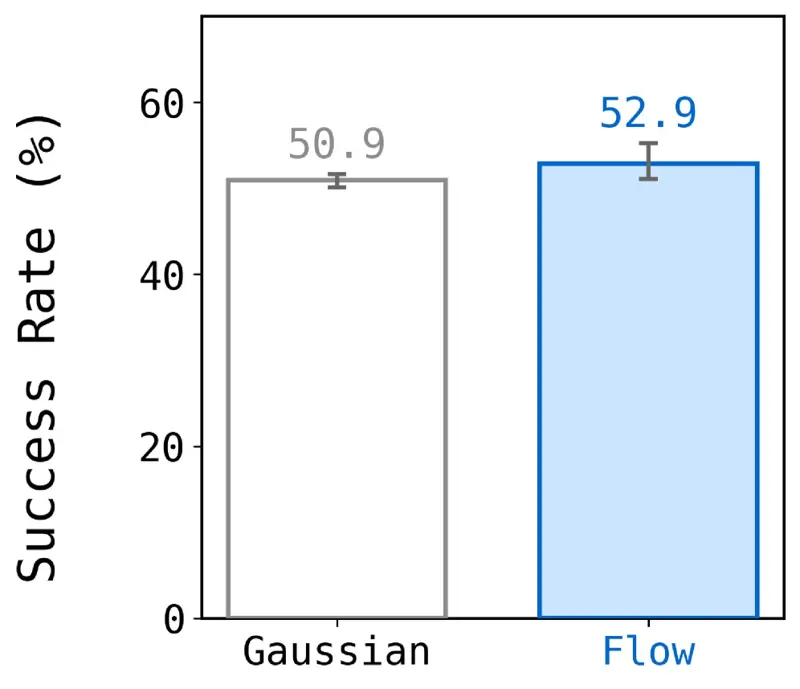
Reinforcement learning (RL) algorithms classically suffer from poor sample efficiency. In robotics, a recent line of work has emerged addressing this problem by encoding physics priors in the learning process. However, most of these approaches are validated on well-defined, low-dimensional benchmark systems rather than high-dimensional robots with complex nonlinear dynamics. In this paper, we introduce SKooP (Symmetric Koopman Predictions), an approach combining the advantages of morphological symmetries with those of a Koopman model learned via autoencoder to enhance policy learning. SKooP learns a Koopman model of the system dynamics alongside the policy. The resulting Koopman predictions are used as privileged observations for the critic, allowing the agent to learn based on smoother, more informative features. We also incorporate group symmetries into the actor, critic, encoder and decoder networks to produce a highly equivariant policy. The SKooP approach is validated via in-depth analysis of the learned Koopman models and symmetric policies to showcase how each of these influences the agent's performance. We also show that the learned policies are transferable to different simulation environments. Our results show that SKooP consistently reduces convergence time and increases the learned reward for multiple challenging bipedal locomotion tasks on a quadruped robot. Project page: https://evelyd.github.io/SymmetricKoopmanPredictions

KoopmanReinforcement Learning
Evelyn D'Elia, Weishu Zhan, Giulio Turrisi · 394 views · Jul 13, 2026
GaitSpan: Growing Humanoid Locomotion from Walking to Running

GaitSpan: Growing Humanoid Locomotion from Walking to Running

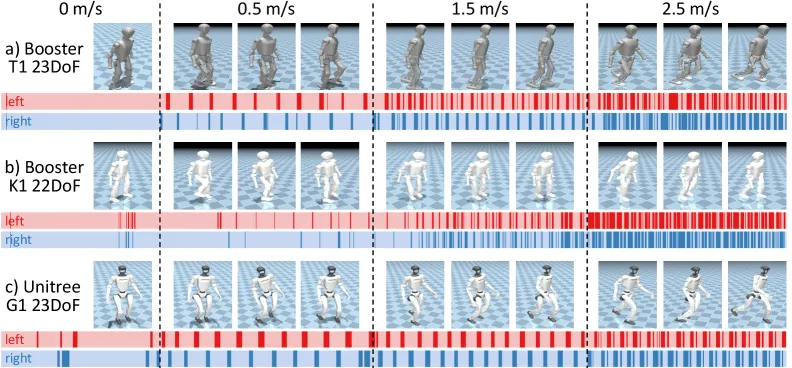
A humanoid that can walk should not relearn locomotion from scratch to jog or run. Yet current approaches often obtain gait diversity by prescribing gait schedules, imitating motion clips, training experts to switch between or distilling skills into one policy. These strategies can produce impressive behaviors, but offer limited flexibility across continuous speed commands, terrains, and morphologies. We study skill growth with GaitSpan, a framework that expands a pretrained, basic walking policy into faster locomotion. It treats walking as a seed skill: reusable motor structure for balance, support, body coordination, and contact transition that can be regenerated at new rhythms, extended into longer/higher strides, and corrected by residual adaptation. This expansion has three aspects: 1) rhythm generation, which modulates the frozen walking policy with multiple internal clocks and learns command-conditioned combinations of the resulting canonical actions; 2) stride shaping, which rewards dynamic locomotion patterns appropriate for higher commanded speeds using a physically grounded objective inspired by spring-loaded inverted pendulum dynamics; and 3) residual adaptation, which captures motion details not accounted for by rhythm generation or stride shaping. GaitSpan is the first to deliver a single command-conditioned humanoid policy that spans walking, jogging, and running-like regimes covering a continuous speed range, transfers across morphologies, and deploys zero-shot on unseen sim-to-sim, and real-world terrains. Compared with baselines either trained with multi-experts or imitation from humans, it learns faster and achieves stronger gait performance.

HumanoidGait
Kwan-Yee Lin, Zilin Wang, Janelle J. Liu · 421 views · Jul 13, 2026
Learning Reusable Hybrid Motion Priors for Humanoid Locomotion from Motion Imitation

Learning Reusable Hybrid Motion Priors for Humanoid Locomotion from Motion Imitation

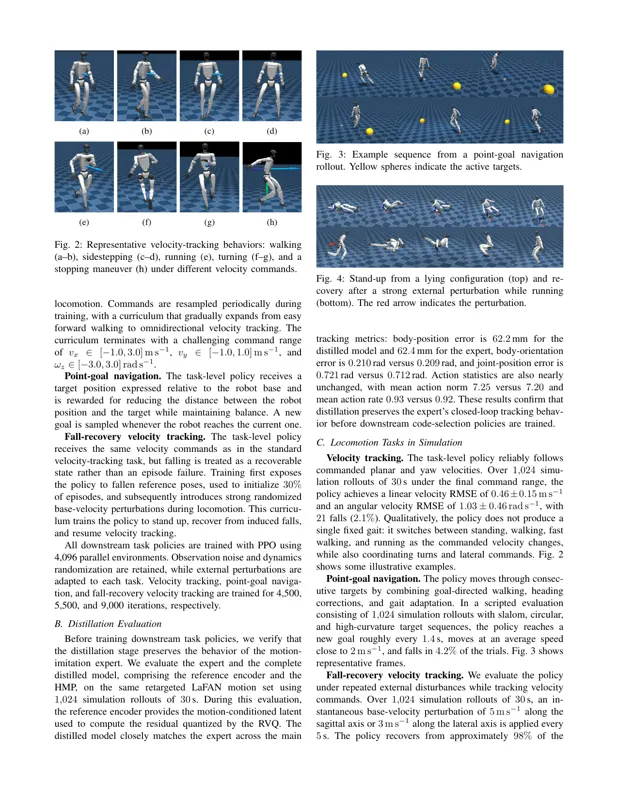
Reinforcement learning can produce robust humanoid controllers, but each new task is typically trained as a separate policy with its own reward design and training process. Motion imitation provides an alternative source of motor competence by training policies to track retargeted human motions, yet the resulting controllers remain reference trackers and are not directly usable as task policies. We propose a three-stage pipeline that turns motion-imitation skills into a reusable hybrid motion prior (HMP) for humanoid locomotion. First, an expert policy is trained to imitate retargeted human motion-capture clips. Second, the expert is distilled into a frozen architecture composed of a proprioceptive encoder, a residual vector-quantized (RVQ) codebook, and an action decoder. Third, task-level policies are trained to solve locomotion tasks by selecting discrete codebook entries while the HMP remains frozen. We evaluate the method on velocity tracking, point-goal navigation, and fall-recovery velocity tracking in simulation, and deploy the velocity-tracking policy on a real Unitree G1 robot. The distillation process preserves the tracking behavior of the expert, while the resulting HMP can be reused without retraining as the action interface for different downstream locomotion policies. The learned HMP reveals an interpretable codebook structure in which the number of active RVQ stages modulates the available gait patterns. We further show that training the codebook with the rotation trick improves latent organization and reduces downstream falls compared with a standard straight-through estimator.

Motion ImitationHumanoid
Valerio Belli, Valerio Modugno, Enrico Mingo Hoffman · 384 views · Jul 27, 2026
Closing the Loop in Humanoid VLA: Persistent 3D Object Tokens for Verifiable Loco-Manipulation

Closing the Loop in Humanoid VLA: Persistent 3D Object Tokens for Verifiable Loco-Manipulation

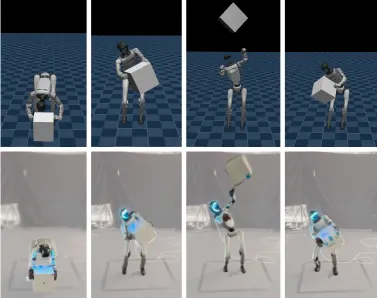
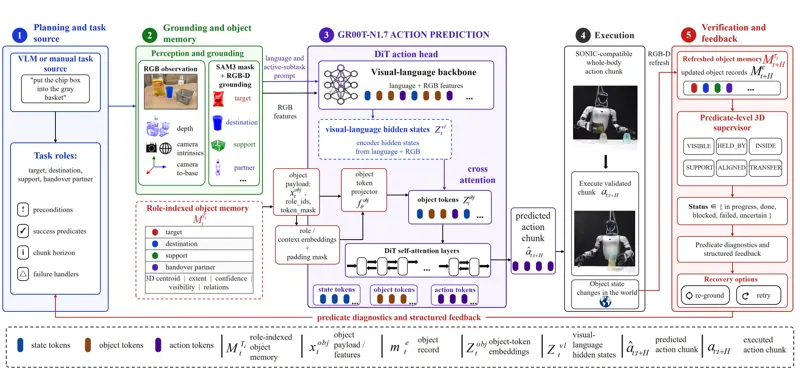
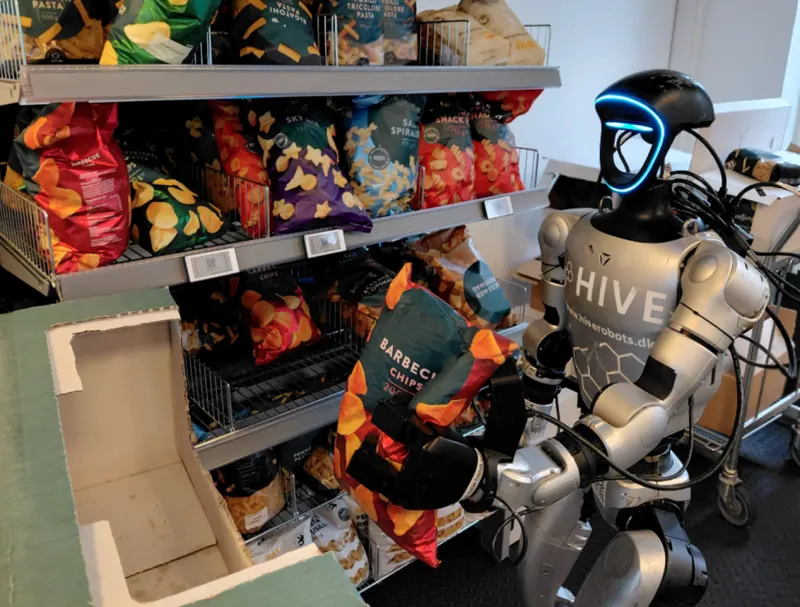
Vision-language-action policies are a promising foundation for general robot control, but long-horizon humanoid loco-manipulation requires the robot to treat task objects as persistent physical entities across movement, contact, occlusion, and recovery. We study this problem as object-state divergence: the object state used to condition a whole-body action can differ from the state used to decide whether the action achieved the intended physical relation. We propose Persistent Object Tokenization (POT), which maintains role-indexed 3D object records from RGB-D observations and converts them into object tokens for a whole-body action expert. Instantiated as POT-VLA, the same object records condition action generation and support geometric predicate checks, yielding a closed-loop execution system in which object state is both actionable and verifiable. On a Unitree G1, POT-VLA improves a matched direct GR00T-N1.7 baseline from 39/80 to 71/80 successes over eight real-world task families. In an external Being-0-aligned reference, POT-VLA achieves 44/50 successes on aligned service tasks, compared with the 37/50 success reported by the Being-0 paper. The largest gains occur on tasks requiring maintained 3D relations, suggesting that persistent object-centered state is a useful abstraction for verifiable humanoid VLA execution.

VLARGB-D
Peng Ren, Haoyang Ge, Jiang Zhao · 645 views · Jul 20, 2026
PRISM: Polynomial Representations for Interaction-Structured Motor Control

PRISM: Polynomial Representations for Interaction-Structured Motor Control

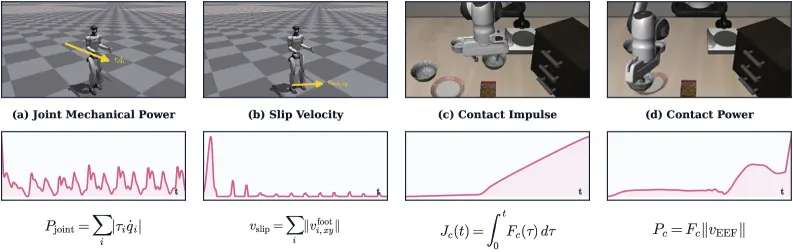
Robot policies are typically MLPs mapping observations to actions. Yet robot observations are physical variables, and many action-relevant cues arise not from individual variables but from their interactions; power, inertial effects, contact, slip, and compliance depend on products among observable signals. We introduce PRISM, a policy representation that makes polynomial interactions among observable physical variables explicit, learnable, and compact. Rather than listing all polynomial terms, PRISM uses a factorized polynomial module to expose higher-order interaction features efficiently. In reinforcement learning, it keeps the standard MLP backbone but applies a gradually activated element-wise polynomial function after it. In imitation learning, it replaces linear proprioceptive conditioning in Diffusion Policy with a polynomial layer trained end-to-end. Across humanoid locomotion and contact-rich manipulation, PRISM improves performance over standard MLP policies and larger MLPs with matched capacity, showing that interaction structure cannot be replaced by capacity alone. It also yields sensorless compliant behavior without force, wrench, tactile input, contact labels, or admittance control. These results suggest that polynomial representations should become a standard architectural choice for embodied motor control. The project page is available at https://lsh3163.github.io/prism/

PrismMotion Control
Seung Hyun Lee, Stella X. Yu · 453 views · Jul 26, 2026
Extreme-RGMT: Continual Learning of Highly Dynamic Skills for Robust Generalist Humanoid Control

Extreme-RGMT: Continual Learning of Highly Dynamic Skills for Robust Generalist Humanoid Control

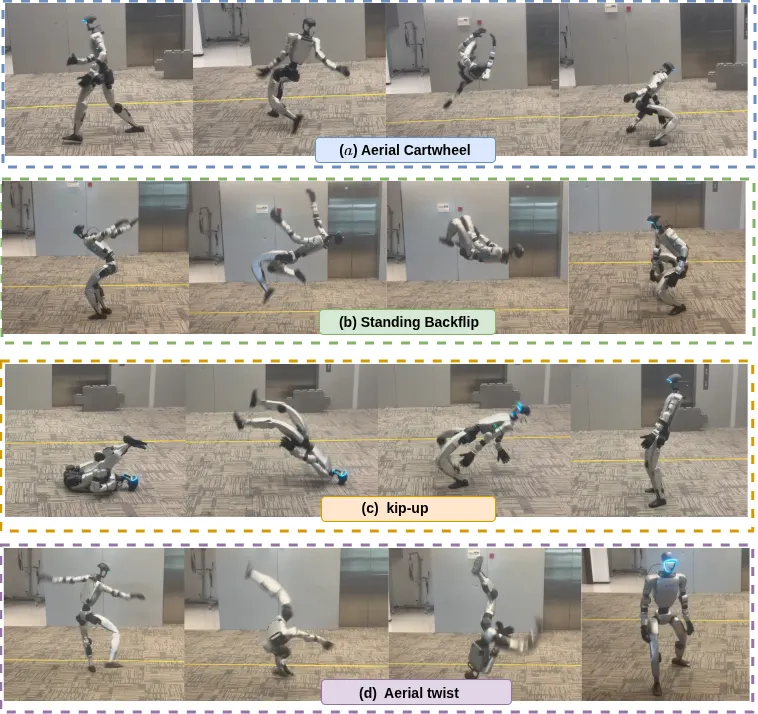
Humans can progressively acquire highly dynamic motor skills while preserving reliable everyday motor abilities. In contrast, existing humanoid controllers face a trade-off between generalist and specialist capabilities: generalist motion tracking policies struggle to reliably execute rare highly dynamic motions, whereas specialist training can degrade previously acquired behaviors. We introduce Extreme-RGMT, a two-stage continual learning framework for robust generalist humanoid control. The method first learns a generalist motion-tracking base policy from diverse multi-source motion data, then employs an asymmetric skill acquisition and capability consolidation mechanism to constrain policy drift on mastered motions while emphasizing difficult dynamic segments. To address the scarcity of highly dynamic motions, their high failure rates, and the resulting shortage of informative samples, Extreme-RGMT combines difficulty-aware sampling with advantage-prioritized trajectory resampling to emphasize critical segments. Experiments show that Extreme-RGMT achieves state-of-the-art generalist whole-body motion-tracking performance, including substantially improved completion of challenging highly dynamic motions. The resulting controller directly executes diverse unseen highly dynamic motions under fixed references and online inertial motion-capture inputs, advancing generalist whole-body motion-tracking controllers toward highly dynamic motor capabilities at the human-expert level.

HumanoidContinual learning
Yubiao Ma, Han Yu, Kai Guo · 469 views · Jul 22, 2026

As an Amazon Associate, we earn from qualifying purchases.