Skip to content
Tac4Loco: Learning Spatiotemporal Plantar Pressure Representations for Humanoid Locomotion

Tac4Loco: Learning Spatiotemporal Plantar Pressure Representations for Humanoid Locomotion

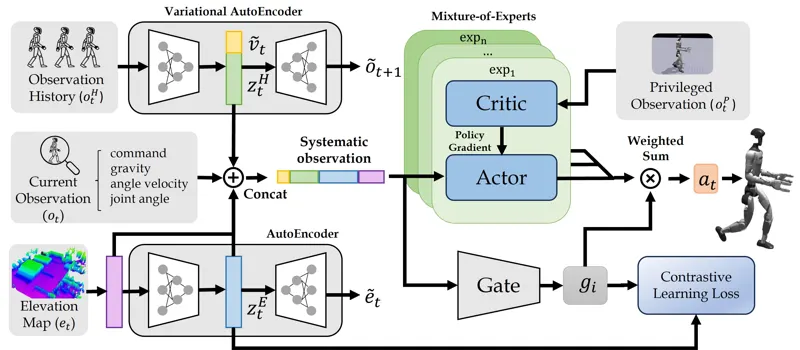
Humanoid robots are expected to traverse complex terrains, where the plantar support may vary dramatically due to foot placement errors, ground properties, and transient dynamics. To achieve robust locomotion, the robots are required to adapt to uneven terrain and uncertain foot–ground interactions. Existing locomotion policies rely primarily on proprioception or exteroceptive terrain perception, where the former provides only indirect evidence of plantar support, while the latter predicts contact conditions before touchdown but cannot observe the actual support in real-time. Although some studies incorporate plantar contacts as an auxiliary perception, they rely mainly on summary statistics, overlooking the spatial topology of plantar pressure, which provides a more direct characterization of the realized contact state. To bridge this gap, we present Tac4Loco, a tactile-perceptive framework that incorporates multi-array plantar pressure as direct feedback for humanoid locomotion. We formulate a topology-preserving ordinal representation to map simulated and physical sensor signals into a shared observation space, with a dual-branch encoder for extracting their spatial and temporal representations. Subsequently, the learned spatiotemporal features are integrated with augmented proprioception including terrain estimation cues, and provided to an asymmetric actor-critic architecture for policy learning. Extensive simulation and real-world experiments demonstrate improved tracking performance and support adaptation on terrains with inclined, partial, asymmetric, and changing support. We further demonstrate its zero-shot deployment on unseen compliant and unstructured terrains, including a foam platform and a gravel road. All code and experimental configurations will be released as open-source to facilitate reproducibility.

Tac4LocoLocomotion
Ziyun Liu, Sikai Guo, Zheng Li · 619 views · Aug 16, 2026
HAF: Adapting Generalist VLAs to Humanoid Whole-Body Loco-manipulation via Hierarchical Action Flow and Spectral Latent RL

HAF: Adapting Generalist VLAs to Humanoid Whole-Body Loco-manipulation via Hierarchical Action Flow and Spectral Latent RL

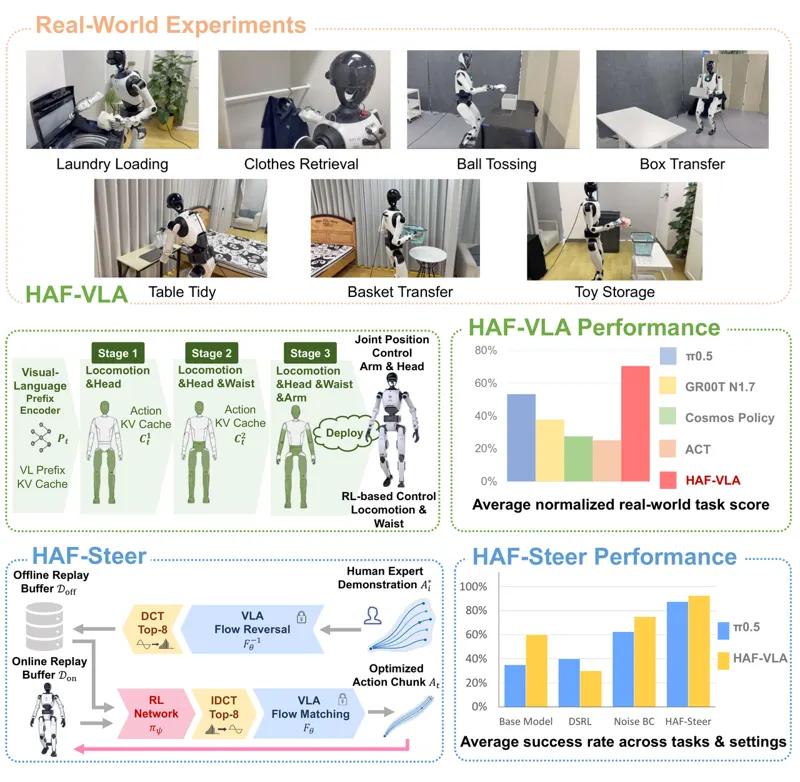
Humanoid robots hold great promise as general-purpose agents in human-centered environments, yet generalist vision-language-action (VLA) foundation models are not readily applicable to humanoid whole-body loco-manipulation. The high dimensionality and interdependence of humanoid motions make it challenging for conventional single-stage VLA architectures to coordinate locomotion, waist posture, and dual-arm manipulation effectively. Moreover, policies trained through offline behavior cloning can remain suboptimal during real-world deployment. Although online reinforcement learning can refine policies through real-world interaction, directly tuning large VLA backbones demands excessive computation and may introduce safety risks during real-robot exploration. To address these bottlenecks, we introduce HAF (Humanoid Adaptation Framework), a two-part framework consisting of HAF-VLA and HAF-Steer that transfers off-the-shelf generalist VLA foundation models to humanoid whole-body loco-manipulation. HAF-VLA is a hierarchical action-flow generator built on a pretrained flow-matching VLA. It splits full-body action denoising into three sequential stages with stage embeddings and cross-stage KV caches that retain kinematic dependencies, avoiding incoherent whole-body actions from one-shot generation. On top of the frozen HAF-VLA, HAF-Steer is a latent offline-to-online RL pipeline that leverages flow-matching invertibility and DCT-based dimensionality reduction to restrict RL optimization to a compact noise subspace and train a regularized SAC policy. This avoids updating the large VLA backbone and enables efficient real-world policy refinement. Evaluated on seven real-world humanoid loco-manipulation tasks, HAF surpasses vanilla single-stage VLA baselines and improves whole-body coordination and task performance. Project website: https://grange007.github.io/HAF .

VLAHumanoid
Langzhe Gu, Chengkai Hou, Meng Li · 702 views · Aug 17, 2026
Light-Loco-Parkour: Versatile Perceptive Whole-Body Locomotion via Multi-Skill Distillation

Light-Loco-Parkour: Versatile Perceptive Whole-Body Locomotion via Multi-Skill Distillation

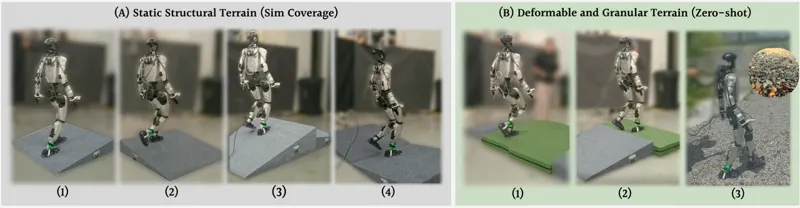
Existing humanoid whole-body control systems still fall short of the way humans move through cluttered terrain: they either track expressive whole-body references without terrain generalization, or react to terrain online while leaving the arms, torso, and knees largely unused. We present Light-Loco-Parkour (LLP), an end-to-end perceptive whole-body locomotion system that closes this gap with a single deployable policy. Conditioned only on onboard depth and a velocity command, the policy decides when to walk, balance, climb, step down, or vault, with no reference input, skill label, hand-coded gate, or runtime motion graph. Compared with prior humanoid systems, LLP makes three contributions. First, it introduces a whole-body perceptive-control pipeline that extends an RL-trained, velocity-tracking locomotion policy with parkour skills learned from object-interacting motions, so the same policy tracks velocity in open terrain, executes whole-body traversal at obstacles, and resumes locomotion afterward. Second, it acquires terrain-conditioned skills from sparse seeds by expanding a single motion into dynamically feasible, terrain-paired references across obstacle geometry, rather than relying on a large motion corpus. Third, it learns autonomous skill transitions from reward, letting the policy decide when and which whole-body skill to invoke from depth and command alone, with no one-hot skill label, hand-coded state machine, or runtime motion generator. Simulation and real-world experiments show high success across both benchmarked terrains and unseen obstacle variations, and the same policy transfers zero-shot to indoor and outdoor hardware experiments. These results demonstrate autonomous perceptive whole-body locomotion on a humanoid in outdoor settings, using only onboard sensing and a single deployable policy.

RLHumanoid
Hongming Chen, Zhuoran Li, Hongxi Wang · 547 views · Aug 1, 2026

As an Amazon Associate, we earn from qualifying purchases.