Skip to content
LEGS: Fine-Tuning Teleop-Free VLAs for Humanoid Loco-manipulation in an Embodied Gaussian Splatting World

LEGS: Fine-Tuning Teleop-Free VLAs for Humanoid Loco-manipulation in an Embodied Gaussian Splatting World

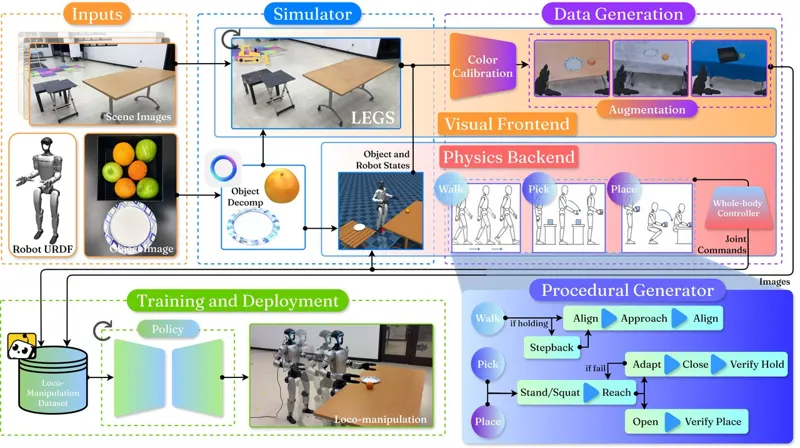
Training vision-language-action (VLA) policies for humanoid loco-manipulation is constrained by the high cost and complexity of collecting human teleoperation demonstrations. VLA policies fine-tuned in simulators have, until now, failed to transfer effectively in humanoid loco-manipulation tasks. We present LEGS (Loco-manipulation via Embodied Gaussian Splatting), a hybrid simulator that composites a mesh foreground (robot, objects, props) over a photorealistic 3D Gaussian Splatting (3DGS) background reconstructed from a handheld scene capture. LEGS uses a procedural motion-primitive generator to synthesize labeled demonstrations at scale without human teleoperation, and a deterministic two-stage color calibration to align the rendered 3DGS image to the robot's deployment camera. On a Unitree G1 humanoid robot, across three pick-and-place tasks of increasing whole-body difficulty and three VLA backbones (psi_0, pi_0.5, GR00T N1.6), a policy trained purely on LEGS data matches or exceeds one trained on human teleoperation demos on every experiment. It also outperforms a mesh-only simulation baseline that ablates the effect of the 3DGS background, showing that photorealistic rendering is a key enabler for synthetic data transfer. Humanoid motion is recorded independently of scene appearance in LEGS, allowing the same auto-generated demonstrations to be re-rendered under new backgrounds and object meshes–covering a new scene at more than 15x lower cost than teleoperation–to augment training data for robustness to scene variations. Under combined object-and-scene appearance shift, the policy trained on re-rendered LEGS-AUG data maintains task success while the baseline trained on teleoperation data fails entirely. Our project page is located at https://legsvla.github.io/.

HumanoidVLA
Kim, Hojune, Chen, Timothy, Sun, Jiankai · 1k views · May 31, 2026
FADA: Few-Shot Domain Adaptation via Dynamics Alignment for Humanoid Control

FADA: Few-Shot Domain Adaptation via Dynamics Alignment for Humanoid Control

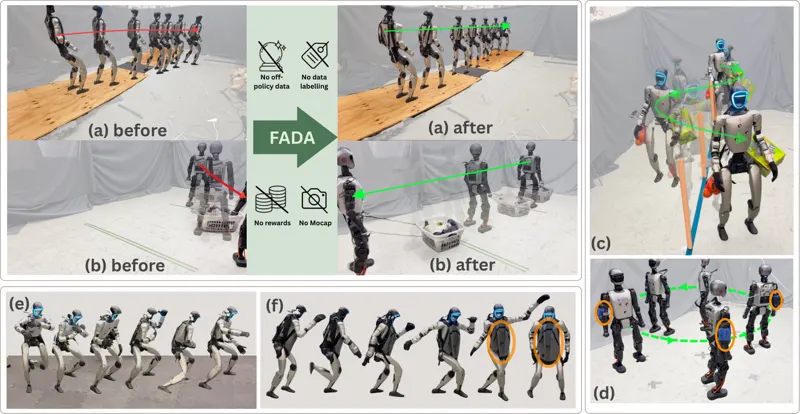
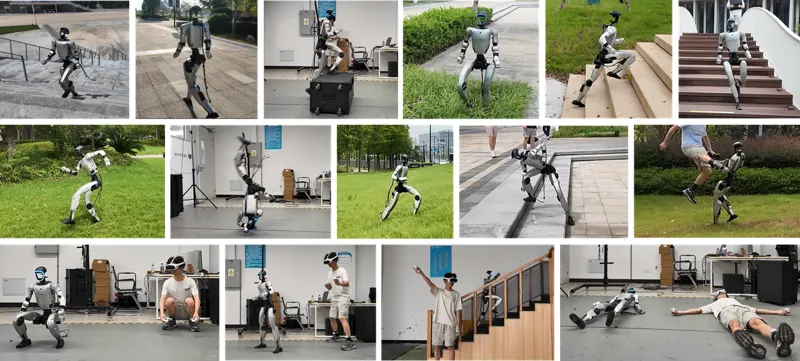
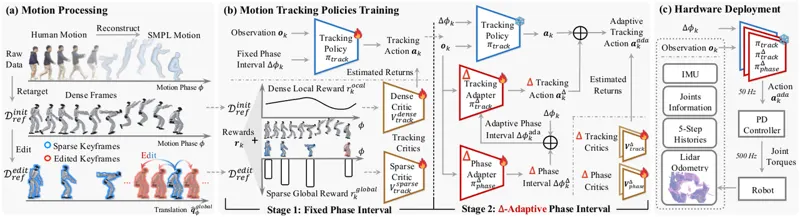
High-precision humanoid control is limited by target-domain dynamics mismatch, where the same control objective can induce different realized motions under changes in terrain, payload, or actuator response. Existing methods either pursue zero-shot transfer through domain randomization or in-context adaptation without target-domain specialization, or require heavy adaptation pipelines that leverage target-domain data, such as model calibration, residual learning, or policy retraining. In this paper, we present FADA (Few-Shot Domain Adaptation via Dynamics Alignment), a three-stage Planner-Inverse Dynamics Model (Planner-IDM) framework for few-shot adaptation in humanoid control. FADA first trains an oracle policy with privileged information and then distills the oracle behavior into a deployable Planner-IDM student through DAgger. At deployment, FADA freezes the planner and finetunes only the IDM using approximately 2 minutes of target-domain rollouts with standard supervised learning. Rather than requiring optimal demonstrations or rewards, FADA uses the paired actions and observations that are observed during these rollouts as supervision, aligning the IDM's action generation with target-domain dynamics. Experiments show that FADA outperforms both in-context and end-to-end adaptation baselines, improving task performance under dynamics shifts and enabling real humanoid robots to execute diverse high-precision whole-body tasks. Implementation details and qualitative hardware rollout videos are available at https://lecar-lab.github.io/FADA-humanoid/.

HumanoidFew-Shot Learning
Angchen Xie, Nikhil Sobanbabu, Ishayu Shikhare · 591 views · Jun 26, 2026
TANGO: Humanoid Navigation in Cluttered Environments with a Whole-Body Vision-Language-Action Model

TANGO: Humanoid Navigation in Cluttered Environments with a Whole-Body Vision-Language-Action Model

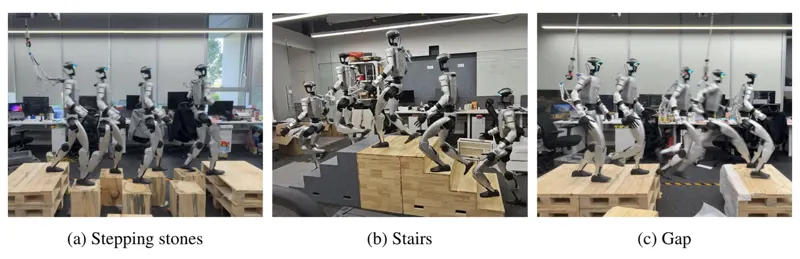
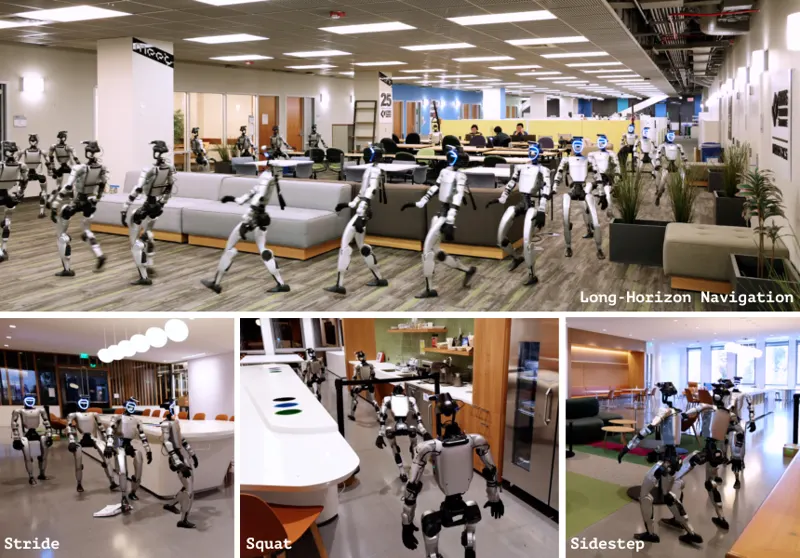
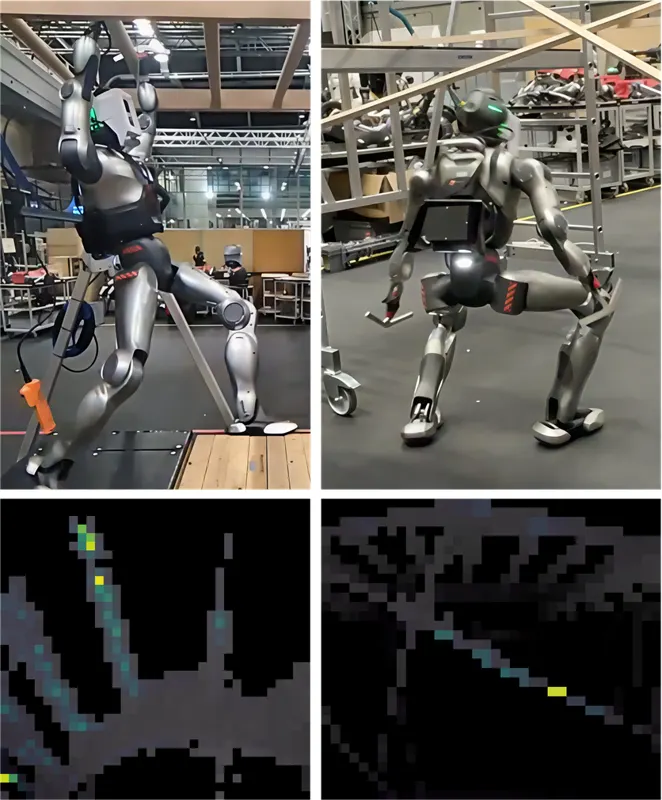
We study the problem of navigating cluttered indoor environments with a humanoid robot. Unlike conventional methods that model navigation as a 2D path planning problem, humanoid traversal in cluttered environments requires continuous geometry-aware whole-body adaptation, including coordinated arm placement, torso adjustment, and gait modulation for collision-free movement through complex 3D spaces. We introduce TANGO, the first whole-body vision-language navigation framework for language-conditioned humanoid traversal in cluttered environments. Given a natural-language instruction and egocentric RGB observations, TANGO directly predicts 29-DoF joint-space actions for downstream whole-body control. We train TANGO entirely in simulation by synthesizing diverse collision-free traversal behaviors via global path planning, kinematic whole-body motion generation, obstacle-aware motion editing, and RL-based tracking. This pipeline provides dynamically feasible action supervision for learning language-conditioned whole-body policies. In extensive simulation experiments, TANGO demonstrates state-of-the-art performance in vision-language navigation, while outperforming strong modular baselines in navigating challenging scenes requiring obstacle negotiation. Lastly, we deploy TANGO zero-shot on a Unitree G1 humanoid robot, and observe robust language-guided traversal in cluttered real-world scenes without training on any real-world navigation data.

HumanoidVLA
Anqi Li, Yuxin Chen, Zhaobo Li · 1.1k views · Sep 8, 2026

As an Amazon Associate, we earn from qualifying purchases.