Skip to content
Thinker-WM: A Unified World Model with Shared Multimodal Representations for Embodied Intelligence

Thinker-WM: A Unified World Model with Shared Multimodal Representations for Embodied Intelligence

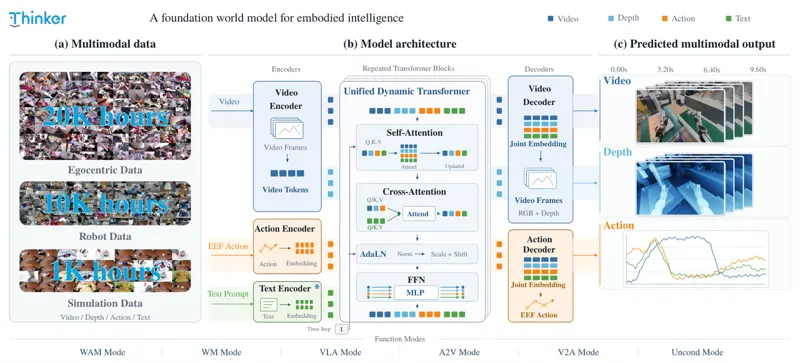
World models have emerged as a promising paradigm for embodied AI, yet existing systems often remain fragmented in the modalities they model and the functions they support. In particular, visual dynamics, geometric structure, and executable action are commonly coupled through separate interfaces or downstream modules rather than being jointly represented and evolved within a shared dynamics model. In this work, we present Thinker-WM, a unified multimodal world model that jointly models and generates RGB, metric depth, and robot action through a shared intermediate Unified Dynamics Transformer with modality-specific encoders and decoders. The model performs multimodal unification at the representation level: appearance, geometry, and action are transformed into a common dynamic representation and jointly evolved by shared parameters, while their distinct output structures are preserved. The same parameterization supports multiple functions, including joint video-action generation, world prediction, policy inference, action-conditioned generation, video-to-action generation, and inverse dynamics. To examine whether the shared representation captures action-related information, we introduce a lightweight motion probe that shows the frozen visual representation contains recoverable motion information. Thinker-WM is trained on a heterogeneous corpus comprising approximately 20K hours of egocentric video, 10K hours of real-robot data, and 1K hours of simulation data, including approximately 4K hours of real-robot data with aligned depth supervision. Extensive experiments demonstrate strong performance across embodied world-model evaluations. Thinker-WM ranks first on EWMBench, WorldOlympiad and WorldArena, while controlled studies further demonstrate the benefits of action conditioning, geometric interaction, and multi-function training within the shared representation.

World ModelsEmbodied AI
Thinker Team, Peng Gao, Jichao Jiao · 285 views · Oct 13, 2026
EWAM: Emergent Depth-Wise Specialization in a Unified Embodied Model – From Semantic Understanding through Visual Foresight to Action

EWAM: Emergent Depth-Wise Specialization in a Unified Embodied Model – From Semantic Understanding through Visual Foresight to Action

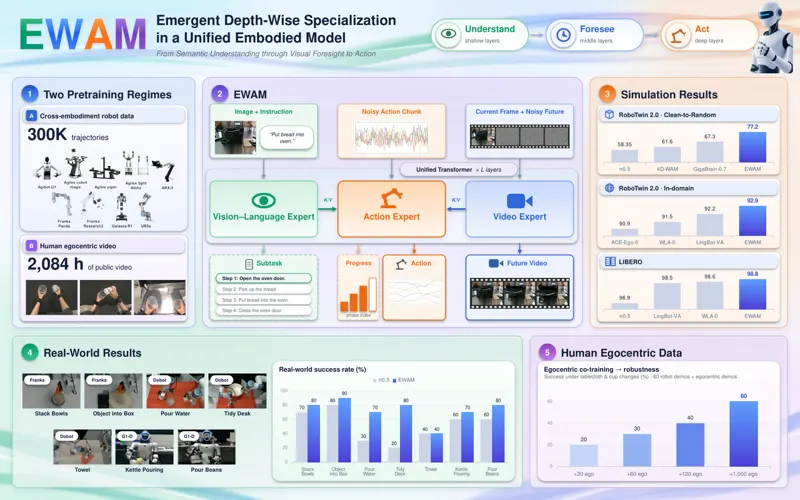
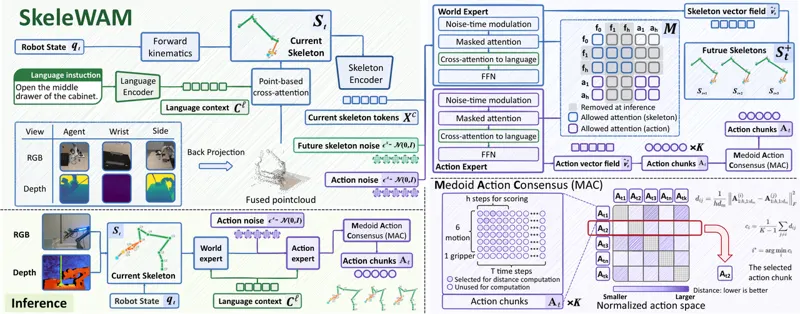
Vision-language-action (VLA) policies emphasize semantic understanding, whereas world-action models (WAMs) learn predictive representations of environment dynamics. Systems that expose a policy to both sources often still concentrate action computation on a single expert. We present EWAM, an action-centric unified embodied model whose asymmetric joint attention lets action tokens read semantic, current-visual, predicted-future, and action information at every layer while the perceptual experts retain their distinct roles. Without layer-wise supervision, EWAM develops an emergent depth-wise specialization: action queries attend mainly to vision-language features in shallow layers, to predicted future frames in intermediate layers, and to action tokens themselves in deep layers. This handoff replicates across tasks and is stable across denoising steps. Checkpoint tracking and causal interventions show that it is learned and that action generation depends on it. EWAM is pretrained in two separate regimes, one on cross-embodiment robot trajectories and one on human egocentric video. In simulation and real-robot experiments, it surpasses existing VLA, WAM, and hybrid baselines. Human egocentric data improve both cross-embodiment transfer and real-robot robustness, and subtask-phase supervision improves long-horizon completion. Together, these results suggest that unified embodied learning can induce an ordered internal progression from semantic understanding, through visual foresight, to action formation.

VLAWorld-action models
Hao Wang, Jiajun Wen, Jingzhi Liu · 212 views · Sep 30, 2026
VT-Bridge: Bridging Pretrained Foundation VLAs to VTLAs via Lightweight Residual Adaptation

VT-Bridge: Bridging Pretrained Foundation VLAs to VTLAs via Lightweight Residual Adaptation

Vision-Tactile-Language-Action (VTLA) models have demonstrated clear advantages over Vision-Language-Action (VLA) models in contact-rich manipulation. However, developing VTLA models is severely constrained by the massive amounts of vision-tactile data and computational resources required. To address this bottleneck, we propose VT-Bridge, a lightweight residual adaptation strategy that bridges pretrained foundation VLAs to VTLAs. Rather than training a VTLA model from scratch or modifying the original architecture of a pretrained VLA, VT-Bridge employs an identical lightweight residual-adapter architecture across VLA backbones and uses backbone-specific weights to refine actions at the robot execution frequency. This design substantially lowers the data and training barriers. Specifically, it requires up to 50 vision-tactile demonstrations per task to fine-tune a VLA backbone and train a 0.98M-parameter residual adapter. Experiments with three representative VLA backbones (π₀, π_0.5, and SmolVLA) across four contact-rich manipulation tasks further demonstrate its consistent effectiveness across VLA architectures. On average, VT-Bridge raises the task completion rate from 11.7% with task-level VLA fine-tuning alone to 62.9%. Together, these findings demonstrate the broad applicability, effectiveness, and accessibility of VT-Bridge for contact-rich manipulation. The project page is available at https://hoxnocha.github.io/vt-bridge-web/.

Tactile SensingVLA
Yansong Wu, Tuo Yang, Rongping Zhao · 315 views · Sep 18, 2026
TacitVLA: Reasoning Vision-Language-Action Models Without Reasoning Latency

TacitVLA: Reasoning Vision-Language-Action Models Without Reasoning Latency

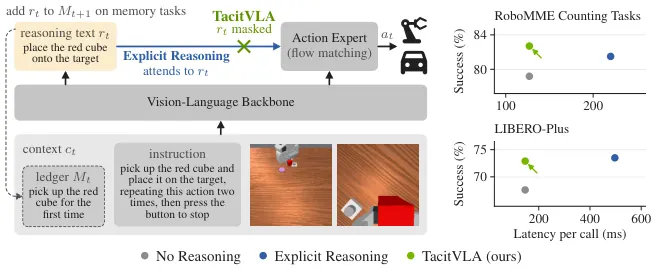
Textual reasoning before acting has improved vision-language-action (VLA) models, but at the cost of latency: every action conditioned on the reasoning text must wait for autoregressive decoding. We show that actions do not need to wait for or condition on the generated reasoning to benefit from it, because the reasoning supervision already improves the backbone representation. We introduce TacitVLA, a reasoning VLA whose action expert never attends to the reasoning it generates for the current call. On long-horizon tasks where the reasoning text also serves as episodic memory, it can generate each entry during action execution rather than before acting. We evaluate it in a controlled study on four benchmarks spanning manipulation and autonomous driving, memory and non-memory tasks: RoboMME, RMBench, LIBERO, and PhysicalAI-AV. On all four, TacitVLA matches the performance of its explicit-reasoning counterpart at up to 3.4x lower latency, and matches the latency of the same architecture trained without reasoning at up to +17.1% success. In absolute terms, it surpasses the best previously published results on the RoboMME Counting suite (82.7% vs. 66.8%) and RMBench (77.5% vs. 56.5%), and reaches 72.9% on LIBERO-Plus and a 52.5% scene score on the public split of the PhysicalAI-AV closed-loop driving challenge. Project page: https://tacitvla.github.io.

VLAEmbodied Reasoning
Jack Lu, Yurong You, Boyi Li · 514 views · Oct 13, 2026
Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models

Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models

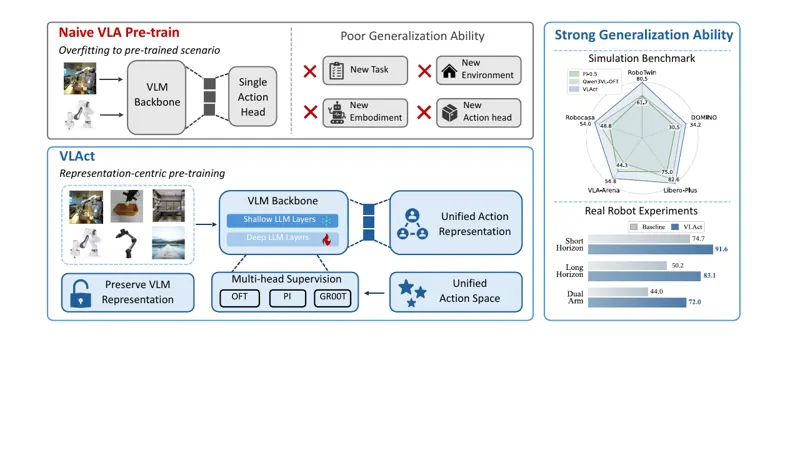
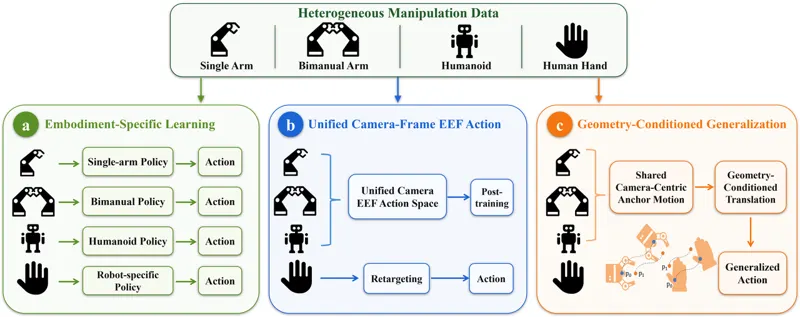
Scaling robot data is crucial for building generalist Vision-Language-Action (VLA) models, yet robot trajectories are harder to scale than web-scale image-text data because embodied collection is costly and sparsely covers the physical world. This makes representation quality a central bottleneck: under a fixed robot-data budget, continued pre-training must turn limited trajectories into transferable visual-action knowledge rather than merely fit actions. We propose VLAct, a VLA-oriented VLM backbone trained on broad, heterogeneous, multi-embodiment robot data before task-specific fine-tuning. VLAct preserves the broad VLM prior and encourages shared action semantics across embodiments through VLM-prior preservation, multi-head continuous action co-supervision, and a partially unified cross-embodiment action layout, while allowing task-specific action heads during fine-tuning. Across simulation, real-world, and unseen-embodiment transfer, VLAct consistently improves downstream performance under fixed fine-tuning protocols. On LIBERO-Plus and RoboTwin 2.0, VLAct surpasses industrial VLA systems including ABot-M0 and LingBot-VLA, achieving success rates of 82.6% and 92.5%. On RoboDojo, VLAct ranks sixth among all policies by success rate and outperforms all explicitly designated world-action model (WAM) entries on both metrics. Most notably, on RoboCasa-GR1, an unseen humanoid embodiment, VLAct using only 20% of downstream trajectories outperforms the full-data GR00T-N1.6 baseline. These results are obtained using fully open-source data and only a 16-GPU training setup, showing that representation-centric continued pre-training can deliver highly competitive performance under a modest compute budget and is an important independent axis of VLA progress beyond data scaling.

VLAContinued Pre-training
Senqiao Yang, Chengyao Wang, Yuxin Chen · 401 views · Aug 27, 2026
MachEmbodied-U0: Unified Understanding and Generation Model for Embodied Intelligence

MachEmbodied-U0: Unified Understanding and Generation Model for Embodied Intelligence

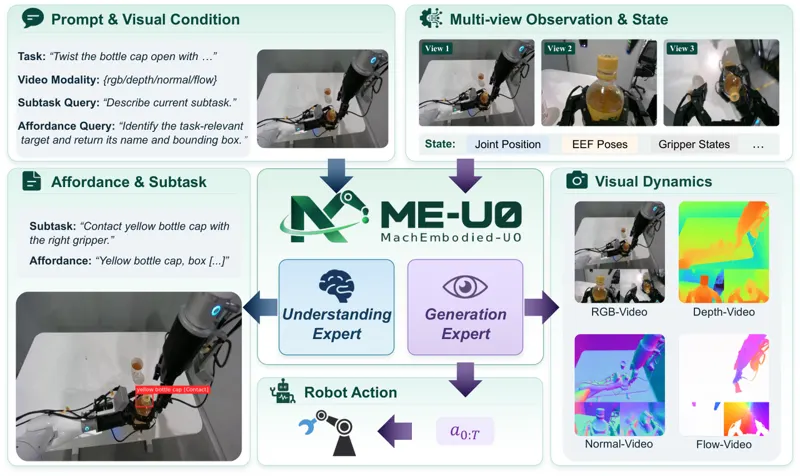
General-purpose robot control requires models to understand task intent, identify where to interact, capture how the scene evolves, and generate precise actions. Vision-language-action models provide strong semantic priors but typically do not explicitly model scene dynamics, while world-action models couple visual prediction with control without necessarily exposing the task-relevant semantic and spatial structure needed for fine-grained manipulation. We present MachEmbodied-U0 (ME-U0), a unified embodied foundation model connecting understanding and generation experts through a Mixture-of-Transformers architecture. Subtask prediction and affordance grounding guide joint visual-dynamics and action generation via flow matching. Visual dynamics encompass future RGB, depth, surface normals, and optical flow, providing complementary supervision for appearance, geometry, and motion. Multi-rate Rotary Position Encoding (MRPE) aligns visual dynamics with fine-grained control. We pretrain ME-U0 on approximately 4,200 hours of curated demonstrations from robotic datasets and egocentric datasets. Using only the supervision natively available in each downstream benchmark, ME-U0 achieves an average score of 17.66 on the RoboDojo simulation benchmark and average success rates of 99.0% and 82.5% on LIBERO and LIBERO-Plus, respectively. We additionally validate ME-U0 on real-world robotic manipulation tasks, demonstrating its effectiveness beyond simulation. Without corresponding downstream supervision, ME-U0 further demonstrates zero-shot subtask prediction, affordance grounding, and visual dynamics on simulated and real-world observations. Overall, ME-U0 combines competitive downstream control performance with transferable task-grounding and visual-dynamics capabilities across simulation and the real world.

MachEmbodiedME-U0
Wen, Haoran, Wang, Wenfu, Shi, Kunsong · 1.1k views · Sep 22, 2026

As an Amazon Associate, we earn from qualifying purchases.