VideoJev: System One Model for Video Understanding and Interaction
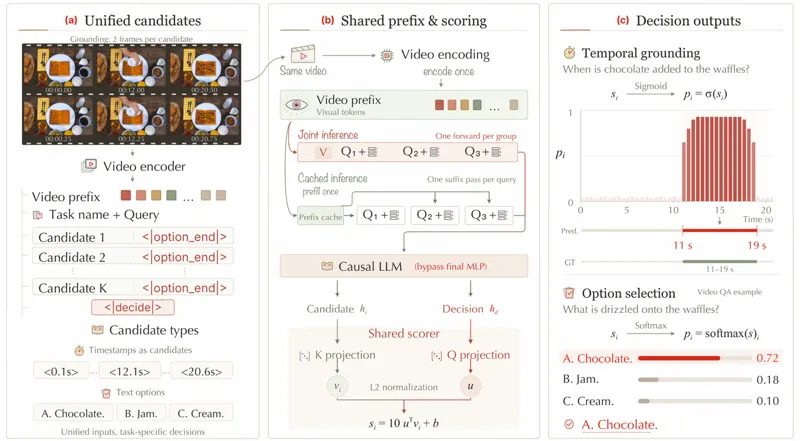
VideoJev casts temporal grounding and multiple-choice video QA as candidate scoring: a shared head scores temporal intervals and textual options against video evidence without autoregressive decoding, while Cached and Joint inference reuse the video prefix, giving +6.7/+10.8 mean mIoU over backbones with 2.8-3.1x and >100x measured speedups.
Yuhan Zhu, Xiangyu Zeng, Qingyi Si · 8 views · Oct 13, 2026
Video understandingTemporal GroundingVideo QAOct 13, 2026