RIWANav: Recursive World-Action Models with Self-Improvement for Urban Navigation
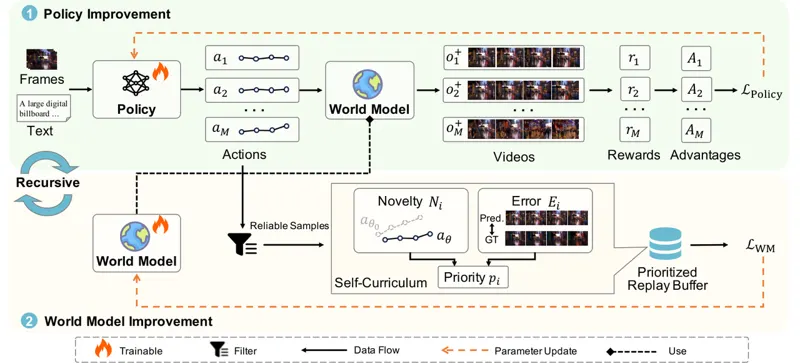
Long-horizon urban navigation compounds single-step errors, imitation learning only supervises expert successes, and a frozen action-conditioned world model drifts out of alignment as the policy evolves. RIWANav casts the coupled adaptation of a world model and a navigation policy as task-specific recursive self-improvement: Cosmos imagines 17 future frames for four sampled waypoint chunks per state, the resulting scores drive GRPO with a KL penalty and an expert anchor, and the improved policy then proposes actions whose expert-consistent action-video pairs (weighted ADE/MADE/AOE/MAOE consistency Q >= 0.35) enter a policy-induced replay pool prioritized by behavioral novelty and current prediction error to refine the world model over K=19 rounds. On UrbanNav it reaches 89.92% SR / 86.87% SPL on test-seen and 88.25% / 82.59% on test-unseen, beating frozen-world-model GRPO-WM by 7.94 / 6.50 points and cutting navigation error from 3.3314 to 2.0429, with world-model L1/LPIPS on policy-induced actions down 3.2% / 7.1%. Real-world trials on a custom mobile robot confirm practical transfer.