
HarnessMM: Recursive Self-Improvement for Harness Token Efficiency
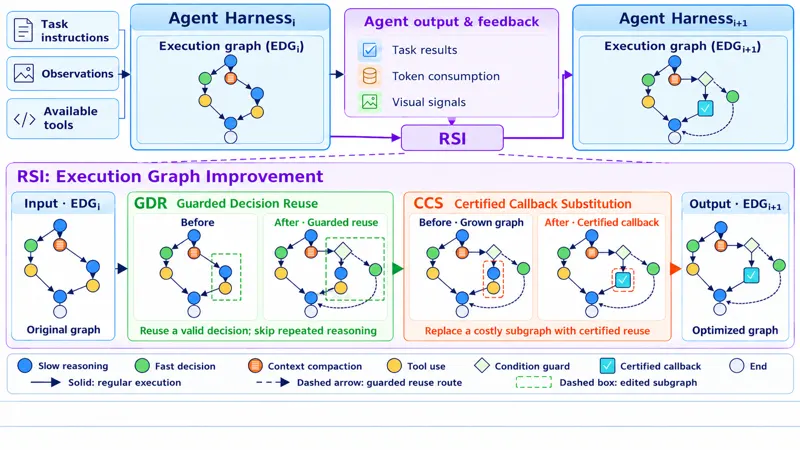
Agent harnesses often invoke the reasoning model again after tool feedback even when an earlier call has already fixed the next action. HarnessMM reuses resolved decisions at the model-tool boundary while keeping actor weights fixed. Executable Decision Graphs retain exact actions, literal arguments, causal dependencies, and public guards; Guarded Decision Reuse activates a stored decision from observed receipts, and Certified Callback Substitution executes it through the native interface while recording removal of the registered slow callback. New semantic decisions, unsupported evidence, and selector abstention fall back to the original actor. A recursive self-improvement loop refines the companion harness configuration from training feedback, with validation selecting the deployed configuration. On HumanEval, Codex preserves 90.82% success while reducing tokens per task from 66.72k to 47.02k; DeepSeek improves from 71.43% to 85.71% while cost falls from 96.28k to 11.62k. A separate MBPP ablation reports 26.91% lower cost than single-use graphs and 19.52% lower cost than retained callbacks.