Skip to content
Tags
Light-Loco-Parkour: Versatile Perceptive Whole-Body Locomotion via Multi-Skill Distillation

Light-Loco-Parkour: Versatile Perceptive Whole-Body Locomotion via Multi-Skill Distillation

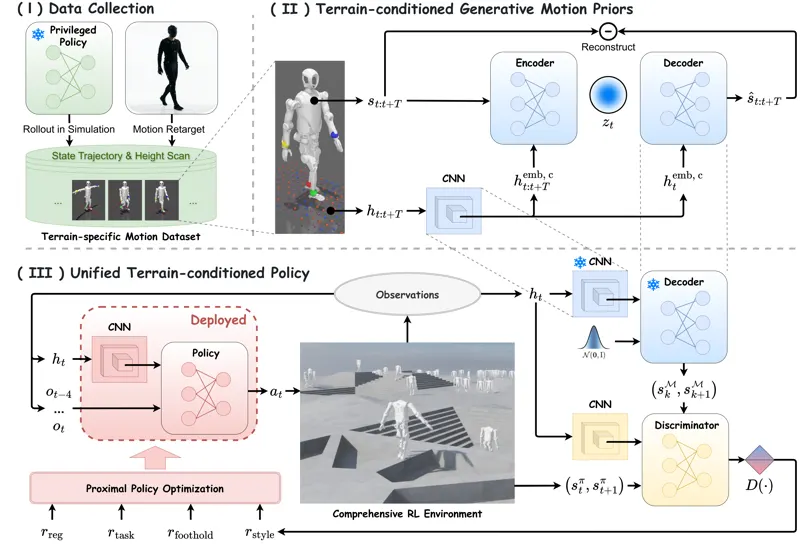
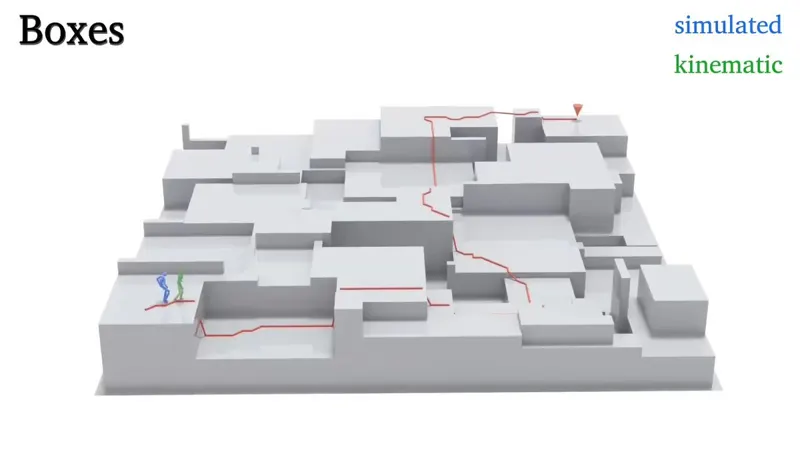
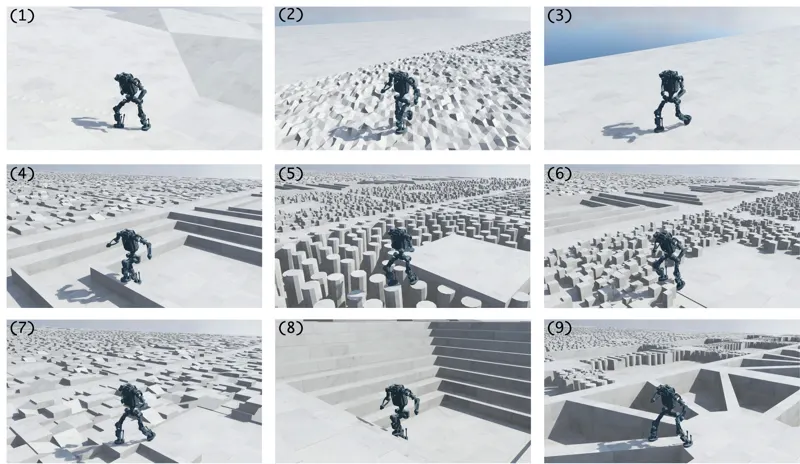
Existing humanoid whole-body control systems still fall short of the way humans move through cluttered terrain: they either track expressive whole-body references without terrain generalization, or react to terrain online while leaving the arms, torso, and knees largely unused. We present Light-Loco-Parkour (LLP), an end-to-end perceptive whole-body locomotion system that closes this gap with a single deployable policy. Conditioned only on onboard depth and a velocity command, the policy decides when to walk, balance, climb, step down, or vault, with no reference input, skill label, hand-coded gate, or runtime motion graph. Compared with prior humanoid systems, LLP makes three contributions. First, it introduces a whole-body perceptive-control pipeline that extends an RL-trained, velocity-tracking locomotion policy with parkour skills learned from object-interacting motions, so the same policy tracks velocity in open terrain, executes whole-body traversal at obstacles, and resumes locomotion afterward. Second, it acquires terrain-conditioned skills from sparse seeds by expanding a single motion into dynamically feasible, terrain-paired references across obstacle geometry, rather than relying on a large motion corpus. Third, it learns autonomous skill transitions from reward, letting the policy decide when and which whole-body skill to invoke from depth and command alone, with no one-hot skill label, hand-coded state machine, or runtime motion generator. Simulation and real-world experiments show high success across both benchmarked terrains and unseen obstacle variations, and the same policy transfers zero-shot to indoor and outdoor hardware experiments. These results demonstrate autonomous perceptive whole-body locomotion on a humanoid in outdoor settings, using only onboard sensing and a single deployable policy.

Hongming Chen, Zhuoran Li, Hongxi WangAug 1, 2026
RLHumanoidWhole-bodyAug 1, 2026
Safe Execution of RL Policies Via Acceleration-Based CBF-QP Constraint Enforcement for Real-World Robotic Deployments

Safe Execution of RL Policies Via Acceleration-Based CBF-QP Constraint Enforcement for Real-World Robotic Deployments

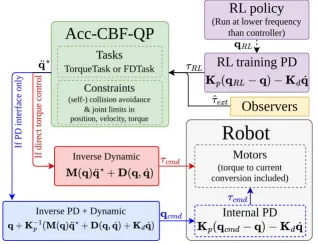
Reinforcement Learning (RL) has demonstrated remarkable capabilities for solving complex robotic control problems, but its lack of safety guarantees severely limits deployment on hardware. In particular, as legged robots and manipulators often operate near safety-critical boundaries, out-of-distribution states can lead to failure upon deployment. To address this, we introduce Acc-CBF-QP, an acceleration-based Quadratic Program (QP) safety filter using Control Barrier Functions (CBFs) that constrains any RL policy onto a safe set at runtime without modifying training. The method applies to unconstrained and Safe-RL policies, and enforces joint position, velocity, torque, and collision constraints within a unified optimization framework. A key contribution is the formulation of RL+QP tasks that regulate deviation from the RL command when constraints would otherwise be violated. We introduce a TorqueTask, minimizing torque deviation, and a Forward Dynamics Task, minimizing induced acceleration deviation, thus providing principled control over safety-performance trade-offs. Experiments on a 7-DoF Kinova Gen3 manipulator and a 19-DoF Unitree H1 humanoid, both in simulation and on hardware, highlight substantial reductions in constraint violations. On the real H1 hardware, a Safe-RL policy alone yielded 10.04 violations/s, which were reduced by 92% to 0.80 violations/s when augmented with Acc-CBF-QP. On the Kinova Gen3, Acc-CBF-QP fully eliminated violations. Nominal task performance of the RL objective is preserved in violation-free regimes. Under aggressive velocity commands on H1, Acc-CBF-QP improves execution by preventing constraint-induced shutdowns, yielding longer survival times. The full pipeline is open-source.

Bastien Muraccioli, Alice Cariou, Pierre-Alexandre LeziartJul 16, 2026
RLSafetyCBF-QPJul 16, 2026