See like a Robot: Robot-Centric Pointmaps for Vision-Language-Action Models
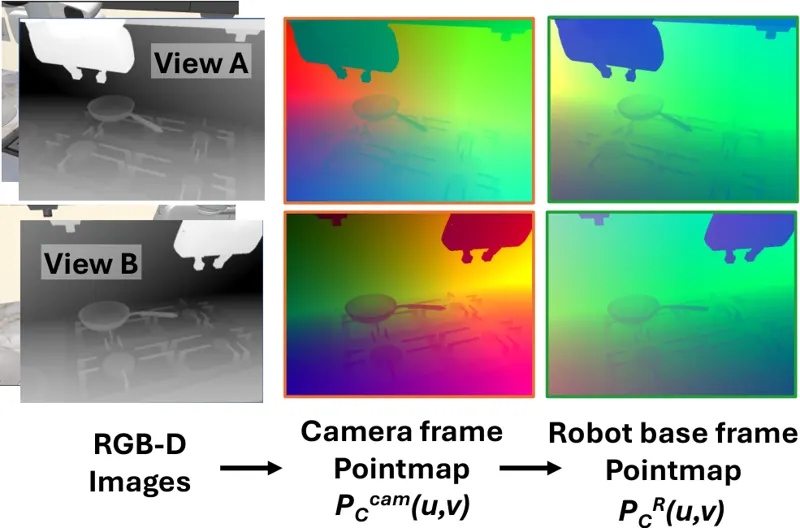
This paper addresses the frame mismatch in VLA models between camera-frame observation and robot-frame action by introducing robot-centric pointmaps—images whose pixels store 3D coordinates in the robot frame. Pointmaps provide robot-frame 3D geometry while preserving image structure, enabling cross-viewpoint generalization across diverse camera setups.
Byungkun Lee, Dongyoon Hwang, Dongjin Kim·Jul 13, 2026
VLAPointmapcross-viewpointJul 13, 2026
 0:43