
Training Reasoning Models in Simulation to Natively Use Real Robots
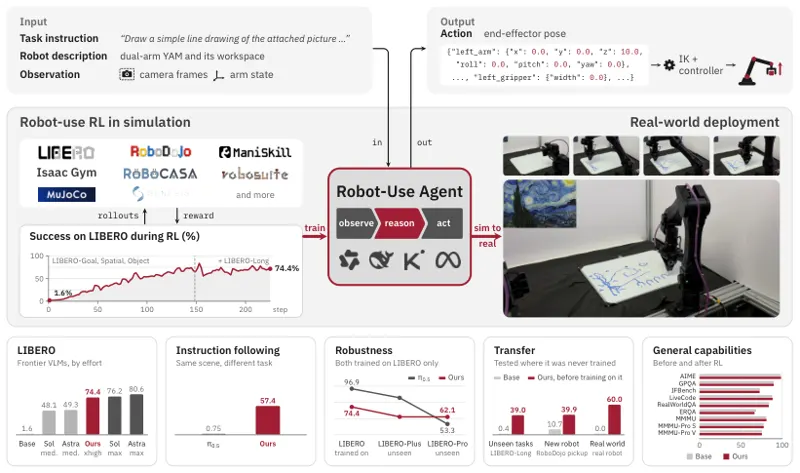
The authors train an open-weight 27B reasoning model to control real robots through simulation-only reinforcement learning and no demonstrations. PEAR uses robot-use reinforcement learning with next end-effector pose prediction; LIBERO success rises from 1.6% to 74.4%, and the trained model reaches 60% success on a real dual-arm robot.
Jiaming Tang, Zhuoyang Zhang, Junxian Guo · 28 views · Nov 13, 2026
Robot-Use AgentsReinforcement Learning
Nov 13, 2026