
Kernel Forge: An Agent Harness for LLM-based Generation and Optimization of CUDA Kernels
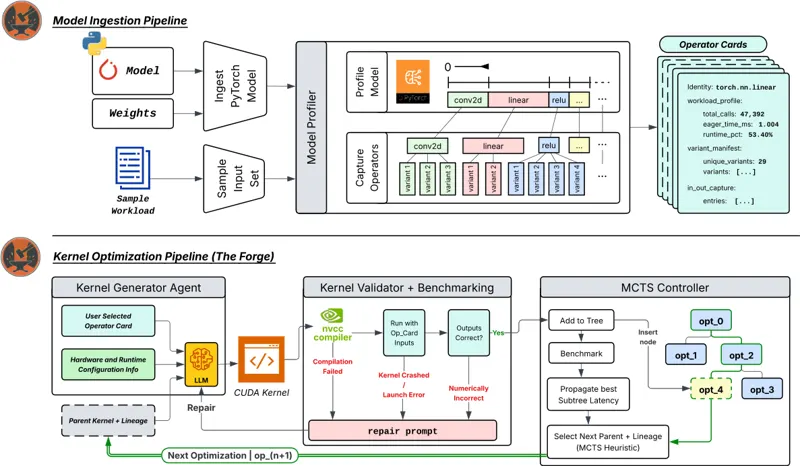
Kernel Forge is an open-source agent harness that accepts an unmodified PyTorch model, captures the operators that execute on representative inputs, and uses an LLM to generate and revise workload-specific CUDA kernels. A persistent Monte Carlo Tree Search controller explores alternative revision paths, while every candidate must compile with nvcc, run on the captured inputs, and match PyTorch eager outputs before it can enter the tree. Exported .cast packages dispatch generated CUDA only when the candidate is valid, compatible, and faster than the captured eager path; otherwise execution falls back to PyTorch. On an NVIDIA DGX Spark GB10, with 50 optimization iterations per kernel, 14 kernels outperform eager across ResNet-50, Stable Diffusion 3.5 Medium, Gemma 4 E2B, and Qwen 3.5 35B-A3B, including 1.52x on adaptive_avgpool2d, 1.70x on group_norm, and 2.83x and 1.54x on softmax.