FAR: Failure-Aware Retry for Test-Time Recovery and Continual Policy Improvement
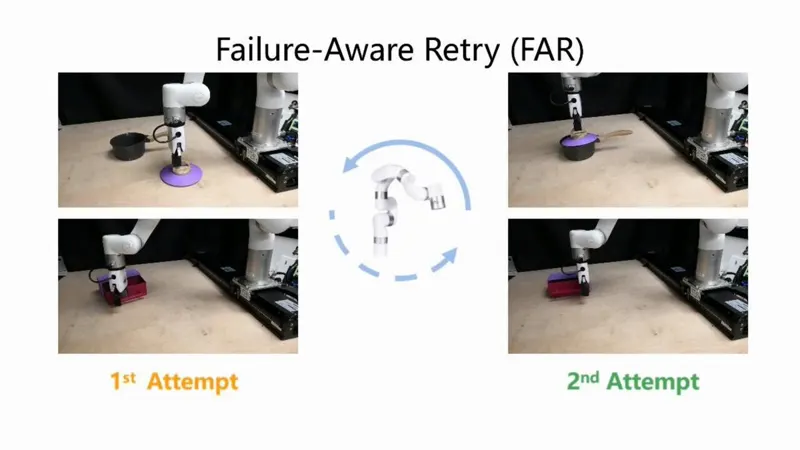
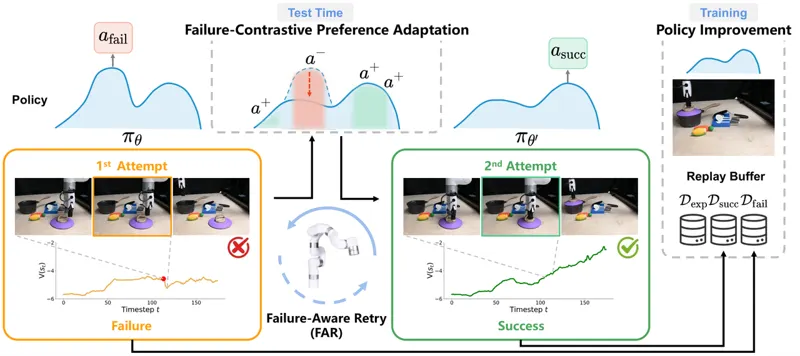
Robot policies trained on offline demonstrations fail inevitably at deployment, and naive retries repeat the same mistake because failure states are out of distribution for the pretrained policy. FAR (Failure-Aware Retry) keeps the scene after a failure, returns the arm to its start pose, and retries: an IQL-style conservative critic attributes the failure to the action chunks whose value drop falls in the lowest percentile, candidate chunks sampled from the current policy are distance-filtered and critic-ranked into top-K positives, and a diffusion preference-optimization loss updates the policy for only 10 gradient steps (1.5-3 s on a single A5000) while temporally smoothed Gaussian perturbations add local exploration during retries. Successful recovery trajectories then feed an advantage-weighted denoising objective for continual policy improvement. Across nine ManiSkill, RoboSuite and RoboMimic tasks FAR beats standard diffusion policy by 17.6 points on average, and on three xArm real-world tasks by 11.7 points (80.0% vs 68.3%), while cutting the environment resets that online learning needs.