WorldKV: managing a world model's memory like a cache
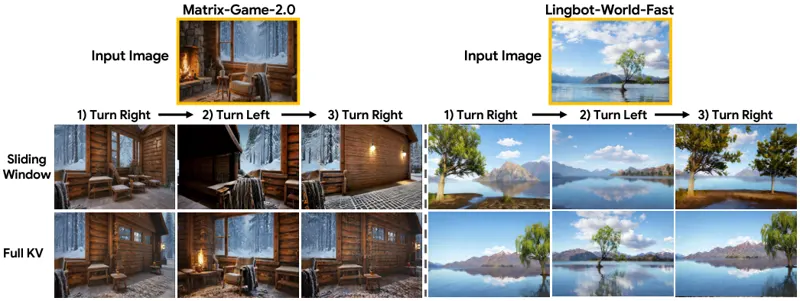
Memory in autoregressive video world models is a bind: full KV attention preserves revisit consistency, but memory footprint and attention cost grow linearly with rollout length, passing 200 GB per minute and exceeding a B200. Sliding window is real-time but drifts. WorldKV trains nothing and works purely at inference: it retrieves evicted KV chunks by camera/action similarity and compresses each chunk to half size by key-key cosine similarity, fitting roughly twice the history at roughly twice the throughput of full KV, with no memory training at all.
Jung Yi, Minjae Kim, Paul Hyunbin ChoMay 21, 2026
WorldModelKVCacheAutoregressiveVideoMay 21, 2026