ABot-N1: Toward a General Visual Language Navigation Foundation Model
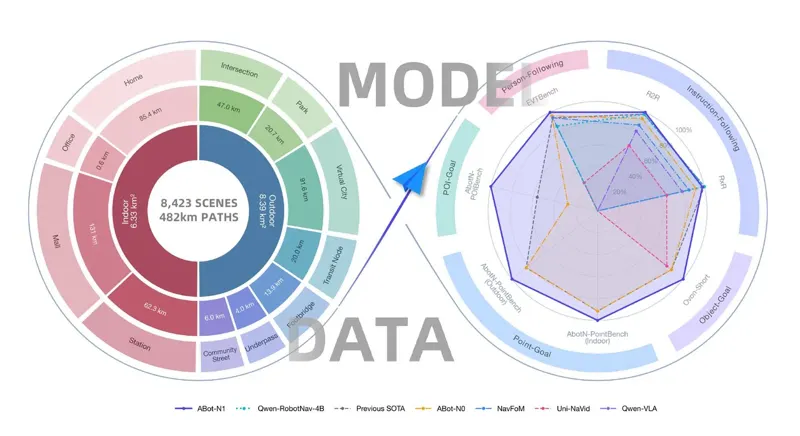
ABot-N1 is a general visual-language navigation foundation model built on a slow-fast dual-system architecture: a 4B slow VLM reasoner emits explicit chain-of-thought plus dual pixel goals (Target Pixel + Affordance Pixel), while a 2B fast action expert decodes continuous SE(2) waypoints via QFormer action queries. The unified pixel-goal interface covers five tasks — point-goal, object-goal, POI-goal, instruction-following and person-following — in a single 30M-sample multi-task checkpoint, further aligned by GRPO post-training with format/target/safety rewards. Two closed-loop benchmarks are released (ABotN-PointBench and ABotN-POIBench). ABot-N1 sets new SOTA on all five benchmarks, boosting POI entrance arrival to 77.3% (+35.0 pp) and reaching 92.9%/95.4% outdoor/indoor point-goal SR, with full deployment on the TuTu quadruped running on a Jetson AGX Orin.