
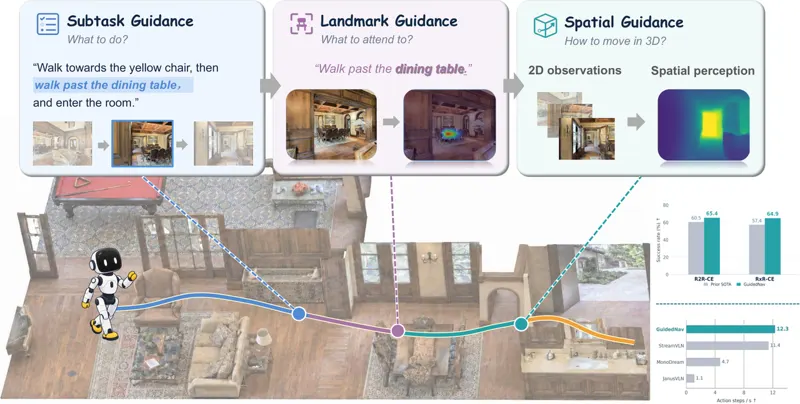
GuidedNav: Shaping Vision-Language Navigation Representations through Pre-action Attention and Spatial Guidance
GuidedNav shapes vision-language navigation representations during training with subtask, landmark, and spatial guidance. It aligns pre-action attention with the active instruction segment and relevant visual regions, then distills long-horizon geometry and local spatial structure into a monocular RGB policy. The method improves success rates on R2R-CE and RxR-CE val-unseen while avoiding intermediate textual reasoning and online geometric encoding at inference.
Jingyu Guo, Jiaxin Huang, Chengxing Lin · 36 views · Oct 9, 2026
Vision-and-Language NavigationEmbodied Navigation
Oct 9, 2026