
AgenticRoboRL: Bringing Coding-Agent Post-Training to Agentic Robotics
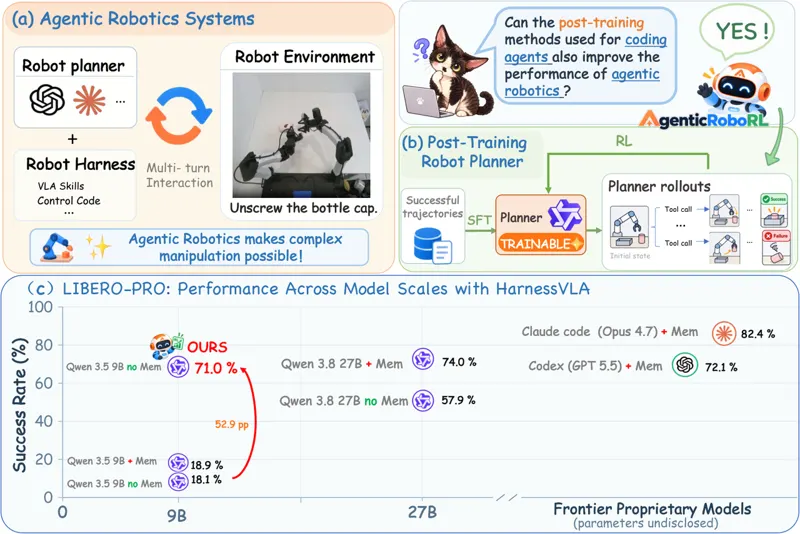
Agentic robot systems pair a language-model planner with a robot harness, but recent gains have largely come from stronger closed-source planners, better harnesses, and external memory rather than from improving the planner itself. AgenticRoboRL investigates whether coding-agent post-training can improve robot planners across both VLA skill invocation and control-code generation. Its recipe combines supervised fine-tuning on successful teacher trajectories with multi-turn reinforcement learning using task success as the terminal reward. A recording proxy preserves each sampled response and its actual context, while harness-specific adapters associate model calls with task outcomes and exclude infrastructure-invalid episodes. Only the planner is trained; perception and execution components remain fixed. With a 9B planner, success rises from 18.1% to 71.0% on LIBERO-PRO and from 19.2% to 72.2% on LIBERO-Plus. With the CaP-X control-code harness, the same post-training pipeline raises success from 2.7% to 28.5%.