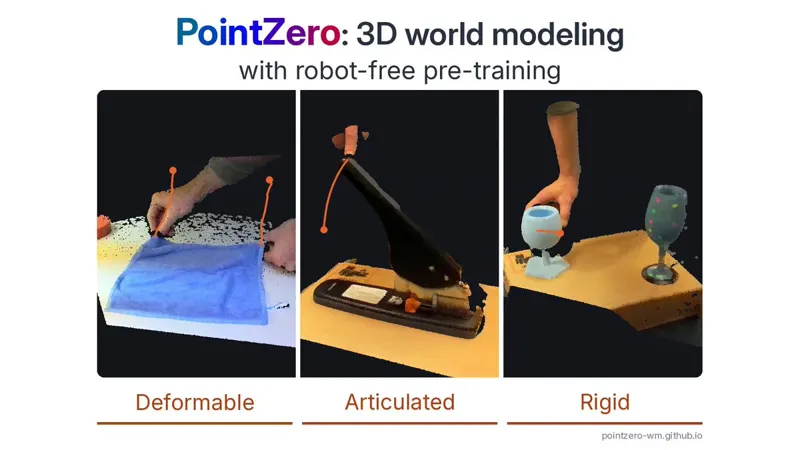
A 3D World Model Learned Without Action Labels
Loading video
Loading videomu-0 learns a physical language for robot interaction traces directly from video, eliminating the need for action labels when building a world model.
Category: world-model
Author: @jbhuang0604
Date: 2026-11-09T00:00:00
Duration: 169.002s
Reference: https://mu0-wm.github.io/