Skip to content
PAVXploreRL: Physical-Action-Visual World Model Reinforcement Learning with Action Exploration

PAVXploreRL: Physical-Action-Visual World Model Reinforcement Learning with Action Exploration

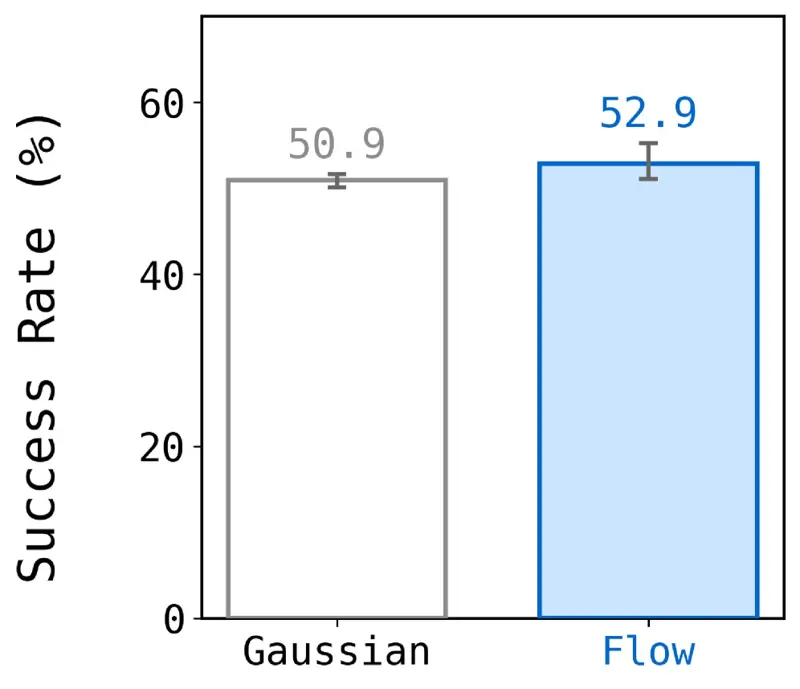
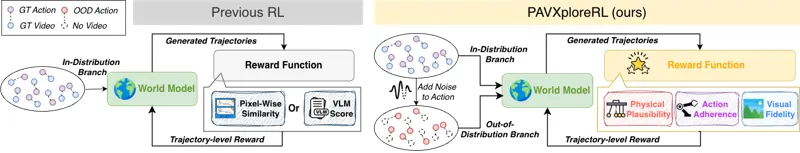
Action-conditioned world models are a key component of embodied AI, serving as scalable policy evaluators that reduce reliance on expensive real-world rollouts. To accurately capture diverse action-induced dynamics, such models should satisfy three key objectives-Physical Plausibility (P), Action Adherence (A), and Visual Fidelity (V), collectively referred to as PAV-while remaining robust to both in-distribution (ID) expert demonstrations and out-of-distribution (OOD) actions. However, existing methods primarily rely on ID action-video pairs and pixel-level reconstruction losses, which do not explicitly optimize PAV objectives and generalize poorly beyond expert data. To address this, we propose PAVXploreRL, a reinforcement learning framework built on a pretrained latent world model that explicitly optimizes PAV objectives through reward-driven training. To improve action generalization, our method jointly leverages ID trajectories and noise-driven OOD action exploration, without paired video supervision. Experiments show that PAVXploreRL consistently outperforms pretrained baselines, achieving a 5.6% average gain across benchmarks and producing higher-quality PAV properties. As a policy evaluator, it also yields more reliable performance estimates and reduces the overestimation bias of prior expert-only world models such as Ctrl-World. Code: https://github.com/Social-AI-Studio/PAVXploreRL

World ModelsReinforcement Learning
Han Wang, Zijun Wang, Shuoshuo Xue · 321 views · Jul 18, 2026
Koopman Dreamer: Spectrally Constrained Latent Dynamics for Stable World-Model Imagination

Koopman Dreamer: Spectrally Constrained Latent Dynamics for Stable World-Model Imagination

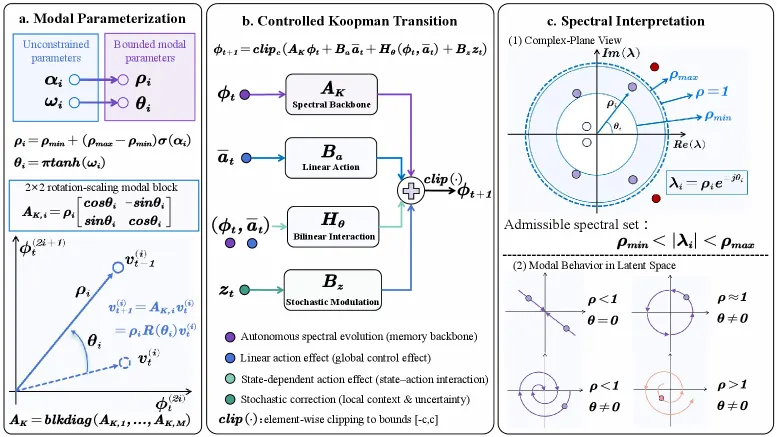
Latent world models improve sample efficiency in continuous control by optimizing policies over imagined latent trajectories, but common neural transitions offer limited direct control over modal persistence and error accumulation in long rollouts. We propose Koopman Dreamer, a Dreamer-style world model with a spectrally constrained deterministic latent dynamics core. Its Koopman-inspired backbone uses two-dimensional rotation–scaling blocks with bounded radii to represent damping, rotation, and near-periodic modes. Linear and low-rank bilinear action terms capture global and state-dependent control effects, while stochastic-state modulation supplies local correction information. To reduce the mismatch between posterior-conditioned training and prior-only imagination, the model combines posterior-conditioned EMA teacher targets with one-step consistency, multi-step rollout, and open-loop observation-prediction objectives. We further derive a multi-step rollout-error bound that separates amplification by the spectral backbone and bilinear interaction from the additive effects of stochastic-state mismatch and modeling residuals, clarifying the trade-off between error attenuation and long-term information retention. Experimental results on proprioceptive continuous-control tasks from the DeepMind Control Suite and UAV-LiDAR autonomous navigation demonstrate that Koopman Dreamer improves the stability of long-horizon latent rollouts and achieves stronger closed-loop control performance on tasks that rely on high-quality multi-step imagination.

DreamerKoopman
Jiaqi Li, Xinglong Zhang, Haibin Xie · 571 views · Jul 22, 2026
The World Model Remembers, the Actor Forgets: Dream Rehearsal for Continual Model-Based RL

The World Model Remembers, the Actor Forgets: Dream Rehearsal for Continual Model-Based RL

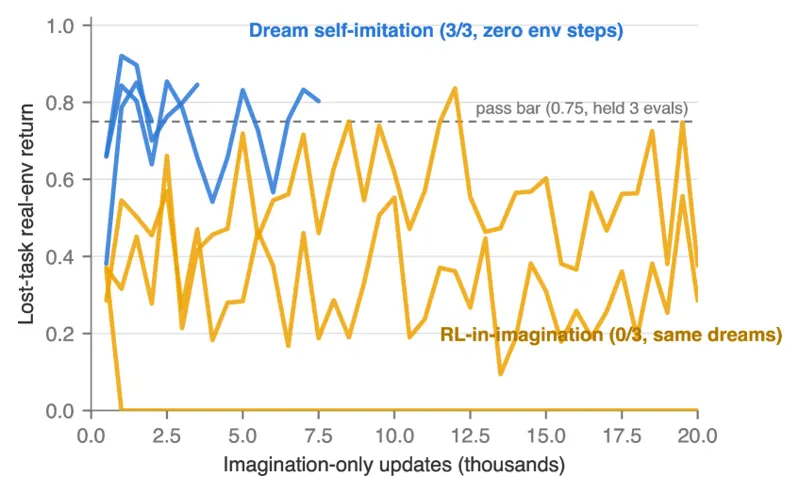
Model-based reinforcement-learning agents of the DreamerV3 family forget catastrophically when trained on task sequences, even when an unbounded replay buffer preserves every earlier experience. We ask a question the continual-RL literature has assumed an answer to but never measured: which component forgets? Under never-clear replay, pre-registered component-level probes (n=3 seeds throughout) show that the world model retains essentially everything measurable about old tasks – reward discrimination (retention ratio ~1.0), value estimates, and termination structure – while the actor's behavior collapses. Forgetting in this regime is a channel problem, not a memory problem. We demonstrate this by intervention: with the world model frozen and identical imagined rollouts, reinforcement learning in imagination fails to recover a lost skill (0/3 seeds), while supervised self-imitation on the world model's own graded dreams recovers it on 3/3 seeds with zero environment interaction. Interleaved during training, this graded dream rehearsal yields a task-label-free, parameter-constant continual learner: 3/3 four-task chains retained where plain replay passes 0/3, 3/3 eight-task chains, and consistent gains over matched real-episode cloning (paired difference +0.13, bootstrap 95% CI [0.07, 0.24], complete seed separation). The dream-grading step is load-bearing: we characterize two scoring failure modes, provide an offline selection gauge that caught both before they contaminated results, and give a realized-first grading rule that closes them. All experiments were pre-registered with committed protocols; every refuted hypothesis is reported.

DreamerWorld Models
Gurp Nijjer · 509 views · Jul 22, 2026
Dreamer-CPC: Message Learning with World Models for Decentralized Multi-agent Reinforcement Learning

Dreamer-CPC: Message Learning with World Models for Decentralized Multi-agent Reinforcement Learning

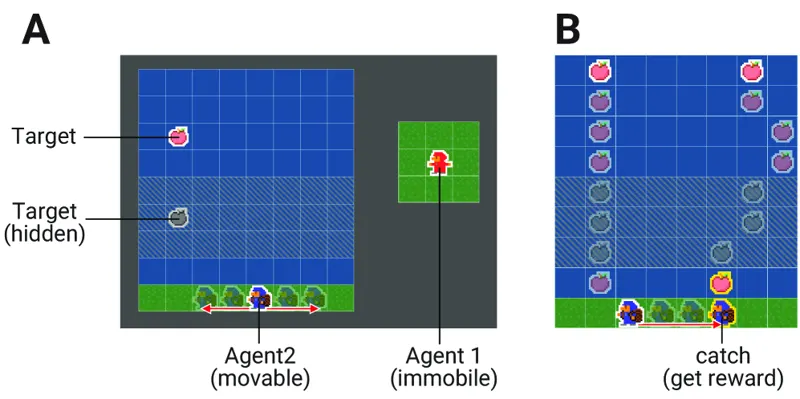
In multi-agent reinforcement learning (MARL), inter-agent communication is effective for improving performance under partial observability. Representation learning-based approaches enable decentralized agents to learn messages grounded in their own observations, but they rely only on current observations and cannot convey information accumulated over time. We propose Dreamer-CPC, a decentralized model-based MARL method that integrates message learning based on Collective Predictive Coding (CPC) into the world model of DreamerV3. Each agent independently maintains a world model and a message module, and infers and exchanges messages from the latent states of the world model that reflect the history of past observations and actions. We evaluated Dreamer-CPC in two environments: Observer, a non-cooperative information-sharing task, and CatchApple, a newly introduced task in which task-relevant observations are temporarily missing. In both environments, Dreamer-CPC outperformed IPPO-CPC, an existing CPC-based method that generates messages from current observations, as well as no-communication baselines. In particular, in CatchApple, Dreamer-CPC achieved 4 to 5 times the episode return of IPPO-CPC, demonstrating effective coordination where other methods fail due to missing observations. These results suggest that communication grounded in the latent dynamics of world models can support decentralized decision-making when current observations alone are insufficient.

DreamerWorld Models
Taisuke Takayama, Naoto Yoshida, Tadahiro Taniguchi · 444 views · Jul 22, 2026
Safe Execution of RL Policies Via Acceleration-Based CBF-QP Constraint Enforcement for Real-World Robotic Deployments

Safe Execution of RL Policies Via Acceleration-Based CBF-QP Constraint Enforcement for Real-World Robotic Deployments

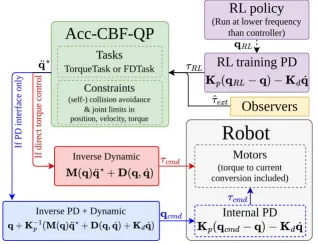
Reinforcement Learning (RL) has demonstrated remarkable capabilities for solving complex robotic control problems, but its lack of safety guarantees severely limits deployment on hardware. In particular, as legged robots and manipulators often operate near safety-critical boundaries, out-of-distribution states can lead to failure upon deployment. To address this, we introduce Acc-CBF-QP, an acceleration-based Quadratic Program (QP) safety filter using Control Barrier Functions (CBFs) that constrains any RL policy onto a safe set at runtime without modifying training. The method applies to unconstrained and Safe-RL policies, and enforces joint position, velocity, torque, and collision constraints within a unified optimization framework. A key contribution is the formulation of RL+QP tasks that regulate deviation from the RL command when constraints would otherwise be violated. We introduce a TorqueTask, minimizing torque deviation, and a Forward Dynamics Task, minimizing induced acceleration deviation, thus providing principled control over safety-performance trade-offs. Experiments on a 7-DoF Kinova Gen3 manipulator and a 19-DoF Unitree H1 humanoid, both in simulation and on hardware, highlight substantial reductions in constraint violations. On the real H1 hardware, a Safe-RL policy alone yielded 10.04 violations/s, which were reduced by 92% to 0.80 violations/s when augmented with Acc-CBF-QP. On the Kinova Gen3, Acc-CBF-QP fully eliminated violations. Nominal task performance of the RL objective is preserved in violation-free regimes. Under aggressive velocity commands on H1, Acc-CBF-QP improves execution by preventing constraint-induced shutdowns, yielding longer survival times. The full pipeline is open-source.

RLSafety
Bastien Muraccioli, Alice Cariou, Pierre-Alexandre Leziart · 476 views · Jul 16, 2026

As an Amazon Associate, we earn from qualifying purchases.