Skip to content
Dreamer-CPC: Message Learning with World Models for Decentralized Multi-agent Reinforcement Learning

Dreamer-CPC: Message Learning with World Models for Decentralized Multi-agent Reinforcement Learning

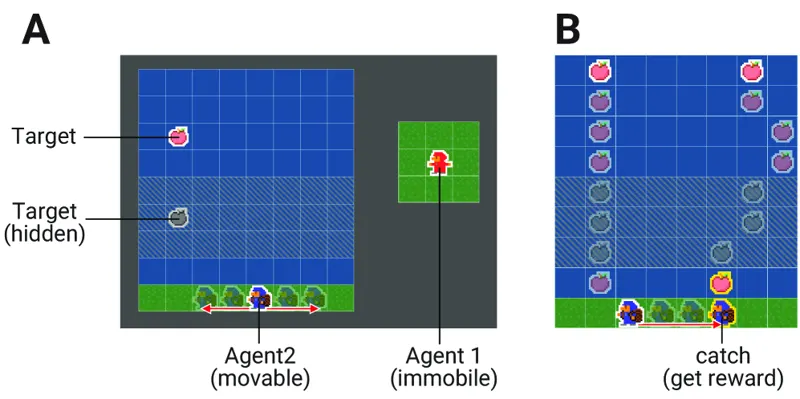
In multi-agent reinforcement learning (MARL), inter-agent communication is effective for improving performance under partial observability. Representation learning-based approaches enable decentralized agents to learn messages grounded in their own observations, but they rely only on current observations and cannot convey information accumulated over time. We propose Dreamer-CPC, a decentralized model-based MARL method that integrates message learning based on Collective Predictive Coding (CPC) into the world model of DreamerV3. Each agent independently maintains a world model and a message module, and infers and exchanges messages from the latent states of the world model that reflect the history of past observations and actions. We evaluated Dreamer-CPC in two environments: Observer, a non-cooperative information-sharing task, and CatchApple, a newly introduced task in which task-relevant observations are temporarily missing. In both environments, Dreamer-CPC outperformed IPPO-CPC, an existing CPC-based method that generates messages from current observations, as well as no-communication baselines. In particular, in CatchApple, Dreamer-CPC achieved 4 to 5 times the episode return of IPPO-CPC, demonstrating effective coordination where other methods fail due to missing observations. These results suggest that communication grounded in the latent dynamics of world models can support decentralized decision-making when current observations alone are insufficient.

DreamerWorld Models
Taisuke Takayama, Naoto Yoshida, Tadahiro Taniguchi · 444 views · Jul 22, 2026
PhysCoRe: Physics-Corrected Residual World Models for Material-Aware Deformable Dynamics

PhysCoRe: Physics-Corrected Residual World Models for Material-Aware Deformable Dynamics

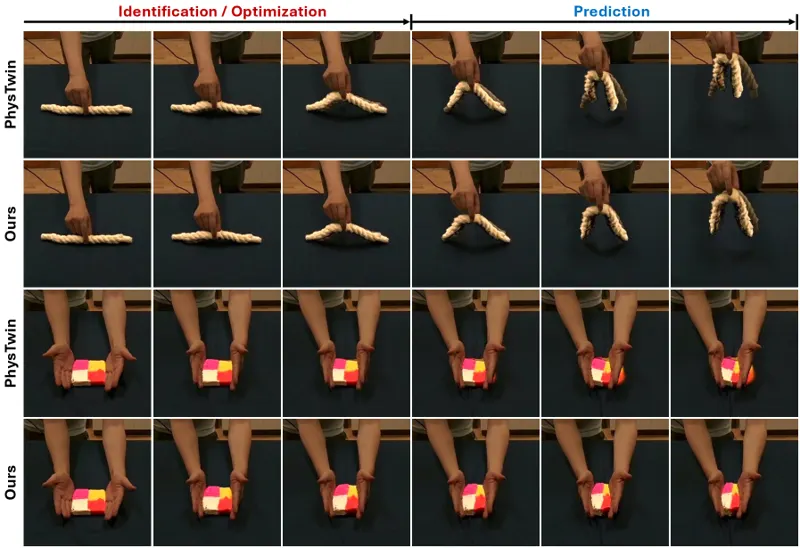
Predicting how deformable objects evolve under robotic manipulation is a longstanding challenge. Existing approaches typically rely on per-object optimization to fit material parameters, which can be slow and cannot generalize, while end-to-end learned alternatives extrapolate poorly and often violate basic physical structure. We present PhysCoRe, a physics-corrected residual world model that couples a differentiable Material Point Method (MPM) simulator with two feed-forward neural networks. A material refinement module, Material from Motion (MfM), infers per-particle elasticity from visual observations, grounding the simulator in object-specific physics. A residual correction module, Residual from Dynamics (RfD), learns the discrepancy and predicts corrections to the simulator's internal dynamics, absorbing systematic biases that the analytical model cannot capture. This design also supports online material identification on novel objects. MfM adapts from limited interactions, and its predictive uncertainty steers further exploration toward the regions where its estimate is least confident. Experiments on real deformable-object manipulation sequences show that PhysCoRe outperforms state-of-the-art baselines in prediction accuracy, and that its predicted confidence forms a reliable distribution across the object's geometry, providing a natural signal for future confidence-guided exploration.

World ModelsPhysics simulation
Haocheng Yin, Shuohan Tao, Yongsheng Chen · 521 views · Jul 22, 2026
AeroAct: Action-Centered World-Action Models for Language-Conditioned Quadrotor Flight

AeroAct: Action-Centered World-Action Models for Language-Conditioned Quadrotor Flight

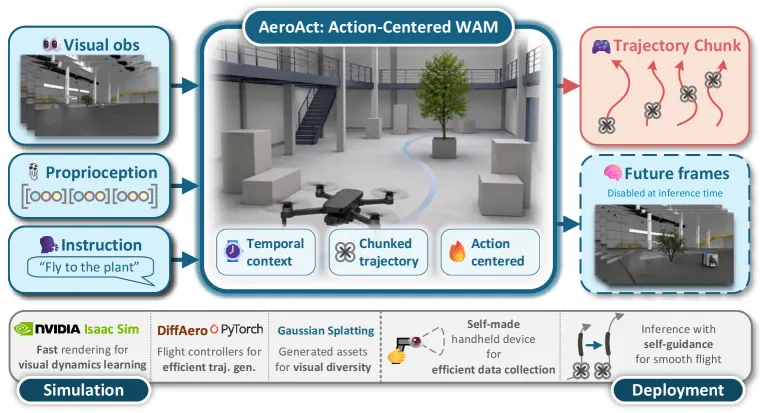
Language-conditioned quadrotor flight requires a policy to ground semantic goals, anticipate the visual consequences of ego-motion, and output control references that remain smooth and dynamically executable under rapidly changing first-person views. Existing aerial vision-language navigation and vision-language-action methods commonly use discrete actions, high-level waypoints, or instantaneous velocity commands, which provide limited supervision about how flight actions change future observations. We present AeroAct, an action-centered world-action model (WAM) for quadrotor navigation. To the best of our knowledge, AeroAct is the first WAM instantiated and demonstrated for real-world aerial flight. The model adapts a pretrained video diffusion Transformer to predict local trajectory-action chunks from egocentric visual history, proprioception, and language. Future first-person frames are used during training as dense consequence supervision, while deployment directly decodes actions without generating future video. To obtain aligned visual, state, language, and dynamically feasible action data, we build a DiffAero-based pipeline with complementary Isaac Lab and 3D Gaussian splatting renderers. We further introduce a low-cost handheld collection device that couples camera observations with motion estimates to recreate flight-like egocentric trajectories, and a self-guidance procedure that improves temporal consistency across overlapping trajectory chunks. Closed-loop simulation and real-world experiments show that temporal visual context improves target tracking and object-search performance, and that WAM-based policies can be executed on a physical quadrotor.

UAVQuadrotor
Xinhong Zhang, Qiyuan Zhu, Yubo Huang · 613 views · Jul 16, 2026
Do Coding Agents Need Executable World Models, Simplification, and Verification to Solve ARC-AGI-3?

Do Coding Agents Need Executable World Models, Simplification, and Verification to Solve ARC-AGI-3?

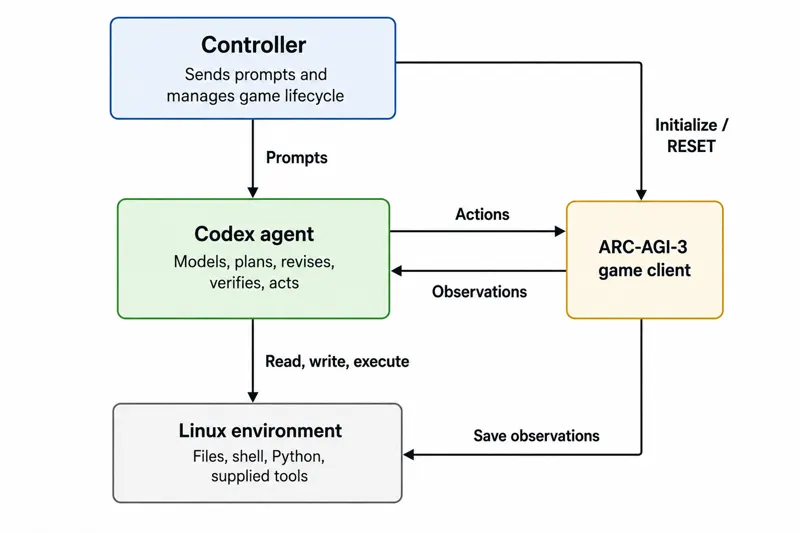
Our previous ARC-AGI-3 agent bundled executable world modeling, scheduled simplification, and exact replay verification, leaving unclear which idea accounted for its performance. We address this attribution question with four nested Codex-based agents: a textual baseline; a flexible-interface executable world model without replay verification; the same executable model with scheduled simplification; and a fixed-interface verification treatment that retains simplification and requires exact reproduction of recorded observations. The main study evaluates all four agents with gpt-5.4 and gpt-5.5 at high and xhigh reasoning effort on the public ARC-AGI-3 games. Exploratory follow-ups evaluate the textual and verification variants with gpt-5.6-sol at xhigh and max. The most robust result is that every agent variant improves with a stronger model and with greater reasoning effort. Within each model-effort setting, differences among variants are smaller than anticipated, while the effects of individual components vary across settings. Requiring a persistent executable deliverable is not universally beneficial: the textual variant outperforms the flexible-interface executable variant in both gpt-5.5 settings. Simplification improves performance in three of the four model-effort settings, with the weakest setting as the only exception. The complete verification treatment ranks first in all four settings, although it uses substantially more resources. In the gpt-5.6-sol follow-up, the verification variant fully solves every public game at both reasoning efforts, achieves about 99% RHAE, and uses fewer than half the total actions of the human baseline. Because the model postdates these games and held-out performance remains untested, this result should be interpreted as saturation of the public set only.

ARC-AGICoding Agent
Sergey Rodionov · 432 views · Jul 16, 2026
Orbis 2: A Hierarchical World Model for Driving

Orbis 2: A Hierarchical World Model for Driving

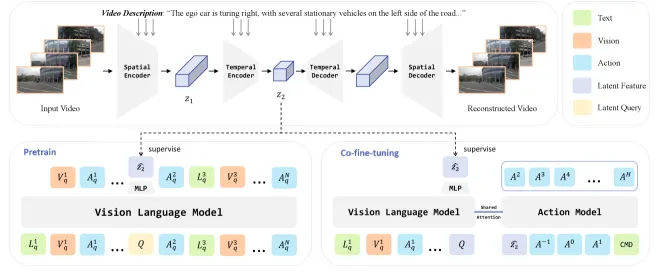
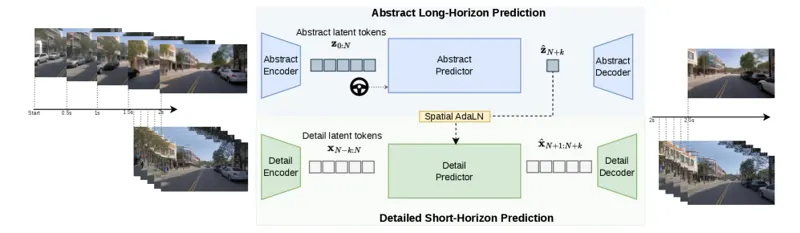
Current world models operate at a single level of abstraction, with most prioritizing perceptual fidelity while lacking the spatial reasoning and semantic understanding required for real-world downstream tasks. We present a hierarchical driving world model that factorizes future prediction across two levels operating at distinct temporal and abstraction scales: a high-level predictor that forecasts coarse scene structure over extended temporal horizons, and a low-level generator that produces detailed predictions conditioned on the high-level output. This decomposition yields high perceptual fidelity while also capturing strong spatial and semantic representations. We further show that pretraining with a diffusion forcing objective yields substantially richer internal representations than the standard teacher forcing objective, while teacher forcing – predicting only the next frame from clean context – produces more stable autoregressive rollouts. We therefore introduce a generic two-stage training paradigm that pretrains the model with diffusion forcing and fine-tunes with teacher forcing, combining the representational benefits of the former with the rollout stability of the latter. Our approach achieves state-of-the-art results across the standard suite of driving world model evaluations on established benchmarks, including long-horizon generation fidelity, steering responsiveness evaluated on counterfactual scenarios, and internal representation quality. Project page with code, demo, checkpoints and qualitative results: https://lmb-freiburg.github.io/orbis2.github.io/

World ModelsDriving
Sudhanshu Mittal, Arian Mousakhan, Silvio Galesso · 495 views · Jul 17, 2026

As an Amazon Associate, we earn from qualifying purchases.