Skip to content
Koopman Dreamer: Spectrally Constrained Latent Dynamics for Stable World-Model Imagination

Koopman Dreamer: Spectrally Constrained Latent Dynamics for Stable World-Model Imagination

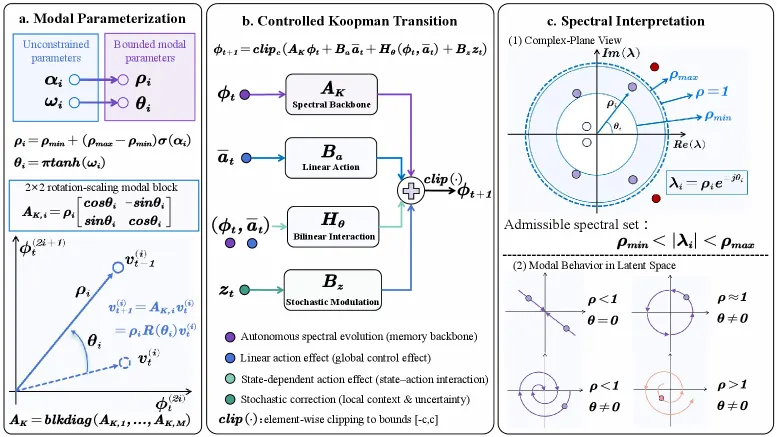
Latent world models improve sample efficiency in continuous control by optimizing policies over imagined latent trajectories, but common neural transitions offer limited direct control over modal persistence and error accumulation in long rollouts. We propose Koopman Dreamer, a Dreamer-style world model with a spectrally constrained deterministic latent dynamics core. Its Koopman-inspired backbone uses two-dimensional rotation–scaling blocks with bounded radii to represent damping, rotation, and near-periodic modes. Linear and low-rank bilinear action terms capture global and state-dependent control effects, while stochastic-state modulation supplies local correction information. To reduce the mismatch between posterior-conditioned training and prior-only imagination, the model combines posterior-conditioned EMA teacher targets with one-step consistency, multi-step rollout, and open-loop observation-prediction objectives. We further derive a multi-step rollout-error bound that separates amplification by the spectral backbone and bilinear interaction from the additive effects of stochastic-state mismatch and modeling residuals, clarifying the trade-off between error attenuation and long-term information retention. Experimental results on proprioceptive continuous-control tasks from the DeepMind Control Suite and UAV-LiDAR autonomous navigation demonstrate that Koopman Dreamer improves the stability of long-horizon latent rollouts and achieves stronger closed-loop control performance on tasks that rely on high-quality multi-step imagination.

DreamerKoopman
Jiaqi Li, Xinglong Zhang, Haibin Xie · 571 views · Jul 22, 2026
The World Model Remembers, the Actor Forgets: Dream Rehearsal for Continual Model-Based RL

The World Model Remembers, the Actor Forgets: Dream Rehearsal for Continual Model-Based RL

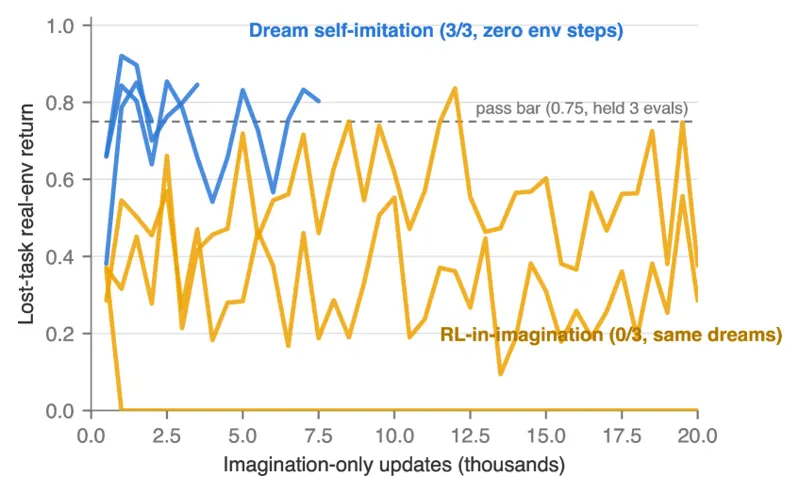
Model-based reinforcement-learning agents of the DreamerV3 family forget catastrophically when trained on task sequences, even when an unbounded replay buffer preserves every earlier experience. We ask a question the continual-RL literature has assumed an answer to but never measured: which component forgets? Under never-clear replay, pre-registered component-level probes (n=3 seeds throughout) show that the world model retains essentially everything measurable about old tasks – reward discrimination (retention ratio ~1.0), value estimates, and termination structure – while the actor's behavior collapses. Forgetting in this regime is a channel problem, not a memory problem. We demonstrate this by intervention: with the world model frozen and identical imagined rollouts, reinforcement learning in imagination fails to recover a lost skill (0/3 seeds), while supervised self-imitation on the world model's own graded dreams recovers it on 3/3 seeds with zero environment interaction. Interleaved during training, this graded dream rehearsal yields a task-label-free, parameter-constant continual learner: 3/3 four-task chains retained where plain replay passes 0/3, 3/3 eight-task chains, and consistent gains over matched real-episode cloning (paired difference +0.13, bootstrap 95% CI [0.07, 0.24], complete seed separation). The dream-grading step is load-bearing: we characterize two scoring failure modes, provide an offline selection gauge that caught both before they contaminated results, and give a realized-first grading rule that closes them. All experiments were pre-registered with committed protocols; every refuted hypothesis is reported.

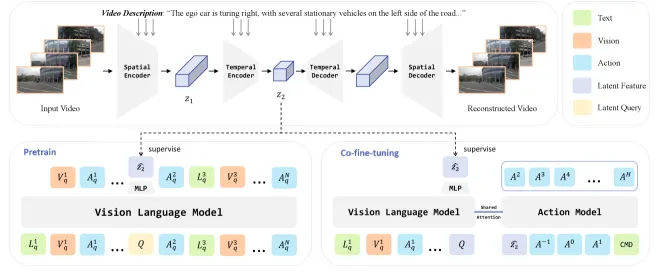
DreamerWorld Models
Gurp Nijjer · 509 views · Jul 22, 2026
Dreamer-CPC: Message Learning with World Models for Decentralized Multi-agent Reinforcement Learning

Dreamer-CPC: Message Learning with World Models for Decentralized Multi-agent Reinforcement Learning

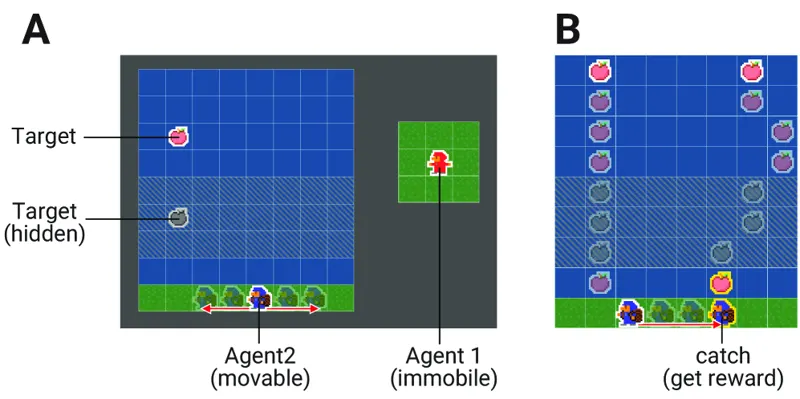
In multi-agent reinforcement learning (MARL), inter-agent communication is effective for improving performance under partial observability. Representation learning-based approaches enable decentralized agents to learn messages grounded in their own observations, but they rely only on current observations and cannot convey information accumulated over time. We propose Dreamer-CPC, a decentralized model-based MARL method that integrates message learning based on Collective Predictive Coding (CPC) into the world model of DreamerV3. Each agent independently maintains a world model and a message module, and infers and exchanges messages from the latent states of the world model that reflect the history of past observations and actions. We evaluated Dreamer-CPC in two environments: Observer, a non-cooperative information-sharing task, and CatchApple, a newly introduced task in which task-relevant observations are temporarily missing. In both environments, Dreamer-CPC outperformed IPPO-CPC, an existing CPC-based method that generates messages from current observations, as well as no-communication baselines. In particular, in CatchApple, Dreamer-CPC achieved 4 to 5 times the episode return of IPPO-CPC, demonstrating effective coordination where other methods fail due to missing observations. These results suggest that communication grounded in the latent dynamics of world models can support decentralized decision-making when current observations alone are insufficient.

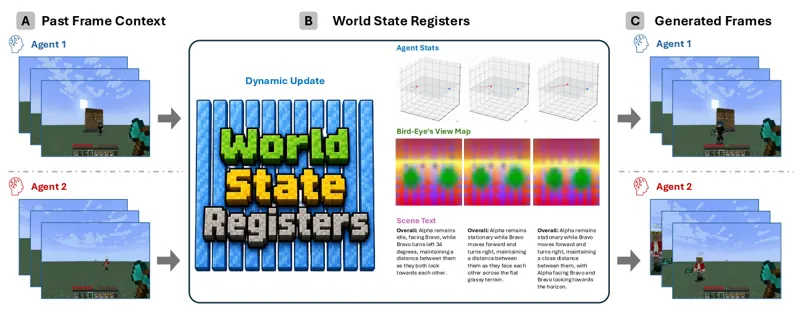
DreamerWorld Models
Taisuke Takayama, Naoto Yoshida, Tadahiro Taniguchi · 444 views · Jul 22, 2026
Odin: Primitive-Level Synchronization for Distributed Point-Based Neural Rendering

Odin: Primitive-Level Synchronization for Distributed Point-Based Neural Rendering

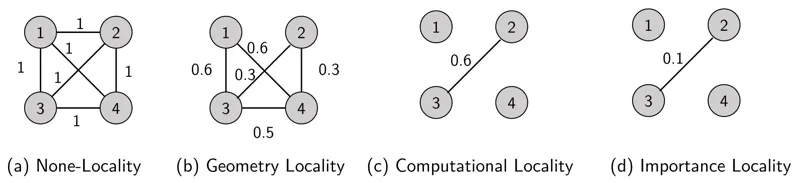
Point-based neural rendering (PBNR) represents 3D scenes as explicit, trainable primitives and underpins high-quality reconstruction and emerging embodied AI and world-model pipelines. Unlike layer-structured neural networks, PBNR has primitive-indexed dependencies: each view reads and updates only a sparse, view-dependent subset of mutable scene state. As large scenes require distributed training and optimized renderers reduce per-view computation, global task- or iteration-level barriers increasingly place synchronization, rather than rendering, on the critical path. We present Odin, a distributed PBNR training system that replaces global barriers with primitive-level synchronization. Its ahead-of-time scheduler uses stable locality and phase order to identify low-conflict overlap windows, while the runtime validates primitive publication before later work observes mutable state. Odin provides a quality-first path that preserves synchronized-training visibility and a throughput-first path that uses overlap and gradient evidence to admit only small, low-impact delayed reads; structural changes and high-impact cases remain synchronized. Across four existing PBNR pipelines and 13 non-city scenes on 8 GPUs, Odin improves throughput by 1.22 times on average and hides 82% of critical-path wait while preserving reconstruction quality. In a MatrixCity mixed-parallel case study scaling to 64 GPUs, Odin improves throughput over Grendel by up to 1.89 times without changing renderer kernels, optimizers, training budgets, or model capacity.

3D Gaussian SplattingNeural rendering
Zhenxiang Ma, Zeyu He, Yuanzhen Zhou · 405 views · Jul 22, 2026
PhysCoRe: Physics-Corrected Residual World Models for Material-Aware Deformable Dynamics

PhysCoRe: Physics-Corrected Residual World Models for Material-Aware Deformable Dynamics

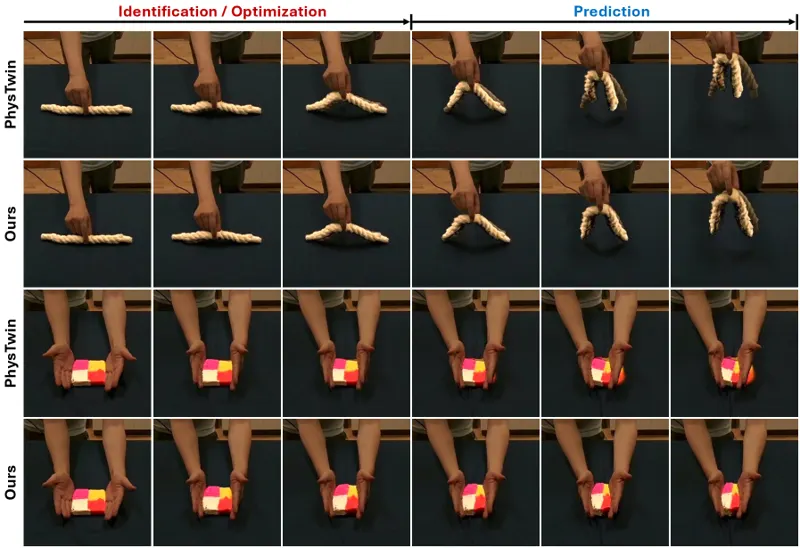
Predicting how deformable objects evolve under robotic manipulation is a longstanding challenge. Existing approaches typically rely on per-object optimization to fit material parameters, which can be slow and cannot generalize, while end-to-end learned alternatives extrapolate poorly and often violate basic physical structure. We present PhysCoRe, a physics-corrected residual world model that couples a differentiable Material Point Method (MPM) simulator with two feed-forward neural networks. A material refinement module, Material from Motion (MfM), infers per-particle elasticity from visual observations, grounding the simulator in object-specific physics. A residual correction module, Residual from Dynamics (RfD), learns the discrepancy and predicts corrections to the simulator's internal dynamics, absorbing systematic biases that the analytical model cannot capture. This design also supports online material identification on novel objects. MfM adapts from limited interactions, and its predictive uncertainty steers further exploration toward the regions where its estimate is least confident. Experiments on real deformable-object manipulation sequences show that PhysCoRe outperforms state-of-the-art baselines in prediction accuracy, and that its predicted confidence forms a reliable distribution across the object's geometry, providing a natural signal for future confidence-guided exploration.

World ModelsPhysics simulation
Haocheng Yin, Shuohan Tao, Yongsheng Chen · 521 views · Jul 22, 2026
Reinforcing Egocentric Spatial Perception in Multimodal Large Language Models via Ego Scene Augmentation

Reinforcing Egocentric Spatial Perception in Multimodal Large Language Models via Ego Scene Augmentation

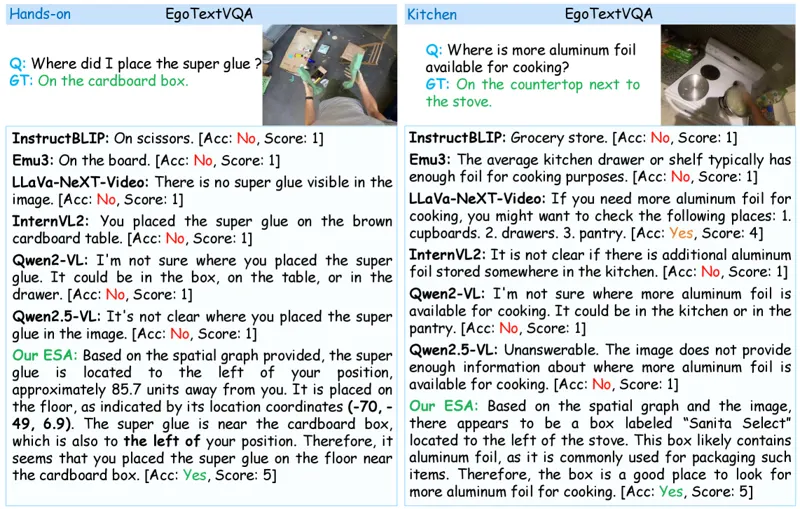
Egocentric Visual Question Answering (VQA) has attracted widespread attention as an important task for enabling Multimodal Large Language Models (MLLMs) to interact with the real world. However, existing MLLMs struggle to perform effective spatial reasoning in complex egocentric scenes due to their limited spatial perception capabilities. To this end, we introduce Ego Scene Augmentation (ESA), an egocentric spatial perception framework, which actively enhances the spatial perception capabilities from the egocentric perspective, powered by the proposed Ego-element Graph. Our core insight is leveraging the Ego-element Graph as an intermediary representation to augment the egocentric spatial perception of MLLMs via visual foundational models. Specifically, we 1) construct the Ego-element Graph, which encapsulates and integrates egocentric spatial features enabled by visual foundational models; 2) enhance the spatial perception capabilities of MLLMs via the Ego-element Graph for ego-perspective scenes. Our proposed ESA framework presents significant performance improvement on the EgoTextVQA benchmark. We achieve an 8.14% gain on the indoor setting and an 8.72% gain on the outdoor setting. Furthermore, our ESA shows the most impressive performance improvement in the shopping subset of the indoor setting. The project code is publicly available.

MLLMFirst-person
Chi Kit Wong, Ye Pan, Yuanhuiyi Lyu · 509 views · Jul 16, 2026
CosFly-VLA: A Spatially Aware Vision-Language-Action Model for UAV Tracking

CosFly-VLA: A Spatially Aware Vision-Language-Action Model for UAV Tracking

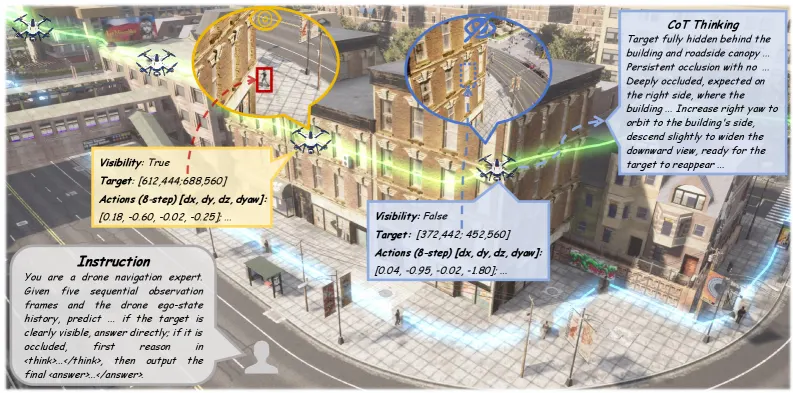
Dynamic target tracking is essential for Unmanned Aerial Vehicles (UAVs) operating in complex urban environments, where both the target and the camera viewpoint change continuously. Existing Vision-Language-Action (VLA) policies can track visible targets effectively, but their performance often degrades when buildings, vegetation, or roadside objects block the line of sight. During sustained occlusion, a policy may lose the target state, execute actions toward an incorrect region, and amplify this error through subsequent observations until re-acquisition becomes impossible. To this end, we present CosFly-VLA, a spatially aware VLA model that jointly grounds the target, estimates its visibility, and generates continuous flight actions through a structured prediction interface. To train this policy, we use a large-scale recipe over diverse data sources. Spatially Grounded Continued Pretraining (CPT) on a 500k mixed pool injects UAV-view depth, distance, and 3-D spatial reasoning. A three-stage Curriculum-based Supervised Fine-Tuning (SFT) process then specializes the tracker through multi-head warm-up followed by two-stage curriculum learning over natural and hard / long-occlusion data. Chain-of-Thought (CoT) training subsequently teaches recovery-oriented reasoning traces before structured answers. Finally, a closed-loop Reinforcement Learning (RL) stage optimizes tracking behavior with a multi-component reward covering stand-off tracking, grounding quality, collision avoidance, and task success. Relative to OpenVLA, CosFly-VLA-0.8B reduces open-loop Average Displacement Error (ADE) by 34.1% on seen-test and 35.3% on unseen-test. Closed-loop optimization improves Success Rate (SR) by 29.8% and 2.5%, respectively. These results demonstrate progress from visible-frame imitation toward spatially grounded action-closed-loop control, evaluated under a shared oracle state history.

UAVVLA
Ruilong Ren, Songsheng Cheng, Yunpeng Zhou · 645 views · Jul 16, 2026

As an Amazon Associate, we earn from qualifying purchases.