Skip to content
World Translation: Minimizing Sim-to-Real Gap with Backward Dynamics Extraction and Unpaired Domain Translation

World Translation: Minimizing Sim-to-Real Gap with Backward Dynamics Extraction and Unpaired Domain Translation

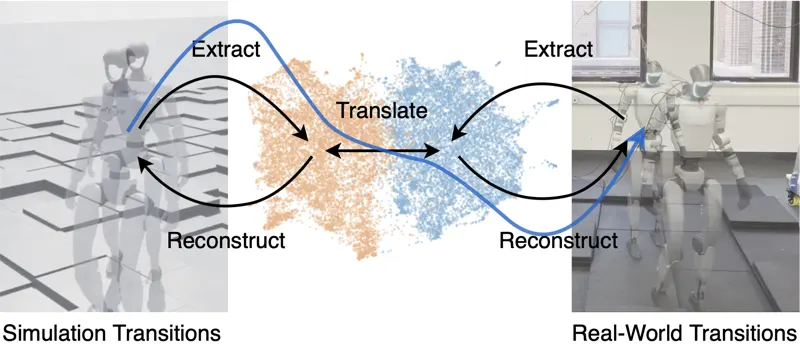
The gap between simulation and reality remains a fundamental challenge in deploying simulation-trained robotic policies in the real world. Real-to-sim methods narrow this gap from the real side, learning transition dynamics from real data to build a more realistic digital world. Learned dynamics models are their dominant instance. Such methods, however, face a partial observability problem: the same observation may branch to different transitions due to unobservable factors. Existing methods assume these factors can be recovered from observation history. However, this may fail whenever observation history is uninformative, such as a sudden contact event with no prior warning. To address this limitation, we propose World Translation, which exploits a complementary strength of simulators and learned dynamics. Simulators are deterministic but physically imperfect, while learned models are accurate but underdetermined under partial observability. Rather than predicting transitions forward from history, we extract the unobservable dynamics information backward from an observed transition, then translate this feature across simulation and reality as an unpaired domain-translation problem that preserves dynamics content while transferring domain style. Experiments across humanoid, quadruped, and manipulator platforms show that our method achieves more accurate dynamics modeling than baselines, with the largest gains when unobservable factors cannot be recovered from observation history. Real-robot deployment on Go2 quadruped confirms improved policy transfer.

Sim-to-RealDomain Adaptation
Xinchen Yao, Leixin Chang, Hua Chen · 499 views · Jul 20, 2026
Learning Adaptive Safety Margins for Visual Navigation

Learning Adaptive Safety Margins for Visual Navigation

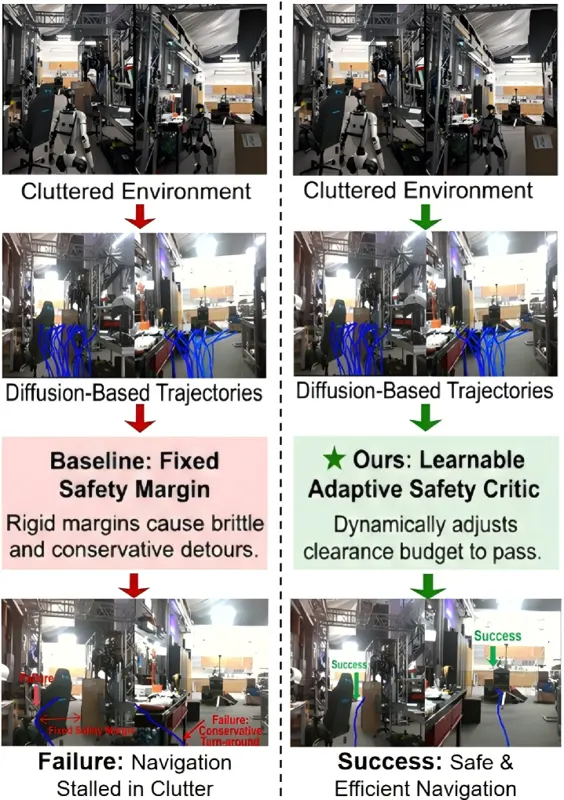
Robots in cluttered indoor spaces often fail not because they cannot generate collision-free paths, but because a fixed safety margin is mis-calibrated: conservative margins cause detours and timeouts, while permissive margins lead to near-boundary shortcuts under perception bias. Diffusion-based planners propose diverse trajectory candidates from egocentric RGB-D, yet reliable selection remains the bottleneck. We propose a context-conditioned safety critic that learns an adaptive clearance preference for ranking diffusion proposals, decomposed into three complementary terms: (i) a safety term with a clearance-budget penalty and a control-barrier-function residual for waypoint- and transition-wise safety, (ii) an efficiency term combining a smoothness penalty with a safety-gated detour-ratio penalty that avoids detours without incentivizing risky shortcuts, and (iii) a distance-constraint matching term that anchors the learned budget to realized ESDF clearances to prevent margin collapse. We train the critic with privileged ESDF geometry in simulation and distill it into a perception-only selector via a two-stage teacher-student procedure. On PointGoal navigation in HM3D and MP3D, including cross-dataset transfer, our method achieves the highest success rate (SR) and success weighted by path length (SPL) among strong diffusion, optimization, and RL baselines. Trained purely in simulation, it transfers to a Unitree G1 humanoid and navigates cluttered indoor scenes without task-specific tuning.

Visual navigationSafety Margin
Junyi Hu, Shuaihang Yuan, Geeta Chandra Raju Bethala · 431 views · Jul 20, 2026
Agentic Real2Sim: Physics-based World Modeling with Vision-Language Agents

Agentic Real2Sim: Physics-based World Modeling with Vision-Language Agents

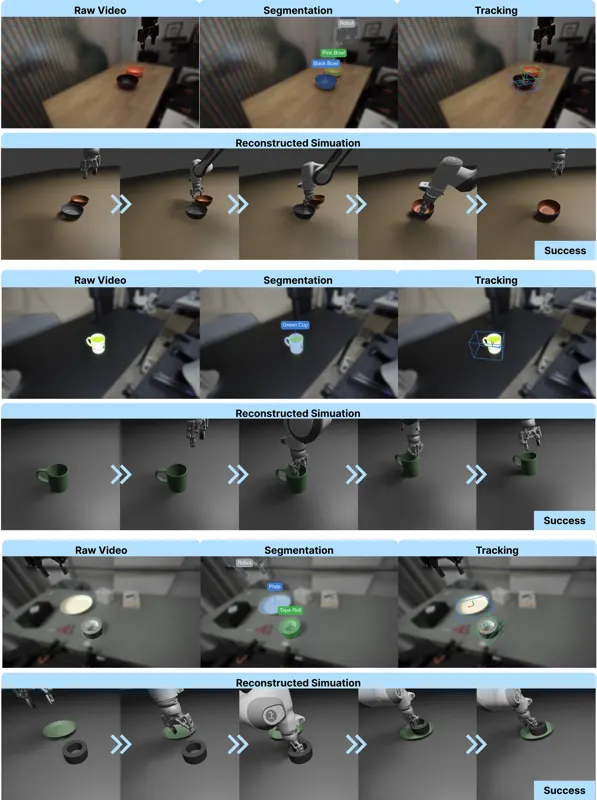
Real-to-sim conversion for robotic interaction with objects remains labor-intensive because it requires more than visual reconstruction: a streamlined real2sim process must recover scene geometries and object states, infer physical parameters, and assemble actors, objects, cameras, poses, and trajectories into a runnable physical simulation. Today this process still depends on manual tuning of visual foundation models, mesh cleanup, coordinate-frame alignment, and brittle workflow glue across visual perception tools and simulators. We introduce Agentic Real2Sim, a framework for generalized physical world modeling with vision-language agents, converting a real-world recording of object-robot interaction into a simulatable episodic twin which preserves observations, geometries, robot interactions, and object states. We evaluate Agentic Real2Sim on rigid-object manipulation, deformable-object interaction, and humanoid motion scenes, spanning domains that are usually handled by separate Real2Sim pipelines, marking a first step toward scalable conversion. The framework's agentic decisions can be driven by an open-weight VLM backend at a small fraction of the cost of frontier models, while attaining comparable conversion success rate. We aim to use the resulting real-world-aligned twins for downstream robotics tasks, specifically policy learning and evaluation. The project site is available at https://agentic-real2sim.github.io/.

Sim-to-RealWorld Models
Guanxiong Chen, Qianjun Xia, Jiawei Peng · 474 views · Jul 21, 2026
Extreme-RGMT: Continual Learning of Highly Dynamic Skills for Robust Generalist Humanoid Control

Extreme-RGMT: Continual Learning of Highly Dynamic Skills for Robust Generalist Humanoid Control

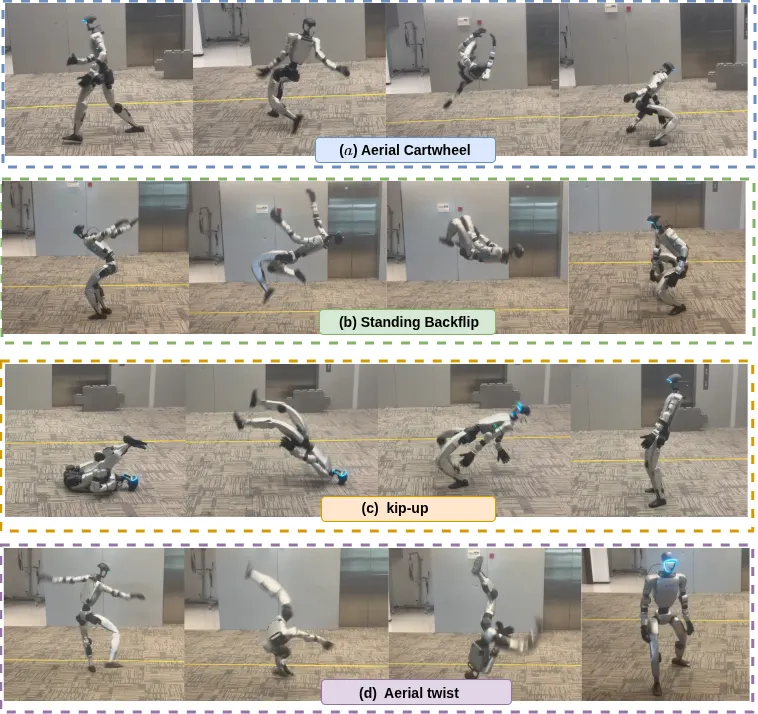
Humans can progressively acquire highly dynamic motor skills while preserving reliable everyday motor abilities. In contrast, existing humanoid controllers face a trade-off between generalist and specialist capabilities: generalist motion tracking policies struggle to reliably execute rare highly dynamic motions, whereas specialist training can degrade previously acquired behaviors. We introduce Extreme-RGMT, a two-stage continual learning framework for robust generalist humanoid control. The method first learns a generalist motion-tracking base policy from diverse multi-source motion data, then employs an asymmetric skill acquisition and capability consolidation mechanism to constrain policy drift on mastered motions while emphasizing difficult dynamic segments. To address the scarcity of highly dynamic motions, their high failure rates, and the resulting shortage of informative samples, Extreme-RGMT combines difficulty-aware sampling with advantage-prioritized trajectory resampling to emphasize critical segments. Experiments show that Extreme-RGMT achieves state-of-the-art generalist whole-body motion-tracking performance, including substantially improved completion of challenging highly dynamic motions. The resulting controller directly executes diverse unseen highly dynamic motions under fixed references and online inertial motion-capture inputs, advancing generalist whole-body motion-tracking controllers toward highly dynamic motor capabilities at the human-expert level.

HumanoidContinual learning
Yubiao Ma, Han Yu, Kai Guo · 469 views · Jul 22, 2026
STeP: Signal Temporal Logic for Precise Specifications for Action Generation with Vision Language Models

STeP: Signal Temporal Logic for Precise Specifications for Action Generation with Vision Language Models

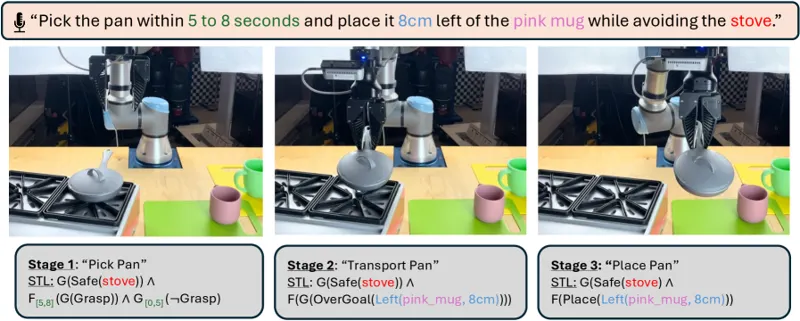
Vision-language-action (VLA) models have shown impressive generalization, but often lack interpretability and can struggle to follow precise natural language instructions that encode spatial, temporal, and logical requirements. We propose a hierarchical framework that uses Signal Temporal Logic (STL) as a shared representation connecting high-level language understanding with low-level robot execution. A high-level policy leverages a VLM to decompose language instructions into high-level subtasks, generate STL specifications for each subtask, and choose a low-level policy for executing each subtask. The STL specifications translate language-derived intent into precise constraints, and the low-level policy selection determines whether those constraints are enforced directly through STL-guided model-predictive control or monitored during execution of a learned policy for perceptually complex, or contact-rich behaviors. By integrating STL into plan validation, low-level policy, subtask monitoring, and replanning, our framework enables language-derived plans to be checked, optimized, and revised at runtime using a common formal structure. We evaluate the approach on a real-world tabletop domain, demonstrating how formal specifications can improve the precision, reliability, and interpretability of language-conditioned robot planning.

Vision-language modelsTemporal Logic
Kasra Torshizi, Anukriti Singh, Sidharth Mathur · 461 views · Jul 20, 2026
RoboInter1.5: A Holistic Intermediate Representation Suite for Embodied World Modeling and Robotic Manipulation

RoboInter1.5: A Holistic Intermediate Representation Suite for Embodied World Modeling and Robotic Manipulation

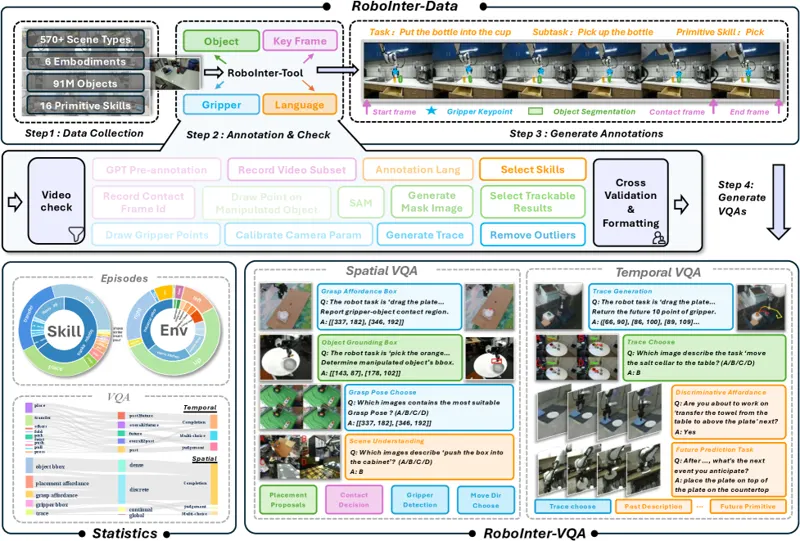
Existing robot datasets remain expensive to curate, embodiment-specific, and insufficiently annotated with the fine-grained structure required for generalizable reasoning, execution, or long-horizon environment dynamics simulation. Building on our prior work, RoboInter1.0, we present RoboInter1.5, an extended and holistic suite of intermediate representations for both robotic manipulation and embodied world modeling. RoboInter1.5 provides a unified resource of data, benchmarks, and models centered on dense manipulation-oriented intermediate representations. Specifically, RoboInter-Data contains over 230k manipulation episodes across 571 scenes with dense per-frame annotations covering more than ten types of intermediate representations, including subtasks, primitive skills, object and gripper grounding, segmentation, affordance, grasp poses, contact points, motion traces, etc. Built upon these annotations, RoboInter-VQA introduces spatial and temporal embodied VQA tasks to benchmark and improve the intermediate-representation reasoning capabilities of our RoboInter-VLM. RoboInter-VLA further studies how such representations benefit action execution through implicit, explicit, and modular plan-then-execute paradigms. To better model the physical world, we further introduce RoboInter-World, which leverages intermediate representations as structured conditioning signals for controllable prediction of future world states. Extensive evaluations demonstrate that RoboInter1.5 provides a unified spatiotemporal scaffolding for intermediate representations. Rather than treating intermediate representations merely as interpretable signals, RoboInter1.5 conceptualizes them as a bidirectional interface that both regularizes low-level action spaces and constrains the latent rollouts of open-world physical simulators.

Robot InteractionRepresentation Learning
Ziqin Wang, Hao Li, Weijun Wang · 359 views · Jul 21, 2026
ReferTrack: Referring Then Tracking for Embodied Visual Tracking

ReferTrack: Referring Then Tracking for Embodied Visual Tracking

Embodied visual tracking (EVT) requires a mobile agent to continuously follow a specific target described in natural language using only onboard vision. While recent vision-language-action (VLA) policies unify target identification and trajectory planning, their chain-of-thought (CoT) reasoning often operates in abstract spatial latents that are difficult to supervise and weakly aligned with explicit image-space detections. To address this, we introduce ReferTrack, a referring-then-tracking paradigm that grounds EVT using a single forward-facing camera. Our model first selects the target from an indexed set of bounding boxes, then decodes tracking waypoints conditioned on this image-grounded decision. To preserve target motion cues over time, ReferTrack maintains a sliding-window queue of previously selected bounding boxes, injecting their geometric features into the visual history via temporal-viewpoint-bbox indicator (TVBI) tokens. We further enhance target identification by co-training on a custom Refer-QA dataset. On EVT-Bench, ReferTrack achieves state-of-the-art single-view performance with success rates of 89.4%, 73.3%, and 74.1% on the single-target, distracted, and ambiguity tracking splits, respectively – matching or even surpassing several multi-camera baselines on identification-heavy tasks. Finally, real-world deployments on legged and humanoid robots validate its robust sim-to-real transfer capabilities. Code is available at https://github.com/MedlarTea/referTrack.

VLAObject tracking
Hanjing Ye, Tianle Zeng, Jiazhao Zhang · 422 views · Jul 22, 2026

As an Amazon Associate, we earn from qualifying purchases.