Skip to content
MEVION: Low-Cost Open-Source Data Collection System for Powerful and High-Speed Dual-Arm Manipulation

MEVION: Low-Cost Open-Source Data Collection System for Powerful and High-Speed Dual-Arm Manipulation

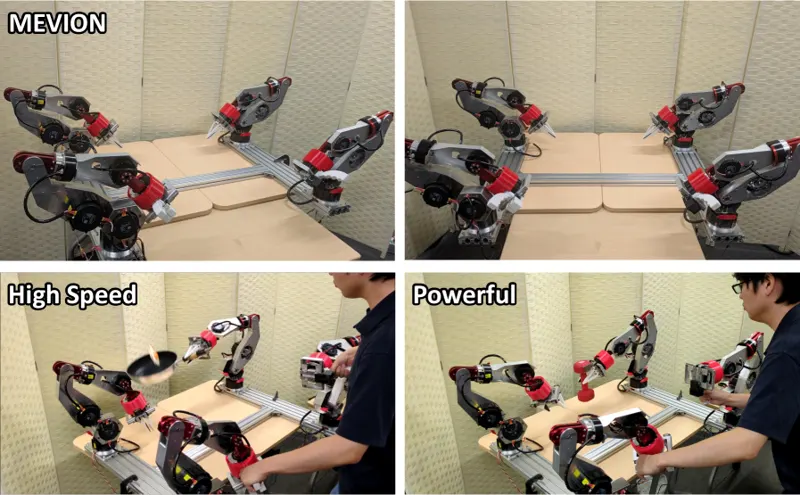
The global competition for developing robotic foundation models is intensifying. Among the data collection systems used for dual-arm robots, ALOHA is representative of being low-cost and open-source, and is widely adopted by researchers as a de facto standard. However, due to its limited ability to generate high forces and speeds, it is difficult to handle heavy objects or perform fast manipulations. To address this, we developed MEVION, a low-cost and open-source dual-arm robot data collection system capable of generating greater force and speed. All parts of this robot can be sourced through e-commerce, and by extensively utilizing sheet metal welding, its large body structure is constructed with a small number of components at low cost, while also simplifying assembly. MEVION is equipped with four 6-DoF arms with parallel grippers. Each arm weighs 7.0 kg and has a maximum torque of 60 Nm, and the entire system can be constructed for about USD 14,000. The elbow joint adopts a closed-link mechanism similar to those used in quadruped robots, which reduces the distal mass and enables higher force and speed output at the end-effector. We demonstrate that MEVION enables data collection for object manipulation tasks not previously possible and supports imitation learning-based motion generation. All hardware and software of this work are included in the Supplementary Materials or https://github.com/haraduka/mevion.

Data CollectionDual-Arm
Kento Kawaharazuka, Yoshiki Obinata, Hirokazu Ishida · 476 views · Jul 20, 2026
PAVXploreRL: Physical-Action-Visual World Model Reinforcement Learning with Action Exploration

PAVXploreRL: Physical-Action-Visual World Model Reinforcement Learning with Action Exploration

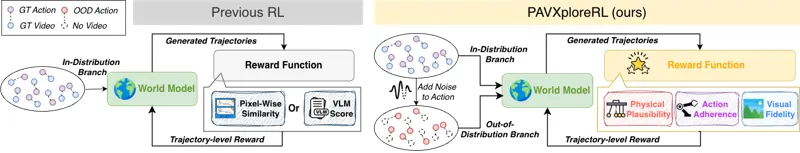
Action-conditioned world models are a key component of embodied AI, serving as scalable policy evaluators that reduce reliance on expensive real-world rollouts. To accurately capture diverse action-induced dynamics, such models should satisfy three key objectives-Physical Plausibility (P), Action Adherence (A), and Visual Fidelity (V), collectively referred to as PAV-while remaining robust to both in-distribution (ID) expert demonstrations and out-of-distribution (OOD) actions. However, existing methods primarily rely on ID action-video pairs and pixel-level reconstruction losses, which do not explicitly optimize PAV objectives and generalize poorly beyond expert data. To address this, we propose PAVXploreRL, a reinforcement learning framework built on a pretrained latent world model that explicitly optimizes PAV objectives through reward-driven training. To improve action generalization, our method jointly leverages ID trajectories and noise-driven OOD action exploration, without paired video supervision. Experiments show that PAVXploreRL consistently outperforms pretrained baselines, achieving a 5.6% average gain across benchmarks and producing higher-quality PAV properties. As a policy evaluator, it also yields more reliable performance estimates and reduces the overestimation bias of prior expert-only world models such as Ctrl-World. Code: https://github.com/Social-AI-Studio/PAVXploreRL

World ModelsReinforcement Learning
Han Wang, Zijun Wang, Shuoshuo Xue · 321 views · Jul 18, 2026
Athena-Brain Technical Report: An Efficient Robot Brain for General Intelligence and Embodied Interaction

Athena-Brain Technical Report: An Efficient Robot Brain for General Intelligence and Embodied Interaction

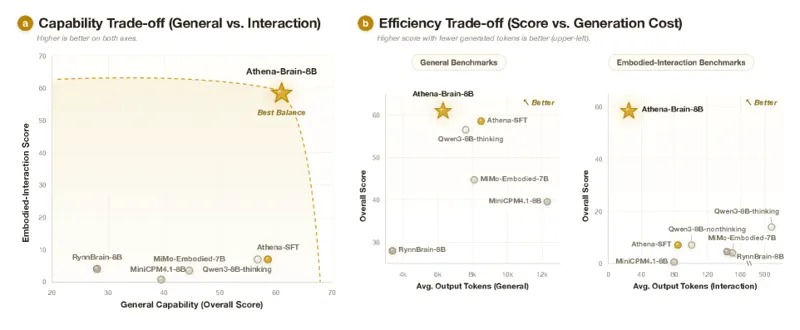
Large language models (LLMs) have demonstrated remarkable capabilities in language understanding, reasoning, and world knowledge. As embodied agents become increasingly capable, there is a growing demand for compact models that can serve as an on-device brain, preserving the broad general intelligence of LLMs while enabling effective high-level interaction with embodied environments. Existing approaches, however, often prioritize either general-purpose intelligence or specialized embodied capabilities, making it challenging to satisfy both requirements within a single model. We present Athena-Brain-8B, an 8B LLM designed to serve as an on-device brain for embodied intelligence for embodied intelligence. Through a multi-stage post-training pipeline consisting of General Supervised Fine-Tuning, General Reinforcement Learning, Embodied Expert training, and Model Merge, Athena-Brain-8B maintains strong general capabilities while acquiring strong high-level embodied interaction capabilities and generating concise responses for efficient embodied interaction. Experimental results demonstrate the effectiveness of Athena across both general and embodied evaluations. Compared with the corresponding Qwen3-8B thinking model, Athena-Brain-8B achieves comparable performance on general language and reasoning benchmarks while generating substantially shorter responses. On in-domain embodied benchmarks, Athena-Brain-8B consistently outperforms models of similar scale and surpasses several substantially larger frontier models evaluated zero-shot, demonstrating that compact language models can effectively integrate strong general intelligence with embodied capabilities.

Embodied AIRobot Brain
Jialian Li, Junhong Liu, Yuchen Cao · 315 views · Jul 21, 2026
EA-Nav: Learning Safe Visual Navigation Policies with Embodiment Awareness

EA-Nav: Learning Safe Visual Navigation Policies with Embodiment Awareness

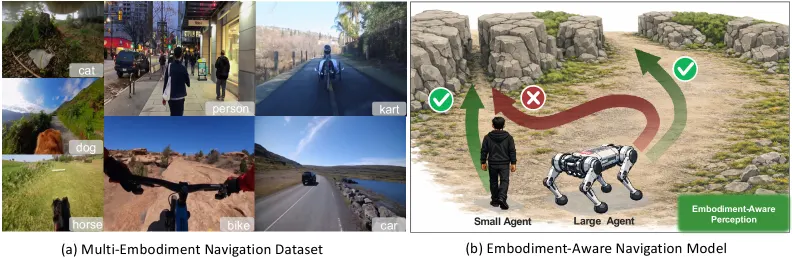
Cross-embodiment navigation is a key challenge in embodied intelligence. Due to differences in embodiment, the same visual observation may imply different actions for different agents, making prediction ambiguous when relying solely on vision. Existing studies mainly rely on reinforcement learning, which requires large-scale interaction and careful reward design, making it difficult to support scalable pretraining and real-world adaptation. In contrast, imitation-learning-based approaches remain limited. To address these challenges, we propose an imitation-learning-based embodiment-aware navigation framework with a modular multi-stage design. In pretraining, we construct a cross-embodiment navigation dataset from Internet videos and introduce embodiment geometry as conditional tokens to reduce action ambiguity under the same observation. In fine-tuning, we design a multimodal information injection mechanism based on a decoupled architecture. Specifically, we design a trajectory augmentation strategy to generate high-risk samples, which are used to train spatial perception and risk-aware correction separately, thereby explicitly incorporating embodiment geometry for safe navigation. Experimental results show that the proposed method effectively improves navigation performance across different embodiment settings, demonstrating the effectiveness of incorporating embodiment geometry into embodied navigation.

Visual navigationBody-Awareness
Jialu Zhang, Yong Du, Xianda Guo · 410 views · Jul 22, 2026
Look Before You Edit: Attention-Guided Camera Placement and Multi-View Alignment for 3D Gaussian Splatting Editing

Look Before You Edit: Attention-Guided Camera Placement and Multi-View Alignment for 3D Gaussian Splatting Editing

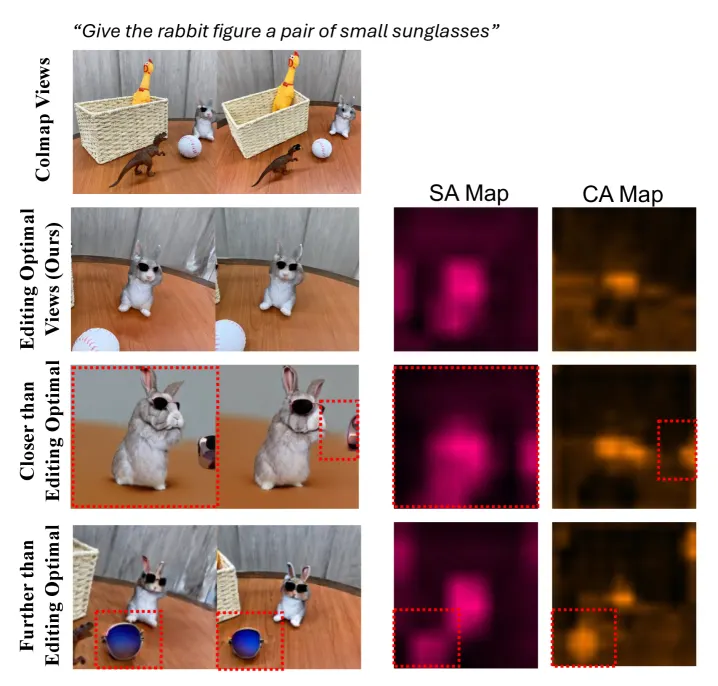
Text-driven 3D scene editing with 3D Gaussian Splatting (3DGS) typically applies a 2D diffusion editor to views rendered from fixed training cameras, limiting both the spatial coverage of edits and the user's freedom to target specific objects in complex scenes. We present LB-Edit, a framework that addresses two coupled problems: where to place editing cameras for localized edits, and how to make per-view edits agree with one another so that the 3D scene remains consistent after fine-tuning. First, Attention-Guided Editing Camera Placement (ACP) probes the diffusion model's self- and cross-attention at multiple candidate camera distances to find where attention is well-contained in the region of interest, then places a compact, geometrically diverse editing camera set at that attention-optimal distance. Second, Multi-view Attention Alignment (MAA) steers the editor toward the same edit across views along two axes: it aligns appearance by sharing self-attention features via token-level correspondence, and aligns spatial location by lifting cross-attention maps onto the 3D Gaussians as a shared 3D attention field, suppressing both appearance and spatial drift. Experiments on multi-object and single-object scenes show that our method achieves the highest user preference in instruction fidelity, multi-view consistency, and editing locality, using as few as 5 editing views and reducing latency by up to 7x over existing methods.

3D Gaussian SplattingScene Editing
Jaeyeon Park, Taeho Kang, Youngki Lee · 391 views · Jul 22, 2026
ATSplat: Compact Feed-forward 3D Gaussian Splatting with Adaptive Token Expansion

ATSplat: Compact Feed-forward 3D Gaussian Splatting with Adaptive Token Expansion

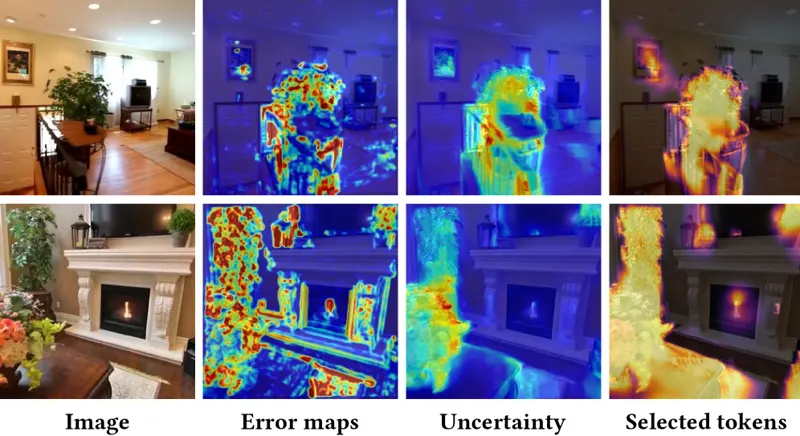
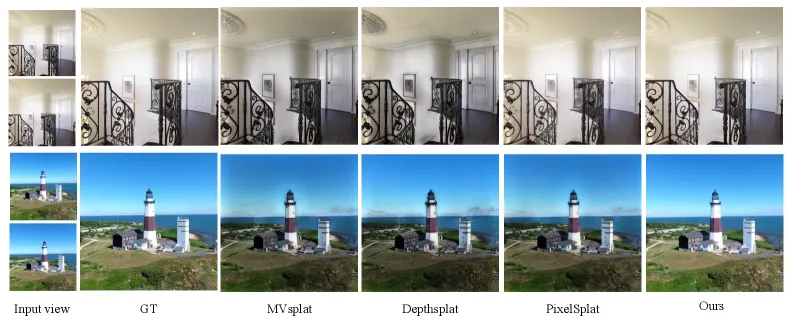
3D Gaussian Splatting (3DGS) achieves high-quality novel-view synthesis by optimizing freely placed primitives in 3D and adaptively densifying them in under-reconstructed regions. However, this scene-adaptive capacity allocation is largely lost in existing feed-forward 3DGS methods, which commonly regress Gaussians at input pixels and lift them along camera rays. Such pixel-aligned formulations make the number and placement of primitives depend on image resolution and input viewpoints rather than scene complexity, resulting in dense and often redundant Gaussian sets. We present ATSplat, a feed-forward 3DGS framework that restores the adaptive allocation capability of 3DGS optimization through Adaptive 3D Tokens. ATSplat first lifts coarse patch-level depth and camera cues into sparse 3D anchor tokens, forming a compact scaffold of the scene. Each token is then regressed into local Gaussians with learnable 3D offsets, decoupling primitive placement from input image grids. An Adaptive Token Expansion module predicts a token-level uncertainty score, supervised by rendering error maps, and selectively expands high-uncertainty tokens through learnable expansion layers. This sparse-to-adaptive formulation enables ATSplat to concentrate primitives in challenging regions while maintaining a compact representation. Experiments on two representative datasets, RealEstate10K and DL3DV, show that ATSplat achieves state-of-the-art rendering quality while reducing the number of Gaussians by more than 5.7× compared with dense feed-forward 3DGS methods. From 12 input images at 512 × 960 resolution, ATSplat completes reconstruction in less than a second using a single commercial GPU, and renders high-quality novel views at 1136 FPS (512 × 960) with only 311K Gaussians.

3D Gaussian Splattingtoken
Cho In, Jeonghwan Cho, Mijin Yoo · 531 views · Jul 22, 2026
GLAM-SLAM: Real-time Gaussian Large-scale Mapping via Flow Densification and Spatial Decomposition

GLAM-SLAM: Real-time Gaussian Large-scale Mapping via Flow Densification and Spatial Decomposition

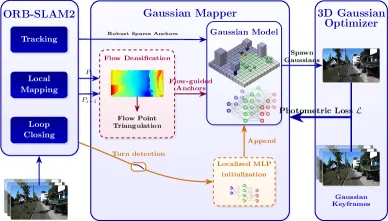
Existing Gaussian-splatting-based monocular Simultaneous Localization and Mapping (SLAM) systems are either tailored to short sequences, are not real-time, or suffer from prohibitive GPU memory requirements, limiting their applicability in realistic, long-horizon scenarios. To address this, we present GLAM-SLAM, a real-time, decoupled Gaussian-splatting SLAM system designed for large-scale outdoor scenes. We ensure lightweight tracking using a robust, feature-based SLAM frontend, while for mapping, we adopt a structured, sparse anchor grid representation that ensures scalable operation and maintains scene coherence across long-term sequences. To satisfy the dense initialization requirements of 3D Gaussian Splatting (3DGS), we introduce a geometry-based flow-densification anchoring strategy using epipolar constraints. Furthermore, by treating mapping as a multi-scene problem, we propose a scene-partitioning strategy that introduces a strong spatial inductive bias via MLP initializations to generate localized Gaussians. We evaluate our system on the challenging, long-sequence KITTI Odometry, Oxford RobotCar, and M'alaga datasets. Extensive ablations and comparisons demonstrate a 15% improvement in reconstruction quality over the second-best performer, while maintaining real-time performance and the ability to scale to longer sequences. Code is publicly available for the benefit of the community.

3D Gaussian SplattingSLAM
Panagiotis Mermigkas, Argyris Manetas, Petros Maragos · 480 views · Jul 23, 2026
GrainGS: Gradient-Decoupled Gaussian Splatting for Efficient Dynamic Novel View Synthesis

GrainGS: Gradient-Decoupled Gaussian Splatting for Efficient Dynamic Novel View Synthesis

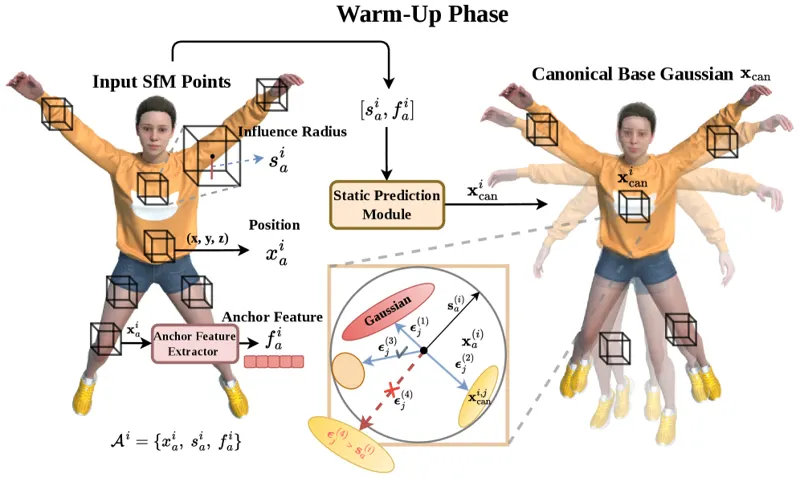
Dynamic scene reconstruction with 3D Gaussian Splatting requires a balance between fine-grained motion modeling, structural stability, and compact representation. Existing per-primitive methods provide flexible local deformation but often suffer from redundant primitive growth, while anchor-based methods improve spatial regularity at the cost of suppressing locally varying motion. To address these issues, we present GrainGS, a dynamic Gaussian framework that combines a hierarchical anchor scaffold with per-Gaussian deformation. A static warm-up stage first establishes a time-invariant canonical representation from observations across all timestamps. During joint training, a stop-gradient operation blocks the deformation-mediated gradient pathway to the canonical positions while preserving their direct refinement through the reconstruction objective. Each Gaussian then predicts independent temporal offsets for position, rotation, and scale, enabling detailed local motion within a structurally constrained scaffold. A canonical-residual appearance decomposition further models frame-dependent photometric changes without forcing them into geometric deformation. Experiments on synthetic monocular and real-world multiview benchmarks show that GrainGS achieves high reconstruction quality, real-time novel view synthesis, and compact storage. Under the synthetic benchmark setting, it reaches an average peak signal-to-noise ratio of 36.98 decibels, renders at 435.6 frames per second, and requires 4.67 megabytes of storage.

3D Gaussian SplattingDynamic Scene
Jiahao He, Yihua Shao, Zhengkai Zhao · 380 views · Jul 23, 2026
GS-Agent: Creating 4D Physical Worlds With Generative Simulation

GS-Agent: Creating 4D Physical Worlds With Generative Simulation

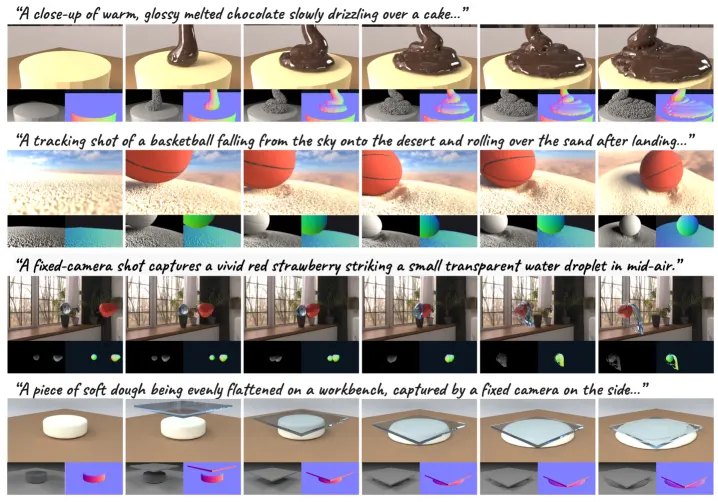
Creating dynamic and physically realistic 4D worlds from natural language descriptions is both fascinating and challenging. Traditional computer graphics methods rely on manual creation, requiring extensive human effort to fine-tune materials, motions, and visual fidelity. Recent advances in generative foundation models have sparked interest in learning to generate such 4D worlds from large-scale data; however, existing methods still struggle to ensure physical plausibility and controllability. In this work, we take a different path by leveraging foundation models to construct an agentic system that emulates how humans traditionally create 4D worlds, yet automates the entire process. We present GS-Agent, an end-to-end multi-agent framework that integrates physics engines in the loop to generate realistic, dynamic, and controllable 4D physical worlds from natural language. Inspired by how humans build 4D worlds, GS-Agent decomposes the task into entity management, covering 3D asset curation, material tuning, placement, and motion control, and rendering configuration, including camera and lighting manipulation. Multiple agents with distinct expertise interact with the physics engine via code, seek multimodal feedback, and collaborate to iteratively construct 4D worlds that align with the given descriptions. Experimental results show that GS-Agent effectively converts natural language into diverse and physically plausible 4D worlds exhibiting rich interactions among liquids, deformable objects, and rigid bodies, while achieving cinematic camera and lighting control. We envision GS-Agent as a foundation for a new paradigm in 4D world generation, empowering creative content creation and physical AI. Project page at https://umass-embodied-agi.github.io/gs-agent/

3D Gaussian Splatting4D Generation
Hongxin Zhang, Chunru Lin, Junyan Li · 526 views · Jul 23, 2026

As an Amazon Associate, we earn from qualifying purchases.