Skip to content
GigaBrain-0.7: Scaling Embodied Foundation Models to Emergent Capabilities with a Three-System Architecture

GigaBrain-0.7: Scaling Embodied Foundation Models to Emergent Capabilities with a Three-System Architecture

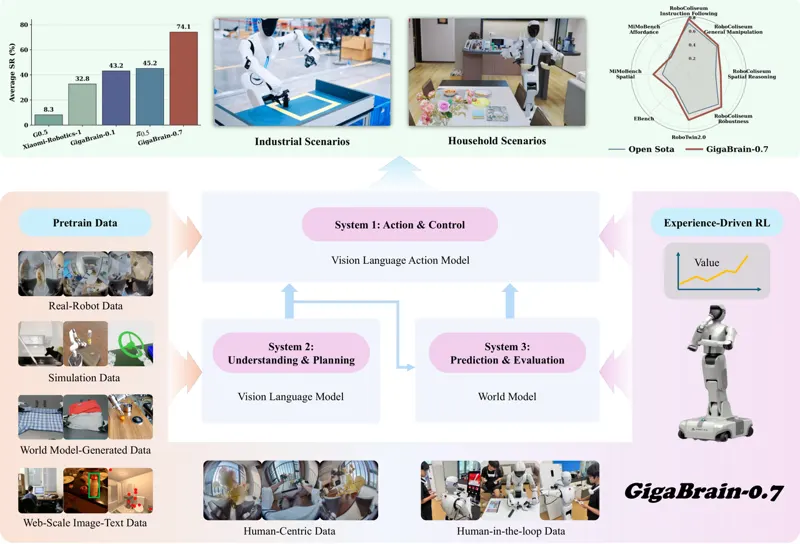
Vision-language-action (VLA) models have become a dominant paradigm for generalist embodied agents, demonstrating strong complex and long-horizon task completion in structured settings. Yet it remains an open question whether current VLA systems can benefit from more effective architectural design, scale to substantially larger and more heterogeneous data regimes, and achieve broader generalization across tasks and embodiments. To this end, we present GigaBrain-0.7, an embodied foundation model with substantially improved generalization across diverse robot embodiments. Specifically, GigaBrain-0.7 unifies understanding, prediction, and action through a three-system architecture, scales pretraining to over 37,000 hours of heterogeneous embodied data, and introduces one-stage alignment training that jointly optimizes vision-language understanding and multi-embodiment action generation. Compared with the preceding GigaBrain-0 series and prior state-of-the-art models including π_0.5, GigaBrain-0.7 achieves substantial improvements in foundation zero-shot capabilities, language-conditioned instruction following, and post-training task success rates. In particular, on our in-house Maker H01 platform and mainstream robot embodiments, GigaBrain-0.7 demonstrates strong task adaptability and completion ability across both home and industrial scenarios. All training code and pretrained model weights will be released.

VLAGigaBrain
GigaBrain Team, Angen Ye, Axiang Sun · 911 views · Aug 16, 2026
Zero-WAM: In-Context World-Action Modeling from Human Videos for Open-Ended Task Generalization

Zero-WAM: In-Context World-Action Modeling from Human Videos for Open-Ended Task Generalization

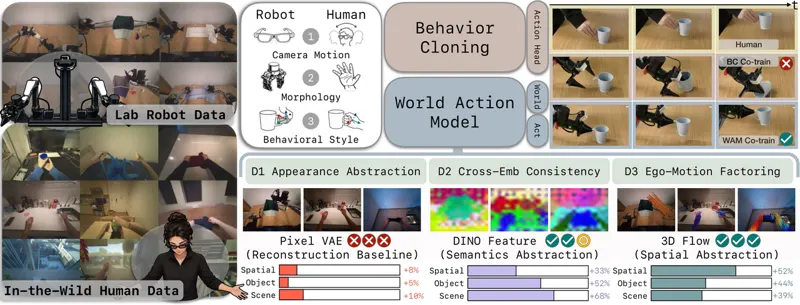
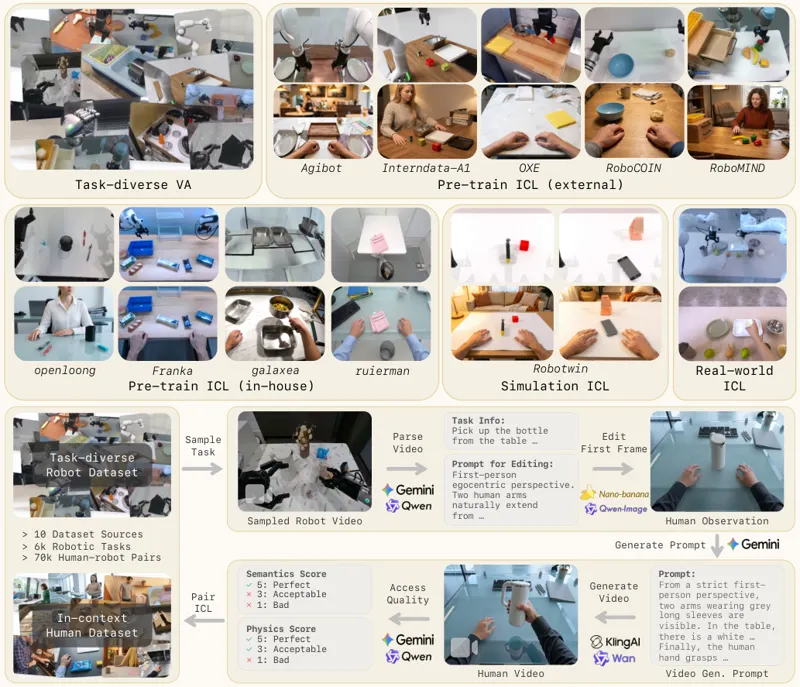
Zero-shot cross-task generalization, where a policy must execute manipulation tasks never seen during training, remains a central challenge in robot learning. In large language models, a novel task can be performed simply by specifying it in the context, without any parameter update. This form of in-context learning (ICL) turns generalization into a problem of task specification. To achieve cross-task generalization, we bring this paradigm to robotic manipulation, and argue that the natural task specification for manipulation is a human video: unlike language, it provides rich visual cues about the intended task evolution. We present Zero-WAM, a causal video-action model that executes unseen tasks by following in-context human video guidance. To address the scarcity of task-rich paired human-robot data, we propose an automatic pipeline that converts task-sampled robot trajectories into semantically matched human videos, yielding HumanGen, a dataset of 74.2K human-robot ICL pairs across 8.6K tasks. For model training, we further introduce an in-context future chunk prediction (IFP) objective that suppresses shortcuts learned from seen tasks and forces the policy to draw task information from the video prompt. On seven unseen tasks in RoboTwin 2.0 simulation, Zero-WAM achieves a 47.0% average success rate, an absolute improvement of 29.5 percentage points over the strongest video-action baseline. In real-world evaluations, it follows human video guidance to generalize to unseen task configurations involving multi-object scenes, long-horizon manipulation, and fine-grained insertion.

Zero-WAMHumanGen
Jiaming Zhou, Qihang Zhang, Gangwei Xu · 710 views · Aug 26, 2026
PhyAI: Real-Time Physical AI at the Edge, Scalable Rollouts in the Cloud

PhyAI: Real-Time Physical AI at the Edge, Scalable Rollouts in the Cloud

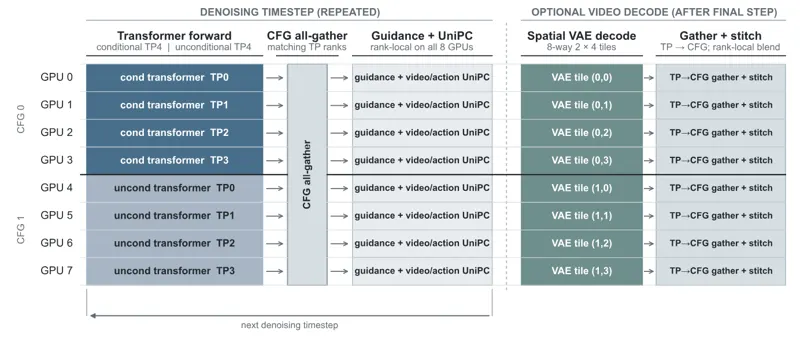
Physical AI policies require inference throughout their lifecycle, including model evaluation, cloud reinforcement learning rollout, edge GPU serving, and onboard deployment. Although these settings share the same checkpoint and action semantics, they often rely on separate inference programs. To unify them, we build PhyAI, a Physical AI inference engine with a single runtime that keeps architecture-specific conditioning, solver, cache, and output logic in model adapters while sharing graph execution, kernels, memory management, and parallel services. The same codebase runs vision-language-action (VLA) models and world-action models (WAMs) on single or multiple GPUs across onboard, edge, and cloud deployments. We used the adapter interface to add MiniCPM-Robot on the day of its release. PhyAI achieves 1.40x-4.65x speedups over the official implementations of pi0, pi0.5, GR00T N1.7, and MiniCPM-Robot. On Cosmos3-Nano-Policy-DROID it reduces latency from 2.46 to 1.18 s on eight H20 GPUs (CFG=2, TP=4), a 2.08x speedup. Specialized runtimes remain faster in several configurations, so our goal is one runtime with competitive latency rather than the fastest result in every case. Detailed profiles reveal why different models need different execution policies: on a Hopper-series GPU at batch size one, the pi0.5 action expert accounts for 8.8% of FLOPs but 57.2% of latency; at batch size 32 its share drops to 13.5% and throughput reaches about 100 samples/s. Cosmos3 remains generation-dominated and gains only 14.3% throughput as batch size increases from 1 to 16. We further introduce the control-time Roofline, which distinguishes inference-bound from environment-bound control; the measured pi0.5 points on four LIBERO suites are environment-bound while Cosmos3 stays inference-bound. Code and benchmarks: https://github.com/mingti-org/phyai.

Physical AIVLA
Chenghua Wang, Daliang Xu, Dongqi Cai · 720 views · Aug 4, 2026

As an Amazon Associate, we earn from qualifying purchases.