Skip to content
HAF: Adapting Generalist VLAs to Humanoid Whole-Body Loco-manipulation via Hierarchical Action Flow and Spectral Latent RL

HAF: Adapting Generalist VLAs to Humanoid Whole-Body Loco-manipulation via Hierarchical Action Flow and Spectral Latent RL

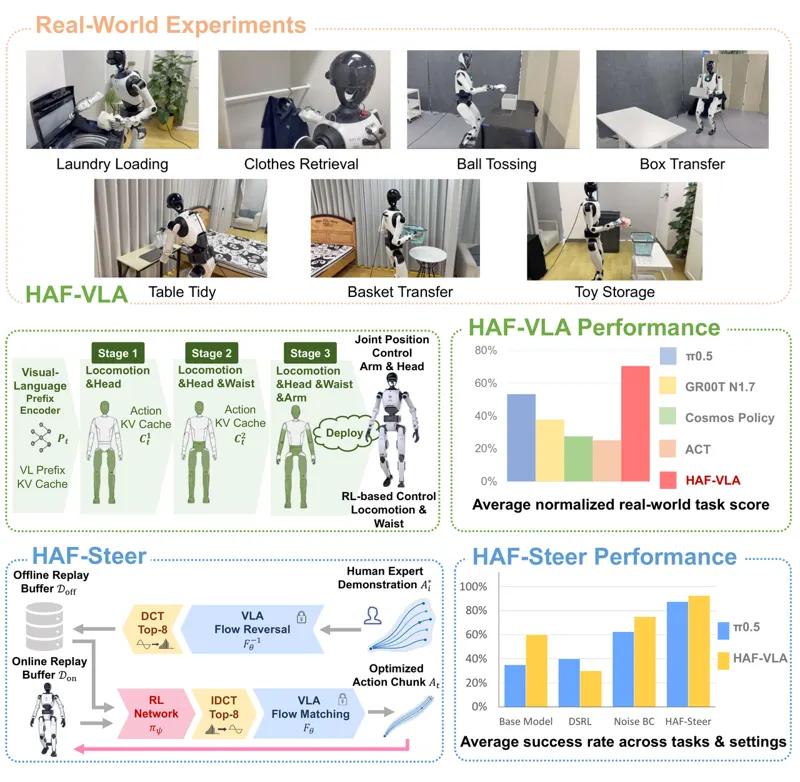
Humanoid robots hold great promise as general-purpose agents in human-centered environments, yet generalist vision-language-action (VLA) foundation models are not readily applicable to humanoid whole-body loco-manipulation. The high dimensionality and interdependence of humanoid motions make it challenging for conventional single-stage VLA architectures to coordinate locomotion, waist posture, and dual-arm manipulation effectively. Moreover, policies trained through offline behavior cloning can remain suboptimal during real-world deployment. Although online reinforcement learning can refine policies through real-world interaction, directly tuning large VLA backbones demands excessive computation and may introduce safety risks during real-robot exploration. To address these bottlenecks, we introduce HAF (Humanoid Adaptation Framework), a two-part framework consisting of HAF-VLA and HAF-Steer that transfers off-the-shelf generalist VLA foundation models to humanoid whole-body loco-manipulation. HAF-VLA is a hierarchical action-flow generator built on a pretrained flow-matching VLA. It splits full-body action denoising into three sequential stages with stage embeddings and cross-stage KV caches that retain kinematic dependencies, avoiding incoherent whole-body actions from one-shot generation. On top of the frozen HAF-VLA, HAF-Steer is a latent offline-to-online RL pipeline that leverages flow-matching invertibility and DCT-based dimensionality reduction to restrict RL optimization to a compact noise subspace and train a regularized SAC policy. This avoids updating the large VLA backbone and enables efficient real-world policy refinement. Evaluated on seven real-world humanoid loco-manipulation tasks, HAF surpasses vanilla single-stage VLA baselines and improves whole-body coordination and task performance. Project website: https://grange007.github.io/HAF .

VLAHumanoid
Langzhe Gu, Chengkai Hou, Meng Li · 702 views · Aug 17, 2026
PhyAI: Real-Time Physical AI at the Edge, Scalable Rollouts in the Cloud

PhyAI: Real-Time Physical AI at the Edge, Scalable Rollouts in the Cloud

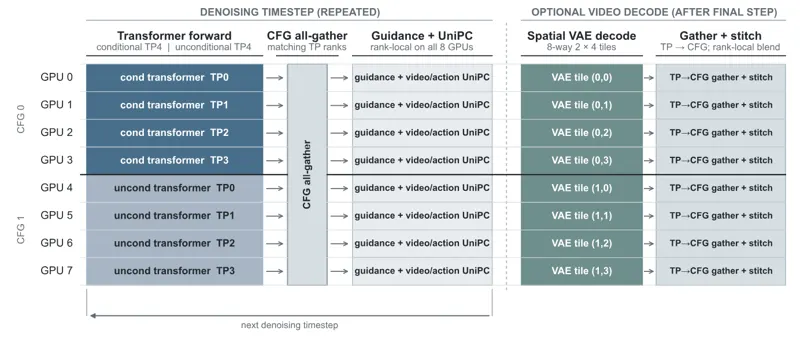
Physical AI policies require inference throughout their lifecycle, including model evaluation, cloud reinforcement learning rollout, edge GPU serving, and onboard deployment. Although these settings share the same checkpoint and action semantics, they often rely on separate inference programs. To unify them, we build PhyAI, a Physical AI inference engine with a single runtime that keeps architecture-specific conditioning, solver, cache, and output logic in model adapters while sharing graph execution, kernels, memory management, and parallel services. The same codebase runs vision-language-action (VLA) models and world-action models (WAMs) on single or multiple GPUs across onboard, edge, and cloud deployments. We used the adapter interface to add MiniCPM-Robot on the day of its release. PhyAI achieves 1.40x-4.65x speedups over the official implementations of pi0, pi0.5, GR00T N1.7, and MiniCPM-Robot. On Cosmos3-Nano-Policy-DROID it reduces latency from 2.46 to 1.18 s on eight H20 GPUs (CFG=2, TP=4), a 2.08x speedup. Specialized runtimes remain faster in several configurations, so our goal is one runtime with competitive latency rather than the fastest result in every case. Detailed profiles reveal why different models need different execution policies: on a Hopper-series GPU at batch size one, the pi0.5 action expert accounts for 8.8% of FLOPs but 57.2% of latency; at batch size 32 its share drops to 13.5% and throughput reaches about 100 samples/s. Cosmos3 remains generation-dominated and gains only 14.3% throughput as batch size increases from 1 to 16. We further introduce the control-time Roofline, which distinguishes inference-bound from environment-bound control; the measured pi0.5 points on four LIBERO suites are environment-bound while Cosmos3 stays inference-bound. Code and benchmarks: https://github.com/mingti-org/phyai.

Physical AIVLA
Chenghua Wang, Daliang Xu, Dongqi Cai · 721 views · Aug 4, 2026

As an Amazon Associate, we earn from qualifying purchases.