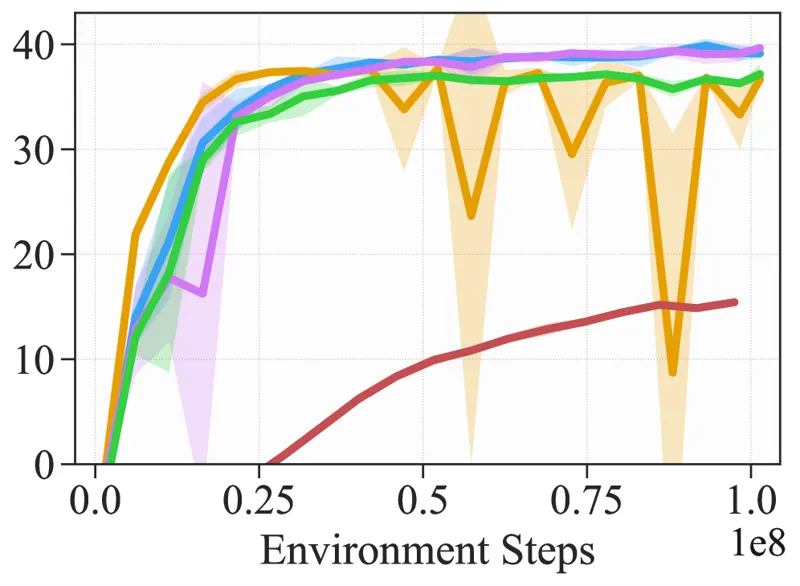
FastDSAC:通过约束探索增强策略可塑性实现可扩展人形运动对目标动作施加均值中心 tanh 截断映射,仅用于 Bellman 备份中目标 Q 值计算,用变量替换推导一致熵项——减少极端目标动作方差放大,在 MuJoCo Playground 和 HumanoidBench 上实现更快更可靠的离策略 RL 训练。Guanchen Lu, Yajuan Dun, Yi Zhou·2026年6月30日SACPlasticityHumanoidBench2026年6月30日