Skip to content
← Tags
LLMDevelopmentTopA

MiMo-V2.6: Live RL as an auditable ledger of 30 steps, 750k trajectories, and dollars
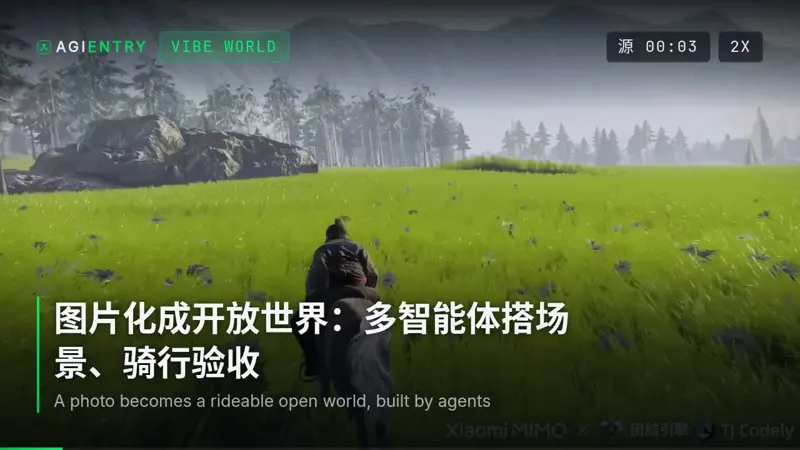
Xiaomi's open-source MiMo-V2.6 Pro/Flash: 30 steps of Live RL, roughly 750k trajectories, public cost of $850k/$2.62M, and 7k+ RL environments released in the same batch; tops the open-weights camp on the Artificial Analysis intelligence index at 46 with +17/+14 points out-of-sample on DeepSWE v1.1; four demo lines (Vibe World, CUA, research, content creation) all open. Self-improvement becomes an auditable ledger - steps, trajectories, and dollars on the table for third-party recomputation.

46Artificial Analysis Intelligence Index (top open-weight)Confirmed · 2026-09
ProductXiaomiSiteRepo
MiMo-V2.6: Live RL as an auditable ledger of 30 steps, 750k trajectories, and dollars
LLMDevelopmentC

Laya: a 421M non-autoregressive System 1 decision model at 33 ms per forward pass

Convai Innovations' open-source non-autoregressive System 1 decision model: 421M parameters, ModernBERT backbone with [MASK] option extraction, one 33 ms forward pass per calibrated decision, Apache-2.0; trained with RLCD strictly proper scoring rules for honest probabilities; the model card ships a real benchmark against Jev plus an honest limitations list. Positioned for edge and high-concurrency small decisions (game NPCs, dialogue policy, request routing), not long reasoning or open generation.

33 msSingle forward-pass latency (421M, vendor)Vendor Claim · 2026-09
ResearchConvai InnovationsSiteRepo
Laya: a 421M non-autoregressive System 1 decision model at 33 ms per forward pass
LLMDevelopmentTopC

Jev: TypeSafe's first System One Model types decisions and prices them two orders of magnitude lower

TypeSafe's first System One Model: outputs are type-safe structured values under three question primitives (Noul/Choice/Score) rather than strings, trained with RLCD for calibrated decision probabilities. The official 13-question parallel experiment makes one synthesized call ~12.2x cheaper and ~10.0x faster than 13 separate calls; four-workflow mean accuracy 67.8% at /tmp/run_ingest2.sh.0004 and 0.4s per instance - opus 5 / sol tier accuracy at almost two orders of magnitude less cost; input $0.042/M tokens, output free. Ships an OpenJev local reproduction path and an eight-item caveats list.

67.8%Mean accuracy across four workflows (vendor eval)Vendor Claim · 2026-09
ProductTypeSafeSiteRepo
Jev: TypeSafe's first System One Model types decisions and prices them two orders of magnitude lower
ReasoningDevelopmentTopA

GPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligence

The OpenAI flagship tier, officially positioned for hardest end-to-end work (gpt-6-astra): 1.05M-token context, 128K-token single output, knowledge cutoff 2026-04-30, with Functions, Web search, File search and Computer use built in, so search, retrieval and interface control ship with the model instead of an outer agent framework. Reasoning effort runs low to max in five steps while price stays fixed at $10/$50, so the cost lever is token consumption; siblings Sol ($2/$10) and Luna ($0.1/$0.5) make a 100x spread, so load splitting can stay inside one vendor. Readings (2026-09-22): #1 on Terminal-Bench 4.0 at 58.18% (n_trials=330, pass@5 0.7121), the protocol closest to a coding agent's daily life; #2 on Arena Agent with net_improvement 11.54 and confirmed_success 17.70, both below leader Fable 5.1, but the field's highest praise at 32.79; #6 and #7 on the intelligence index (max 52.67). The cutoff is nearly five months older than this page, so version numbers and API changes must go through Web search; computer-use reliability appears on no board; closed, API only. Graded A (confirmed); not benchmarked by us.

58.18%Terminal-Bench accuracyConfirmed · 2026-09
ProductOpenAISite
GPT-6 Astra: first on terminal engineering tasks, third tier on composite intelligence
ReasoningDevelopmentTopA

Claude Fable 5.1: the long-horizon agentic tier that tops the ladder on a different ruler

The fixed version Anthropic positions for demanding reasoning and long-horizon agentic work (claude-fable-5-1, retirement no earlier than 2027-09-01): default thinking effort high at $10/$50 per million tokens, 2.5x sibling Opus 5.5, and default-high is itself a default cost behaviour. Its standing only holds once you switch rulers: #1 on net_improvement in the Arena Agent board (13.71, confirmed_success 19.83, praise 31.83) ahead of GPT-6 Astra (11.54/17.70/32.79), while Opus 5.5 misses the top eight; #2 on Terminal-Bench 4.0 at 57.88% (n=330), 0.3 points behind Astra at 58.18% but with pass@5 of 0.7879 against 0.7121, lower single-shot and more robust over five attempts; #4 on the intelligence index at 53.35 (max), below Opus 5.5. The picture is consistent: not first on composite intelligence, first on pushing a real task forward. A separate praise column means the board carries a human or judge component and is not an objective benchmark. Choose by whether the workload is hard from reasoning or from long-horizon consistency. Closed, API only. Graded A (confirmed); no long-task comparison on our own harness.

13.71Arena Agent net improvementConfirmed · 2026-09
ProductAnthropicSite
Claude Fable 5.1: the long-horizon agentic tier that tops the ladder on a different ruler
ReasoningDevelopmentTopA

Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinking

The fixed version Anthropic positions for long-running agentic coding and knowledge work (claude-opus-5-5, retirement no earlier than 2027-09-22): 1M-token context, 128K-token single output, adaptive thinking defaulting to medium, at $4/$20 per million tokens, the cheapest of the three top rows we track. On the Artificial Analysis intelligence index this site syncs (2026-09-22) the top three rows are all its thinking tiers (max 57.62, xhigh 55.99, high 53.58), while the default medium tier sits #8 at 51.24, with sibling Fable 5.1 (53.35) and GPT-6 Astra (52.67) in between. Two discounts: those rows carry the with fallback qualifier while Astra reads (max), so the protocols differ, and the 53.94% at #8 on Terminal-Bench belongs to the previous-generation Opus 5. Closed, API only; adaptive thinking is a black box, so budget on p90 rather than the mean; 1M context is not 1M of effective attention, so whole-repo input still needs retrieval. Use it for most workloads and move to Fable 5.1 only when the highest tier is not enough: 2.5x the price for 4.3 index points. Graded A (confirmed); not benchmarked by us.

57.62Artificial Analysis Intelligence IndexConfirmed · 2026-09
ProductionAnthropicSite
Claude Opus 5.5: the long-running agentic tier at $4/$20 with 1M context and adaptive thinking