PAPER DEEP DIVE
FLORA: An Open Model Suite for Scaling Robotics Data Engines
The life-cycle of robotics foundation models crucially depends on data labels. Outcome reward labels are needed for monitoring real-world deployments. Process reward labels are needed during RL post-training. Timestamped captions are needed for filtering and balancing pretraining data. We present Flora, an industrial-quality data engine used for training GR00T models, that simultaneously covers these capabilities. Flora achieves SOTA scores on the captioning benchmark WGO-Bench and reward benchmarks RoboReward and Robometer. On internal benchmarks it is competitive with GPT-6 Astra while beating other frontier models. The model is substantially cheaper than API-based alternatives, roughly 125 times cheaper than GPT-6 Astra. Flora is battle tested at scale, labeling 200,000 hours of data per day across 512 GB300s. By open-sourcing our data engine, we enable researchers to scale custom robotics datasets and explore emerging applications such as physical auto-research and human-to-robot transfer.
In one sentence
Flora turns raw robot video into timestamped action captions, dense process rewards, outcome rewards, and test-time rubric rewards; NVIDIA reports that the same open data engine was used to train GR00T and costs about 1/125 as much per annotation hour as GPT-6 Astra under its stated deployment assumptions.
Why robotics needs a data engine
Robot foundation models have moved from policies tuned for one robot to generalist systems trained on heterogeneous corpora. As the corpus grows, the limiting resource is often not another policy architecture. It is the label that tells the training loop which part of a video contains an action, whether that action advanced the task, and whether a deployed fleet is succeeding or failing.
The paper separates those needs into three operational layers. Pretraining consumes timestamped action captions because language conditioning and data rebalancing both require knowing what happened and when. Reinforcement learning after policy pretraining consumes process rewards because a single trajectory score cannot assign credit to the individual step that caused a failure. Fleet monitoring consumes outcome rewards because operators need an auditable completion signal over thousands of unscripted episodes.
Existing tooling tends to solve one layer at a time. General video-language models can be prompted for each format, but their per-hour cost becomes severe when modern corpora are measured in thousands or millions of hours. Narrow reward models or segment retrieval systems are cheaper, yet they rarely share one output contract, one camera preprocessing path, and one failure taxonomy. Teams then maintain several labeling stacks whose errors cannot be compared directly.
Flora is designed as an industrial pipeline rather than a single benchmark model. Its segmentation model finds action intervals, its captioner writes the intended action inside those intervals, and its reward model judges execution quality. All three are fine-tuned from Qwen3.5 vision-language models and deployed with batch tooling. The reported throughput is up to 200,000 hours per day on 512 GB300 GPUs, and the authors state that the outputs were used to train GR00T models.
Open weights matter for robotics in a specific way. Many laboratories cannot upload proprietary demonstrations, unreleased hardware behavior, or safety-critical failures to a hosted API. A local data engine lets them keep the video, adjust the ontology and rubrics to their own tasks, regenerate labels after camera or policy changes, and inspect exactly how a label was produced. That is the practical claim behind Flora's open release.
Labels and granularity
A timestamped caption is a pair of interval boundaries plus a description. The interval is half-open, so the start belongs to the event and the end does not. The description concerns the intended action rather than only the successful outcome: a dropped connector or missed grasp is still an event if the operator attempted it. This distinction is important for imitation data, where failed attempts can be as informative as clean successes.
Reward labels differ by temporal scope. An outcome reward summarizes the whole episode. A dense process reward maps 0.5-second groups to failure, suboptimal, or normal execution. A rubric reward decomposes a user-defined task into steps and assigns each step a score from an allowed set. The same physical trajectory can therefore receive three consistent views: what happened, which parts went wrong, and how much of the task was completed.
Flora does not ask one model to perform all semantic work. The 9B segmenter and the 27B captioner form a two-stage pipeline; the 27B rewarder is a separate model whose behavior is switched by prompts. That separation lets the captioner preserve the boundaries produced by the segmenter and lets the rewarder specialize in execution quality rather than language generation.
Method
The supervision contract
For a video X of duration T, Flora emits the set in Equation (1):
$$\mathcal{A}(X)=\{(s_i,e_i,c_i)\}_{i=1}^{N},\qquad I_i=[s_i,e_i),\quad 0\le s_i < e_i \le T.$$
Here I_i is the i-th half-open interval and c_i describes the intended action. This single tuple is the engine's reusable product. Pretraining code can filter or rebalance data by action, RL code can align process rewards with the same timeline, and monitoring code can query failures on the same episode clock.
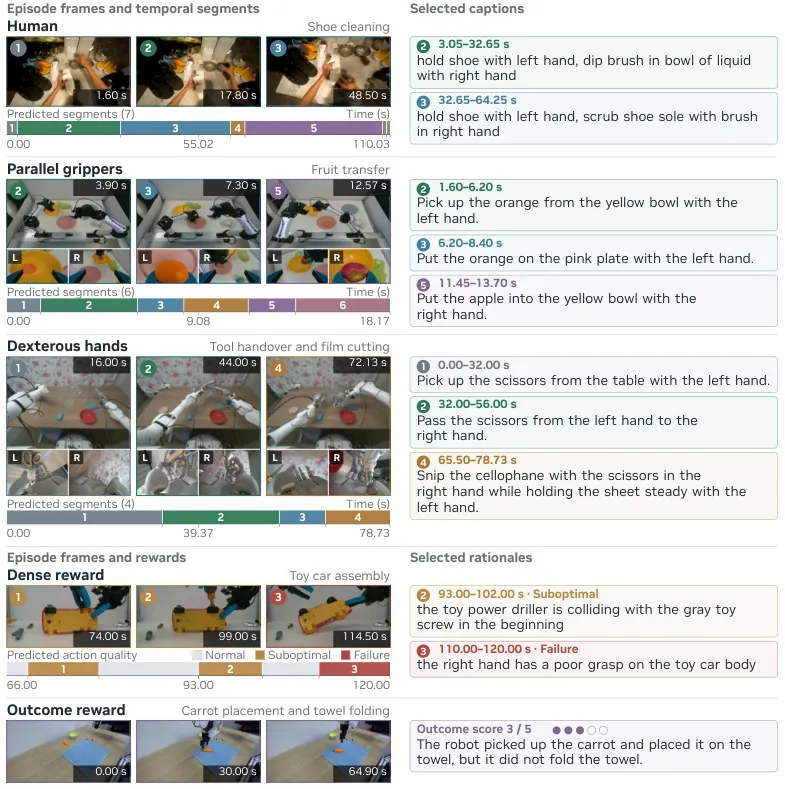
Figure 6: Overlapping segmentation windows are stitched into event intervals; the captioner adds contextual descriptions while a separate rewarder produces execution labels.
The full flow is easiest to read as three branches from the same video:
flowchart TB
    V[Raw robot video] --> M[Temporal segmenter 9B]
    M --> W[Overlapping windows
16s or 32s by source type]
    W --> S[Deterministic stitching
with continuation flags]
    S --> C[Captioner 27B]
    C --> A[Timestamped captions]
    V --> R[Rewarder 27B]
    R --> D[Dense failure, suboptimal, normal labels]
    R --> O[Outcome score from 1 to 5]
    R --> U[Test-time rubric reward]
    A --> P[Pretraining filtering and mixture control]
    D --> RL[RL credit assignment and curation]
    O --> F[Fleet monitoring and evaluation]
Temporal segmentation by central emission
Instead of consuming an entire episode at once, the segmenter processes overlapping windows. A standard human or robot window is 16 seconds: the central 12 seconds are the emission core and the two-second regions on each side are guards. Sixty-four frames are sampled at 4 Hz. Long-horizon robot data uses a 32-second window, a 24-second core, four-second guards, and 128 frames. The released production adapter encodes exactly this profile in `fine_temporal.py:108`.
For the k-th window, the model returns Equation (12):
$$\mathcal{F}_k=f_\theta(X_{W_k},q_k)=\{(u_{kj},v_{kj},\ell_{kj},r_{kj})\}_{j=1}^{n_k}.$$
The local boundaries u and v are expressed on a 20 Hz tick grid, while the two flags indicate whether an action continues past the left or right window edge. Deterministic filtering retains only fragments that intersect the emission core. Fragments are then projected to episode time and joined when they overlap and their continuation flags are compatible. A short action observed by several windows can therefore accumulate evidence without becoming several redundant intervals.
Central emission is the key to stable boundaries. The guard context tells the model what preceded and followed a candidate action, but only the core is allowed to vote for an interval. This prevents adjacent windows from repeatedly extending the same event into one another. For difficult edges, the system reruns the segmenter on shifted windows rather than blindly averaging nearby endpoints.
Contextual captioning without boundary editing
Once intervals exist, the captioner receives the target interval plus the nearest non-overlapping events before and after it. Equation (2) defines the generation:
$$c_i=g_\phi(X_i^-,X_i,X_i^+,q_{\mathrm{cap}}).$$
The neighboring blocks X_i^- and X_i^+ help resolve which object is being manipulated and where the action sits in a sequence. The prompt nevertheless restricts the answer to I_i. The released captioner adapter names these blocks BEFORE, TARGET, and AFTER in `pts_input_adapter.py:18`; unavailable context is simply omitted.
For multi-camera robots, synchronized views are tiled into one image at every sampled time. The prompt states the camera roles and asks for one self-contained action description across them. It also requests the imperative intended action, relevant object identities, manipulator roles, and spatial relations. A failed grasp remains a grasp attempt; the caption may describe the intended operation without implying that it succeeded.
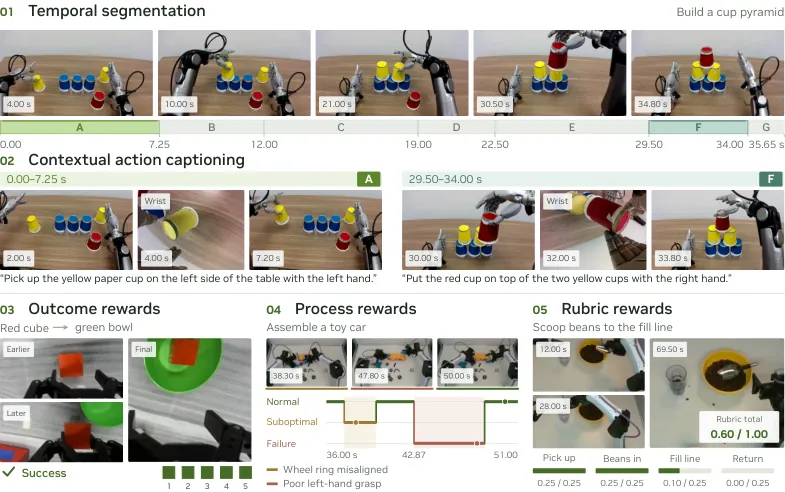
Figure 1: Flora produces timestamped captions from segmentation and captioning, and execution rewards from dense, outcome, or user-defined rubric interfaces.
One reward model, three interfaces
The rewarder is a single 27B model, not three unrelated heads. Outcome mode emits a one-to-five completion score. Dense mode emits one of three labels for every 0.5-second group and a rationale for contiguous non-normal spans. Rubric mode reasons over user-provided steps and awards one grade per step.
Equation (3) formalizes the rubric contract:
$$R_\rho(X)=\sum_{j=1}^{n}\hat y_j,\qquad \hat y_j\in V_j,\qquad \sum_{j=1}^{n}\max V_j=1.$$
Each step j may only choose from its allowed grade set V_j, and the maximum step scores sum to one. Because the schema is public and constrained, a rubric reward can be checked by a human, replayed in an RL run, or compared against the same rubric graded by another rater.
Outcome mode can expose the probability of each score token. If p_k is the probability of integer score k, Equation (19) converts the distribution into a continuous value:
$$p_k=p_\psi(s=k\mid X,\ell,q_{\mathrm{out}}),\qquad \mathbb{E}[s]=\sum_{k=1}^{5}k\,p_k,\qquad \hat y=\frac{\mathbb{E}[s]-1}{4}\in[0,1].$$
This gives partial credit to partially completed trajectories. Ranking by the expected score is especially useful when a task visibly advanced but did not finish, a regime where binary success classifiers usually collapse many distinct outcomes into the same label.
Retrospective dense reward
The dense rewarder uses the same 16-second, 64-frame window family as the segmenter, but groups adjacent frames into thirty-two 0.5-second units. It must first declare the worst level observed in the window and then list the group labels; the parser rejects inconsistent answers. Labels are failure, suboptimal, and normal. A failure means a major task loss, unsafe event, or loss of task viability, while suboptimal captures hesitation, inefficiency, imprecision, or a recoverable local mistake.
Windows advance by ten seconds. The final four seconds of a non-final window are discarded. This is not a decoding trick: dense labels are retrospective, and whether an action became a failure is often visible only in later frames. The production constants appear in `rewarder/batch_utils/core.py:412-421`, including 64 frames, 32 groups, a 10-second stride, and the 4-second trim.
Overlapping windows must still be merged deterministically. Equation (22) chooses the source window and group with lexicographically smallest keys:
$$(k^{\star},g^{\star})=\operatorname*{lexmin}_{(k,g)\in\mathcal{C}}\left(\min_{\tau\in\tau_{k,g}}\lvert t-\tau\rvert,\;-\min(g-1,\,32-g),\;k,\;g\right),\qquad a_t=a_{k^{\star},g^{\star}}.$$
In words, the merger prefers the retained group nearest to the query time, then the group farthest from a window edge, then the earlier window, and finally the lower group index. This removes the need for ad hoc averaging and makes the same input produce the same episode timeline.
Training and verifiable rewards
All models start from Qwen3.5 vision-language checkpoints: 9B for the segmenter and 27B for the captioner and rewarder. Supervised fine-tuning minimizes output-token cross entropy. Equation (15) averages the loss over tokens and examples in a batch:
$$\mathcal{L}_\eta(\mathcal{B})=-\frac{\sum_{(x,y)\in\mathcal{B}}\sum_{t=1}^{|y|}\log p_\eta(y_t\mid x,y_{<t})}{\sum_{(x,y)\in\mathcal{B}}|y|},\qquad \eta\in\{\theta,\phi,\psi\}.$$
The segmentation LoRA has rank 32 and keeps the visual encoder frozen. The captioner updates the language model and visual merger. The rewarder updates the language model, visual merger, and visual encoder, using a lower learning rate for the encoder. These choices reflect how much each task depends on stable visual evidence.
The segmenter is further optimized with GRPO. Equation (16) combines four verifiable signals:
$$r_{\mathrm{seg}}=0.45F_{0.5}+0.15F_{0.75}+0.25P_{0.5}+0.15B.$$
The two F terms are F1 at tIoU thresholds 0.5 and 0.75, P is precision at 0.5, and B measures boundary and continuation-flag accuracy. The lower-threshold F1 rewards recall, the higher-threshold F1 punishes loose boundaries, precision discourages flooding the timeline with fragments, and B keeps the window continuation flags inside the optimization signal.
The captioner uses a grounded point-quality reward. Equation (17) is:
$$r_{\mathrm{cap}}=\frac{2M}{R+M+F}.$$
R is supported reference mass, M is the covered mass, and F penalizes demonstrated factual errors. The penalty is counted by semantic error family rather than by every repeated phrase, so a model does not receive a much larger penalty merely because it restates the same wrong fact. The released rewarder is SFT-only; rubric examples use thinking mode while outcome and dense examples answer directly.
Experimental evidence
Timestamped captions
WGO-Bench contains 25 HomER human egocentric episodes, 50 DROID externally viewed robot episodes, and 25 Galaxea head-camera episodes. Segmentation is one-to-one temporal matching at tIoU at least 0.75. Gold-window captioning is evaluated within reference intervals, and joint annotation requires both time and text agreement. Equation (5) is the matching F1:
$$F_{\mathrm{seg}}=\frac{2\,\mathrm{TP}}{|\widehat{\mathcal{I}}|+|\mathcal{I}^{\star}|}.$$
Flora reaches 50.3% mean segmentation F1, 64.7% gold-window caption accuracy, and 34.5% joint F1. It leads segmentation and ranks second in joint F1. The caption score remains below GPT-6 Astra's 77.4%, so the decisive gain is temporal localization rather than standalone text quality.
| System | Segmentation F1 at 0.75 | Gold-window caption | Joint F1 at 0.75 |
|---|---|---|---|
| GPT-6 Astra | 46.0 | 77.4 | 39.0 |
| Gemini 3.8 Flash | 26.4 | 70.9 | 21.7 |
| Qwen3.5-27B | 22.4 | 43.7 | 13.7 |
| Flora | 50.3 | 64.7 | 34.5 |
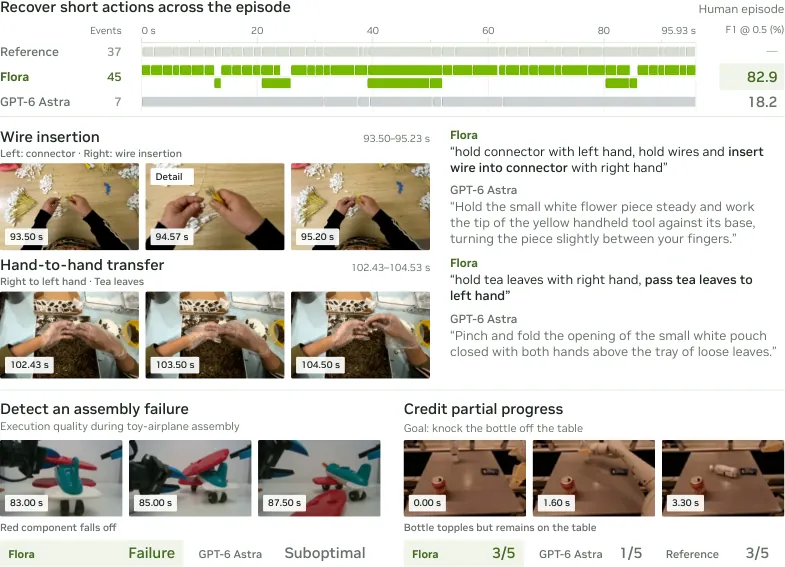
Figure 4: Complete pipelines on WGO-Bench. Higher is better; values are percentages.
The pipeline comparison is more informative than the raw model comparison. Relative to Refiner, Flora adds 16.9 points of segmentation F1 and 7.3 points of joint F1 while keeping gold-window caption quality nearly unchanged. In an API-substitution diagnostic, the production windows and prompts remain in place but both trained models are replaced by Gemini 3.8 Flash; segmentation drops to 21.2% and joint F1 to 16.4%. The trained models, not the prompt layout alone, produce the advantage.
DenseCaptionBench extends the test to 300 complete episodes: 100 human, 100 parallel-gripper robot, and 100 dexterous-hand robot episodes. It allows multi-camera robot recordings and scores partial coverage of action, object identity, coordination, and detail. Flora leads all three Human100 metrics with 54.6% segmentation, 66.5% caption quality, and 37.4% joint F1. On Robot200 it ranks second behind Astra with 66.9%, 73.7%, and 51.0% respectively.
| System | Human seg. | Human caption | Human joint | Robot avg seg. | Robot avg caption | Robot avg joint |
|---|---|---|---|---|---|---|
| GPT-6 Astra | 44.2 | 60.3 | 29.7 | 71.9 | 80.2 | 57.9 |
| GPT-5.6 Sol | 32.6 | 36.4 | 14.6 | 45.8 | 69.6 | 33.6 |
| Gemini 3.8 Flash | 33.5 | 46.7 | 17.7 | 45.8 | 66.0 | 32.2 |
| Flora | 54.6 | 66.5 | 37.4 | 66.9 | 73.7 | 51.0 |
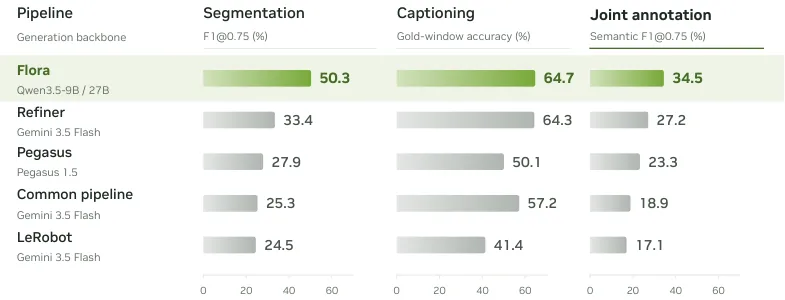
Figure 3: One data engine covering timestamped captioning and several reward formats.
Reward quality
RoboRewardBench scores 2,831 episodes on a human-labeled one-to-five outcome scale and reports mean absolute error multiplied by 100. Flora-Rewarder obtains 40.0, versus 55.4 for GPT-6 Astra, a 27.8% relative reduction. The largest separation appears on partially completed episodes, where an expected score retains information that a hard success or failure decision would discard.
| System | RoboReward MAE | Dense macro F1 | Failure recall | Rubric pooled L1 |
|---|---|---|---|---|
| GPT-6 Astra | 55.4 | 40.7 | 0.0 | 3.6 |
| Gemini 3.8 Flash | 83.3 | 38.8 | 11.7 | 32.6 |
| Qwen3.5-27B | 84.8 | 30.8 | 5.7 | 15.4 |
| Flora-Rewarder | 40.0 | 46.2 | 53.3 | 6.5 |
DenseRewardBench tests the part public reward benchmarks usually omit: locating the moments when execution goes wrong. It contains 40 held-out bimanual episodes and 4,861 labeled time steps, including 300 failure steps. Flora recalls 53.3% of failure steps and obtains 46.2 macro F1. No baseline exceeds 11.7% failure recall, and Astra detects none. The tradeoff is explicit: about 11% of normal steps are also labeled failure.
On RobometerBench, Flora's OOD Kendall tau-a is 72.0 while Astra reaches 82.3. On successful-trajectory progress ordering, Flora ties Astra at 98.9 ID VOC and reaches 99.6 OOD VOC. These are therefore complementary results rather than a claim that Flora wins every reward metric.
Cost and qualitative behavior
The cost study uses a fixed 50-episode subset of DenseCaptionBench: 20 human, 15 parallel-gripper, and 15 dexterous-hand episodes. Flora reaches 57.1% mean quality. With an eight-GB300 deployment at 10 dollars per GPU-hour, Equation (9) estimates the cost:
$$C_{\mathrm{Flora}}=\frac{p\,g\,N}{3600\,H\,S}.$$
Here p is price per GPU-hour, g is GPU count, N is episode count, H is source-video hours, and S is the conditional processing rate. With S=1.23495 episodes per second, the estimate is 0.72 dollars per source-video hour. Astra at maximum reasoning reaches 53.7% quality at a known-usage API cost of 88.49 dollars per hour. The exact ratio is 122.49, summarized as about 125 times lower. The paper also reports an engineering rate interval of 0.70804 to 1.74862 episodes per second.
| System | Quality | Cost per source hour | Cost basis |
|---|---|---|---|
| Flora | 57.1 | 0.72 dollars | Eight-GB300 deployment model |
| GPT-6 Astra | 53.7 | 88.49 dollars | Known API usage, maximum reasoning |
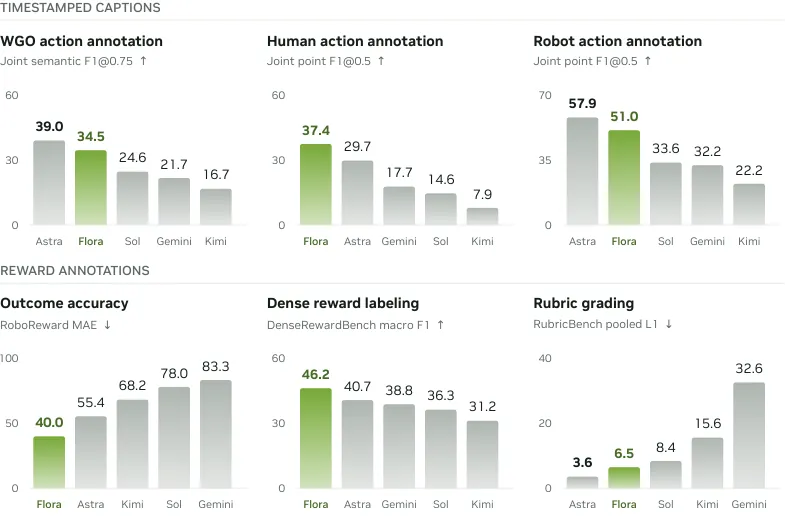
Figure 2: Mean annotation quality against estimated cost under the paper's stated accounting assumptions.
The qualitative examples show why temporal fidelity is not cosmetic. In one episode, Flora matches 34 of 37 reference intervals while Astra matches four; their F1 at tIoU 0.5 is 82.9 versus 18.2. Captions distinguish wire insertion from holding a connector and identify a right-to-left handover where Astra invents unrelated actions. In reward examples, Flora labels a falling component as failure and gives partial progress a score of three when a bottle topples without falling off the table, while Astra assigns one.
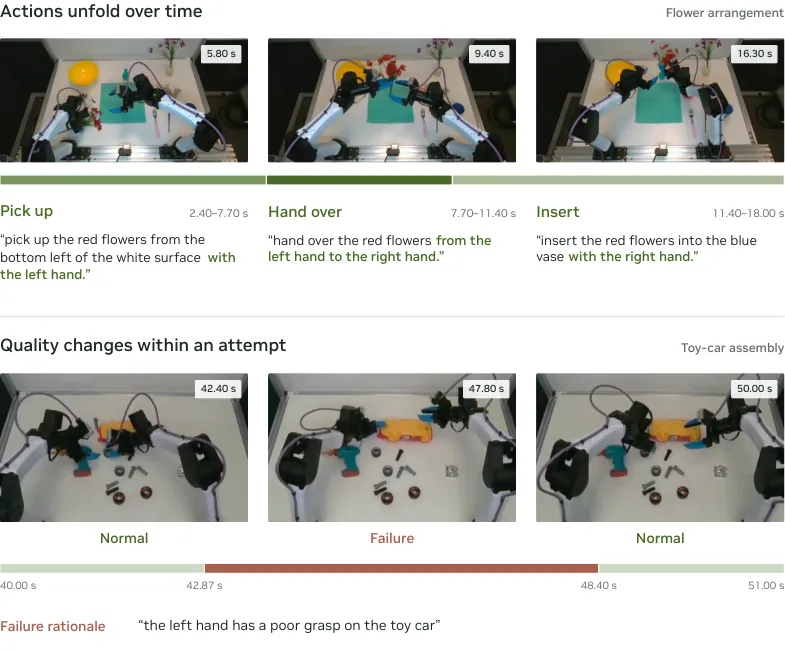
Figure 5: Qualitative comparisons over temporal coverage, intended action, failure recognition, and partial progress.
Limitations
First, the authors identify a generator-judge conflict. The DenseCaptionBench judge is GPT-6 Astra, and Astra is also a compared system. Model identities are hidden, but shared-judge self-preference cannot be ruled out mechanically. This is particularly relevant to the Human100 results, where Flora and Astra are close competitors.
Second, the strongest dense-reward advantage carries a false-positive cost. About 11% of normal steps are called failure. For RL this can discourage useful but awkward behavior; for fleet monitoring it can flood operators unless thresholds, secondary review, or task-specific failure taxonomies are added.
Third, caption text is not uniformly best. Flora's 64.7% WGO gold-window caption score trails Astra's 77.4% and Gemini 3.8 Flash's 70.9%. A team that needs only a single paragraph describing an already known interval may prefer Astra; Flora's benefit appears when boundaries and joint timeline coverage are part of the deliverable.
Fourth, the cost ratio is an estimate rather than a universal invoice. The deployment model assumes 10 dollars per GPU-hour, batch size 16, and a conditional rate of 1.23495 episodes per second whose production GPU-hour denominator has not been verified. Of 7,062 API attempts, 106 remain unpriced, and storage, serving overhead, billing granularity, and training are excluded from the comparison.
Fifth, qualitative analysis in the appendix notes that Flora can split coarse reference events into several short intervals. Dense segmentation improves recall, but on a coarse ontology it can lower precision and make the output less readable unless events are merged downstream.
Assessment
Flora's main contribution is an explicit supervision contract for the robot data life cycle. The segmenter, captioner, and rewarder each own one part of that contract, and their training rewards are tied to checkable references or rules rather than a vague preference score. The result is not a universal victory over frontier APIs; it is a practical route to local, reproducible labeling at robot-corpus scale.
Several design choices generalize beyond this paper. Central-window emission decouples context from boundary voting. Half-open intervals and fixed tick grids make timeline arithmetic auditable. Retrospective dense labels wait for later evidence. Rubric score sets are fixed before test time. Dense error penalties are grouped by semantic family. These are engineering constraints that another robotics team can adopt independently of the exact Qwen3.5 checkpoints.
Open weights turn the suite into a starting point rather than a service boundary. The next step for most laboratories is calibration to their own cameras, tasks, failure definitions, and rubrics. If that calibration holds, the same supervision stream can support pretraining curation, RL credit assignment, and deployment monitoring without forcing every downstream consumer to learn a different label format.
Golden line
Before scaling robot policies, scale the labels that make their data inspectable.
SOURCE LINKS