PAPER DEEP DIVE
RPL: Learning Robust Humanoid Perceptive Locomotion on Challenging Terrains
RPL uses a two-stage framework that distills terrain-specific height-map experts into a unified depth-based transformer policy, enabling robust bidirectional humanoid locomotion with payloads on slopes, stairs, and stepping stones.
One-Sentence Summary
RPL first trains terrain-specific expert policies with privileged height maps, then distills them into a transformer-based visual policy that uses efficient multi-depth rendering, depth feature scaling based on velocity commands, and random side masking to traverse slopes, stairs, and stepping stones bidirectionally while carrying payloads.
1. Background and Motivation
Humanoid robots have recently shown impressive whole-body control, expressive motion tracking, and manipulation skills. Yet one capability that separates them from wheeled mobile manipulators is the ability to move over diverse terrain while performing useful tasks such as carrying an object. RPL targets this capability under a demanding setting: robust bidirectional locomotion on a long course that mixes slopes, stairs, and sparse stepping stones.
Existing perceptive locomotion methods can be grouped into two broad families. Mapping-based approaches use LiDAR or reconstructed elevation maps to build a compact terrain representation before planning or control. They can be reliable when calibrated well, but they depend on accurate state estimation and online mapping. End-to-end depth-based policies directly map depth images to actions and avoid explicit mapping, but most use a single forward camera and only demonstrate forward traversal. Neither family has fully addressed asymmetric multi-view perception during bidirectional locomotion.
The visual problem becomes asymmetric when different cameras observe different terrain families at the same time. A robot descending stairs forward may still have its rear camera looking at stepping stones or a slope. A policy that treats all visual features equally will be distracted by information that is irrelevant to the current walking direction. RPL treats this not as a preprocessing issue but as a policy learning issue that should be handled during distillation.
Terrain width is another distribution-shift source. Simulators often train on wide stairs, wide slopes, and generous stepping-stone spacing. Real buildings can contain staircases only 1.2 m wide, and real stepping stones can be sparse. If the learned policy relies on lateral context near the image boundary, it can fail on unseen narrow terrain. RPL introduces random side masking to force the policy to act from central visible geometry.
Finally, whole-body motions create self-occlusion. When the robot bends down to pick up a payload, its torso and arms enter the depth image. A rendering pipeline that only casts rays against static terrain cannot produce realistic depth during loco-manipulation. RPL therefore ray-casts against both dynamic robot meshes and static terrain meshes in the same massively parallel system.
2. Preliminaries
RPL builds on FALCON, a dual-agent framework for humanoid loco-manipulation. A lower-body locomotion policy and an upper-body manipulation policy share a short history of proprioceptive observations. This decoupling lets the upper body execute task goals without being directly tied to terrain perception, while the lower body handles foothold selection, body orientation, and velocity tracking.
Training follows a two-stage recipe. In the first stage, PPO trains terrain-specific experts with privileged height maps. In the second stage, DAgger-style distillation regresses student actions toward expert actions on trajectories generated through interaction. This converts the complex multi-terrain skill set into one deployable visual policy without learning depth perception from scratch.
Understanding RPL also requires understanding why multi-depth simulation is expensive. Rendering depth images for thousands of parallel environments and multiple cameras is costly in existing simulators. Dynamic robot meshes make the problem harder because they change every frame. RPL keeps each robot body mesh in its local frame and transforms rays into that frame, avoiding per-frame refitting in the world frame.
3. Method
3.1 Overall Two-Stage Design
Stage 1 trains separate experts for slopes, stairs up, stairs down, and stepping stones. Stage 2 distills them into a unified student policy. At deployment, the student locomotion policy is combined with the original blind upper-body policy to produce whole-body actions for low-level PD tracking. Figure 1 summarizes the framework.
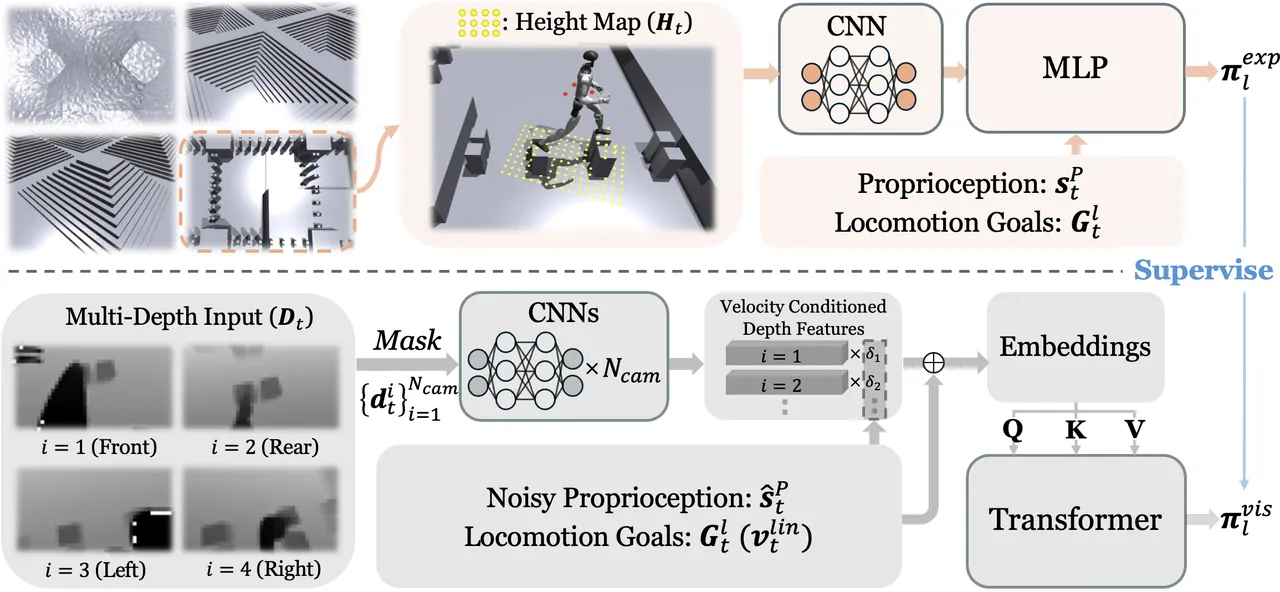
Fig. 1: RPL two-stage framework. Stage 1 learns terrain experts with height maps; Stage 2 distills them into a multi-camera depth policy.
Both agents observe the same proprioceptive history at time $t$:
$$ \mathbf{s}_{t}^{p}=\big[\mathbf{q}_{t-4:t},\dot{\mathbf{q}}_{t-4:t},\boldsymbol{\omega}^{\text{root}}_{t-4:t},\mathbf{g}_{t-4:t},\mathbf{a}_{t-5:t-1}\big]. $$Here $\mathbf{q}$ is joint position, $\dot{\mathbf{q}}$ is joint velocity, $\boldsymbol{\omega}^{\text{root}}$ is base angular velocity, $\mathbf{g}$ is the gravity direction estimate, and $\mathbf{a}$ is the action history. The windowed history gives the policy short-term dynamic context without explicit contact-force estimation.
The lower-body policy is conditioned on locomotion goals $\mathbf{G}_{t}^{l}$, which include linear velocity, yaw rate, stance mode, root height, and torso orientation. The upper-body policy is conditioned on upper-body joint targets $\mathbf{G}_{t}^{u}$. Perception is included only in the lower-body policy because terrain mostly governs leg movement. The mappings are:
$$ \boldsymbol{\pi}_{l}:(\mathbf{s}_{t}^{p},\mathbf{G}_{t}^{l},\mathbf{H}_{t}\;\mathrm{or}\;\mathbf{D}_{t})\rightarrow\mathbf{a}_{t}^{l},~\boldsymbol{\pi}_{u}:(\mathbf{s}_{t}^{p},\mathbf{G}_{t}^{u})\rightarrow\mathbf{a}_{t}^{u}, $$with the final action $\mathbf{a}_{t}=[\mathbf{a}_{t}^{l};\mathbf{a}_{t}^{u}]$ sent to the low-level controller. Keeping manipulation blind avoids coupling visual terrain features to arm motions that do not depend on the ground.
3.2 Terrain Experts and Reward Design
The privileged height map is a local grid of $1.6\,\mathrm{m}\times 1.0\,\mathrm{m}$ at $0.1\,\mathrm{m}$ resolution. The training terrains are demanding: slopes up to $37^{\circ}$, stair step lengths from $0.25$ to $0.30\,\mathrm{m}$, step heights from $0.05$ to $0.27\,\mathrm{m}$, and stepping stones from $0.25$ to $0.40\,\mathrm{m}$ separated by up to $0.70\,\mathrm{m}$. Unitree G1 has a foot length of about $0.21\,\mathrm{m}$, so the smallest stair treads and stones leave little margin.
The reward design addresses two failure modes. The foot-edge penalty precomputes dilated edge masks and penalizes contact when sampled points on the foot sole lie near an edge. The foothold penalty samples a dense grid over the foot sole and penalizes invalid coverage. Stairs use the foothold penalty because edge dilation is too conservative on narrow treads, while stepping stones use the foot-edge penalty because boundary contact is dangerous on isolated supports. Figures 2 and 3 show both effects.
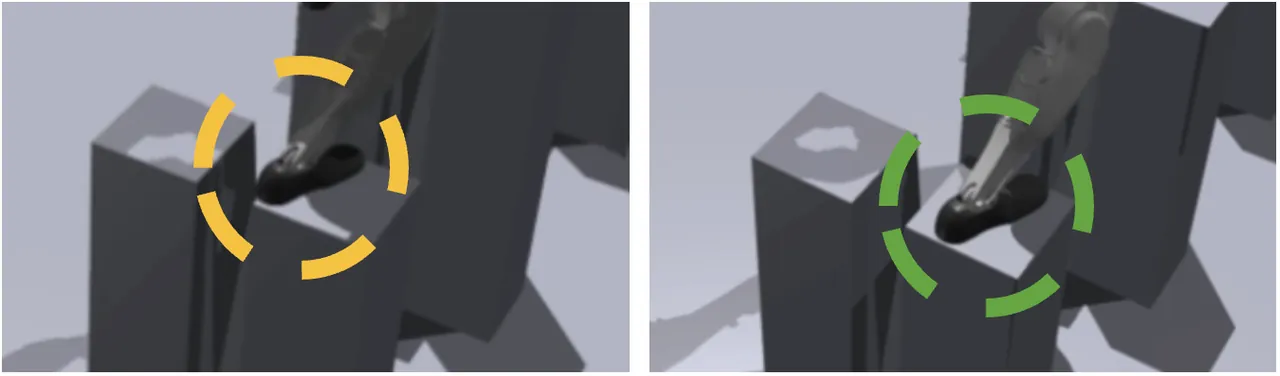
Fig. 2: Stepping stones without and with the foot-edge penalty.
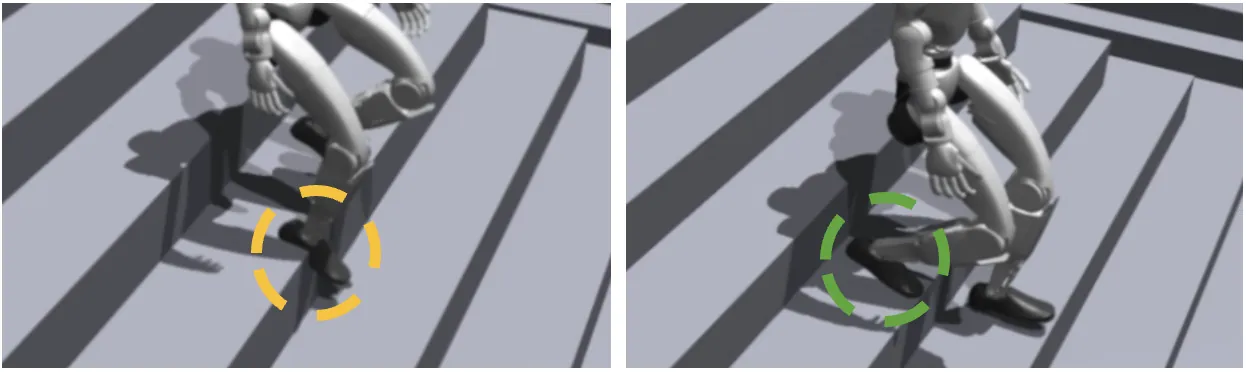
Fig. 3: Stairs without and with the foothold penalty.
RPL also tracks torso orientation. The reward compares projected gravity in the torso frame to a reference:
$$ r_{\text{torso}}=\exp\left(-\frac{\|\mathbf{g}_{\text{proj}}-\mathbf{g}_{\text{ref}}\|^{2}}{\sigma}\right). $$This reward encourages the waist and hip joints to work together, providing a stable base for upper-body tasks such as crouching and picking up payloads.
3.3 Distillation Objective
The student policy $\boldsymbol{\pi}_{l}^{\text{vis}}$ observes noisy proprioception and multi-view depth $\mathbf{D}_{t}$, while expert policies observe clean proprioception and privileged height maps $\mathbf{H}_{t}$. RPL minimizes action regression:
$$ \mathcal{L}_{\text{distill}}=\mathbb{E}_{k,t}\!\left[\left\|\boldsymbol{\pi}_{l}^{\text{vis}}(\mathbf{s}_{t}^{p},\mathbf{G}_{t}^{l},\mathbf{D}_{t})-\boldsymbol{\pi}_{l,k}^{\text{exp}}(\mathbf{s}_{t}^{p},\mathbf{G}_{t}^{l},\mathbf{H}_{t})\right\|_{2}^{2}\right]. $$The subscript $k$ indexes terrain experts. This loss avoids explicit geometric reconstruction and directly aligns the student with expert actions under the same task goals. It also prevents perception errors from being amplified by a separate planning stage.
3.4 Efficient Multi-Depth Simulation
RPL implements a GPU ray-casting system in NVIDIA Warp. For each environment, camera, and pixel, the camera intrinsics generate a ray:
$$ \mathbf{r}_{c}=\mathbf{K}_{e}^{-1}[x,y,1]^{\top}. $$The ray is rotated into the world frame and cast from the camera origin $\mathbf{o}=\mathbf{p}_{c}^{e,c}$ along direction $\mathbf{d}$. Depth is the Euclidean distance to the closest mesh intersection, clipped at far plane $d_{\max}$.
Dynamic robot meshes are handled in local coordinates. A world-frame ray is transformed into each body frame:
$$ \mathbf{o}_{b}=\mathbf{R}_{b}^{\top}(\mathbf{o}-\mathbf{t}_{b}),\quad\mathbf{d}_{b}=\mathbf{R}_{b}^{\top}\mathbf{d}, $$where $(\mathbf{t}_{b},\mathbf{R}_{b})$ is the world pose of body $b$. The kernel first queries all dynamic robot meshes and maintains the closest hit $z^{\star}$. That distance becomes an upper bound for the static terrain query, enabling early termination. The final depth is written to $\mathbf{D}[e,c,y,x]$.
This design batches inverse intrinsics per environment, supports per-camera randomization without control-flow divergence, and captures the whole pipeline into a CUDA graph. It models realistic sensor latency, Gaussian depth noise, and dropout while remaining fast enough for large-scale distillation. Figure 4 illustrates the DFSV feature modulation concept.
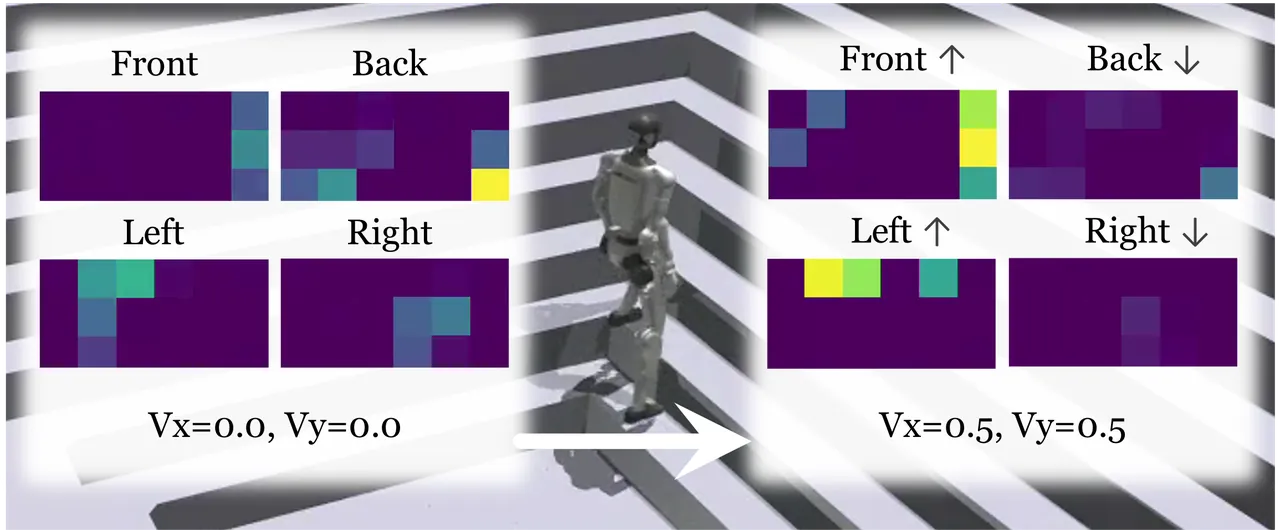
Fig. 4: DFSV adjusts the relevance of each camera based on the commanded velocity.
3.5 Depth Feature Scaling Based on Velocity Commands
Multiple cameras pointing in different directions are not equally relevant under every velocity command. DFSV computes a scalar for each camera from the dot product between the planar velocity command and the camera viewing direction:
$$ \delta_{i}=1-\sigma\left(-k\left(\langle\mathbf{v}_{t}^{\mathrm{lin}},\boldsymbol{\hat{n}}_{i}\rangle-v_{\mathrm{th}}\right)\right),\quad i=1,\ldots,N_{\text{cam}}. $$Here $k$ controls sharpness, $v_{\mathrm{th}}$ is a small threshold, and $\langle\cdot,\cdot\rangle$ is the inner product. Cameras aligned with motion get scales close to 1; cameras facing away get scales close to 0. The scaled CNN features are fused before the policy head:
$$ \mathbf{f}_{\text{fused}}=\bigoplus_{i=1}^{N_{\text{cam}}}\delta_{i}\cdot\mathbf{f}_{i}. $$This is a lightweight, command-conditioned attention mechanism without learned attention parameters. It is especially useful when the front camera sees stairs and the rear camera still sees stepping stones during a descent.
3.6 Random Side Masking for Unseen Terrain Widths
RSM randomly occludes peripheral regions of the depth image during training. Each environment samples a masking mode from a terrain-specific categorical distribution:
$$ \mathrm{mode}\sim\mathrm{Categorical}(\mathbf{p}_{k}),\quad \mathbf{p}_{k}=\big[p_{k}^{\text{none}},p_{k}^{\text{small}},p_{k}^{\text{large}}\big]. $$Occluded pixels are filled with random depth values in $[d_{\text{near}},d_{\text{far}}]$, preventing the policy from exploiting fixed boundary artifacts. Continuous terrains such as stairs and slopes can tolerate larger masks because traversability depends mainly on local geometry ahead. Stepping stones use smaller masks because valid footholds may appear only in the lateral field of view. Figure 5 shows the modes.
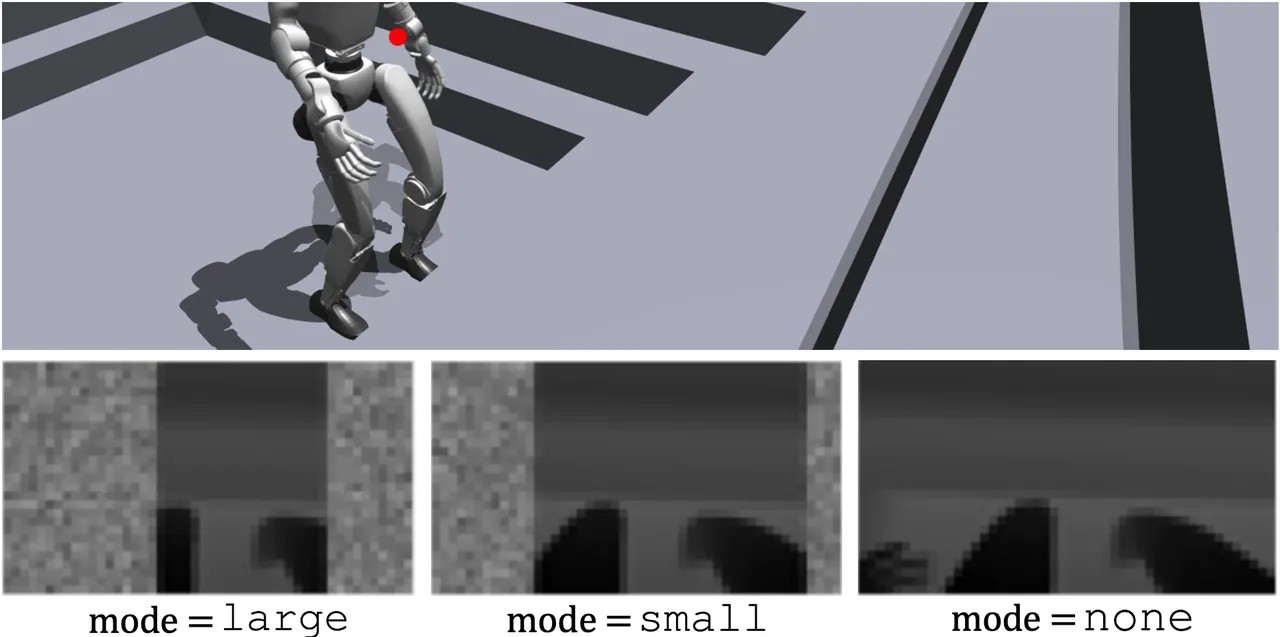
Fig. 5: RSM modes. Random side occlusion forces reliance on central visible geometry.
flowchart TB
    subgraph S1["Stage 1: Terrain Experts"]
        H["Privileged Height Map"] --> PPO["PPO + Force Curriculum"]
        PPO --> E1["Slope Expert"]
        PPO --> E2["Stairs Up/Down Expert"]
        PPO --> E3["Stepping Stone Expert"]
    end
    subgraph S2["Stage 2: Unified Depth Policy"]
        D["Front/Back Depth Cameras"] --> CNN["CNN Encoders"]
        CNN --> F["DFSV + RSM"]
        F --> TF["Transformer Fusion"]
        TF --> S["Visual Locomotion Policy"]
    end
    E1 --> L1["Action Regression Loss"]
    E2 --> L1
    E3 --> L1
    L1 --> S
    S --> W["Deploy Unitree G1 at 50 Hz"]
4. Experiments
The experiments address four questions: rendering scalability, architecture and distillation loss, robustness to asymmetric views and unseen widths, and real-world long-horizon performance with payloads. Stage 1 uses 4 NVIDIA L40S GPUs with 4096×4 environments for 24 hours. Stage 2 uses 8 L40S GPUs with 1024×8 environments for 12 hours.
During distillation, depth images are captured at 10 Hz with a $101^{\circ}\times 69^{\circ}$ field of view, rendered at $240\times 135$, and downsampled to $48\times 27$. Simulation can support four cameras. Real deployment uses two ZED 2i cameras in front-back configuration because Unitree G1 provides mounting holes on the front and rear torso shell. Real depth images are captured at $1280\times 720$ and downsampled before inference.
| Rendering Method | Dynamic Mesh | 1 Camera VRAM/Iter | 2 Cameras VRAM/Iter | 4 Cameras VRAM/Iter |
|---|---|---|---|---|
| IsaacGym PhysX | Yes | 16.8 GB / 35.6 s | 22.5 GB / 70.1 s | 33.9 GB / 146.5 s |
| IsaacSim RTX | Yes | 17.5 GB / 5.3 s | 23.2 GB / 7.6 s | 34.4 GB / 12.6 s |
| IsaacSim Warp | No | 12.8 GB / 3.5 s | 15.1 GB / 5.9 s | 20.7 GB / 9.1 s |
| RPL (Algorithm 1) | Yes | 13.3 GB / 1.3 s | 14.6 GB / 1.5 s | 17.3 GB / 1.9 s |
Table I shows that RPL is about five times faster than IsaacSim Warp, the fastest prior option, while also supporting dynamic robot meshes. The speed advantage grows with camera count. This makes it practical to train a policy under realistic self-occlusion and multi-camera observations instead of relying on simplified static rendering.
Table II reports terrain levels for different camera configurations. In bidirectional locomotion, a single downward camera reaches only 5.1 on stepping stones, while front-back and four-camera policies reach 6.0. In omnidirectional locomotion, the downward camera drops to 3.0 on stepping stones. The front-back camera setup improves this to 4.5, and four cameras reach 4.6. Sparse footholds require visual coverage aligned with each walking direction.
| Task | Policy | Slopes | Stairs Up | Stairs Down | Stepping Stones |
|---|---|---|---|---|---|
| Bidirectional | Expert | 6.0 | 6.0 | 6.0 | 6.0 |
| Bidirectional | 1 Down | 6.0 | 6.0 | 5.9 | 5.1 |
| Bidirectional | 2 Front-Back | 6.0 | 6.0 | 6.0 | 6.0 |
| Bidirectional | 4 Cameras | 6.0 | 6.0 | 6.0 | 6.0 |
| Omnidirectional | Expert | 6.0 | 6.0 | 6.0 | 5.6 |
| Omnidirectional | 1 Down | 6.0 | 6.0 | 5.9 | 3.0 |
| Omnidirectional | 2 Front-Back | 6.0 | 6.0 | 5.9 | 4.5 |
| Omnidirectional | 4 Cameras | 6.0 | 6.0 | 6.0 | 4.6 |
Architecture comparisons evaluate CNN+MLP, CNN+RNN, CNN+Transformer, and U-Net+Transformer. CNN+Transformer achieves the lowest distillation loss. The U-Net reconstruction baseline is incompatible with random side masking because the intermediate height-map reconstruction depends on complete lateral context. Attention-based fusion is therefore preferable for partially observed depth.
The OOD study uses a MuJoCo course with a narrow 1.2 m stair section followed by stepping stones. Without RSM, backward descent fails when stairs become narrower than the training distribution. Without DFSV, forward descent fails when the front camera sees stairs while the rear camera still sees stepping stones. Full RPL completes both cases.
Real-world deployment runs the transformer policy at 50 Hz on an NVIDIA Jetson Orin NX 16GB. Depth capture and policy inference communicate through shared memory. The robot completes a roughly 50 m course with a 20° slope, stairs with different step lengths, and stepping stones with 60 cm gaps. It also bends down to pick up and carry a 2 kg payload throughout the course. Figure 6 shows the terrain course.
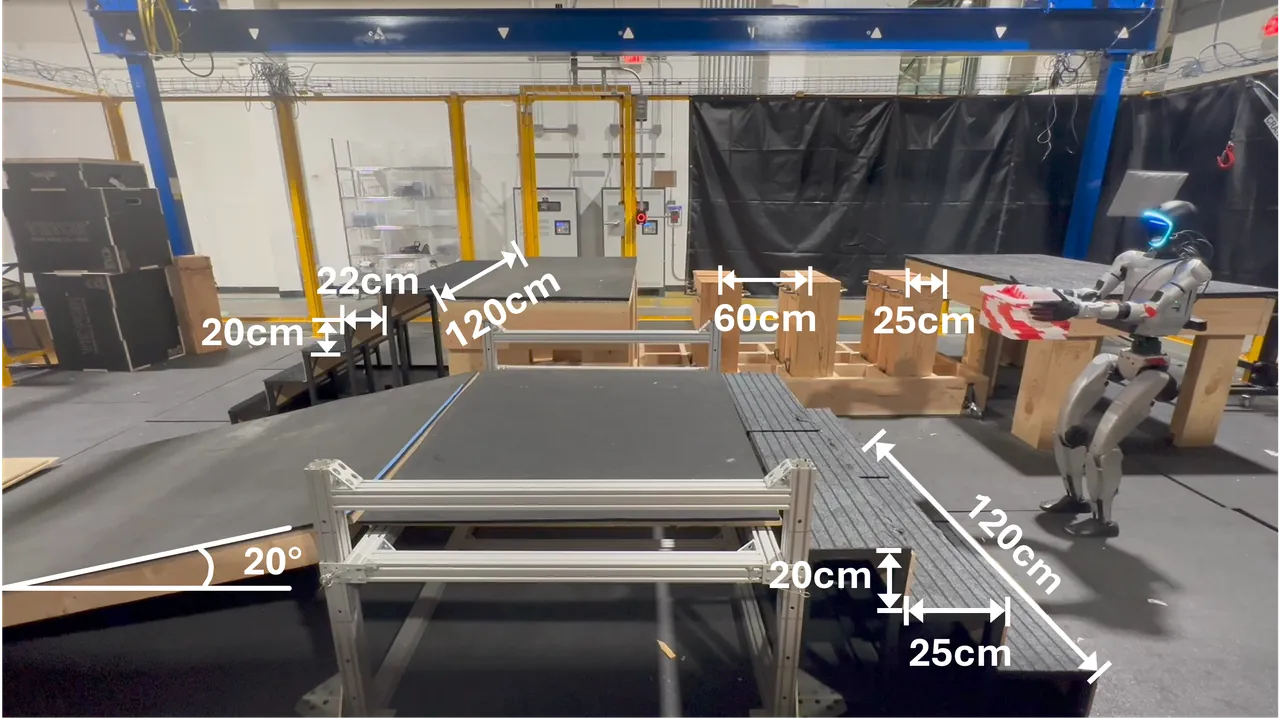
Fig. 6: Real terrain course with annotated slope, stair, and stepping-stone dimensions.
5. Discussion
RPL connects two normally separate problems: producing realistic multi-depth observations during training and handling asymmetric viewpoints during deployment. Without scalable rendering, multi-camera distillation is too expensive. Without DFSV, additional cameras can introduce conflicting information instead of improving perception.
The current experiments focus on structured hard terrain such as slopes, stairs, and stepping stones. Softer ground, slippery surfaces, moving obstacles, or interactions with other people remain outside the reported scope. The authors also note that sideways locomotion was not demonstrated on the real robot.
Reproducibility currently depends on the promised code release. The most sensitive parts are the Warp ray-casting kernel, reward weights, camera noise model, and deployment code for shared-memory inference. Until the repository appears, direct comparison with RPL will be difficult.
6. Limitations
The authors identify two main limitations. First, real-world sideways locomotion is not demonstrated, even though omnidirectional policies were trained in simulation. Distilling expert-level omnidirectional performance across all terrain families remains difficult. Second, RPL mostly relies on fixed camera viewpoints and does not learn active exploration or viewpoint selection for heavily occluded or ambiguous loco-manipulation scenarios.
From an independent perspective, RSM simulates narrower terrain but not wider terrain or entirely unseen geometry combinations. The random masking range is fixed by design, so the generalization claim is strongest for the tested narrow-width regime. In addition, the real system uses two cameras, while the four-camera setting is only evaluated in simulation; power, latency, mounting, and reliability on physical hardware are not yet established.
Another important observation is that final distillation loss does not predict OOD robustness. Variants with and without DFSV and RSM converge to similar losses, yet their deployment behavior differs significantly. This suggests that loss monitoring alone is insufficient, and dedicated OOD courses are needed to audit robustness during development.
7. Conclusion and Outlook
RPL provides a complete path from privileged height-map experts to one unified depth-based visual policy. Its dual-agent design supports payload transport, its Warp-based rendering system handles dynamic self-occlusion and scalable multi-camera training, and DFSV with RSM improves robustness to asymmetric views and unseen widths. Real experiments on Unitree G1 demonstrate long-horizon bidirectional walking over a 50 m course with a 2 kg payload.
Future work could explore active camera control, true sideways and omnidirectional deployment, richer terrain randomization, and reproducible comparisons once code is released. If the multi-depth rendering system is integrated into a general humanoid training framework, RPL can serve as a practical baseline for perceptive loco-manipulation.