OPEN SOURCE DEEP DIVE
REA: one MCP and CLI that puts reverse engineering inside coding agents
MIT-licensed reverse-engineering MCP server and CLI. One npx rea-agents setup pulls Hopper/Ghidra/IDA, pwntools, JADX, Binwalk and CDP behind a single tool contract and registers it into Claude Code, Codex or Cursor, covering twelve target classes from native binaries, JS/Electron, .NET, Android and firmware to EVM bytecode and websites. Its stance is evidence-first: observed and inferred edges are labelled separately, missing evidence is reported as unknown rather than empty or false, provider bindings are immutable with no silent fallback, and REA never kills a process it cannot prove it owns.
What it is
REA (Reverse Engineer Anything) is an MCP server plus a matching CLI that hands reverse-engineering capability to your coding agent. One command, npx rea-agents setup, registers its MCP server and a set of matching workflow instructions into Claude Code, Codex, Cursor, Gemini CLI, Grok Build and other hosts. After that you can tell your agent "work out how the search feature in Notes actually works, show me the evidence, then implement something similar in my project", and the agent will decompile the binary, follow the renderer's clipboard call through preload and IPC into the main process, and come back with conclusions plus the evidence supporting them. The repo sits at 26,401 stars / 2,978 forks / 85 watchers, MIT licensed, TypeScript, published to npm as rea-agents (v6.1.0), with docs at rea.tools.
The tagline is unusually precise: "See a feature you like. Understand how it works, down to the binary level." This is not another tool that helps AI write code. It helps AI read code that has already been compiled and shipped by somebody else. Within the AI Coding category it fills the input side: no matter how strong the model is, if it cannot see the target program it can only guess.
By the numbers
| Item | Value |
|---|---|
| Repository | morluto/rea (MIT, TypeScript, MCP name io.github.morluto/rea) |
| Stars / Forks / Watchers | 26,401 / 2,978 / 85 (as of 2026-10-09) |
| Created / Last push | 2026-04-14 / 2026-10-09 (release rea-agents 6.1.0 (#1106); five months to 26k stars) |
| npm package | rea-agents v6.1.0, two bins: rea and rea-agents, both pointing at scripts/rea.mjs |
| Runtime | Node.js ^22.19.0 || ^24.11.0 || >=26.0.0 plus npm |
| Source size | 1,282 TypeScript files under src/ across 24 top-level modules; largest are domain/ (409), application/ (240), browser/ (107), server/ (69), contracts/ (60) |
| Test size | 650 *.test.ts files — roughly one test file per two source files |
| Cross-language bridges | bridge/ carries Python (Hopper, mitmproxy, pwntools, pwndbg, an LLDB tracer), Java (Ghidra, JADX) and Swift (native UI children, process run-token reader) |
| Docs | 40+ guides under docs/ plus 3 ADRs; README officially translated into 15 languages |
| Supported agent hosts | Claude Code, Codex, Cursor, Gemini CLI, Grok Build, and any client that can attach to a local MCP server |
The problem it attacks
Reverse engineering has always been expert tooling plus expert intuition. Hopper, Ghidra and IDA each have their own GUI and scripting surface; pwntools, JADX, Binwalk and mitmproxy each own one slice. Results live in a person's head and in throwaway scripts. Almost none of this is usable by an LLM agent: an agent has no eyes for a GUI, and no instinct for judging whether a given decompiler output is trustworthy.
REA's move is to pull all of those engines behind one uniform tool contract and expose that contract over MCP. It does not implement its own decompiler. It is a provider router with an evidence ledger: Hopper over a Unix socket bridge, Ghidra over a headless Java bridge, IDA through an upstream MCP adaptation, offline ELF and core dumps through caller-supplied pwntools, EVM bytecode through EVMole (WASM inside a bounded worker), browsers through CDP/Playwright, Android through a version-pinned headless JADX, firmware through Binwalk/Unblob, .NET through static metadata reads.
What makes it more than a wrapper is that the project is explicit about its own position. One README sentence is effectively the design charter: "Analysis runs locally and returns observations, limitations, and unknowns." The agent does not receive "I think this function computes the stereo pan". It receives: these instructions at these addresses, this pseudocode produced by this engine at this version, this inference resting on that observation, and these points marked unknown because they could not be resolved.
Architecture: two entry points, one session, many providers
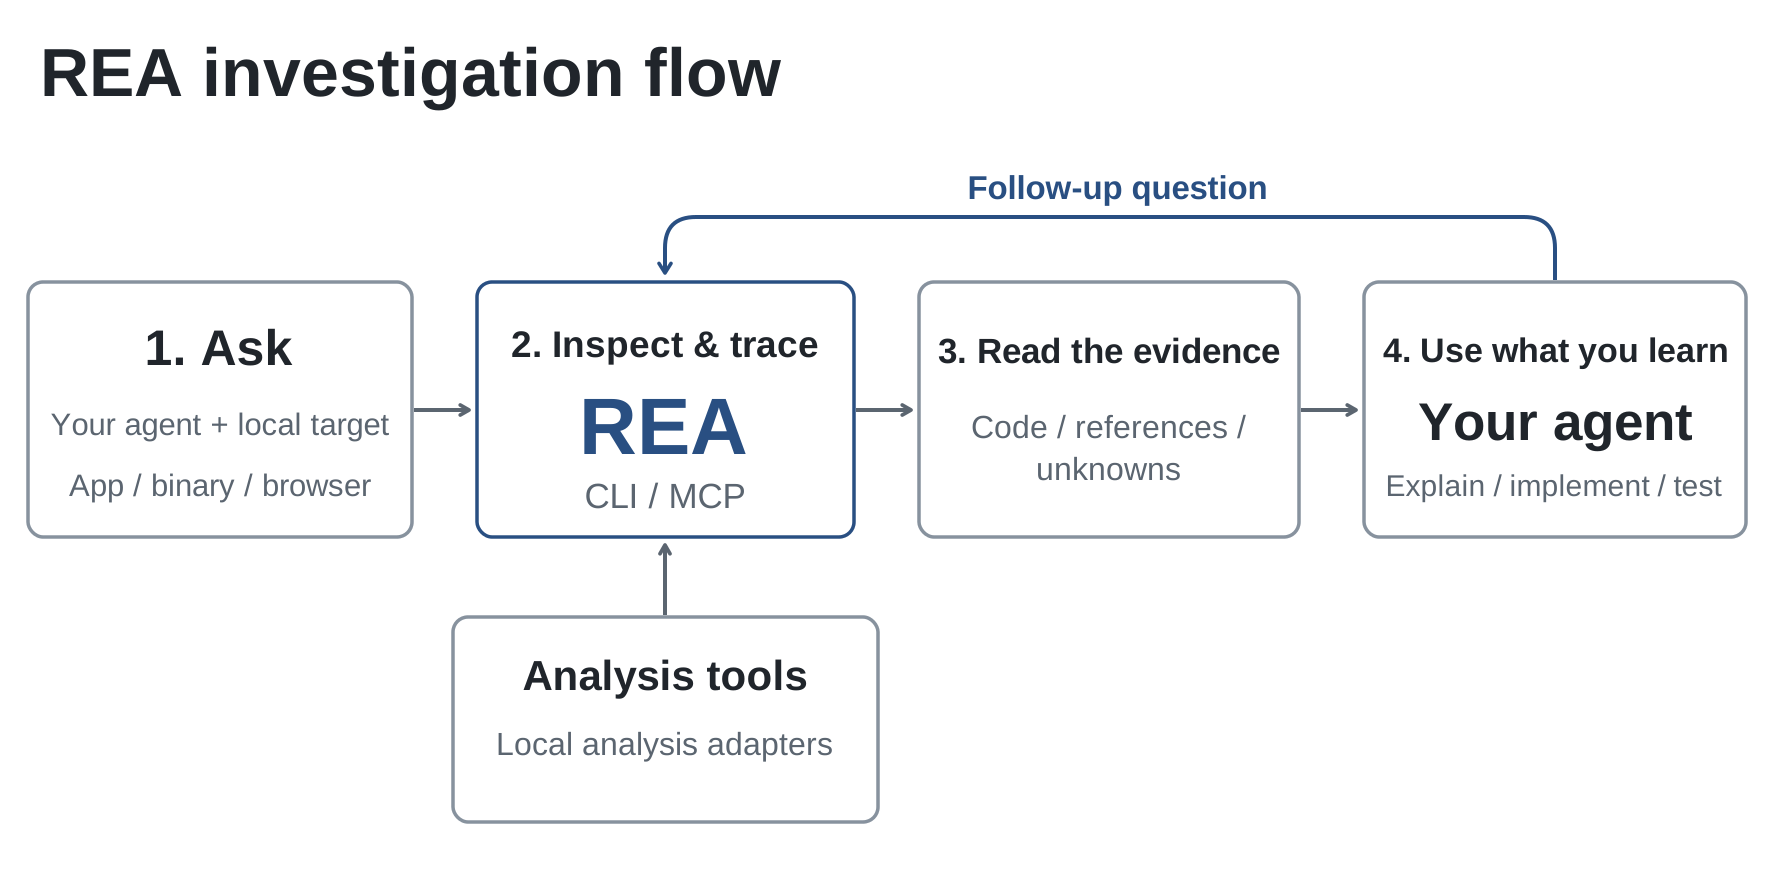
The layering is legible straight off the directory tree:
- Entry points.
src/cli.tsis the one-shot CLI process,src/main.tsis the stdio MCP server,scripts/rea.mjsis the package dispatcher. Both entry points run the same application workflows and the same evidence contracts — the CLI is not a reduced edition of the MCP server, it is a second front end over one body of logic. - Composition.
src/composition/(18 files) holds typed factories that wire providers, sessions and recorders together;src/server/(69 files) only translates the MCP protocol and carries no analysis logic. - Application layer.
SessionProviderRouterplusBinarySessionare the core: one immutable deep binding per target.AnalysisProviderRegistryproduces a deterministically sorted candidate list; when selection is unclear it reportsambiguousand never silently falls back. Alongside them sit InvestigationRecords, the EvidenceLedger, Unknown ownership, a snapshot cache, and JavaScript artifact reconstruction. - Providers.
src/hopper,src/ghidra,src/ida,src/evm,src/browser,src/dotnet,src/android,src/firmware,src/inspectorandsrc/referenceeach wrap one engine and expose only provider-neutral contracts upward. - Process foundation.
src/process/(44 files) owns process groups, private runtime roots, deadlines and ownership.native/windows/is a Node-API addon (filesystem.cc,process.cc) that backsWindowsOwnedProcess,WindowsPrivateRuntimeandWindowsAuthorityinsrc/windows/for NTFS admission, DACLs and Job Objects.
Session contracts: bind once, never swap engines behind your back
This is where the design density clearly exceeds a typical tool project. A few specifics worth calling out:
Provider binding is immutable. open_binary takes a concrete provider id or auto. After a successful deep open, the session exposes one immutable provider, a concrete version, the selection source and a complete analysis profile through analysis_provider_binding. The docs state it flatly: "A selected provider is never replaced automatically after a runtime failure." For an agent this matters enormously — a silent engine swap means two consecutive conclusions came from two different decompilers and the model has no way to notice.
Availability is reported per tool, not as a global flag. Calling binary_session with {} returns tool_availability: for the current target, provider, host and negotiated client capabilities, every tool is either available or unavailable, with a reason and a remediation. It also reconciles the live session against caller expectations via expected_package_version, expected_catalog_digest and expected_server_path. Meanwhile tools/list always returns the complete canonical inventory including tools that are currently unavailable, and opening or closing a target does not emit notifications/tools/list_changed. The catalog is stable; availability floats; the two are kept apart.
Advertised output schemas contain no reachable recursive references, nesting is capped at ten object/array/anyOf/oneOf/allOf levels, and tests re-check the full catalog after SDK conversion alongside its generated counterpart. That is REA's own local compatibility profile, since individual model APIs impose further limits.
A run id is allocated before any provider process starts. Every successful target transition allocates analysis_run.run_id first. process_lineage reads not_observed until a dynamic provider starts, then becomes snapshots recording each started provider's identity and retained ownership observation. Each observation is either verified — launcher PID, parent PID, process group, and the descendants seen at that bounded check — or unavailable with a reason. The docs go out of their way to add: these are historical snapshots, not live process inventories, and they do not claim that no short-lived descendant existed.
Progress is never invented. Updates are monotonic, rate-bounded to at most one intermediate update per 100 ms, and a terminal update is always allowed. Unknown totals are omitted rather than estimated — REA does not fabricate percentages. Cancellation is treated as distinct from timeout. A failed cleanup surfaces through cleanup_incomplete, listing only the owned resource kinds that remain; on failure, whatever observations were collected survive in details.partial_observation and report their own partial coverage. The CLI needs no progress token and translates SIGINT into the same AbortSignal the providers receive. Then comes the sharpest constraint in the codebase: "REA never kills a process it cannot prove it owns."
A taxonomy of tool shapes: primitives first, workflows second
docs/tool-design.md is the document most worth stealing from this repo. It defines six tool shapes, and any new tool has to be classified into one of them first:
| Shape | Use it for | Contract should return |
|---|---|---|
inspect | Facts about one explicit target, address, object or resource | Relevant fields, source locations, facet-level availability |
search / list | Finding candidate targets or entities | Stable ordering and useful result context; pagination only when the format or the caller's query needs it |
trace | Relationships across code, metadata, UI resources or observations | Typed edges, supporting evidence, unresolved paths, and any genuine traversal boundary |
compare | Two explicitly identified artifacts, versions or evidence sets | Paired identity, comparable coverage, and deltas with evidence |
workflow | A distinct analyst outcome worth composing inside REA | A useful inline result, contributing evidence, and partial/unavailable facets |
observe / capture | A question that requires runtime behavior | Required authority, launch/attach behavior, real operational constraints, lifecycle and cleanup status |
The accompanying decision rules are just as sharp. Start with a primitive whenever one call can report a reusable fact about one identified object or relationship — an instruction decode, a type layout, a reference, a dispatch target, a resource graph. Escalate to a workflow only when repeated analysis shows callers keep needing the same multi-source result and REA can join the evidence without hiding important choices or uncertainty. The test it proposes is a good one: would this workflow still be meaningful for a different application that shares the relevant evidence types? If its purpose depends on one application's business rules, keep that interpretation outside the general contract and expose the underlying primitives instead.
Two explicit prohibitions follow: no opaque mode flags, and no mega-tools that fuse discovery, execution and mutation. Public tool names and result semantics must stay provider-neutral, with engine-specific parsing and protocol handling confined to adapters — "do not create parallel tools just because engines differ". Prompts are optional and concise: they may point out useful tools, but must not prescribe a call sequence when the task can be answered directly.
What you can point it at
Coverage is the most immediately visible value. Beyond Node.js and npm, every extra dependency is optional and tied to a target type:
| Target | What REA returns | Requirements |
|---|---|---|
| Native binaries | Pseudocode, assembly, strings, symbols, calls and references | Hopper, Ghidra or IDA |
| Offline ELF layout | Sections, segments, raw symbols/relocations, static mitigation candidates | Linux x64 with caller-provided pwntools |
| EVM bytecode | Dispatch selectors, byte offsets, inferred arguments and state mutability | Local raw-byte or hex input carrier |
| Recorded Linux crashes | Raw note records, per-thread registers/signals, optional mapping candidates | pwntools; GDB/pwndbg optional |
| JavaScript / Electron | Modules, imports, source maps, routes, IPC and native extension relationships | Node.js and npm only |
| Websites | Page structure, scripts, network observations, per-request screenshots | A Chrome-family browser |
| Saved network captures | Requests, responses, accessible payloads and source locations | HAR; native mitmproxy capture needs mitmdump on Linux |
| .NET assemblies | Metadata, CIL instructions, declared native dependencies, build comparison | Static inspection, no external engine |
| Android APKs | Manifest declarations, classes, decompiled methods and references | Headless JADX plus a full JDK on Linux/macOS |
| Firmware | Regions, extraction results, and what gets handed on to native analysis | Binwalk / Unblob on Linux |
| Packages and resources | File inventories, digests, plists, Apple bundle structure, extracted resources | None |
| Process behavior | Terminal output, interaction, exit and filesystem observations, plus run comparison | Linux/macOS with native PTY support |
The boundary is stated plainly: static JavaScript and .NET inspection reads the files you supply and does not run the application, whereas runtime captures execute or interact with the target under your own user permissions, with each runtime guide spelling out the effects. Ghidra additionally covers 16-bit DOS analysis and experimental Windows support.
Unknown is not empty: the evidence contract
If one rule from this codebase deserves to be copied into every agent tool ever built, it is this: "missing evidence is unknown, not empty or false."
Those three values mean different things, yet most tool outputs collapse them into one empty array or null. empty means "I looked and there genuinely is none". false means "I looked and the answer is no". unknown means "I could not look". Treating the third as either of the first two is exactly how an agent ends up confidently asserting "this application makes no IPC calls" when in reality it never opened the relevant channel.
REA therefore separates the three at the contract level, and keeps observed edges distinct from derived or inferred ones, with effects declared truthfully — whether a call launches a process, touches the network, or writes to disk. Evidence records retain artifact identity, source locations, observations, inferences and unresolved findings, and can be validated, exported to canonical form, or diffed as bundles through rea evidence-import, evidence-export and compare. Exports preserve an existing destination unless --overwrite is explicit.
Snapshotting follows the same discipline: a cached result is reused only when target bytes, operation, parameters, provider and settings all match. Mutations and cursor-dependent calls are excluded from the cache entirely, and snapshot files stay local with owner-only permissions.
The replay engine it deleted
The single best indicator of this team's judgement is the status line on docs/adr/0002: Superseded — the controlled JavaScript replay tool was removed, with the design retained as historical context.
The intent behind that tool was reasonable: execute selected, extracted JavaScript modules against controlled inputs and deterministic stubs so that parsers, sanitizers and serializers could be compared across versions. The ADR then walks through why that is a different kind of problem. Source recovered from an application is untrusted code. It can read files, contact services, spawn processes, exhaust resources, corrupt the analysis process, forge protocol output, or interfere with another same-user process — deliberately or by accident. The conclusion is worth quoting: "A JavaScript realm or Node.js vm context is useful for constructing an API surface, but it is not a security boundary." Node itself documents its permission model as protection against accidental access by trusted code, not as containment for malicious code.
Crucially, the team refused to stretch existing authorities to cover the new behavior. browser_observe authorizes passive attachment to an already-running, operator-owned target — not evaluation, navigation, input or target lifecycle changes. process_capture authorizes one explicitly declared host process scenario and states outright that it is not a sandbox. So the capability was removed. docs/roadmap.md records the two pull requests: #555 removed REA permission grants, scope ceilings, elicitation and repeated approval fields; #572 removed the replay engines, the Node characterization prepare/execute flow, and the plan-only managed runtime correlation tool. The current position is that local operations use the current user's OS permissions — a retreat from "we built our own permission system" to "we will not pretend to offer isolation we cannot deliver".
In an ecosystem where "sandboxed agents" is a marketing bullet point, deleting your own sandbox narrative and leaving an ADR explaining why is rare engineering honesty.
Reconstruction obligation ledgers: making "I rebuilt it" a decidable claim
A second abstraction worth attention is build_reconstruction_obligation_ledger (CLI: rea build-reconstruction-obligation-ledger), which turns authenticated Evidence records into a deterministic list of reconstruction claims.
It is deliberately conservative to the point of being harsh. Static Application Graph facts create candidate obligations only; they do not prove runtime or process behavior. A required obligation closes only when one manifest binding supplies a unique owner, any required parser/schema/domain type, every required case fixture, and a passing verifier whose authority is comparable to the original observation. The verifier must enumerate the obligation ID, and its result must be present in the input Evidence bundle. Contradictions, duplicate definitions or owners, residual unknowns, missing dependencies and unavailable authority all keep closure open or failed.
The docs even ship an empty request as a client-integration smoke test. It is valid, and it returns an unknown ledger with zero obligations, because "absence of source Evidence never claims closure". That is the whole evidence philosophy applied to the last step: even "I checked nothing" is forbidden from masquerading as "I checked everything and it's fine".
Three showcases: how deep it actually goes
The three showcases in the README are the best available evidence of what this class of tool can really do, because each one has a reproducible endpoint:
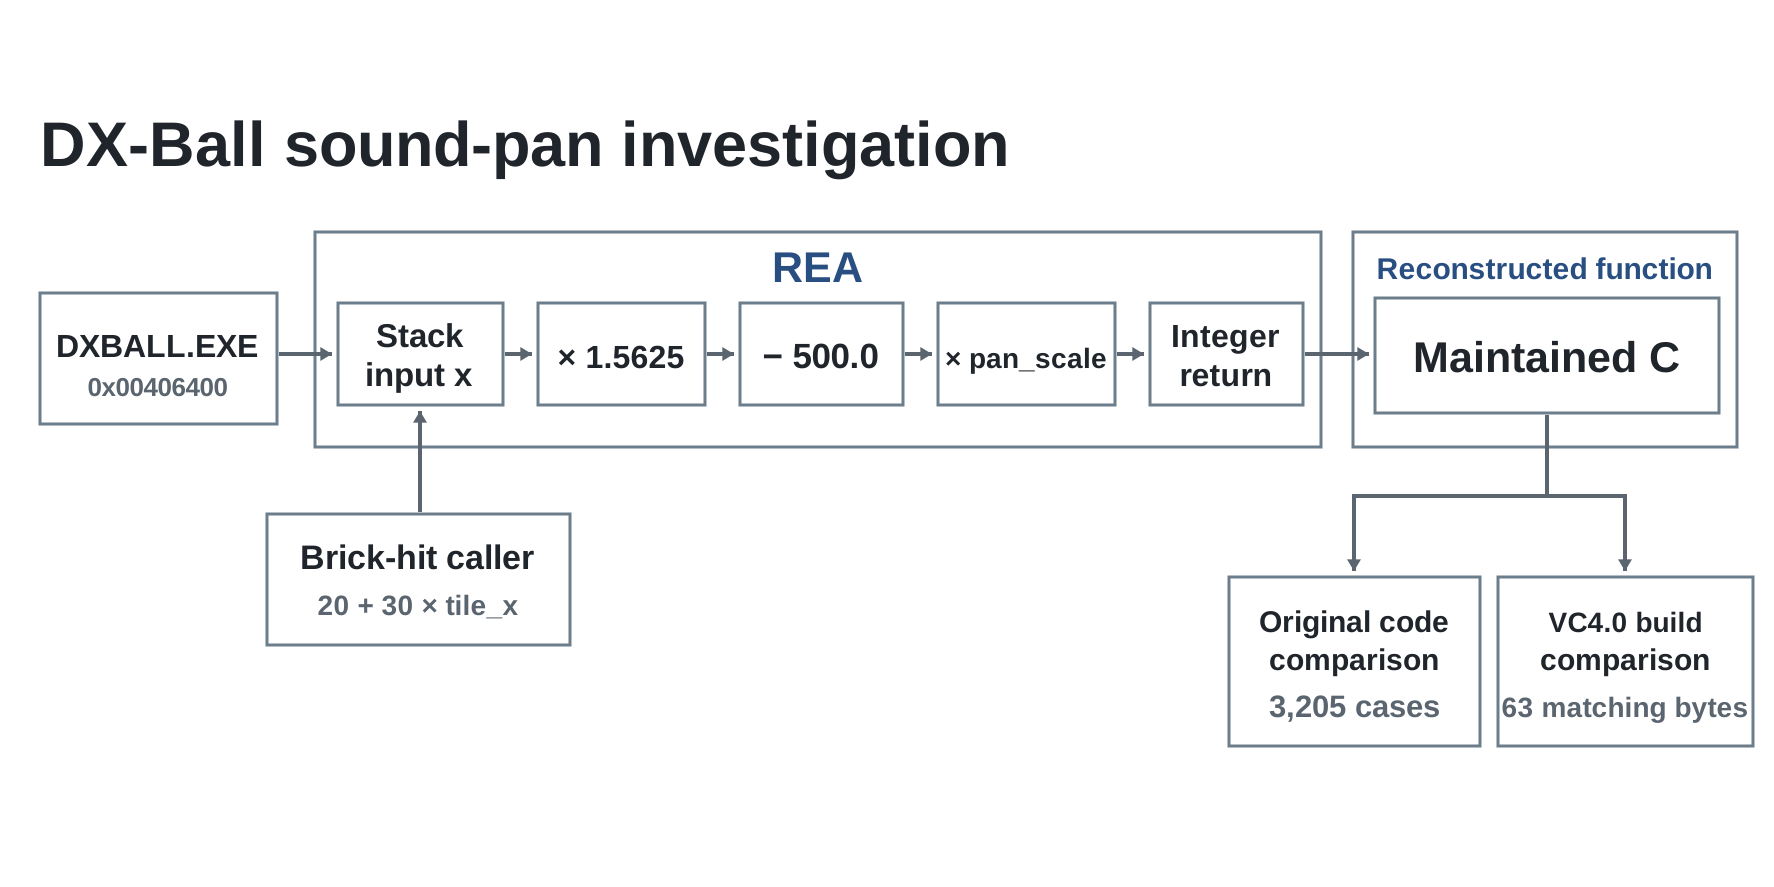
- DX-Ball: reconstructing the stereo-pan computation. Following a sound call to a helper at offset
0x00406400inDXBALL.EXEthat takes a positional inputxoff the stack, multiplies it by 1.5625, subtracts 500.0, scales by apan_scaleand returns an integer; the brick-hit logic calling it computes20 + 30 × tile_x. Inspecting the instructions and turning incomplete pseudocode into C, the reconstruction passes 3,205 original x86 test cases and reproduces all 63 bytes of the VC4.0-compiled function. Byte-for-byte agreement is the hardest acceptance criterion in reverse engineering — not "behaves roughly the same", but "the compiler output matches". - Notion: tracing the Electron clipboard bridge. Locating the renderer's clipboard API, following it through preload and IPC into the main process, and inspecting rich-format clipboard data. This is the canonical "I want to build the same feature in my own product" scenario, and it crosses precisely the process boundary Electron makes hardest to see.
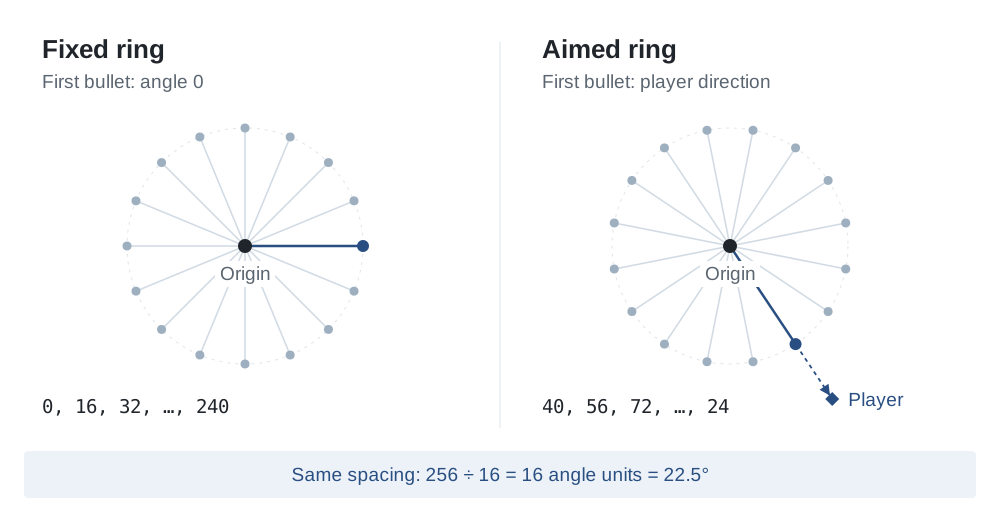
- TH04: recovering the DOS bullet-ring math. Inspecting 16-bit instructions from an original PC-98 game and recovering the ring arithmetic: that generation of code defines a full clockwise turn as 256 angle units, so sixteen bullets are spaced 256 ÷ 16 = 16 units apart (22.5°). A fixed ring starts at angle 0 (0, 16, 32 … 240); an aimed ring starts at the player's direction (for a direction of 40: 40, 56, 72 … 24). The rebuilt C++ is then compared against the period compiler's output. Thirty-year-old 16-bit x86, taken on through Ghidra's DOS support.
Installing and day-to-day use
To wire it into an agent:
npx rea-agents setupPick the host, review the planned changes, approve. Setup adds REA's MCP server and the matching workflow instructions, backing up existing configuration, then you restart the agent. Native analysis can reuse an existing Hopper, Ghidra or IDA install; setup can also install Hopper once you approve it, and static JavaScript analysis needs none of them. setup --dry-run returns planned and exits 0 without writing anything (a cancelled setup also exits 0); it exits 1 for needs_confirmation or needs_human.
Or drive it straight from a terminal, with no global install:
npx -y rea-agents@latest analyze-javascript-application /absolute/path/to/app --json

# native analysis (configure a provider first)
rea analyze /absolute/path/to/program --provider ghidra --json
rea search  /absolute/path/to/program "search" --provider ghidra --json
rea decompile /absolute/path/to/program 0x1000 --provider ghidra --json
rea xrefs   /absolute/path/to/program 0x1000 --provider ghidra --json
rea trace   /absolute/path/to/program "search" --provider ghidra --json

# providers and readiness
rea providers --json
rea capabilities --json
rea doctor --provider ghidra --json
A few practical details: the default terminal format is TOON, and --json is for JSON consumers — output selection never changes operation status. Exit codes are 0 completed (the result may still carry partial evidence, warnings or unresolved questions), 1 could not complete, and 128+N ended by signal N. REA_ANALYSIS_PROVIDER sets a standing preference that an explicit --provider overrides, matching open_binary's provider_id on the MCP side. --snapshot persists successful results for later queries. In a pipeline, enable set -o pipefail, or a downstream jq will swallow REA's failure status.
Updates go through rea update for the CLI or npx rea-agents@latest setup for agent registration and the skill; the README stresses that the project moves fast and new releases frequently carry bug fixes.
Engineering surface
1,282 source files against 650 test files is a high water mark for this category, and the test names show what is actually being tested: ProcessOwnership.identity.test.ts, ProcessOwnership.part2/3.test.ts and ProcessOwnership.validation.test.ts split the single concept of process ownership across four suites; EvmWorkerLimits.test.ts pins the EVM worker's resource ceilings; contractSnapshot.test.ts snapshots the tool contracts themselves. docs/mcp-contracts.md adds that the machine-readable catalog at docs/public/product-catalog.json is generated by npm run build:cached and describes the exact source revision being built rather than a checked-in snapshot, with PR CI retaining it alongside the packaged skill and portable conformance projections in a generated-docs artifact.
The roadmap is equally concrete: keep generated metadata and narrative docs aligned with tools, providers, setup options and releases; expand native architecture, type and indirect-call verification across Hopper and Ghidra; connect more static extractors and runtime observations into cross-layer feature traces; improve obfuscated .NET comparison and the links between managed findings and verified native analysis; extend process, protocol, filesystem, reconnect and build-comparison coverage plus browser and Electron scenario actions; and evaluate native runtime observation through LLDB, Frida, system logs and API tracing, alongside further engines and targets such as Binary Ninja and Rizin.
Verdict: who this is for
Good fit for developers who need to understand a shipped desktop app, game or plugin without its source and want an agent in the loop; for security research and vulnerability analysis teams that need a citable evidence chain rather than a chat transcript; and for platform teams adding "reads binaries" to their own coding agent — docs/tool-design.md alone is a reusable specification for MCP tool design.
Poor fit if you expect it to judge whether a conclusion is correct. REA's stance is to hand over evidence, limits and unknowns faithfully; interpretation and decisions stay with the caller. If what you want is "just tell me what this program does", what you get is an evidence dossier that you or your agent still have to read. It is also demanding on the host: Node 22.19+/24.11+/26+, one of Hopper/Ghidra/IDA for native work, Linux or macOS plus a full JDK for Android, Linux for firmware, and historical-source import returns unsupported_host on native Windows (the project recommends running the Linux build under WSL).
26,000 stars in five months did not come from marketing. REA occupies a real gap: agents can now write code, but they still cannot read the compiled world. It fills that gap with a contract that prefers saying "I don't know" over pretending to know — which, in the current AI Coding landscape, is scarcer than yet another completion model.
SOURCE LINKS