Building Always-On Agents: A Five-Primitive Harness for Long-Running Work
Anthropic explains five runtime primitives for always-on agents: an event inbox, timers, persistent memory, permission controls, and an outbox.
Over the past few months, always-on agents have made a strong return. The useful definition is not that a process literally never stops. It is that the agent is stateful and proactive: it carries context across sessions and can take action without a person supervising every step.
Underneath, these systems still use the same basic agent loop as any other agent. What changes is the architecture around that loop. A set of primitives decides when the agent wakes up, what survives between runs, which actions it may take on its own, and how its work reaches the user.
The recent resurgence is largely a result of model progress, which has made this pattern practical to operate. First, current models exercise better judgment: they are more reliable at reading user intent and recognizing when they should check in. Second, intelligence is becoming cheaper, and long-horizon work benefits most. On one long-horizon coding benchmark, for example, Opus 5.5 cost 78% less per solved task than Opus 5. On typical workloads, the corresponding reduction was 40%.
Customers have begun asking how to bring this kind of experience into their own products. Some want to make an existing agent more proactive. Others want to build one from the ground up.
This article breaks down the primitives behind always-on agents and shows how they fit together.
The cycle behind the always-on agent
An always-on agent is not actually always on. “Always on” describes the user experience, not the process lifetime.
In reality, the agent spends most of its time asleep. It wakes periodically to do work, and each stretch of work is a run. During a run, the agent receives an event, completes its task, and saves information about what happened. The run works inside a session, the transcript of messages and tool calls associated with that work. When the run finishes, the agent goes back to sleep. The cycle can then repeat indefinitely.
The core primitives
The architecture around an always-on agent rests on five primitives: an event inbox, timers, memory, permissions, and an outbox. Each one owns a separate part of the lifecycle.
Event inbox
Most AI agents run only when the user sends a message. Always-on agents can be triggered by many other event types, including webhooks, scheduled tasks, and background jobs.
One tempting design is to let every event source call the agent directly, but that creates several failure modes. Two events can arrive at the same time and start competing runs. A crash can lose an event entirely. There is also no durable place to inspect what has arrived but has not yet been processed.
The event inbox solves these problems. Instead of calling the agent, every source writes an event to an inbox, and a worker picks it up.
The simplest version has three components:
- A durable list of events, usually a database table.
- A handler, usually an HTTP endpoint, that writes incoming events to the list.
- A worker, usually a background service, that reads from the list and starts runs.
The inbox should track the status of every event, and events can be deduplicated using unique identifiers supplied by the source. A relational database works well here: each event is appended as a row. A good starting point is one inbox per user, with further partitioning only when more parallelism is needed.
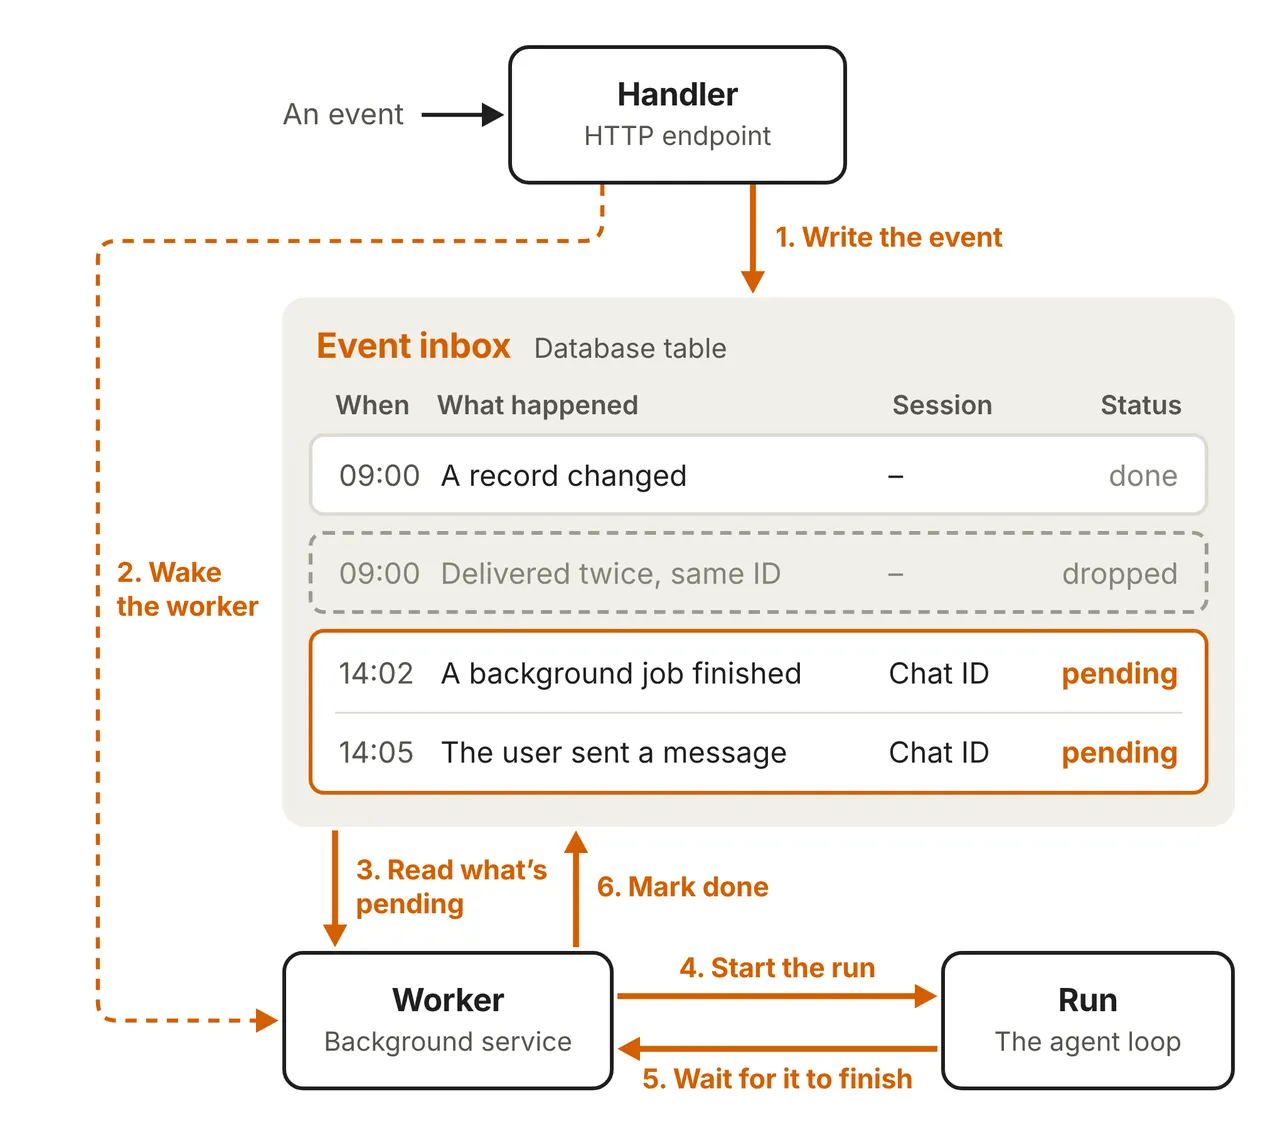
When a new event arrives, the handler writes it to the inbox and wakes the worker. The worker reads the pending events and starts a run. Events that continue earlier work, such as a reply from the user, resume an existing session. Everything else starts a new session.
The worker then passes the events to the agent loop, waits for the run to complete, and marks the corresponding events as done. The implementation can become subtle, so several practices matter:
- Acknowledge events quickly. Some sources, especially webhook providers, treat slow responses as failures. The handler can perform lightweight checks, but deeper verification, such as prompt-injection screening, belongs inside the run.
- Treat the inbox as the source of truth. When a worker wakes, it should first pull the latest state from the inbox. If the worker dies mid-run, a replacement can recover the same event and retry it.
- Allow only one active worker per inbox. This prevents two runs from duplicating work or overwriting each other. If another event arrives during a run, the system can push it to the next run, fold it into the current run, or interrupt and restart.
- Batch pending events. If a user sends several messages in succession, the worker can merge them into one run so the agent responds once instead of producing several overlapping replies.
Timers
Along with the event inbox, timers let an always-on agent be proactive. They generally fall into two categories. A follow-up is a deadline the agent sets for itself, such as checking back on a reply. A schedule is a recurring task with a known cadence, such as publishing a daily newsletter.
Timers belong in their own durable store, usually a separate database table. The inbox should contain only events that are ready to be worked on. A follow-up and a schedule can share most of a schema, but a schedule must also track its recurrence.
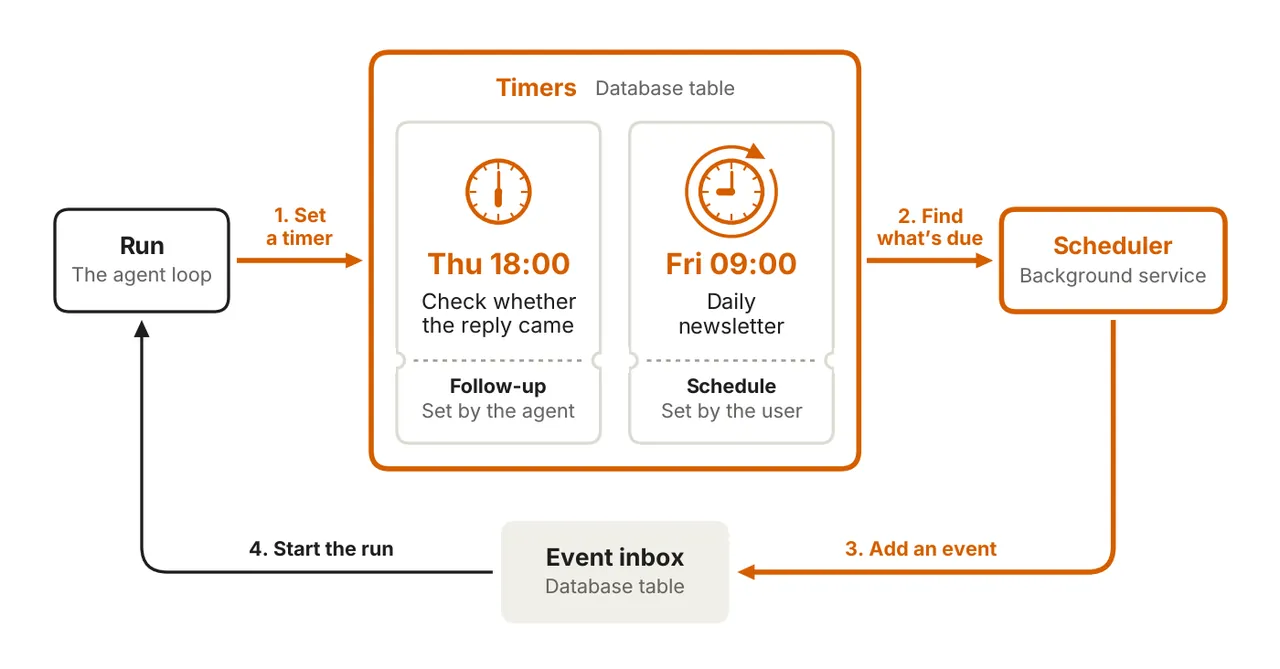
A timer never starts a run by itself. A scheduler, usually a background service, polls the timer store at a fixed interval and fires whatever is due. On each pass, it:
- Scans the store for timers whose due time has arrived.
- Updates each timer according to its type: mark a follow-up complete, or advance a schedule to its next occurrence.
- Adds an event to the inbox and wakes the worker.
The scheduler can be a custom service or a durable execution engine, depending on the operational constraints of the product.
Memory
Always-on agents work across many separate runs, so continuity depends on memory. Like the event inbox and timers, memory should have its own store.
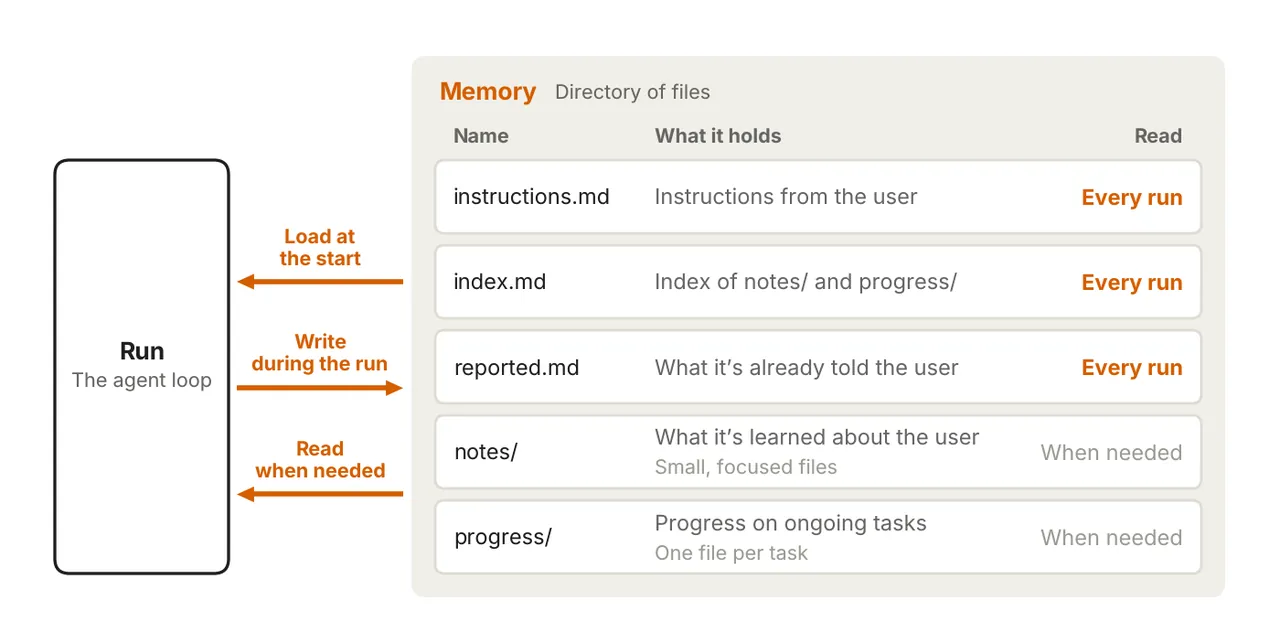
In Anthropic products such as Claude Code’s auto memory and the Messages API’s memory tool, memory is implemented as a directory of files. For an always-on agent, those directories should map to durable storage, typically a database or object store, so that memories outlive any individual worker.
A useful rule is to store only what the agent cannot look up again. If information already lives in another system of record, such as an issue tracker, save a pointer instead of copying the data into memory.
An always-on agent generally needs four kinds of memory:
- User instructions: Save instructions about agent behavior in their own file and load that file at the start of every run. The user will not always be present to steer the agent, so durable instructions must carry over.
- User notes: Record what the agent has learned about the user, including role, preferences, and corrections. Start with one file; as notes grow, split them into smaller files. In that case, load only an index at the start of each run and pull in individual files when more detail is needed.
- Past messages: Track what the agent has already told the user so it does not repeat itself. This can live in a separate file loaded at the start of each run, or the worker can load the last few messages exchanged with the user.
- Task progress: For each ongoing task, keep a progress file describing what is done and what remains. A new run can read it and continue where the previous run stopped. As with user notes, load an index first and retrieve individual files only when necessary.
The categories above describe memory written during normal runs. A system can also add a dreaming process that reviews past sessions and curates memory. Dreaming can remove outdated entries and identify patterns that become visible only across many runs. Anthropic’s article on agent memory covers this topic in more detail.
Inside the context window
Before doing any work, the agent loads its system prompt, tool definitions, and memory files. This baseline context is present on every run, so it should stay lean. Prompt caching can reduce the cost of repeatedly processing it.
A new session begins with only this baseline context plus the events that triggered the run. An existing session also restores the messages and tool calls from its earlier runs.
If a session grows too long, the system can either compact older messages or start a new session. Both choices lose detail, so anything that must survive should be written to memory along the way.
Permissions
Permissions carry the greatest risk in an always-on system. A run holds the user’s access and is designed to operate without direct supervision. For every tool call, it must decide whether to proceed, block the action, or wait for approval.
The components are familiar from other agents:
- Credential store: Always-on agents often need sensitive credentials, such as passwords or access tokens, to be useful. The recommended pattern is to place a proxy outside the agent’s environment. The agent sends a request without credentials, and the proxy injects the real credentials before forwarding it.
- Auto mode: An always-on agent must be able to work without constant input. Claude Code’s auto mode applies this idea by using classifiers to review higher-risk actions and block those identified as dangerous, allowing the agent to find a safer approach. Human review remains necessary for the most consequential decisions.
- Deferred tool calls: A hook can defer a tool call and wait for additional user input. The same pattern works for always-on agents that need clarification or approval before acting. When a call is deferred, the run ends and the session is saved mid-call. The request is shown to the user, for example through an interactive card built with MCP Apps, and the answer returns as an event in the inbox. That event starts a new run and resumes the saved session. While the call waits, the worker can process other events, so one approval does not block all progress.
Outbox
With most AI agents, the response streams to the user while it is generated. The user can watch the agent reason, call tools, and write an answer.
Always-on agents usually do most of their work in the background. The user should receive the outcome and a few useful details, not the entire step-by-step trace of every run.
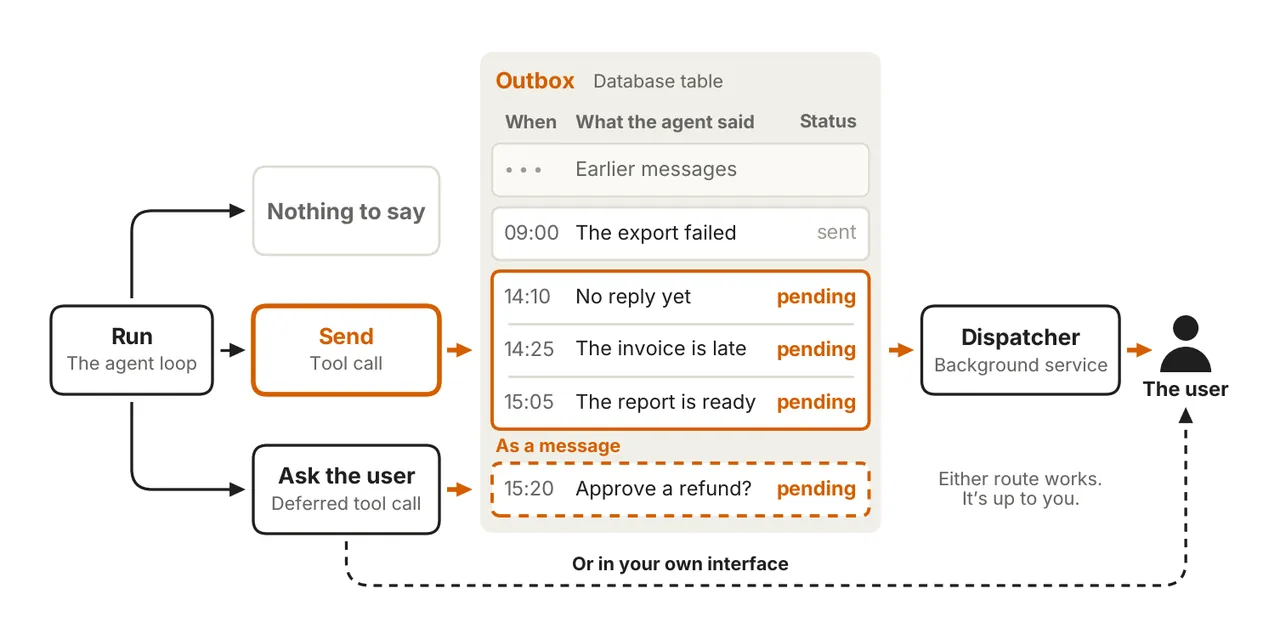
A run can end in one of three ways:
- The agent sends a message to the outbox.
- The agent decides that no message is needed.
- The agent uses a deferred tool call to request permission or more information.
Many always-on agents can start with a simple “send” tool that delivers a message directly to the user. A formal outbox becomes valuable when messages need pacing, retries, or recovery from delivery errors.
The outbox is a separate table of outgoing messages, analogous to the event inbox. A dispatcher, analogous to the worker, reads pending messages, decides what to deliver, and sends it to the user. A request produced by a deferred tool call can pass through the outbox or be shown directly in the interface.
Delivery is only one part of the problem. The agent also needs the right message frequency. An agent that sends too often becomes noisy; one that sends too rarely misses information the user needed. Evaluations can help find the balance. In practice, it is safer for an agent to begin quiet and earn more attention over time.
How everything fits together
The five primitives form one cycle rather than five isolated services:
Every run starts with an event from the inbox, whether that event came from a user message, a webhook, or a timer. When the worker picks it up, it starts a run and wakes the agent in either a new or an existing session. The agent reads memory to establish context, acts within its permissions, and writes back anything it learned. When the run finishes, it adds a row to the outbox, and the dispatcher delivers the resulting message to the user.
Together, these transitions form a loop. A run can set a timer that wakes the agent later. When the user replies to a delivered message, that reply re-enters through the inbox as another event. Each run is brief, but the loop continues indefinitely. That continuity is what makes the system feel always on.
Acknowledgements
Written by William Hu. Special thanks to Rodrigo Olivares and Michael Segner for their contributions.
Source: “Building always-on agents” by William Hu, Anthropic, November 13, 2026. Figures reproduced from the original article.
Source:Anthropichttps://claude.com/resources/articles/building-always-on-agents