Build Your Own Jev (100% Local): Recreating Fixed-Answer Scoring with SGLang
Jev-style fixed-answer scoring reproduced locally with SGLang /v1/score: single-token labels, restricted softmax, confidence-gated routing, and a 6 ms vs 1088 ms benchmark against generation.
Most LLM calls do not need newly written text. The application already knows the possible answers; it only needs the model to choose one. A support ticket that says "I was charged twice for the same subscription" must reach exactly one of three teams: billing, technical support, or account access. A normal LLM call asks the model to write an answer, a sentence, a label, or a JSON object, and the application then waits for that text, parses it, and extracts the selected team.
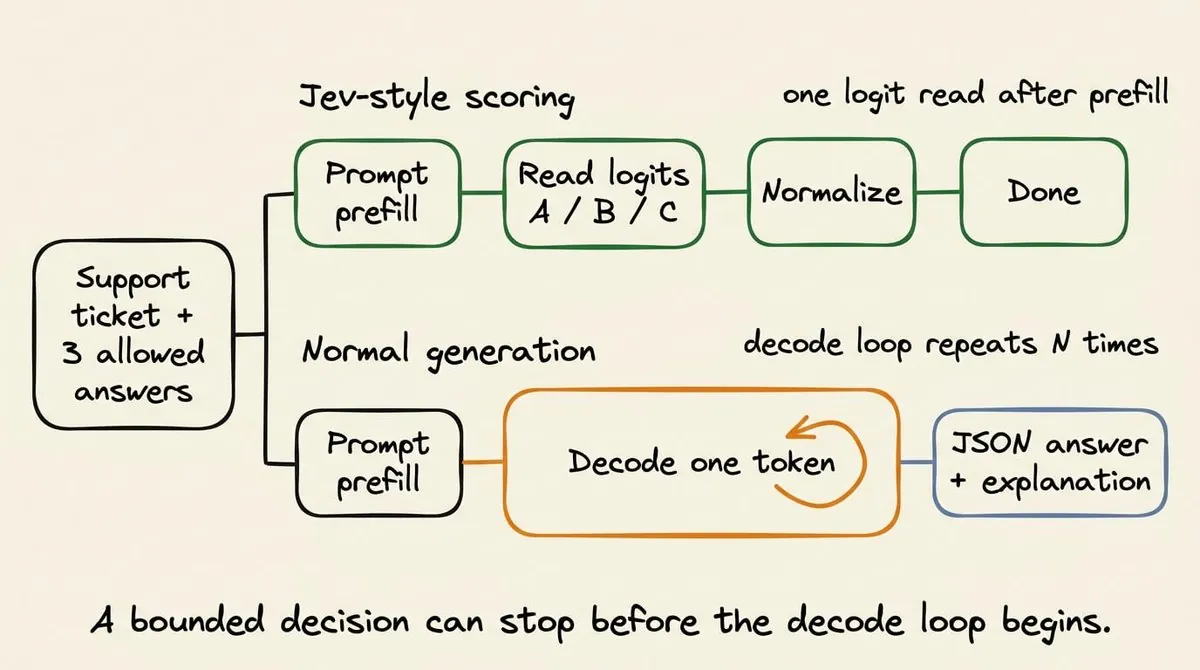
That round trip is unnecessary when every valid answer is already known. The better and more efficient framing treats the same request as a decision: the application provides the ticket and the three allowed answers, and the model returns a score for each answer in one go:
billing             0.91
technical support   0.06
account access      0.03
Billing wins with the highest probability, and the application code can see how strongly it won. This is the behavior Jev possesses, and this article reproduces it locally: one scoring request returns a decision and a probability distribution without generating a single sentence or JSON object. Jev itself is closed-source, but the inference pattern already exists in several open language models. Concretely, we implement it with SGLang's /v1/score endpoint, test it on Qwen and DeepSeek models, and compare it against structured output and ordinary text generation on the same model.
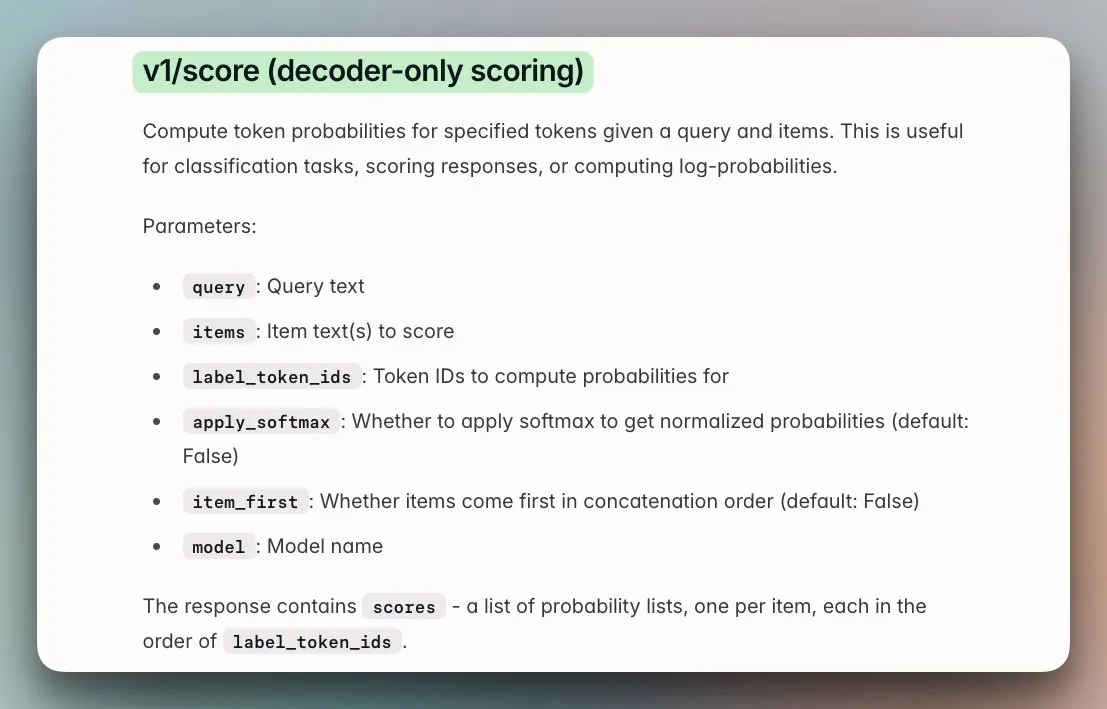
/v1/score computes token probabilities for specified tokens given a query: exactly the primitive a Jev-style decision engine needs.One expectation up front: this article recreates the inference path, not the complete Jev system. Jev also includes training and calibration work that a scoring endpoint does not provide.
Fixed-answer scoring is not structured output
It is easy to confuse Jev's mechanism with structured output, because both restrict what the application receives. They do different work inside the inference server. For the same support ticket, structured output might return:
{"team": "billing"}The schema prevents an invalid object, but it does not select the team on its own. Under the hood the model still generates the opening brace, the field name, the value, and the closing brace, one token at a time; only after generation finishes does the application read the team field.
{"team": "billing"} token by token before anyone knows the answer.With scoring, the application supplies the three teams as the complete list of valid outcomes. The server reads one model score per outcome and returns the distribution shown above. No JSON object is generated at all.
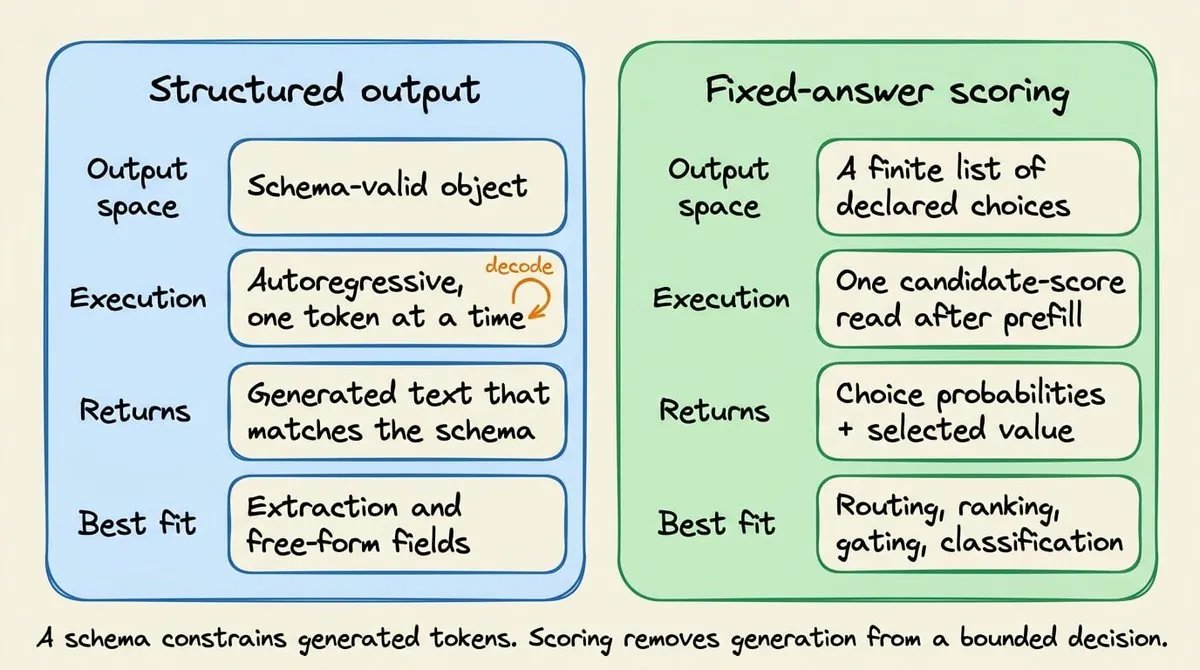
The difference becomes operational once you return all the values instead of only the winner:
Result 1                          Result 2
billing       0.91                billing       0.46
technical     0.06                technical     0.44
account       0.03                account       0.10
Both results select billing, but the first is a clear preference while the second is almost a tie. The application can route the first ticket automatically and send the second one for human review. The model only supplies scores; the rule for using them lives in application code, where it can be tested and changed. For instance, one might require the top answer to exceed 0.80 and lead the second answer by at least 0.20, i.e. accept only when $p_{\top} \geq 0.80$ and $p_{\top} - p_{2} \geq 0.20$.
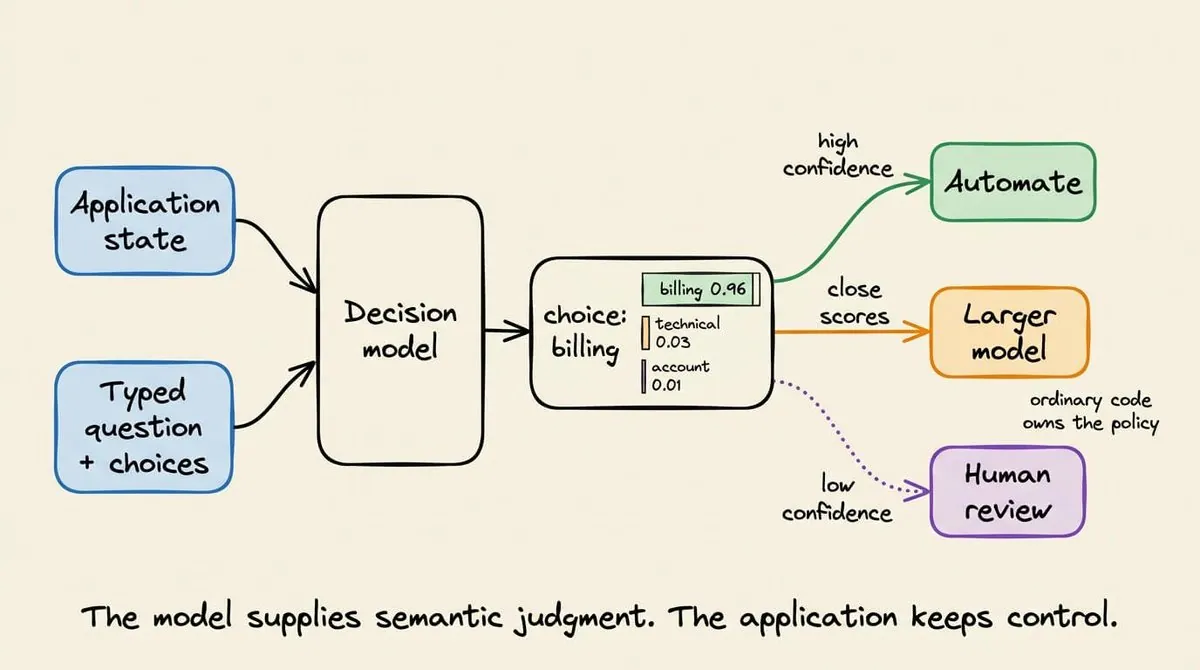
One calibration warning: a value of 0.91 means billing received 91 percent of the probability mass over these three choices. It does not prove the model is correct 91 percent of the time. Measuring that requires labeled examples. Remember the division of labor: structured output generates a valid object; fixed-answer scoring returns a distribution over answers the application already knows.
How an LLM generates the first output token
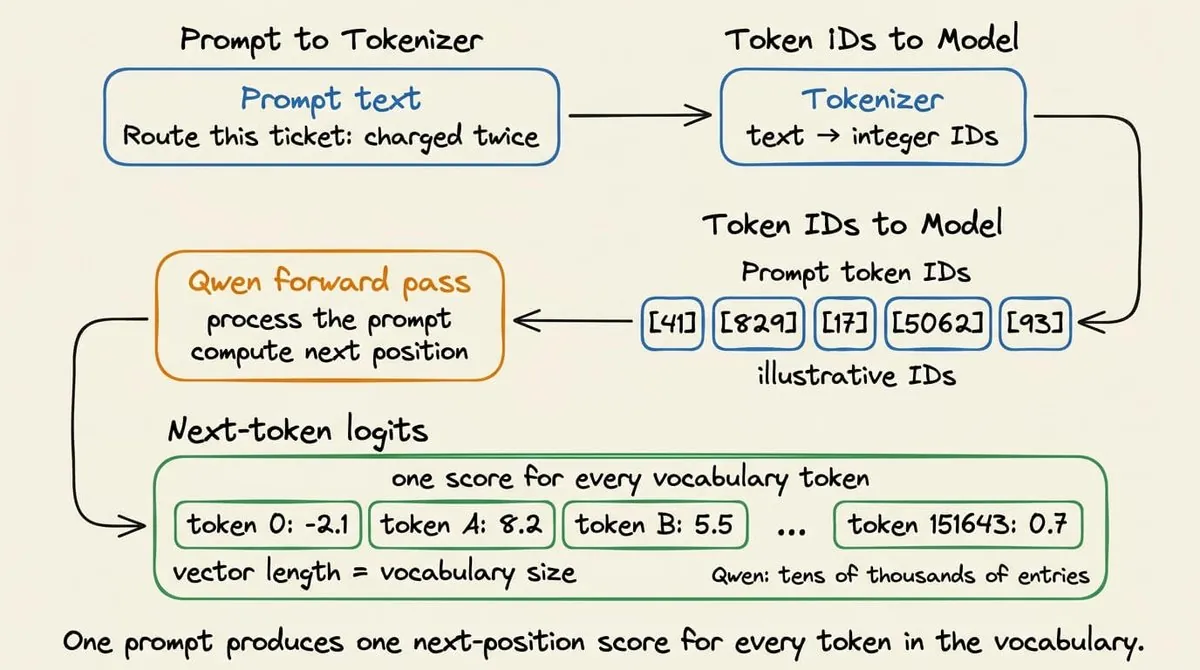
A regular generation step works like this:
- A tokenizer converts the prompt into token IDs.
- The model processes that sequence and produces a vector for the next position.
- The vector holds one number per vocabulary token. These raw numbers are logits: a larger logit means the model prefers that token as the next continuation, but they are not probabilities yet.
During normal generation the server applies the decoding rules (temperature and friends), selects one token, appends it to the prompt, and produces a new vocabulary-sized vector for the next position. Decoding repeats until a stop token or the output limit.
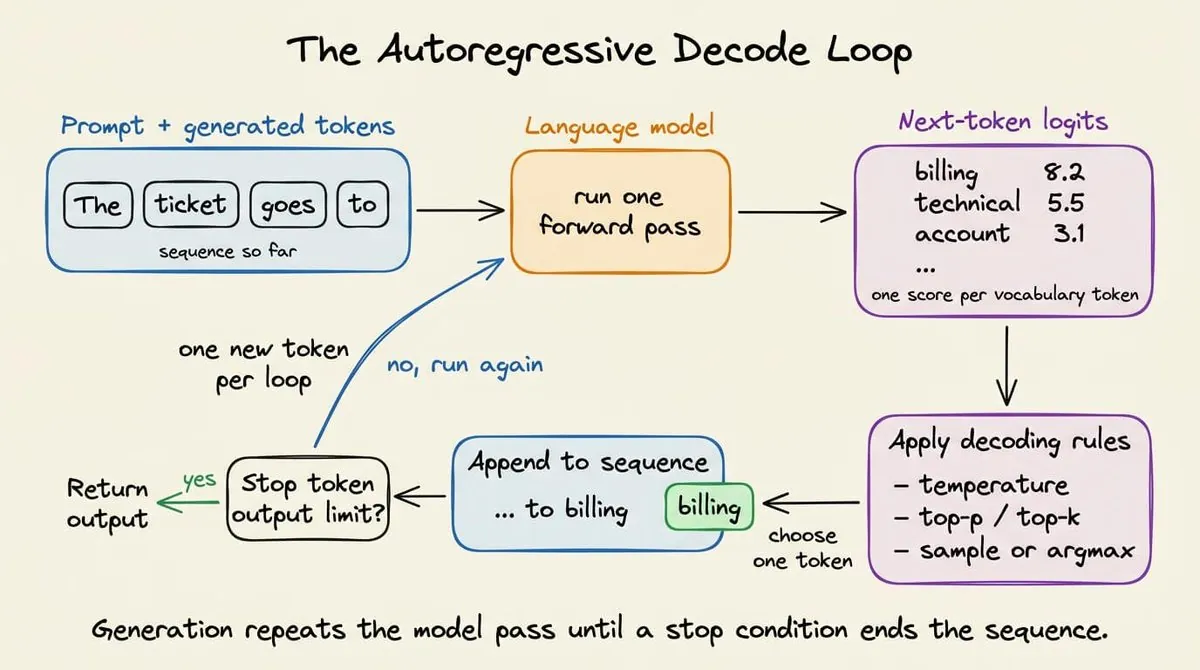
For a bounded decision we care about the first vector only. Take the support router: the application accepts three answers, and the prompt assigns each a short label:
Route the support ticket into exactly one category.

Ticket:
I was charged twice for the same subscription.

Allowed labels:
A = billing
B = technical support
C = account access

Return only the label.

Label:
"Label:" is the final text in the prompt, so the next position is exactly where the model would normally generate A, B, or C. After processing the prompt, the model produces its usual vocabulary-sized vector for that position, containing the logits for A, B, and C alongside every other token. The scoring path then performs four operations:
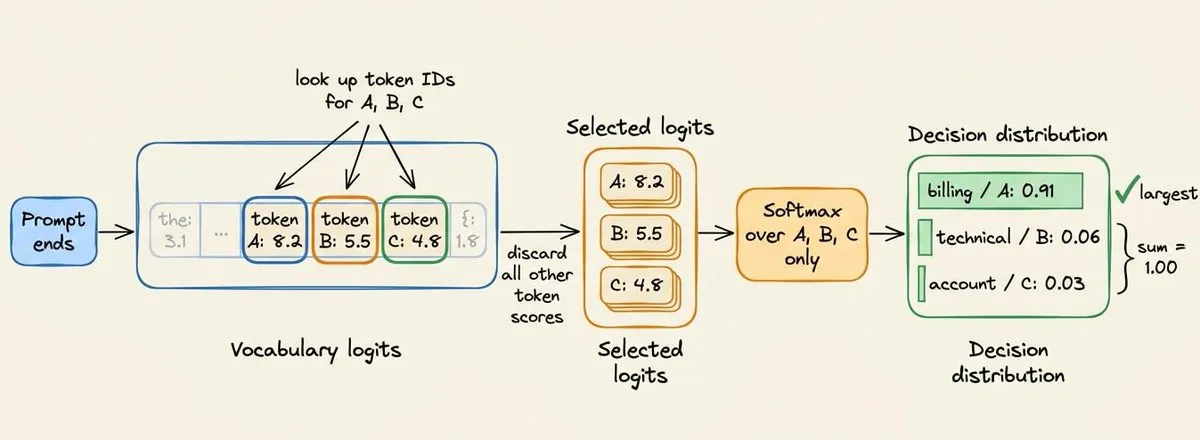
- Find the token IDs for A, B, and C.
- Read the three logits at those positions in the vocabulary vector.
- Ignore every other logit.
- Apply softmax across the three selected values.
If the selected logits are 8.2, 5.5, and 4.8, the restricted softmax produces approximately 0.91, 0.06, and 0.03:
$$p_i = \frac{e^{z_i}}{\sum_{j \in \{A,B,C\}} e^{z_j}}, \quad \mathrm{softmax}([8.2,\,5.5,\,4.8]) \approx [0.91,\,0.06,\,0.03]$$Mapping those positions back to billing, technical support, and account access gives the decision distribution. The normalization is restricted to the declared choices: we are not asking whether A has 91 percent probability across the entire vocabulary, but how the model divides its preference among A, B, and C after the application has ruled out every other response.
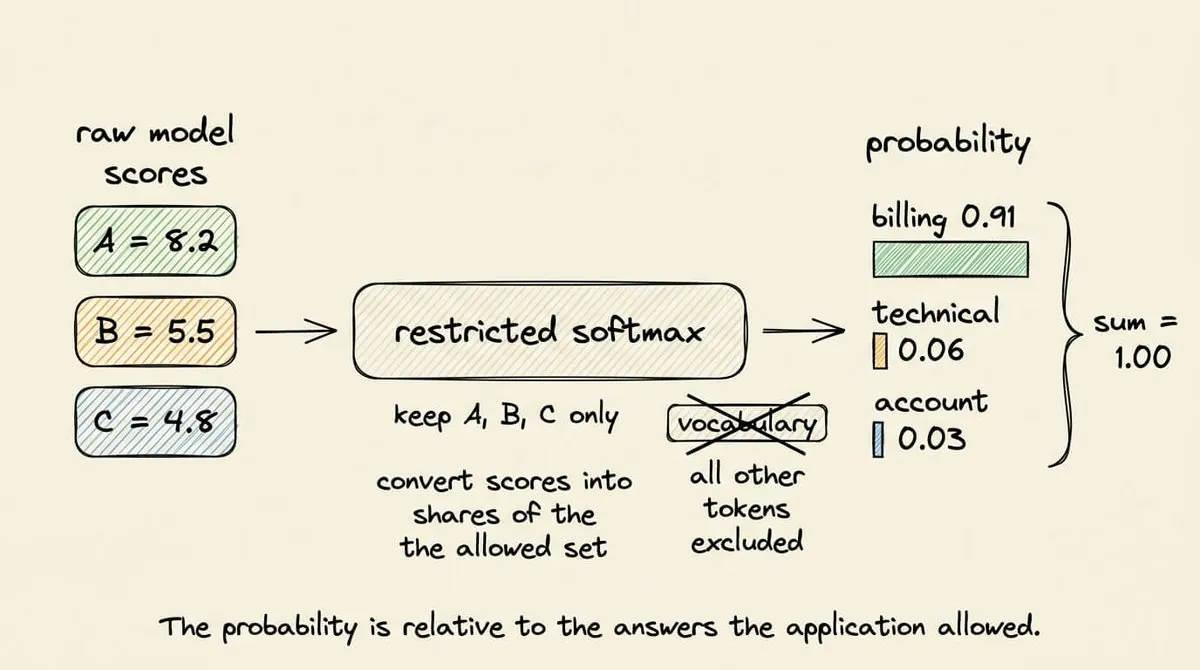
This is an operation SGLang already implements in /v1/score: it runs the prompt through the model, reads the requested token positions, and returns their scores, saving us from modifying the Qwen implementation and extracting the final tensor ourselves.
Why label the answers A, B, C instead of scoring the words "billing", "technical support", and "account access" directly? Because a visible word is not necessarily one token:
- "billing" might be one token for one tokenizer and several tokens for another.
- "technical support" will definitely span multiple positions.
Comparing multi-token phrases requires sequence scoring: score the first token, append it, score the next, combine the values, and let length leak into the comparison. Single-token labels avoid all of that. Every option is one vocabulary entry at the same output position, while the semantic meaning still appears in the prompt:
A = billing questions and payment problems
B = product errors and technical failures
C = login, password, and account access problems
The model reads those descriptions while processing the prompt; the label is only the token whose logit we inspect afterwards. We still have to verify that each label is one token, because tokenizers often encode a leading space as part of the token: the strings "A" and " A" can have different token IDs.
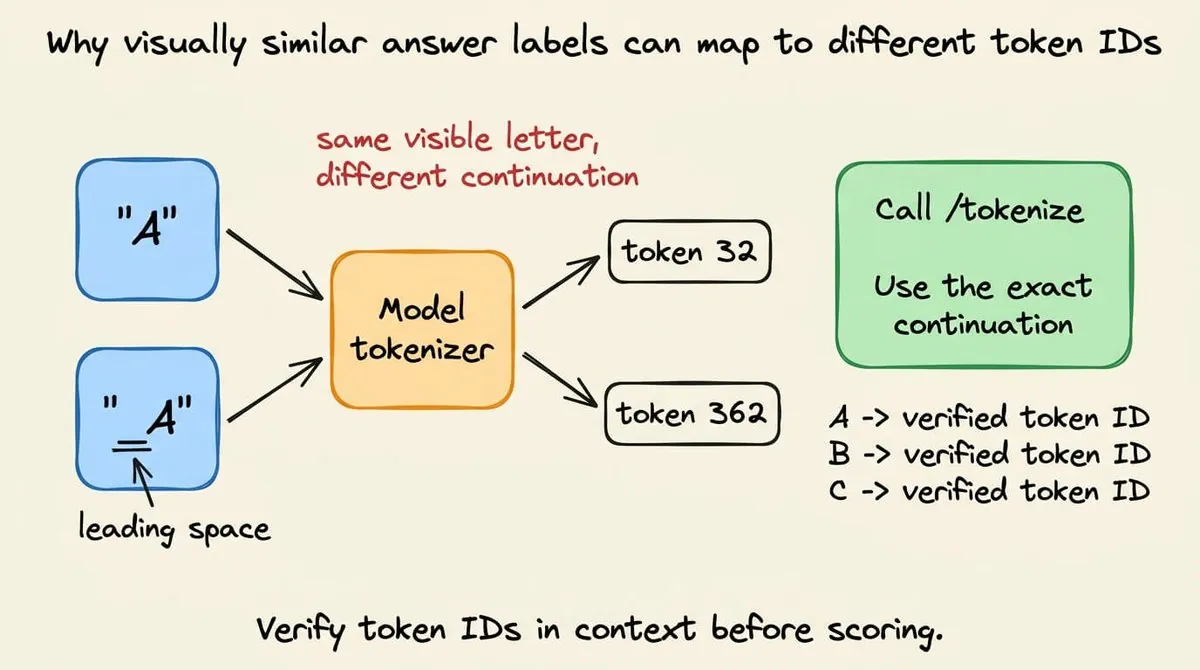
/tokenize with the exact continuation and verify the IDs in context before scoring.A chat template may also place whitespace or control tokens immediately before the answer position. The safe procedure: render the complete prompt with the model's chat template, determine the exact continuation expected at the answer position, send that continuation to /tokenize, and reject any label that produces anything other than one token. This label mapping stays inside the scoring client: the application sends semantic choices such as billing and technical_support, never token IDs, and never sees A, B, or C. That is what keeps the public API independent of model labels.
Finally, the answer list needs an escape route for when the listed choices are not exhaustive. If a security incident reaches a router that offers only billing, technical support, and account access, restricted softmax still assigns all probability mass to those three wrong choices. Add OTHER or ESCALATE whenever none of the named options may be correct.
Implementing a local scoring endpoint using SGLang
Only one inference server is needed. SGLang loads Qwen into GPU memory and exposes its native HTTP endpoints; our Python script talks to that server directly. The complete process:
- Start SGLang with a Qwen model.
- Write the decision as a prompt with letter labels.
- Ask SGLang to tokenize those labels.
- Send one request to
/v1/score. - Map the returned probabilities back to the choices.
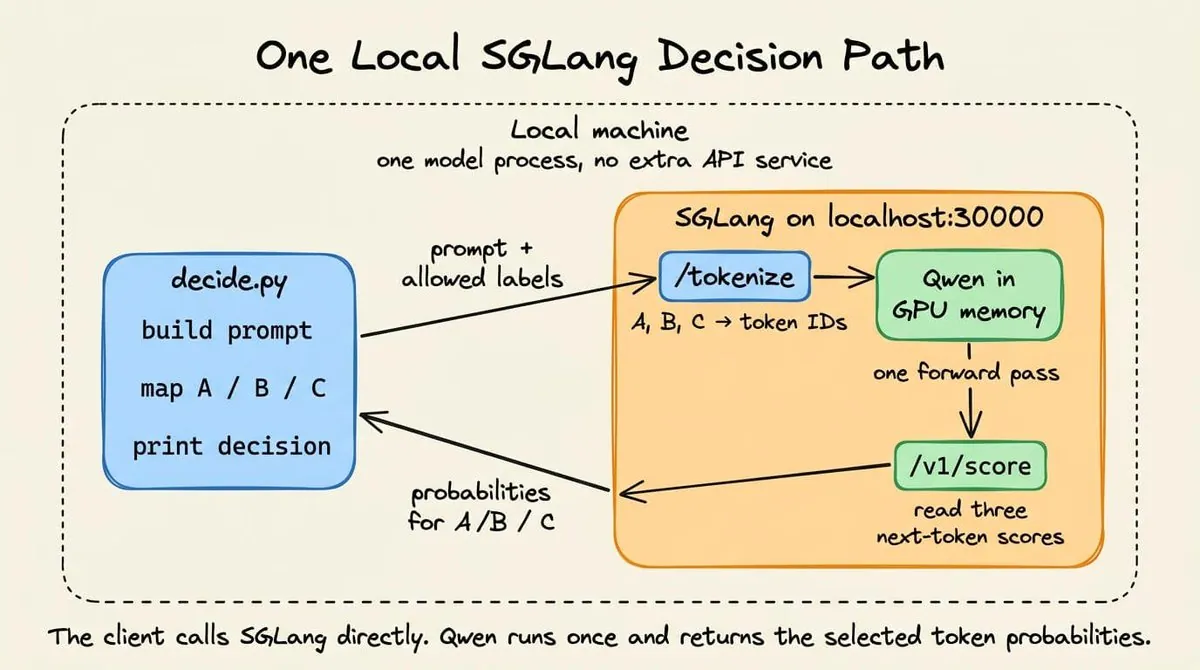
Step 1: Start Qwen with SGLang
Create a Python environment and install the two packages used here:
python3 -m venv .venv
source .venv/bin/activate
pip install "sglang[all]==0.5.10.post1" "requests==2.34.2"
Then start the model server:
python -m sglang.launch_server \
  --model-path Qwen/Qwen2.5-0.5B-Instruct \
  --host 127.0.0.1 \
  --port 30000
The first launch downloads the model from Hugging Face; later launches reuse the local cache. Once loading finishes, Qwen stays in memory and SGLang listens on port 30000. Keep this process running while the client below executes.
Step 2: Define the choices and build the prompt
Create decide.py with the following code:
import json
import requests

BASE_URL = "http://127.0.0.1:30000"
MODEL = "Qwen/Qwen2.5-0.5B-Instruct"

choices = {
    "A": "billing and payments",
    "B": "technical support",
    "C": "account access",
}

ticket = "I was charged twice for the same subscription."
choice_lines = "\n".join(
    f"{label} = {meaning}" for label, meaning in choices.items()
)

prompt = f"""Ticket:
{ticket}

Question:
Which category matches the ticket?

Allowed labels:
{choice_lines}

Return only the label.
Label:
"""

print(prompt)
The dictionary records both representations of each answer: A is the token we score, "billing and payments" is the meaning returned to the application, and their order must remain unchanged through tokenization, scoring, and result mapping. The exact prompt produced ends at "Label:", and we want the model's scores for the token that would appear next, without asking SGLang to generate it.
Step 3: Resolve the label token IDs
label_token_ids = []

for label in choices:
    response = requests.post(
        f"{BASE_URL}/tokenize",
        json={
            "model": MODEL,
            "prompt": label,
            "add_special_tokens": False,
        },
        timeout=30,
    )
    response.raise_for_status()
    token_ids = response.json()["tokens"]

    if len(token_ids) != 1:
        raise ValueError(
            f"{label!r} is not a single token: {token_ids}"
        )

    print(f"{label!r} -> {token_ids}")
    label_token_ids.append(token_ids[0])
SGLang's /tokenize endpoint returns the integer IDs produced by Qwen's tokenizer, and we reject any label that becomes several tokens: the scoring request needs exactly one vocabulary position per answer. For Qwen/Qwen2.5-0.5B-Instruct this prints:
'A' -> [32]
'B' -> [33]
'C' -> [34]
Each list holds one integer, so the later scoring request will read vocabulary positions 32, 33, and 34. The check also prevents assuming tokenization is identical across models: a label that works with Qwen may split under another tokenizer.
Step 4: Ask SGLang for the three probabilities
response = requests.post(
    f"{BASE_URL}/v1/score",
    json={
        "model": MODEL,
        "query": prompt,
        "items": [""],
        "label_token_ids": label_token_ids,
        "apply_softmax": True,
    },
    timeout=120,
)
response.raise_for_status()
score_response = response.json()

print(json.dumps(score_response, indent=2))
scores = score_response["scores"][0]querycontains the complete prompt.- The empty
itemsentry means we score the position immediately after it. label_token_idstells SGLang which three entries to read from Qwen's vocabulary-sized output.apply_softmaxnormalizes those entries into probabilities.
The response carries one score list because items contains one entry. Running this exact prompt against the same Qwen checkpoint returns:
{
  "scores": [
    [
      0.67776233,
      0.310878605,
      0.011359035
    ]
  ]
}
The three positions follow the order of label_token_ids, per the official endpoint reference: the first score belongs to A, the second to B, the third to C. The selected logits were 25.277620, 24.498226, and 21.188837 before softmax; small numeric differences may appear across hardware and precision settings.
Step 5: Convert model labels back into decisions
probabilities = {
    choices[label]: float(score)
    for label, score in zip(choices, scores, strict=True)
}

decision = max(probabilities, key=probabilities.get)

print(
    json.dumps(
        {
            "decision": decision,
            "probabilities": probabilities,
        },
        indent=2,
    )
)
Run the script in a second terminal:
{
  "decision": "billing and payments",
  "probabilities": {
    "billing and payments": 0.6777623295783997,
    "technical support": 0.31087860465049744,
    "account access": 0.011359035037457943
  }
}
One SGLang process tokenizes the labels, runs Qwen once, and returns the selected probabilities. Here billing wins with only 0.678 probability: a policy requiring 0.70 would send this ticket for review instead of automating the route, and that threshold should come from evaluation on labeled examples.
Measuring scoring latency against autoregressive generation
The single-request example shows the mechanism; a small benchmark application shows how it behaves across many decisions.
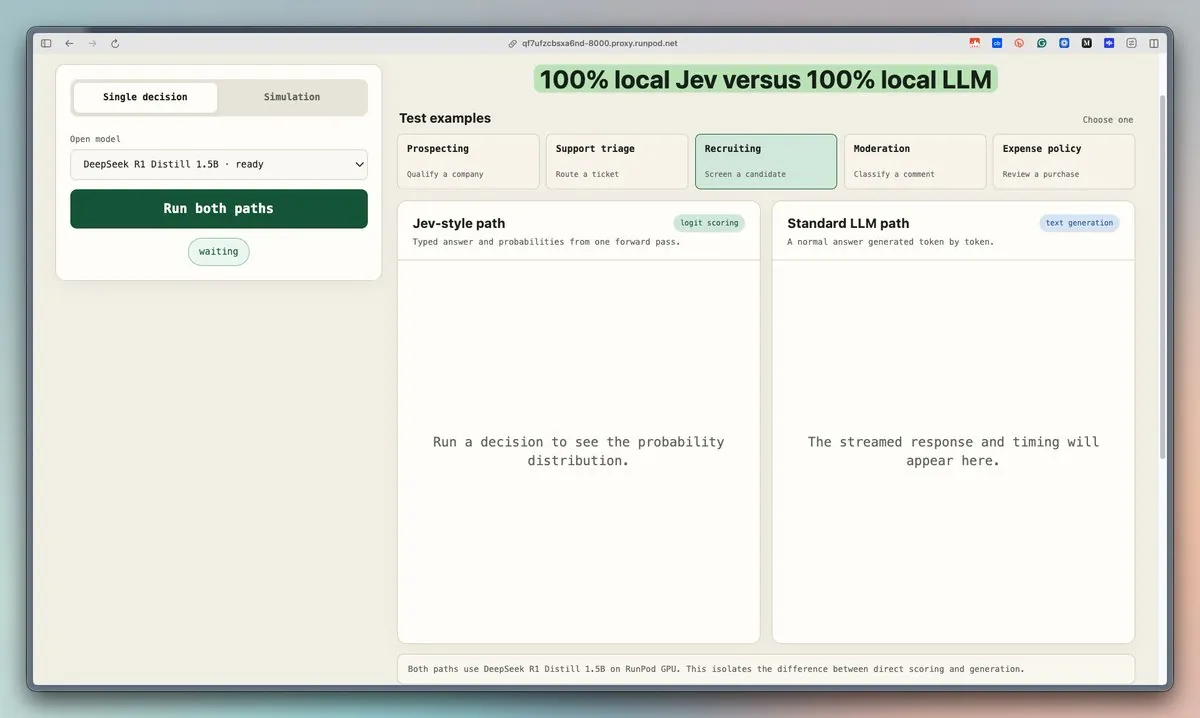
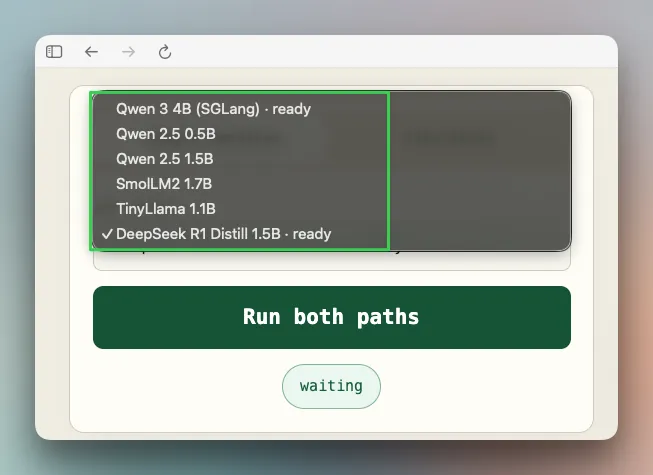
The demo supports several open models: Qwen 3 4B, Qwen 2.5 0.5B and 1.5B, SmolLM2 1.7B, TinyLlama 1.1B, and DeepSeek-R1-Distill-Qwen 1.5B.
The Jev-style lane calls the decision method:
result = engine.decide(request)
answer = result["answers"]["decision"]
choice = answer["choice"]
probabilities = answer["probabilities"]
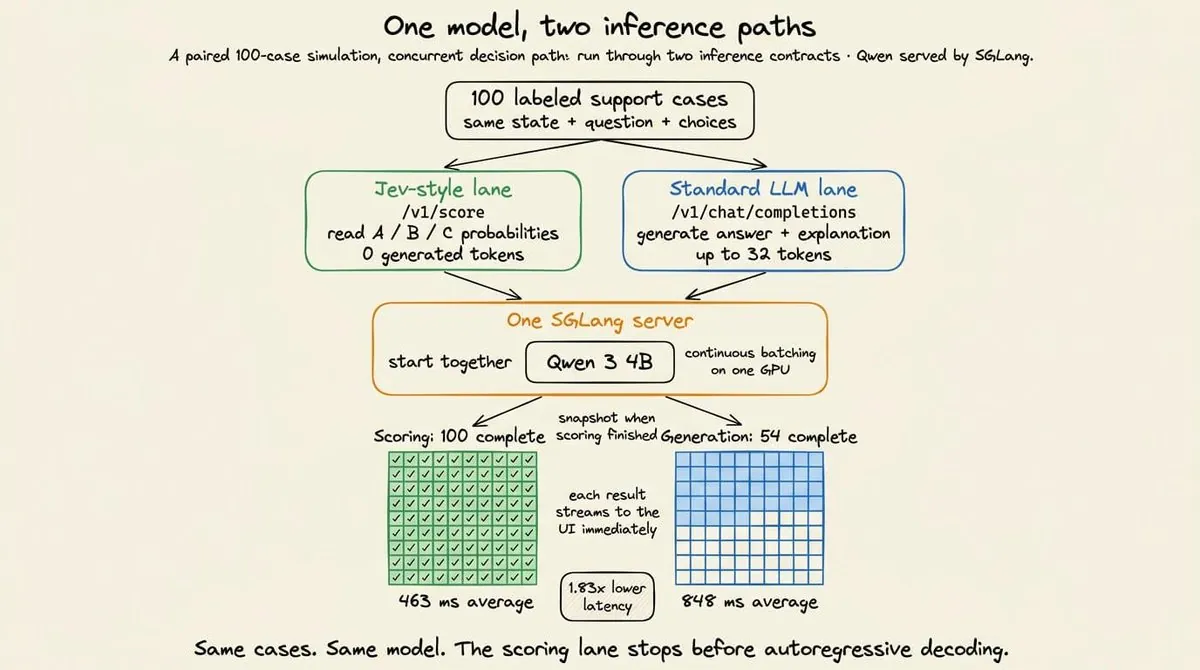
Inside decide(), SGLang receives the prompt through /v1/score with the token IDs for A, B, and C; it runs the prompt, reads the three next-token scores, normalizes them, and stops. The response contains no generated tokens. The standard lane calls generation on the same engine:
result = engine.generate_response(
    case["state"],
    case["question"],
    list(case["criteria"].items()),
    max_tokens=32,
)
That method sends the same state, question, and choices to /v1/chat/completions; Qwen generates an answer plus a short explanation, up to 32 tokens. The application searches the first 100 characters for one allowed choice name and marks the case correct when the parsed choice matches the stored label.
strong_fit in 6 ms with 0 output tokens and 100.0% confidence, while the generation lane needs 1088 ms and 105 output tokens to say the same thing.The speed difference is immediately evident, for the reasons discussed above. Beyond the single case, the benchmark simulates 100 cases from a fixed local dataset; the current datasets cover support routing, candidate screening, and expense review, and their expected labels let the interface display both speed and correctness.
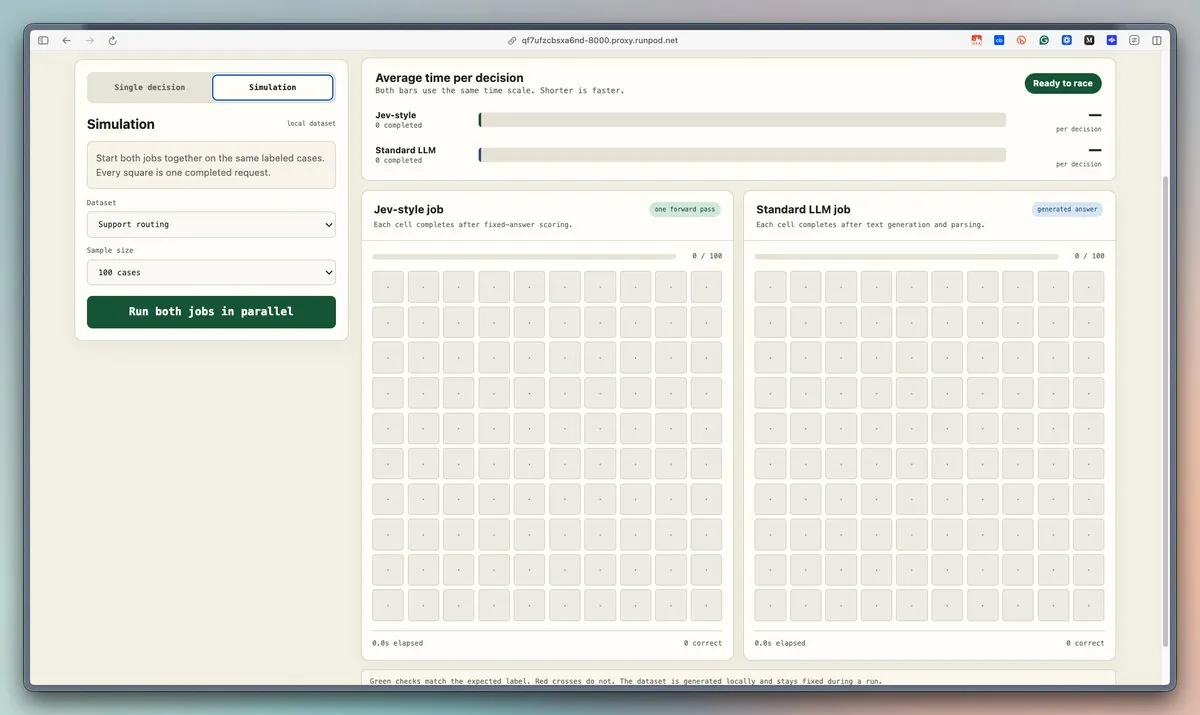
The remote SGLang path starts two workers behind one barrier, so both lanes begin together without flooding the server with all 200 requests at once:
starting_line = threading.Barrier(2)

def worker(lane, runner):
    starting_line.wait()
    for case in cases:
        updates.put(runner(case))

workers = [
    threading.Thread(target=worker, args=("jev", run_jev)),
    threading.Thread(target=worker, args=("llm", run_llm)),
]

for worker_thread in workers:
    worker_thread.start()
Each lane processes its own cases in order, sending the next request as soon as the previous one finishes. SGLang receives concurrent work from both lanes and schedules it through continuous batching; both request types share the same GPU, memory bandwidth, and scheduler.
| Measurement | Jev-style scoring | Standard generation |
|---|---|---|
| Single case (Qwen 3 4B, demo UI) | 6 ms, 0 output tokens, 100.0% confidence | 1088 ms, 105 output tokens |
| 100-case average latency | 463 ms | 848 ms (54 of 100 done at snapshot) |
| Work per decision | One forward pass, three logits read | Up to 32 generated tokens, then parse |
| What the caller receives | Choice plus probability distribution | Free text that must be parsed |
How to choose the right approach
Scoring is not a replacement for generation. Jev's approach applies only when the application defines the output space before inference: a compatible workload has a finite set of meaningful labels, each label maps to a distinct downstream action, and the caller needs only a label plus its probability distribution, not new text. Structured output is different in kind: it defines the syntax of a response while the decoder still generates field names and values token by token, so use structured generation when the values cannot be enumerated beforehand. Scoring removes decoding only when the candidate values are already known.
A good way to proceed is to choose the inference path from the required output:
- Generate when the output content is unknown before inference.
- Score when the output set is known and selection is sufficient. The first next-token vector already contains the ranking; returning it avoids an autoregressive loop the caller does not need.
| Dimension | Plain LLM decoding | Structured output | Jev-style scoring |
|---|---|---|---|
| Constraint | Free generation | Grammar-constrained tokens | One scored output position |
| Decode steps | N sequential steps | N constrained steps | 1 logit read after prefill |
| Returns | Free-form text | Schema-valid object | Label plus probability distribution |
| Best fit | Drafting, explanation, synthesis | Extraction with unknown values | Routing, ranking, gating, classification |
| Poor fit | Calls that only need one known label | Fixed-choice decisions | Writing new text or unknown field values |
To reiterate: this project reproduces the Jev-style inference mechanism, not Jev's weights, RLCD process, or evaluation stack. The training and calibration story behind those is a separate article.
Source: Avi Chawla, "Build your own Jev (100% local)", X article, 2026-09-20, x.com/_avichawla/status/2101563610644496464.
Source:Avi Chawla (X)https://x.com/_avichawla/status/2101563610644496464